Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
FLEX_START Scheduling for Delay-Tolerant GPU Training
Free sample question, answered and explained below. The Professional Cloud Architect practice bank has 2,335 more like it. Try 10 free: instant score, no account.
An enterprise machine learning team is optimizing its infrastructure on Google Cloud to train large deep learning models using specialized accelerators, such as NVIDIA A100 GPUs. The training jobs are batch-oriented, delay-tolerant, and require guaranteed runtime completion once started, without unexpected mid-run interruptions or preemptions.
The team wants to optimize accelerator acquisition and compute costs while ensuring efficient scheduling of high-demand GPU resources on Vertex AI.
Which compute scheduling architecture should the team implement for their Vertex AI custom training jobs?
Explanations
Deploy an NVIDIA Triton Inference Server container inside a Vertex AI Endpoint using a shared deployment resource pool
Deploy an NVIDIA Triton Inference Server container inside a Vertex AI Endpoint using a shared deployment resource pool
What NVIDIA Triton on Vertex AI Endpoints Is
NVIDIA Triton Inference Server on Vertex AI Endpoints is an optimized serving runtime tailored for high-concurrency, low-latency online model inference, supporting multi-framework model execution on GPU and CPU compute instances.
Why It Doesn't Meet the Requirement
- Wrong Workload Lifecycle: Triton Server is built for online prediction and serving, not for executing long-running batch model training jobs.
- Endpoints vs. Jobs: Vertex AI Endpoints host persistent web services that listen for live prediction requests (
rawPredictorpredict), whereas the requirement is to run asynchronous, batch deep learning model training.
Key Characteristics and Limitations
- Optimized for Concurrency: Maximizes throughput for concurrent inference requests across dynamic model ensembles.
- Continuous Hosting Costs: Endpoints incur ongoing hourly compute charges to stay warm for incoming user traffic rather than terminating after a training run.
This Answer Would Be Correct If
The organization needed to deploy a trained multi-framework model to a production endpoint to serve low-latency online inference requests from web clients.
Additional Context
While Triton is part of the broader AI acceleration stack, compute architecture must separate training pipelines (CustomJob) from serving endpoints (Endpoint).
Deploy standard Compute Engine Spot virtual machines attached to GPU accelerators with an automated script to handle preemption signals
Deploy standard Compute Engine Spot virtual machines attached to GPU accelerators with an automated script to handle preemption signals
What Spot Virtual Machines Are
Spot VMs are surplus Compute Engine compute instances available at significant discounts. However, they can be reclaimed by Google Cloud at any time with a 30-second preemption notice whenever the capacity is needed for standard on-demand workloads.
Why It Doesn't Meet the Requirement
- Risk of Preemption: The scenario specifically states that the training workload must run to completion without unexpected mid-run interruptions or preemptions. Spot VMs provide no runtime guarantees and can be evicted repeatedly, disrupting large distributed training loops.
- Operational Complexity: Writing custom checkpoint-and-resume logic with preemption listeners adds substantial administrative overhead compared to managed serverless scheduling on Vertex AI.
Key Characteristics and Limitations
- No Availability SLA: Spot instances offer no guarantee of immediate resource availability or continuous uptime.
- Interrupted Synchronization: In multi-node distributed training, if a single worker is preempted, the entire training step fails and stalls the cluster.
- Manual Infrastructure Management: Requires managing self-managed VMs instead of managed Vertex AI training jobs.
This Answer Would Be Correct If
The workload consisted of short, stateless tasks or fault-tolerant hyperparameter searches that can tolerate frequent terminations and restarts.
Execute a standard synchronous Vertex AI TrainingPipeline using on-demand GPU instances without defining scheduling parameters
Execute a standard synchronous Vertex AI TrainingPipeline using on-demand GPU instances without defining scheduling parameters
What Standard Synchronous Training Pipelines Are
A standard Vertex AI TrainingPipeline provisions compute nodes immediately on-demand using standard Google Cloud GPU quota without any queuing or specialized workload scheduling mechanisms.
Why It Doesn't Meet the Requirement
- Capacity Constraints: High-end accelerators (like NVIDIA A100 or H100 GPUs) frequently experience on-demand quota and immediate capacity constraints. Without queuing, jobs fail immediately if capacity is momentarily unavailable.
- Lacks Cost Optimization: Standard on-demand execution does not leverage DWS pricing or preemptible quota benefits, resulting in higher operational infrastructure costs for batch workloads.
Key Characteristics and Limitations
- Immediate Provisioning Failure: If the requested accelerator zone lacks instant capacity, the job throws a stockout error (
RESOURCE_EXHAUSTED). - Standard Quota Consumption: Consumes
custom_model_training_nvidia_a100_gpusquota rather than flexible scheduling pools.
This Answer Would Be Correct If
The training job were time-critical, had strict real-time starting requirements, and had guaranteed on-demand quota reservations.
Additional Context
For delay-tolerant batch training on constrained AI Hypercomputer infrastructure, relying on unmanaged on-demand scheduling leads to frequent job launch failures.
Configure Vertex AI CustomJob with Dynamic Workload Scheduler (DWS) using the FLEX_START scheduling strategy and define a maximum wait duration
Configure Vertex AI CustomJob with Dynamic Workload Scheduler (DWS) using the FLEX_START scheduling strategy and define a maximum wait duration
What Dynamic Workload Scheduler (DWS) Is
Dynamic Workload Scheduler (DWS) is an advanced compute orchestration feature in Google Cloud and Vertex AI designed to optimize accelerator allocation for large-scale AI/ML workloads. It queues training jobs until the requested compute accelerators (such as NVIDIA A100 or H100 GPUs) become fully available, running them with predictable performance and discounted economics.
DWS FLEX_START Queued Provisioning Flow
Process Flow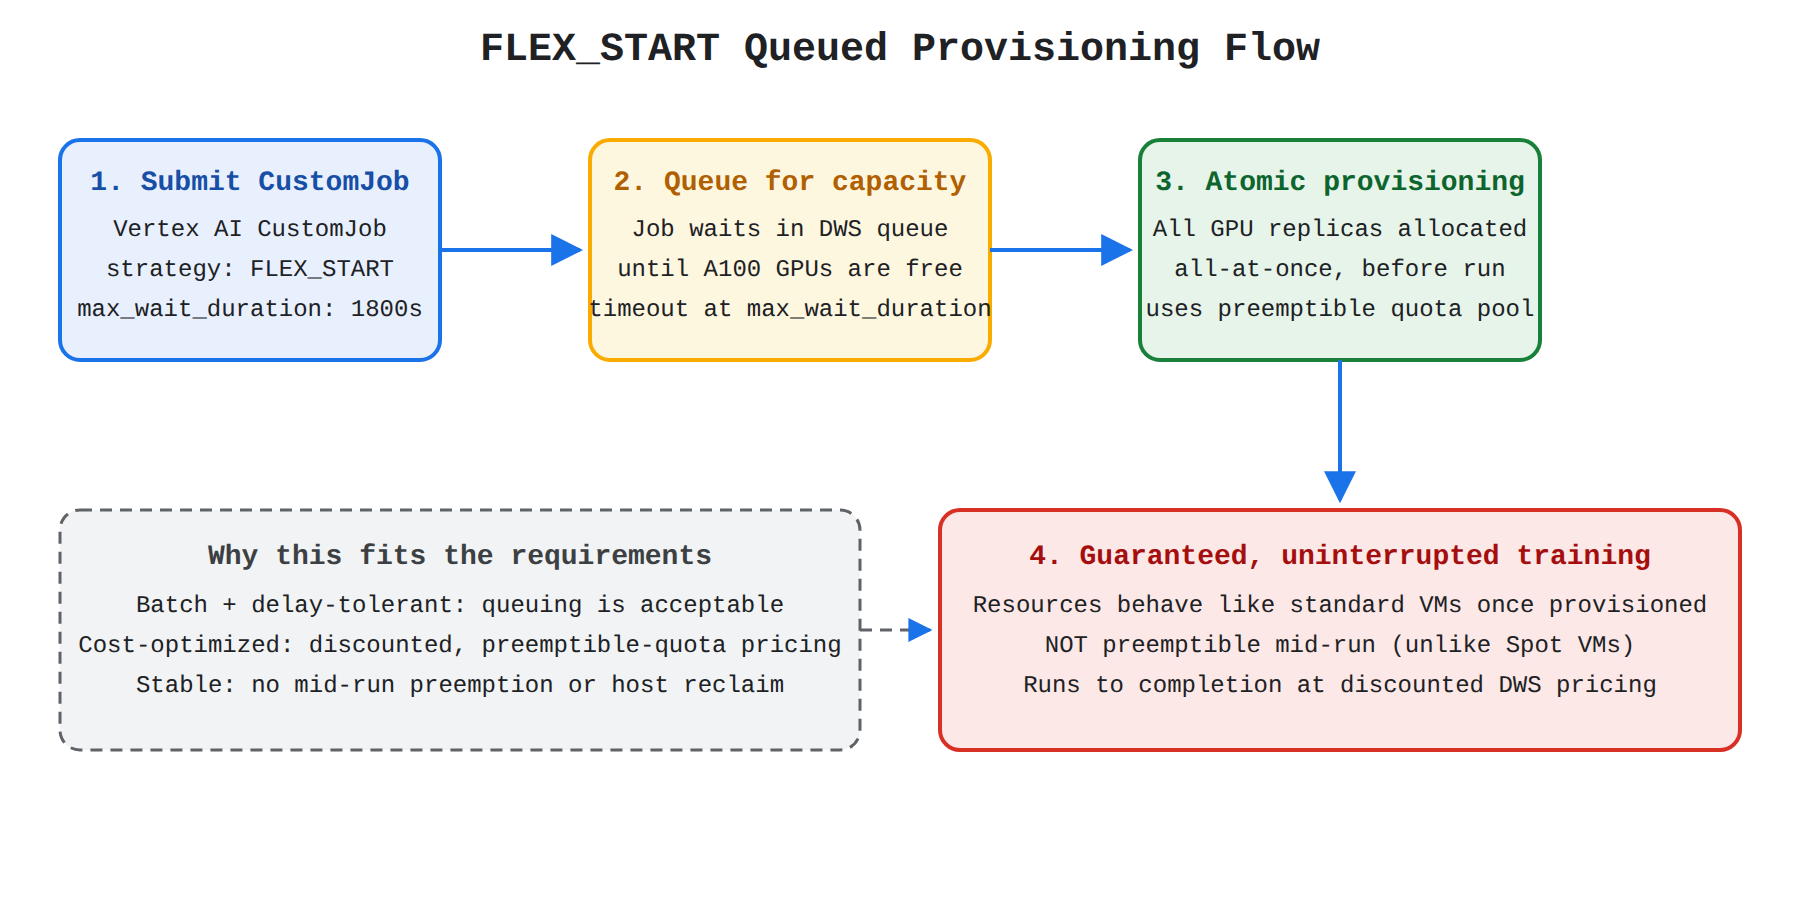
How It Meets the Requirements
- Optimized Resource Allocation and Cost: Under the
FLEX_STARTstrategy, jobs consume preemptible quota allocations rather than scarce on-demand quotas, offering cost-optimized pricing tiers while acquiring top-tier accelerator hardware. - Guaranteed Runtime Completion: Unlike standard preemptible VMs or Spot instances that can be terminated at any moment, resources provisioned via DWS behave like standard resources once provisioned and are not preemptible during execution. This guarantees uninterrupted model training until job completion.
- Delay-Tolerant Batch Scheduling: By setting
max_wait_duration(e.g.,1800s), the team defines how long Vertex AI will hold the job in queue waiting for GPU capacity before timing out.
Key Advantages and Capabilities
- Atomic Multi-Accelerator Provisioning: Ensures all requested GPU replicas and nodes are co-allocated simultaneously before execution begins.
- Predictable Execution: Eliminates mid-training failures caused by host reclaim events.
- Seamless SDK & API Support: Configurable directly within
aiplatform.CustomJobusinggca_custom_job_compat.Scheduling.Strategy.FLEX_START. - Quota Flexibility: Utilizes separate preemptible quota pools to bypass standard on-demand GPU capacity limits.
Why This Is Optimal
DWS FLEX_START strikes the exact balance between cost optimization and workload stability for large AI models, providing discounted, non-preemptible accelerator runtime for batch training.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,335 practice questions across all 6 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
IntermediateProfessional Cloud Architect
Model Garden Tiered Model Selection
Google Cloud AI and machine learning solutions (e.g., Gemini LLMs, Agent Builder, Model Garden, Gemini models, and AI Hypercomputer)
IntermediateProfessional Cloud Architect
Vertex AI Agent Engine Grounding and Integration
Google Cloud AI and machine learning solutions (e.g., Gemini LLMs, Agent Builder, Model Garden, Gemini models, and AI Hypercomputer)
IntermediateProfessional Cloud Architect
SRE Error Budget
Team assessment/skills readiness
IntermediateProfessional Cloud Architect
Customer-Managed Encryption Keys (CMEK)
Data security (key management, encryption, secret management)
IntermediateProfessional Cloud Architect
Private Google Access and VPC Service Controls
Accessing Google API best practices
AdvancedProfessional Data Engineer
Cloud Composer Dataproc Ephemeral Cluster Orchestration
Job automation and orchestration (e.g., Cloud Composer and Workflows)
Last updated