Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Gemini Agents, Model Garden and AI Hypercomputer
Infrastructure optimization via the AI Hypercomputer (opens in a new tab) is the use of an integrated supercomputing system to run AI training and serving efficiently. AI Hypercomputer is the unified portfolio for Google Cloud AI infrastructure and provides a single entry point to explore, configure, and deploy hardware, open software, and flexible consumption models. The system vertically integrates those three layers to maximize goodput, the measure of actual machine learning productivity, across the full lifecycle from prototyping and development to massive-scale training and real-time serving.
Specialized Accelerators and High-Performance Networking
Specialized accelerators and high-performance networking in AI Hypercomputer are the combination of compute chips and fast interconnects that keep accelerators doing productive work. AI Hypercomputer supports all available NVIDIA GPUs and Google Cloud TPUs, and accelerators connect over high-bandwidth networking to optimize throughput across thousands of compute instances. This tight coupling lets distributed training and large-model inference scale without throughput collapsing as node count grows.
GPU capacity is divided by how the system handles lifecycle events and maintenance. General GPUs are managed as independent compute units with asynchronous maintenance and use standard node auto-repair to maintain pod-level uptime for serving fleets. Clustered GPUs are managed as a single tightly coupled system with synchronized maintenance and include automated hardware health monitoring with proactive node replacement. Google Cloud TPUs use hardware designed for large matrix operations with on-chip high-bandwidth memory (HBM) for larger models and batch sizes, and TPUs can be connected in groups called slices that scale workloads with little to no code changes.
Exam tip: Choose Clustered GPUs when you need synchronized maintenance and proactive node replacement for tightly coupled training, and choose General GPUs when you need independent units with asynchronous maintenance and node auto-repair for serving fleets.
Optimized Storage for Training and Inference
Optimized storage for training and inference is high-throughput storage that prevents input-output bottlenecks from starving accelerators. Data flows from high-throughput storage services to GPU and TPU nodes, so checkpoint loading, dataset reads, and token delivery keep pace with computation. The documented options for this path are Google Cloud Managed Lustre and Cloud Storage Rapid, which are designed to eliminate I/O bottlenecks for demanding AI workloads.
Storage choice follows workload stage and access pattern. Large-scale distributed training for generative AI, fraud detection, and recommendation models needs sustained throughput for repeated passes over large datasets. Real-time inference and model serving for fraud detection and recommendation engines needs low-latency access to models and features. Small-scale experiments and early-stage development can start with simpler storage and move to high-throughput services only when accelerator utilization shows an I/O limit.
Orchestration with Open Software
Orchestration with open software is the layer that schedules AI work onto accelerators and manages scaling, restarts, and capacity. The frameworks include PyTorch, JAX, and TensorFlow, which run on top of the accelerator and networking layer. The orchestration layer schedules work onto those accelerators and manages scaling, restarts, and capacity.
Deployment options for accelerators divide by automation and control:
- Google Kubernetes Engine (GKE) for automated container-native scaling with Kubernetes orchestration
- Slurm through Cluster Director for cluster scheduling with colocation for multi-GPU training
- Cluster Toolkit blueprints for customizable infrastructure-as-code deployments
Control over the operating system and kernel depends on the chosen deployment tool. If you choose Cluster Director, Google manages the cluster environment and lifecycle on custom Ubuntu. If you choose Google Kubernetes Engine (GKE) in Autopilot mode, Google manages nodes and capacity adjustments without manual intervention, while in Standard mode you manage cluster node pools. Google Kubernetes Engine (GKE) adjusts capacity with Horizontal and Vertical Pod Autoscalers, the cluster autoscaler, and batch-job orchestration through Kueue.
Consumption Options and Reliability for Scale
Consumption options and reliability controls in AI Hypercomputer match provisioning style to workload predictability and scale. Flexible options include Flex-start VMs, Spot VMs, and Reservations for different workload needs. The Dynamic Workload Scheduler (DWS) provides atomic provisioning for entire blocks of interconnected nodes for large-scale training, so a large job obtains its full set of connected nodes together instead of starting partially.
Reliability and scheduling are tuned to maximize goodput, keeping accelerators on productive computation rather than system overhead. Clustered GPUs depend on automated health monitoring and proactive replacement to protect long-running distributed training, while General GPUs depend on node auto-repair to protect serving availability. For fault-tolerant evaluation and experimentation, Spot VMs lower cost but can be preempted, while committed capacity and calendar or flex-start reservations improve obtainability for high-demand accelerators.
Choosing a Compute Configuration
A compute configuration in AI Hypercomputer is the combination of accelerator support, control, orchestration, and scaling that fits training versus serving. The workflow depends on the orchestrator, and the orchestrator depends on how much control and automation the team needs. Choose Cluster Director for managed Slurm training on the newest high-end GPUs, choose Google Kubernetes Engine (GKE) for containerized training and inference with automatic pod and node scaling, and choose self-managed options when fine-grained operating system control matters more than automation.
The four compute options compare as follows:
| Compute option | Accelerator support | Control and orchestration |
|---|---|---|
| Cluster Director | NVIDIA GB300 Ultra, GB200, B200, H200, and H100, no TPUs | Google-managed custom Ubuntu with Slurm orchestration and automatic scaling based on CPU consumption |
| Google Kubernetes Engine (GKE) | All available NVIDIA GPUs and all available Google Cloud TPUs | Google-managed Autopilot or semi-managed Standard with Kubernetes orchestration and automatic pod and node scaling |
| Cluster Toolkit | All available NVIDIA GPUs and all available Google Cloud TPUs | Self-managed with automated configuration files and customizable scaling using MIGs or GKE tools |
| Compute Engine | All available NVIDIA GPUs and all available Google Cloud TPUs | Self-managed with manual orchestration and manual or automatic scaling using MIGs |
Design and orchestration of AI agents and search applications is the practice of combining a foundation model with enterprise data, memory, and tools so outputs are accurate and actionable. A conversational agent manages multi-turn dialogue and takes actions through tools, while a search application retrieves relevant enterprise content and generates a grounded answer. In Google Cloud, Vertex AI Agent Builder and Gemini Enterprise Agent Platform provide the building blocks for both patterns, with Gemini models for reasoning, retrieval for grounding, and Cloud Run (opens in a new tab), Google Kubernetes Engine (GKE), or Agent Runtime for deployment.
Conversational Agents Compared with Search Applications
Conversational agents and search applications solve different interaction problems with the same grounding principle. A conversational agent holds a dialogue, remembers context across turns, calls tools or APIs, and completes tasks such as customer service, order management, and scheduling. A search application focuses on finding and summarizing trusted information, where a document-retrieval agent fetches relevant passages from a curated set of documents and returns factual answers with citations to the source material. Choose a conversational agent when the user needs back-and-forth help and actions, and choose a search application when the user needs a cited answer drawn from validated policy, product, or technical documentation.
Grounding with Retrieval-Augmented Generation
Grounding is the technique that connects model output to verifiable data so answers reflect enterprise truth rather than model invention. Retrieval-Augmented Generation (RAG) implements grounding by first retrieving relevant chunks or entities and then passing those results into the model prompt for generation. Vertex AI Search can serve as the retrieval backend through RAG Engine on Gemini Enterprise Agent Platform, and information retrieval (IR) is the process that finds relevant documents from a corpus based on the user query. The retrieval system depends on the vector database and the curated corpus, and answer quality depends on input data quality, so inaccurate or incomplete source data produces suboptimal or false outputs.
Memory for Agent Context
Memory for agent context gives an agent the ability to retain context within a session and learn preferences across sessions. Short-term memory holds active conversational state, while long-term memory persists history and user preferences for future interactions. Data flows from the user conversation to the memory store on each turn, and then flows back into the next prompt so the orchestrator can stay consistent.
The three memory options divide by duration and behavior:
- Memorystore for Redis provides short-term memory for fast, temporary conversational context.
- Firestore provides long-term memory for storing conversational history and user preferences based on raw data.
- Vertex AI Agent Engine Memory Bank provides long-term personalized memory that automatically extracts from conversational history to remember and update user preferences over time.
Vertex AI Agent Engine Memory Bank depends on Vertex AI Agent Engine, because at least one Agent Engine instance must be created to use Memory Bank with Cloud Run.
Exam tip: Use Memorystore for Redis for short-term session context, Firestore for long-term history based on raw data, and Vertex AI Agent Engine Memory Bank when preferences should be automatically extracted and updated over time.
Vector Database for Enterprise Data
A vector database for enterprise data supports RAG and structured lookup by storing embeddings and returning the most similar vectors for a query. The agent queries the database for specific entity information or performs a vector search over embeddings, and the retrieved passages ground the Gemini response. Google Cloud supports this pattern with the pgvector extension on Cloud SQL for PostgreSQL and on AlloyDB for PostgreSQL. A sample chatbot architecture connects GKE or Cloud Run to Cloud SQL, Vertex AI, and pgvector over Private Service Connect in a Virtual Private Cloud (VPC), with Terraform for infrastructure and Python with asyncpg and FastAPI for the API layer.
Tools and Orchestration for Actions
Tools and orchestration are the components that let the agent orchestrator act on external services, APIs, and websites. The orchestrator reasons about the user goal, selects a tool, sends the tool input, and then uses the tool output in the next reasoning step. A trusted agent can also ground its tool calls in real-world contextual data from Google Maps Platform and Google Calendar, so location and scheduling answers reflect current external facts.
The documented tool types are:
- Model Context Protocol (MCP) for communicating with external tools executed through an MCP server hosted on Cloud Run.
- Basic utilities for precise math calculations, time conversions, and similar utilities.
- API calling for read or write calls to internal or third-party APIs.
- Image or chart generation for quickly creating visual content.
- Browser and operating system automation for running a headless or full graphical operating system in a container to browse the web, extract information, or perform clicks and keyboard input.
- Code execution on Cloud Run in a secure environment with multi-layered sandboxing and minimal or no Identity and Access Management (IAM) permissions.
- Vertex AI Agent Engine Code Execution for execution in secure, isolated, and managed sandbox environments that support file input and output, less than one second execution, and long-lived memory.
Vertex AI Agent Engine Code Execution depends on Vertex AI Agent Engine, because at least one Vertex AI Agent Engine instance must be created to use the feature in Cloud Run.
Model and Runtime Choices for Deployment
Model and runtime choices for deployment determine quality, latency, cost, and operational control for agents and search applications. Gemini 2.5 Flash is designed for agentic workloads with higher speed, built-in tool use, multimodal generation across text, images, video, audio, and code, and a 1M token context window. Model Garden and Vertex AI help teams find and customize foundation models from Google, open source, and third-party sources, while Vertex AI endpoints serve custom models or other foundation models on managed infrastructure. A GPU-enabled Cloud Run service can serve a fine-tuned model directly, which keeps model inference close to the agent without managing servers.
The agent runtime and the model runtime can be selected separately to balance control and management. The reference single-agent architecture deploys the agent and its tools on Cloud Run with Agent Development Kit (ADK), Gemini, and Model Context Protocol (MCP), with GKE or Agent Runtime as alternatives for the agent runtime and Agent Platform, Cloud Run, or GKE as alternatives for the model runtime. When consuming large language models (LLMs) through the Vertex AI API, inference runs on Google managed infrastructure and reduces the need for specific GPU or Tensor Processing Unit (TPU) quotas in the GKE cluster. Choose the most affordable model and machine type that still meets response quality and latency requirements, and select regions by service availability, end-user latency, resource cost, and regulatory requirements.
Model selection and lifecycle management in Model Garden is the process of choosing a foundation model and keeping it current from tuning through monitoring. Model Garden is the catalog for discovering and comparing foundation models from Google, open-source projects, and third-party partners. A foundation model is a large model trained on multi-terabyte datasets of text, images, code, or other media that can perform many tasks from a simple prompt, such as translation, summarization, question answering, and code generation. Model Garden connects model choice to the full lifecycle, from selecting a base model to tuning it, deploying it to an endpoint, and keeping it current as business needs evolve. Gemini models (opens in a new tab) in the catalog are built for multimodality and can reason across text, images, video, audio, and code.
Model Garden as a Foundation Model Hub
Model Garden as a foundation model hub provides access to Google models such as Gemini, partner models, open models, and custom models in one place for evaluation and deployment. Google models are accessed through a managed API that reduces operational overhead, while open models can be self-hosted when deep control is needed for fine-tuning on proprietary data or for strict security and data residency requirements. Self-hosted models run within your own network and infrastructure, while managed models run on Google infrastructure with enterprise-grade security and scaling. This choice creates a core tradeoff between simplicity and control that shapes cost, operations, and compliance.
Selecting a Model by Modality, Size, and Cost
Selecting a model by modality, size, and cost starts with finding the most affordable model that still meets response quality and latency requirements. Three selection dimensions determine fit between a business use case and a technical model, and the selection decision flows from use case to modality, then to the smallest size that meets quality, then to cost validation.
- Modality: the high-level data types a model is trained for, such as text, images, video, and audio, which must match the task like text-to-image generation or multimodal search.
- Size: the number of parameters in a model, where a larger model can learn more complex patterns and produce higher-quality responses but often costs more and responds more slowly.
- Cost: the combined price of inference, latency, and operations, where multimodal or larger models may increase cost and latency compared with smaller, single-modality models.
Gemini models are built for multimodality, which makes them flexible for search, assistants, and agentic applications. When flexibility is not required, a narrower model with the correct modality is often cheaper and faster.
Comparing Gemini Variants and Routing Strategy
Comparing Gemini variants and routing strategy is how teams balance reasoning power, latency, and cost across requests. Gemini variants divide work by reasoning power, latency, and cost, with Gemini Pro recommended as the primary task orchestrator for agentic applications that need strong reasoning and multi-step planning. Gemini Pro and Flash models include a built-in thinking process, and the thinking budget controls how many thinking tokens the model uses before answering. A higher thinking budget allows more detailed reasoning and can improve response quality, but it can also increase latency and cost.
Model routing optimizes performance and cost by dynamically selecting the most appropriate model for each request based on complexity, cost, or latency requirements. For example, simple structured tasks like text classification or routine code generation can be routed to a small language model (SLM), while complex reasoning stays on a more powerful and expensive model. This routing flow sends traffic from the application router to the SLM first for simple tasks and only to the larger model when complexity requires it, so high performance is preserved without paying for maximum reasoning on every request.
Exam tip: Choose a managed Gemini API to minimize operational overhead, and choose a self-hosted open model when you must fine-tune deeply on proprietary data or keep the model inside your own network for security and data residency.
Choosing a Model Runtime for Deployment
A model runtime is the environment that hosts and serves a model and makes its reasoning available to applications and agents. Model Garden models can be served through different runtimes depending on control, traffic pattern, and hardware needs. Traffic flows from the application to the runtime endpoint, and the runtime then provisions compute, runs inference, and scales with demand.
| Model runtime | Serves | Choose when |
|---|---|---|
| Agent Platform | Gemini models, partner models, open models, or custom models through a fully managed API | You need enterprise-grade security, scaling, and generative AI tools without managing servers |
| Cloud Run | Open or custom containerized models as serverless containers | You prioritize serverless simplicity and cost-efficiency for variable traffic that can scale to zero |
| Google Kubernetes Engine (GKE) | Open or custom containerized models on Kubernetes | You need maximum control over infrastructure, specialized hardware, or complex security and networking |
The runtime depends on the model type, because managed Gemini and partner models use Agent Platform directly while containerized open or custom models need Cloud Run or GKE.
Managing the Model Lifecycle from Tuning to Monitoring
Managing the model lifecycle from tuning to monitoring keeps a deployed model current and reliable by linking selection, customization, evaluation, controlled release, and observability. Trained artifacts are stored in Cloud Storage or registered in Model Registry, which preserves lineage and enables rollback to the most recent stable version. This closed loop connects monitoring signals back to retraining and reselection, so data drift, quality shifts, or new base models trigger a new cycle rather than a one-time deployment.
Model Garden Lifecycle Loop in 5 Steps
Process Flow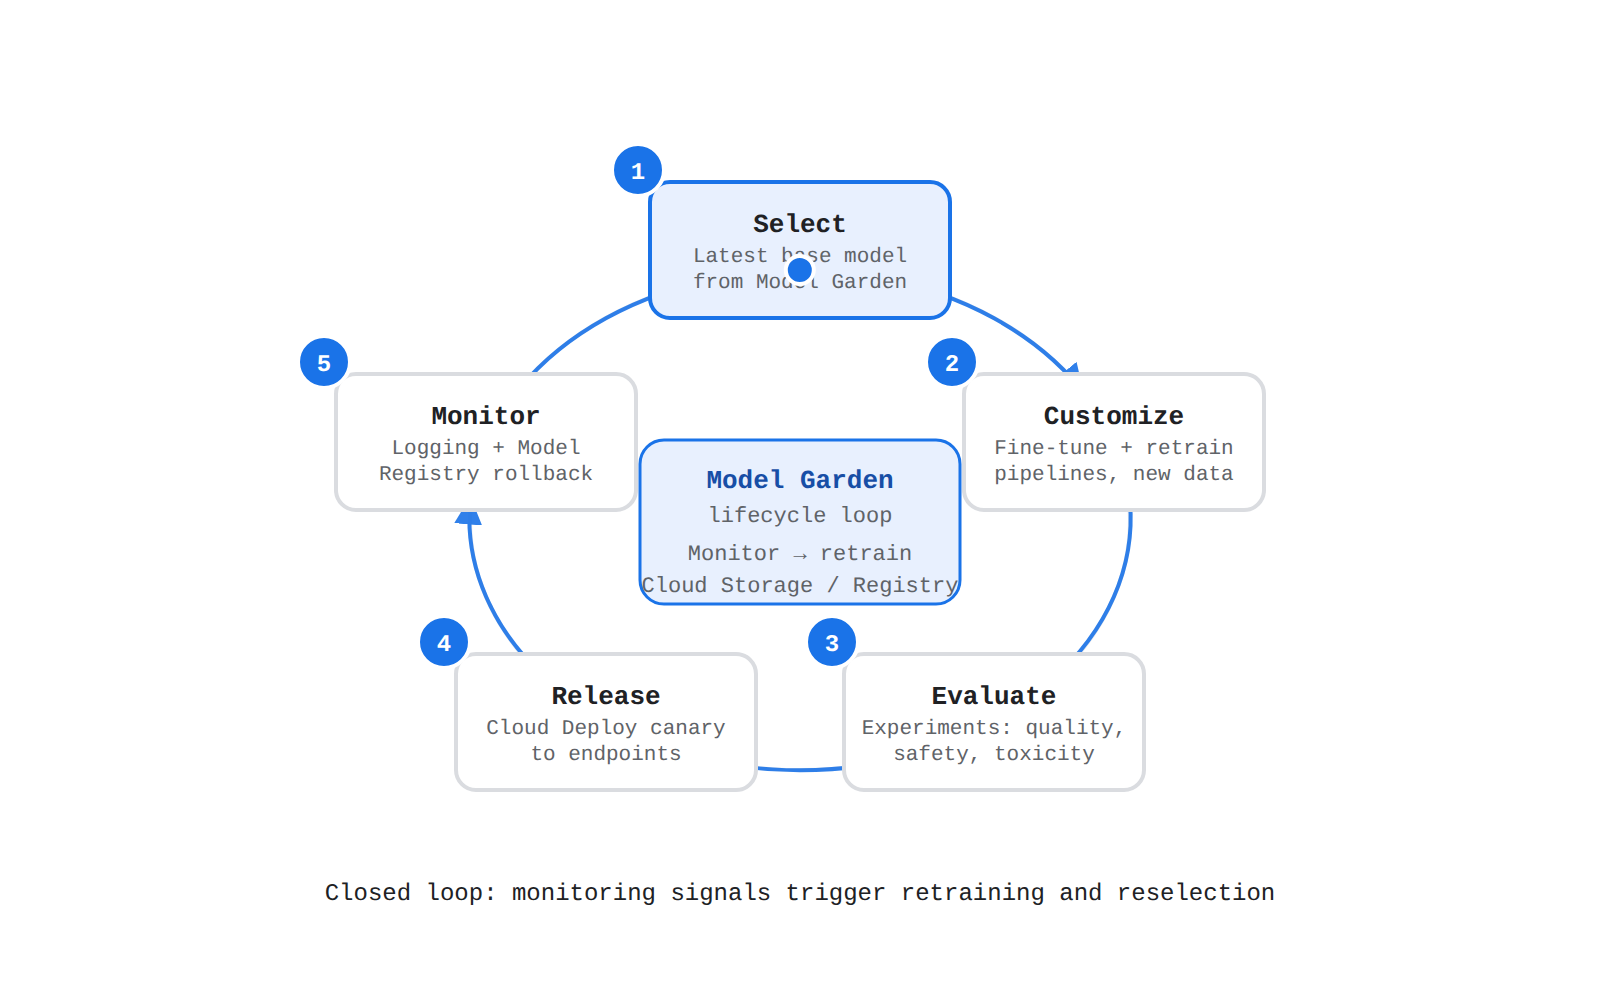
A circular flow with five boxes: Select base model, Customize and retrain, Evaluate and compare, Release with canary, Monitor and rollback. A dot travels clockwise showing order, with artifacts stored in Cloud Storage and Model Registry.
The lifecycle moves through an ordered sequence:
- Select base model: Choose the latest suitable base model from Model Garden for tuning to keep outputs relevant and optimized.
- Customize and retrain: Fine-tune or continuously retrain with new data or prompts through automated pipelines, including continuous training on new data.
- Evaluate and compare: Assess quality, factual accuracy, toxicity, coherence, and safety with automated evaluation and compare candidates with Experiments.
- Release in stages: Package with Cloud Deploy and deploy to Agent Platform endpoints using canary releases that send a new version to a subset of users before full rollout.
- Monitor and roll back: Track output quality, harmful content, latency, token throughput, and queries per second with logging and monitoring, and roll back through Model Registry when thresholds are breached.
Key Facts
- AI Hypercomputer vertically integrates performance-optimized hardware, open software, and flexible consumption models to maximize goodput across training and serving.
- Clustered GPUs use synchronized maintenance with proactive node replacement for tightly coupled training, while General GPUs use asynchronous maintenance with node auto-repair for serving fleets.
- Retrieval-Augmented Generation (RAG) grounds model output by retrieving relevant chunks from enterprise data and passing those results into the model prompt for generation.
- Vertex AI Agent Engine Memory Bank automatically extracts and updates user preferences over time, while Firestore stores long-term history based on raw data and Memorystore for Redis holds short-term session context.
- The Model Garden lifecycle runs in order from selecting a base model through customizing, evaluating, releasing with canary deployments, and monitoring with rollback through Model Registry.
Frequently Asked Questions
What is the difference between Clustered GPUs and General GPUs in AI Hypercomputer?
Clustered GPUs are managed as a single tightly coupled system with synchronized maintenance and automated hardware health monitoring with proactive node replacement for tightly coupled training, while General GPUs are managed as independent compute units with asynchronous maintenance and standard node auto-repair to maintain pod-level uptime for serving fleets.
When should I use Memorystore for Redis, Firestore, or Vertex AI Agent Engine Memory Bank for agent memory?
Memorystore for Redis provides short-term memory for fast, temporary conversational context, Firestore provides long-term memory for storing conversational history and user preferences based on raw data, and Vertex AI Agent Engine Memory Bank provides long-term personalized memory that automatically extracts from conversational history to remember and update user preferences over time.
How does Retrieval-Augmented Generation (RAG) ground model output in enterprise data?
Retrieval-Augmented Generation grounds model output by first retrieving relevant chunks or entities from enterprise data and then passing those results into the model prompt for generation so answers reflect enterprise truth rather than model invention.
Sample Question
An enterprise is designing an automated customer support solution using Python and the Agent Development Kit (ADK). The design must satisfy the following architectural requirements:
- Deploy the agent on a fully managed runtime with minimal operational overhead and built-in short-term session memory management.
- Ground model responses with internal enterprise documentation to eliminate hallucinations and provide accurate information.
- Execute actions against existing enterprise backend workflows using a least-privilege security model tied directly to the agent's runtime lifecycle.
Which architecture should the cloud architect recommend?
Deploy the agent on Cloud Run with Cloud Memorystore for session caching, and authenticate backend API tools using a single shared user-managed service account with Project Owner permissions.
Deploy the agent as a containerized service on Google Kubernetes Engine (GKE), deploy a Redis cluster for session memory, and use Grounding with Google Search for enterprise data retrieval.
Build the agent in Vertex AI Agent Designer, store conversational history in Vertex AI Feature Store, and embed static API keys directly in the agent instructions to call backend APIs.
Deploy the agent to Vertex AI Agent Engine with agent identity enabled, equip the agent with the Vertex AI Search tool for document grounding, and connect backend workflows using Application Integration tools.
How learners score on this domain
Last updated