Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Using SRE Error Budgets to Govern Releases
Free sample question, answered and explained below. The Professional Cloud Architect practice bank has 2,335 more like it. Try 10 free: instant score, no account.
An enterprise e-commerce team is transitioning from traditional operations to Site Reliability Engineering (SRE) and DevOps practices in Google Cloud. During an operational readiness assessment, the team presents their proposed strategy for managing automated CI/CD releases alongside Service Level Objectives (SLOs).
Which proposed approach demonstrates proper operational readiness and alignment with SRE and DevOps methodologies?
Explanations
Bypass continuous integration automated testing suites and conduct manual exploratory testing directly in production whenever error budgets are low
Bypass continuous integration automated testing suites and conduct manual exploratory testing directly in production whenever error budgets are low
What Bypassing CI/CD Testing Entails
This approach disables automated continuous integration (CI) and test automation suites, replacing them with ad-hoc manual testing in live production environments when service error budgets are depleted.
Why It Doesn't Meet the Requirement
- Violates DevOps Capabilities: Test automation and continuous integration are foundational technical capabilities designed to catch regressions early (shifting left).
- Increases Production Risk: Performing untested releases in production during an error budget deficit dramatically increases the probability of major outages.
- Misunderstands Error Budgets: When an error budget is depleted, teams should restrict risky releases and harden the platform, not lower testing standards.
Key Limitations
- Introduces human error and unpredictable regression risks into production environments.
- Slows down feedback loops by removing automated unit, integration, and security checks from the delivery pipeline.
- Directly contradicts the principle of low-risk, repeatable automated delivery.
This Answer Would Be Correct If
The organization had no automated environments and was executing a live incident recovery protocol under extreme, temporary disaster recovery constraints.
Target a 100% availability SLO for every production microservice and mandate Change Advisory Board (CAB) manual approval for each automated pipeline execution
Target a 100% availability SLO for every production microservice and mandate Change Advisory Board (CAB) manual approval for each automated pipeline execution
What This Strategy Proposes
This strategy attempts to achieve zero downtime by defining a 100% availability target and instituting a heavyweight Change Advisory Board (CAB) manual review process before any pipeline can deploy code to production.
Why It Doesn't Meet the Requirement
- Unrealistic Target: Targeting 100% availability is economically unfeasible and anti-SRE, as it leaves zero error budget for updates, experiments, or unavoidable third-party failures.
- Heavyweight Governance: Requiring manual change approval boards slows delivery speed and contradicts DevOps practices that emphasize streamlined change approval and deployment automation.
- Diminishing Returns: Users generally cannot perceive the difference between 99.99% and 100% availability due to client-side network fluctuations.
Key Limitations
- Eliminates the concept of an error budget, making any release theoretically unacceptable.
- Creates deployment bottlenecks and lengthy release cycles.
- Encourages large, infrequent, high-risk deployments rather than small, frequent, low-risk releases.
This Answer Would Be Correct If
The organization were managing an isolated, safety-critical hardware system where zero failures can be tolerated and automated deployments are strictly prohibited by regulation.
Define user-centric Service Level Indicators (SLIs) to determine an error budget, automate releases while the budget is positive, and pause non-essential deployments to focus on reliability when the budget is exhausted
Define user-centric Service Level Indicators (SLIs) to determine an error budget, automate releases while the budget is positive, and pause non-essential deployments to focus on reliability when the budget is exhausted
What SRE Error Budget Governance Is
Site Reliability Engineering (SRE) uses Service Level Indicators (SLIs) and Service Level Objectives (SLOs) to quantify user happiness and establish an error budget. An error budget represents the acceptable amount of unreliability a service can experience over a given period while still meeting user expectations.
Error Budget Release Governance
Decision Tree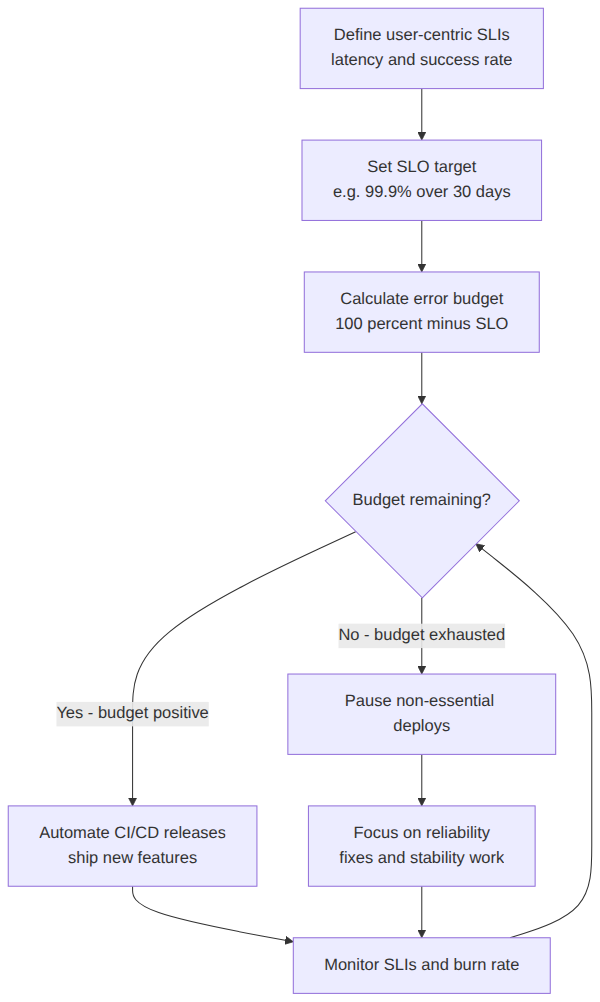
How It Meets Operational Readiness and DevOps Requirements
This approach directly aligns with core SRE and DevOps tenets by balancing product feature velocity with system stability:
- Automated Deployments: Fast, continuous delivery is enabled as long as the system operates within its error budget.
- Data-Driven Release Governance: When the error budget is exhausted, release policies dictate halting risky new feature rollouts to prioritize stability, bug fixes, and infrastructure reliability work.
- User-Centric Measurement: SLIs measure real user interactions (such as request latency and success rate) rather than isolated server metrics.
Key Advantages
- Shared Responsibility: Aligns development and operations around a single objective metric for release risk.
- Sustainable Pace: Prevents continuous delivery from outpacing the team's ability to maintain high service availability.
- Objective Decision-Making: Removes subjective arguments regarding whether software is stable enough to deploy.
- Automated Feedback Loops: Enables CI/CD pipelines to make policy-based deployment decisions.
Why This Is Optimal
Using SLIs to derive error budgets bridges the gap between fast continuous delivery and dependable service reliability. It ensures that development teams are empowered to innovate rapidly until reliability data objectively indicates that stabilization is necessary.
Rely exclusively on virtual machine CPU and memory utilization thresholds as the primary SLIs to trigger automated deployment rollbacks
Rely exclusively on virtual machine CPU and memory utilization thresholds as the primary SLIs to trigger automated deployment rollbacks
What Infrastructure-Only SLIs Measure
This strategy relies strictly on low-level infrastructure metrics, such as virtual machine (VM) CPU and RAM utilization, as the core indicators of service health and criteria for automated rollbacks.
Why It Doesn't Meet the Requirement
- Lack of User Context: Infrastructure metrics do not reflect user happiness or user-perceived performance. A service can experience 100% successful requests under high CPU, or return 500 errors under 5% CPU.
- Improper SLI Selection: Effective SLIs measure promises made to users, such as request success rates or end-to-end latency, rather than raw compute utilization.
- Flawed Rollback Triggers: Rolling back a deployment purely because CPU usage increased can prevent legitimate high-throughput processing or legitimate background migrations.
Key Limitations
- Low Fidelity: Fails to capture the actual experience of end users interacting with application workflows.
- False Positives/Negatives: Causes spurious rollbacks during routine traffic spikes and fails to catch silent logic bugs that crash user flows without loading the CPU.
This Answer Would Be Correct If
The assessment specifically focused on configuring automated horizontal pod or instance autoscaling rather than evaluating user-facing service health and release quality.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,335 practice questions across all 6 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
IntermediateProfessional Cloud Architect
Cloud Skills Gap Analysis
Team assessment/skills readiness
IntermediateProfessional Cloud Architect
Apigee Cloud Armor reCAPTCHA WAAP Architecture
API management best practices (e.g., Apigee)
IntermediateProfessional Cloud Architect
Cloud Run vs GKE Refactoring Strategy
Cloud-first design approach
IntermediateProfessional Cloud Architect
Cloud Run Scale-to-Zero
Data processing and compute provisioning
IntermediateProfessional Cloud Architect
Private Service Connect Published Services
Cloud-native networking (e.g., virtual private cloud [VPC], peering, firewalls, load balancers, routing, container networking, shared VPC, and Private Service Connect)
FundamentalGenerative AI Leader
LLMs vs Multimodal Foundation Models vs Diffusion Models
Defining core gen AI concepts (e.g., artificial intelligence, natural language processing, machine learning, generative AI, foundation models, multimodal foundation models, diffusion models, prompt tuning, prompt engineering, large language models)
Last updated