Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Reliable Cloud Operations with Observability and Automation
Understanding the principles and recommendations of the operational excellence pillar of the Google Cloud Well-Architected Framework
The operational excellence pillar of the Google Cloud Well-Architected Framework (opens in a new tab) is the set of practices for running reliable cloud operations through incident response, observability, and automation. The operational excellence pillar (opens in a new tab) connects detection of a failure to resolution, resolution to review, and review to better processes and tooling. Telemetry flows from resources to monitoring to analysis to dashboards, while infrastructure code flows from version control through pipelines to production.
Incident Response with Review and Continuous Learning
Incident response with review and continuous learning is the closed loop that limits harm during a failure and prevents recurrence. Clear procedures assign roles to incident commanders, investigators, communicators, and technical experts, and define communication protocols and escalation paths. Steps for communication, triage, investigation, and resolution are documented in a runbook or playbook, and teams train regularly so they can follow it under pressure.
Incident Response Closed Loop
Process Flow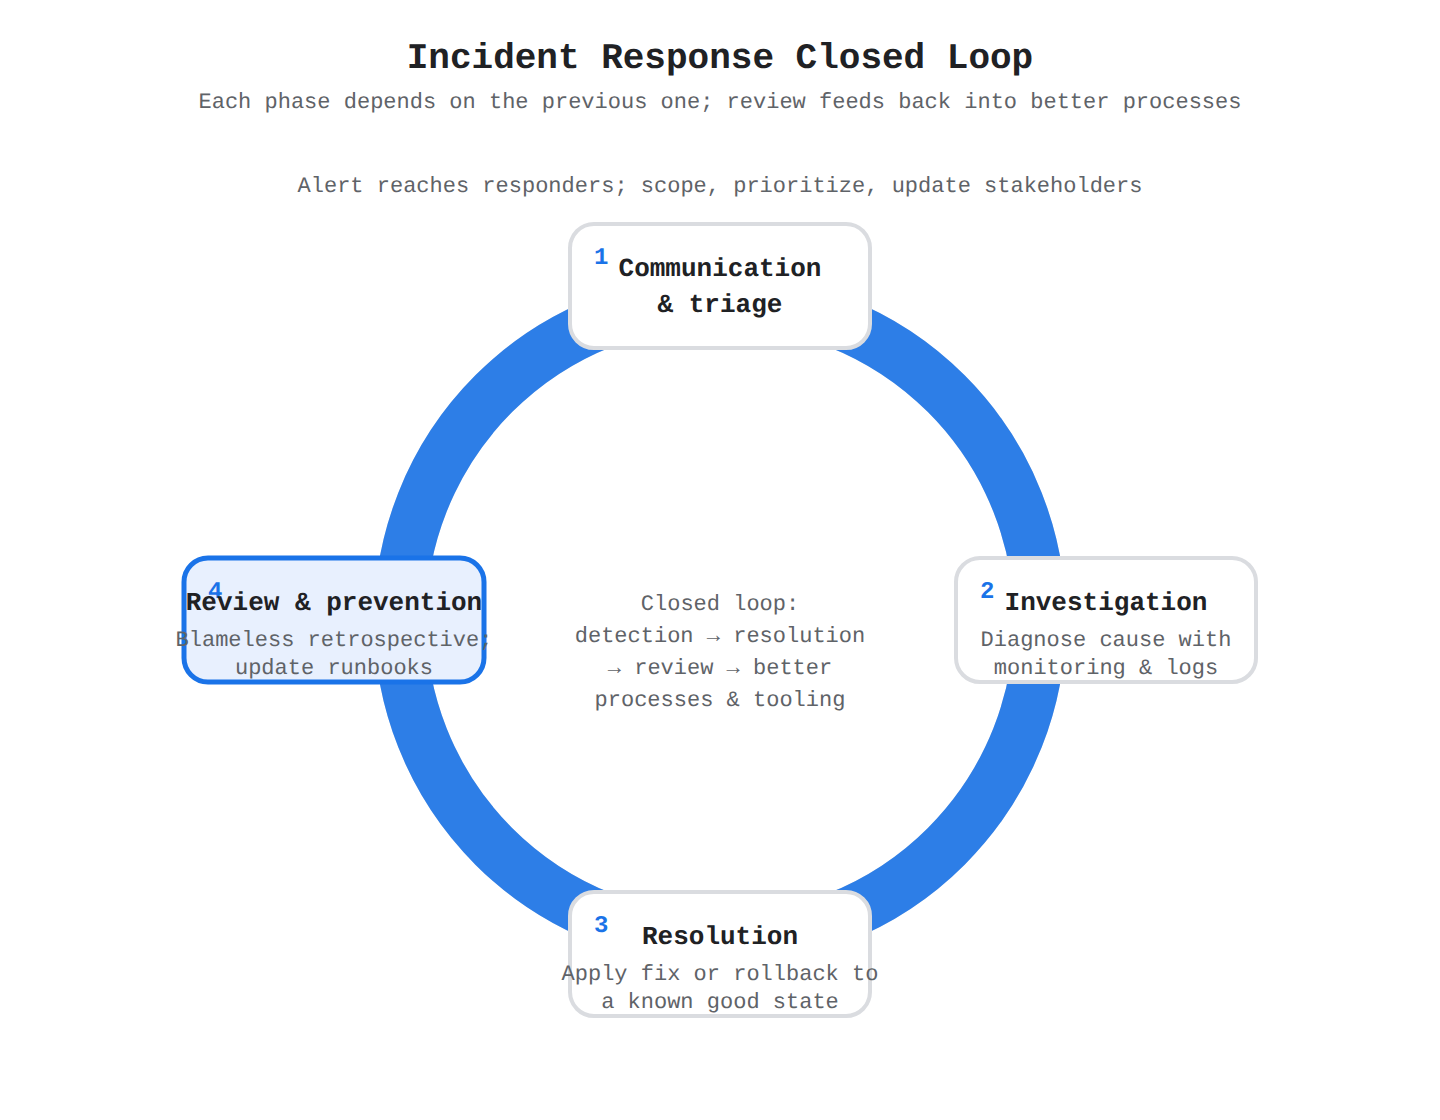
A circular process flow showing the four phases of incident response: communication and triage, investigation, resolution, and review and prevention, with an animated pulse traveling around the loop to show each phase feeding the next and the loop closing back to monitoring.
An incident moves through an ordered response sequence where each phase depends on the previous one:
- Communication and triage: The alert reaches responders, the issue is scoped and prioritized, and status flows to stakeholders.
- Investigation: Investigators and technical experts diagnose the cause using monitoring and logging data.
- Resolution: The team applies a fix or rollback to restore a known good state.
- Review and prevention: A blameless retrospective produces preventive measures and runbook updates.
Automated response connects detection directly to notification and then to remediation. Cloud Run functions (formerly Cloud Functions) or Cloud Run can watch systems, trigger alerts, collect diagnostics, and run remediation such as isolating a system, quarantining a file, or rolling back a change. A shared knowledge base in Google Workspace preserves solutions with version control, and after each incident teams update it with new fixes. Retrospectives use models such as Start-Stop-Continue to decide what to start, stop, and continue, and learning is tracked with Cloud Monitoring for real-time observation and BigQuery for long-term analysis.
Exam tip: An SLI is the measured metric such as error rate, while an SLO is the target for that metric such as error rate below 0.1%.
Observability with Indicators, Objectives, and Dashboards
Observability with indicators, objectives, and dashboards is the practice of collecting metrics, logs, and traces to judge service health. Google Cloud Observability collects telemetry from Google Cloud services, applications, and external sources. Cloud Monitoring analyzes metrics for availability, performance, and latency, while Cloud Logging collects system events for deeper analysis.
A Service Level Indicator (SLI) is a quantitative measure such as average request latency, error rate, or throughput. A Service Level Objective (SLO) is the target value for an SLI, such as latency lower than 100 milliseconds. Cloud Monitoring tracks SLIs over time to verify SLOs and service level agreements (SLAs). Comprehensive monitoring tracks system health such as CPU utilization, memory usage, network traffic, disk I/O, and application response times, plus business-specific metrics. Data flows from monitored resources to Cloud Monitoring for real-time views, then to BigQuery for storage and analysis, then to operational dashboards for visualization. A key performance indicator (KPI) reflects overall performance, while a metric is a specific data point that feeds a KPI.
Automation with Declarative Code and Secure Pipelines
Automation with declarative code and secure pipelines defines infrastructure through machine-readable code instead of manual clicks. Cloud APIs let code provision and manage resources, version control stores that code as truth, and continuous integration/continuous delivery (CI/CD) pipelines make deployments repeatable, testable, and auditable. Declarative Infrastructure as Code (IaC) describes the desired state, and automation brings the environment to that state with a known good state for rollback.
Provisioning and configuration tools divide the work:
| Area | Purpose | Example tools |
|---|---|---|
| Provisioning | Create networks, projects, clusters, and cloud resources | Terraform, Config Controller |
| Configuration | Configure operating systems and software on provisioned resources | Ansible, Chef, Puppet |
| Policy and operations | Enforce constraints and manage operations as code | Open Policy Agent (OPA), Policy Controller, GitOps |
Policy as code checks infrastructure code before deployment, with Policy Controller using OPA as its policy engine in the pipeline. Toil is reduced with Cloud Scheduler triggering work, Cloud Run and Cloud Composer running it, and the Google Cloud CLI scripting Cloud APIs. A typical change follows commit to version control, then automatic policy and security checks, then deployment with tools such as Terraform and Cloud Build, then audit with rollback by reverting code. Application releases use the same idea, where Cloud Build builds and tests artifacts and Cloud Deploy manages progressive delivery from development to test to production.
Familiarity with Google Cloud Observability solutions means knowing how logs, metrics, traces, and profiles flow into centralized analysis and alerting. Telemetry flows from Google Cloud resources to Cloud Logging and Cloud Monitoring, then through sinks to storage or analysis, and through alerting policies to incidents and notifications. Google Cloud Observability agents (opens in a new tab) on virtual machines extend system metrics with application data for this flow.
Centralized Log Routing, Retention, and Cost Control
Centralized log routing is the practice of collecting logs from many projects into one destination for search and retention. A log is timestamped entries where each entry describes one event. Cloud Logging stores, searches, analyzes, and alerts on log data. Data flows from resources to Cloud Logging, then a sink routes matching entries to a chosen destination, while a copy can remain in a log bucket for short-term viewing.
Organization-level sinks centralize entries from many projects, and destinations serve different needs:
- Cloud Storage receives logs for low-cost, long-term archival and compliance.
- BigQuery receives logs for large-scale SQL analysis and security investigation.
- Pub/Sub receives logs for real-time streaming to applications or third-party tools.
Retention is controlled by rules on the log bucket, with custom retention between 1 day and 3650 days applying to all logs in that bucket. Encryption is managed by Google by default, while Customer-managed encryption keys (CMEK) let an organization control keys for advanced requirements. Cost control uses exclusion filters that drop selected entries before storage, so excluded entries avoid bucket charges but lose detail. Data Access audit logs are high-volume and drive most cost, so teams view usage, alert on usage, and exclude them in development projects where compliance does not require them.
Audit Log Types, Queries, and Log-Based Alerts
Audit logs in Cloud Audit Logs record administrative actions, data access, system events, and policy decisions. Analysis in Logs Explorer and Log Analytics shows who acted, on which resource, and whether access was allowed or denied. Centralization at organization or project level lets security teams review the whole environment from one query interface.
Cloud Logging organizes audit logs into four peer types:
- Admin Activity audit logs appear as
activityand record configuration changes. - Data Access audit logs appear as
data_accessand record reads and writes of user-provided data. - System Event audit logs appear as
system_eventand record Google Cloud system actions. - Policy Denied audit logs appear as
policyand record denials based on policy checks.
To retrieve entries, open Logs Explorer for the organization, select the resource type, select the log name, and run the query. Only retained log types present in buckets can be selected. Cloud Monitoring creates an incident when a log entry matches an alerting policy filter and notifies the configured channel. Log-based alerting fires on an individual matching entry, while log-based metrics convert recurring log data into time-series counts or values that a metric policy evaluates for thresholds and trends.
Exam tip: Data Access audit logs are the most expensive to keep because of volume — exclude them in development projects where they are not needed.
Metrics, Traces, and Dashboards Across Layers
Metrics, traces, and dashboards across layers provide real-time visibility from infrastructure to user actions. Infrastructure metrics track CPU, GPU, and TPU usage, memory, network throughput and latency, and disk I/O across managed environments and self-managed resources such as Google Kubernetes Engine (GKE) nodes and Cloud Run instances. Application metrics reflect team-defined workflows such as query execution time, service monitoring observes interactions between microservices, and end-to-end monitoring checks whether users can complete actions such as login or checkout.
The four golden signals give a shared vocabulary for user-facing health: latency is time to respond, traffic is request volume, error rate is rate of failures, and saturation is closeness to capacity limits. Distributions such as 95th percentile are often more informative than averages. As resources are created or applications register with App Hub, Google Cloud creates managed dashboards with health, logs, metrics, and open alerts, while custom dashboards can show metric charts, log data, error groups, alert charts, text, and events. An alerting policy watches a condition such as VM CPU over 80% and notifies through email, Cloud Mobile App, PagerDuty, or Slack. Health checks and synthetic monitors pull endpoints, route around unhealthy VMs, autoheal managed instance groups, and probe HTTP, HTTPS, and TCP with uptime checks.
Cloud Trace assembles instrumented request data into traces of spans that show flow across services, with OpenTelemetry as the recommended vendor-neutral instrumentation. Error Reporting groups repeated errors with the same signature, and log-based metrics count structured log entries over time for visualization in Cloud Monitoring.
Profiling, Benchmarking, and Alert Policy Design
Profiling, benchmarking, and alert policy design link code-level cost to service objectives and precise notifications. A Service Level Indicator is the measured metric such as success rate, while a Service Level Objective is the target such as 99.9% success. Cloud Profiler attributes CPU and memory use to source code, while Cloud Monitoring checks availability, performance, and latency against objectives.
A single profile collects data usually for 10 seconds every 1 minute per instance in one Compute Engine zone, with overhead less than 5 percent during collection and commonly less than 0.5 percent amortized. Support depends on language: Go supports CPU time and heap, Java supports CPU time, heap, and wall time, Node.js supports heap and wall time, and Python supports CPU time and wall time. The agent collects samples on the virtual machine, sends data to the configured project, and the console shows flame graphs, comparisons, and trends. Load testing simulates realistic traffic to validate baselines, while stress testing pushes limits to find bottlenecks. Active Assist suggests rightsizing such as VM resizing.
Alerting connects policy to incident to channel in order. The policy defines data, condition, and notification; Monitoring evaluates continuously, creates an incident when met, and notifies each channel. Metric incidents close automatically when the condition clears.
| Condition type | What triggers it | Example use |
|---|---|---|
| Metric-threshold condition | Value above or below threshold for a retest window | Latency at 500ms or higher for five checks over 10 minutes |
| Metric-absence condition | No data for a window up to 24 hours | No HTTP requests for five minutes |
| PromQL condition | PromQL expression with ratios or dynamic thresholds is true | Ratio of two metrics or evaluation beyond 25 hours |
| Forecasted condition | Forecast predicts violation in 1 hour to 7 days | Disk likely to reach 80% in 24 hours |
Precise policies use tight filters, longer durations to avoid false positives, severity levels, documentation with triage steps, and snoozes rather than schedules. SQL-based policies in Observability Analytics aggregate logs with SQL before deciding to alert.
Continue with this study guide: Familiarity with Google Cloud Observability solutions
Deployment and release management is the standardized path that carries code from source to production as secure, versioned artifacts. Source flows into Cloud Build for compilation and testing, images flow from Cloud Build into Artifact Registry for storage, and releases flow from Artifact Registry through Cloud Deploy to targets in order. Advanced deploy mode (opens in a new tab) in Looker follows the same principle of promoting a verified ref to production.
Standardized Builds with Centralized Artifact Management
Standardized builds with centralized artifact management ensure every deployment starts from the same tested source. Cloud Build runs compilation and testing on Google Cloud infrastructure in isolated and ephemeral environments with granular Identity and Access Management (IAM) permissions and VPC Service Controls. Finished images flow from Cloud Build to Artifact Registry, which provides one universal package manager with versioning, access control, service perimeters, and organizational policies.
Cloud Build produces supply-chain evidence including Supply-chain Levels for Software Artifacts (SLSA) Level 3 support and verifiable build provenance with image digests, source locations, toolchain, build steps, and duration. Security insights show SLSA level, vulnerabilities, and provenance. Artifact Registry handles external and internal packages with distinct repository types:
| Repository type | What it holds | How it helps the pipeline |
|---|---|---|
| Remote repositories | Cached artifacts from Docker Hub, Maven Central, Python Package Index (PyPI), Debian or CentOS, plus user-defined sources | Reduces download time, improves availability, and scans if enabled |
| Virtual repositories | Consolidated same-format repositories behind one endpoint with search order | Prioritizing private packages reduces dependency confusion attacks |
Artifact Analysis scans new images on upload, continuously monitors metadata for new vulnerabilities, and updates occurrences as sources change. Scanning on creation narrows reviews, and a software bill of materials (SBOM) with Vulnerability Exploitability eXchange (VEX) statements documents contents.
Automated Delivery with Promotion and Rollback Controls
Automated delivery with promotion and rollback controls moves only verified artifacts through development, test, and production in sequence. Release artifacts flow from Artifact Registry to Cloud Deploy, and Cloud Deploy promotes them to Google Kubernetes Engine (GKE), GKE Enterprise, and Cloud Run. Cloud Deploy provides approvals, rollbacks, audit, delivery metrics, and security insights.
Promotion is gated by Binary Authorization, which checks attestations at deployment time on GKE or Cloud Run. Attestations certify that a specific build system created the image, that the image meets vulnerability policy, and that it passed promotion criteria from development to quality assurance (QA). Only images with required signatures deploy, with different policies per environment. A rollback is a promotion of a prior stable release through the same pipeline, approvals, and IAM controls, so recovery keeps permissions and audit history. Global resources such as Virtual Private Cloud (VPC) networks and global load balancers need extra review because one misconfigured forwarding rule can stop the frontend even when backends are healthy.
Exam tip: Remote repositories cache external packages for faster builds, while virtual repositories consolidate same-format repositories and prioritize private packages.
Deployment Targets with Progressive Risk Reduction
Deployment targets with progressive risk reduction connect specific runtimes to monitoring that confirms health after release. A delivery pipeline defines the promotion sequence, and each release moves through targets in order. Notifications flow from Cloud Deploy to Pub/Sub topics to external approval systems, while platform and audit logs flow to Google Cloud Observability and Cloud Audit Logs. An automationRun represents each execution of an automation rule that depends on the pipeline for targets and on IAM for permission.
Looker, GKE, Cloud Run, and Monitoring illustrate target-specific mechanics. The Looker API endpoint <HOST_URL>/api/4.0/projects/<PROJECT_ID>/deploy_ref_to_production uses ?branch=<BRANCH_NAME> for the head of a branch and ?ref=<SHA_OR_TAG> for a pinned commit or tag. A GKE Deployment named pubsub uses selector.matchLabels with app: pubsub to bind to pods with the same label, running container subscriber from image us-docker.pkg.dev/google-samples/containers/gke/pubsub-sample:v2. Cloud Run deploys with gcloud run deploy FUNCTION --source . --function <ENTRY_POINT> --base-image BASE_IMAGE, then an Eventarc trigger routes Pub/Sub events of type google.cloud.pubsub.topic.v1.messagePublished from the topic to the service. Progressive delivery deploys narrowly to a few virtual machines (VMs) in one zone, monitors effects, reverts quickly on issue, fixes outside production, and expands gradually only after verification.
Continue with this study guide: Deployment and release management
Assisting with the support of deployed solutions means quickly deciding whether a failure comes from customer code or the Google Cloud platform, then tracking response in one place. Personalized Service Health filters disruptions to owned projects, while the public Service Health dashboard shows all-customer status by region. Together with organization views, application views, and alerts, these tools define blast radius and next action. CloudOps (opens in a new tab) practices for readiness and performance tie these health signals to maintenance and optimization.
Service Health Views with Alerts and Permissions
Service health views with alerts and permissions answer different scope questions about a platform disruption. Google Cloud Service Health at status.cloud.google.com reports status by service and region for all customers. Personalized Service Health in the console at Service Health > Google Cloud Incidents shows only disruptions relevant to owned projects, with scope, symptoms, workarounds, and progress updates filtered by service, location, relevance, and status.
Organization and application scopes aggregate further. Organization Views shows active incidents for any project in the organization, and the Service Health API provides the same events programmatically. Cloud Hub shows incidents for App Hub applications when the incident relates to products supporting App Hub and has Related relevance. Setup requires configuring a folder, setting up App Hub and creating an application, granting servicehealth.events.list plus apphub.applications.get and apphub.applications.list, and enabling the App Hub API.
| View | Scope | Choose when |
|---|---|---|
| Google Cloud Service Health | All customers by service and region | Confirm a suspected regional or global disruption |
| Personalized Service Health | Incidents relevant to owned projects | Evaluate workload impact and coordinate response |
| Organization Views and Service Health API | All projects in an organization | Need aggregated or programmatic cross-project view |
Service Health events flow from Service Health to Cloud Logging to alerting for new incidents, updates, or product- and location-specific events. Essential Contacts customizes recipients at project, folder, or organization level instead of relying only on IAM roles. Enabling Personalized Service Health ahead of time requires the Service Health API and serviceusage.services.enable, included in Owner or Service Usage Admin. GKE insights for GKE_RELIABILITY_INCIDENT name the impacted cluster with incident ID, description, update time, and mitigation, remaining visible until mitigated.
Post-Deployment Maintenance with Rightsizing and Recovery Tests
Post-deployment maintenance with rightsizing and recovery tests keeps solutions reliable, performant, and cost-efficient after go-live. Right-sizing continuously matches allocation to demand, because over-provisioning wastes cost and under-provisioning creates bottlenecks. Data flows from running resources to Cloud Monitoring for utilization visibility, and Recommender analyzes that data to suggest new sizes. Custom metrics and threshold alerts trigger adjustments before degradation.
Autoscaling adjusts capacity within minimum and maximum bounds as workload fluctuates. Compute Engine managed instance groups (MIGs) scale groups of VMs as one entity, for example adding VMs when CPU passes a threshold and removing them when it falls. Continuous optimization reassesses architecture as traffic, behavior, and dependencies change, planning for critical periods such as seasonal peaks, audit days, tax season, or trading hours with peak testing and code freezes. Disaster recovery testing follows the planning guide, with resilience tests escalating from intermittent failures to blocked dependencies to blocked network communication to terminated hosts, validating retries, fallbacks, degradation, and redistribution at each stage. Maintenance uses unified setup guidance, IaC in source control deployed through CI/CD, and immutable redeploys rather than in-place edits for predictable rollbacks.
Exam tip: Cloud Monitoring shows what resources are using, while Recommender suggests how to resize them.
Diagnosis with Centralized Logs and Metrics
Diagnosis with centralized logs and metrics collects evidence once and reuses it for detection and repair. Log data flows from infrastructure and application sources to centralized collection, dashboards make health visible, alerting policies evaluate signals, and alerts lead back to the same logs and metrics for root-cause analysis. Support follows monitoring and analysis, then alerting on thresholds or anomalies through channels, then troubleshooting and remediation with centralized evidence.
Cloud Logging and Cloud Monitoring provide the shared foundation. Monitoring observes performance, health, and security events through dashboards and visualizations. An alerting policy applies to a metric or log-based signal and notifies a configured channel when its condition is met. Troubleshooting flows from alert or symptom to correlated logs and metrics to failing component, then back to the affected system for repair. Centralized observability improves visibility, early mitigation, security monitoring with audit trails, faster troubleshooting, operational efficiency, and compliance with data residency when data stays in the required environment.
Continue with this study guide: Assisting with the support of deployed solutions
Evaluating quality control measures means measuring service behavior from the user's view and validating every change before it reaches production. Holistic observability links reliability goals to layered metrics to continuous improvement in order: first select measurements, then set targets, then manage risk with allowed error. Monitor applications (opens in a new tab) guidance connects these health signals to scaling and maintenance decisions.
Service Indicators, Objectives, and Error Budgets
Service indicators, objectives, and error budgets turn user experience into measurable targets. A Service Level Indicator (SLI) measures one aspect of good service, such as request counts with 2xx or 5xx responses and response latencies. Cloud Monitoring collects these metrics, auto-identifying useful metrics for Cloud Service Mesh, Istio on GKE, and App Engine, while other workloads define custom service types.
Standard SLIs are ratios:
| SLI type | What is counted | Example of good service |
|---|---|---|
| Request-based | Atomic units of service | Successful HTTP requests out of all requests |
| Windows-based | Time periods meeting a criterion | Minutes where latency stays below threshold |
An availability SLI is successful responses divided by all responses, while a latency SLI is calls below threshold divided by all calls. AI-specific SLIs add success rate, time to first token (TTFT), harmful-response rate, and model FLOPS utilization (MFU). A Service Level Objective (SLO) combines an SLI, a performance goal, and a compliance period, with up to 500 SLOs per service and a highest settable value of 99.9%. Examples include 99.9% successful API calls, 95th percentile latency below 300 ms, TTFT below 500 ms for 99% of requests, and harmful output below 0.1%. Rolling periods such as last 30 days continuously slide, while calendar periods such as a week extrapolate from elapsed time. An error budget starts at 1 minus the SLO, such as 0.1% for 99.9%, and declines as misses consume it. Fast burn pauses releases and triggers scaling, while slow burn allows feature work. Saturation of CPU, memory, GPU, or TPU plus traffic volume guides scaling alongside budget signals.
Validated Releases with Health-Aware Traffic Management
Validated releases with health-aware traffic management test changes in isolation and send traffic only to healthy instances. Automated testing in CI/CD validates application changes before deployment, and Terraform validate and plan on every commit validates infrastructure code. The pipeline triggers on commit through Cloud Build and Infrastructure Manager, runs validation and test suites, and promotes versioned artifacts across dev, staging, and prod. Coverage includes unit testing of isolated units, integration testing of service interactions, end-to-end testing of user workflows, plus performance and load testing with Cloud Load Balancing simulations to tune resources before release.
Isolated environments use separate dev, QA, and staging instances, such as ticketing-system-dev, ticketing-system-qa, and ticketing-system-staging created declaratively. Terraform with modular templates and Cluster Toolkit blueprints keeps environments consistent and rollback-capable, while Config Connector manages configuration declaratively. During rollout, load balancers pull health checks and send traffic only to passing instances, Kubernetes liveness and readiness probes manage pods, and health checks autoheal Compute Engine MIGs by recreating unhealthy VMs. Regional MIGs and GKE regional clusters survive zone outages, with critical topologies using at least two regions with three zones each, traffic from Cloud DNS and load balancers spread across them, and capacity overprovisioned by a third for failover. Data redundancy uses Cloud SQL high availability (HA), regional persistent disks with synchronous replication, and multi-region Spanner and Cloud Storage. Chained availability multiplies, so four 99.9% tiers yield about 99.6%, while parallel availability follows 1 minus the product of failure rates.
Exam tip: HA applies to regional deployments with synchronous replication and zero or near-zero RTO and RPO, while DR applies to multi-region deployments with typically asynchronous replication.
Continuous Testing with Supply-Chain Enforcement
Continuous testing with supply-chain enforcement builds, checks, and signs every change before delivery. Data flows from source through Cloud Build to Artifact Registry and then to Cloud Deploy, with each step depending on the prior success. The ordered CI workflow is commit triggering build, building and pushing an image with a digest, running language-specific automated tests, scanning structure and vulnerabilities, signing with Binary Authorization, and creating a Cloud Deploy release. The digest ensures the tested image is the deployed image.
Functional checks include linters during review and tests after integration, with Container Structure Tests verifying commands, file existence, file content, and metadata such as labels and entrypoints. Security testing uses Artifact Analysis for Common Vulnerabilities and Exposures (CVE) with Common Vulnerability Scoring System (CVSS) severities of critical, high, medium, low, or minimal, plus Web Security Scanner for cross-site scripting and misconfigurations on App Engine, Compute Engine, and GKE. Binary Authorization enforces supply-chain security with policies, notes, attestations, attestors, and signers. The enforcer allows GKE deployment only when images have required signatures for scans, quality tests, or owner sign-off, blocking others unless breakglass bypass is used and logged in Cloud Audit Logs.
Continue with this study guide: Evaluating quality control measures
Ensuring the reliability of solutions in production (e.g., chaos engineering, penetration testing, and load testing)
Ensuring reliability in production proves that applications meet Service Level Objectives under realistic, extreme, and hostile conditions. Traffic flows from clients through Cloud Load Balancing to backends in managed instance groups or Kubernetes clusters, so tests must validate every layer together. How Google protects its production services (opens in a new tab) includes periodic zone and region disconnect testing that informs customer resilience practices.
Load Testing with Benchmarking and Capacity Planning
Load testing with benchmarking and capacity planning simulates traffic to find acceptable limits and provision for peaks. External measurements show client experience, while internal measurements show host limits, so complete tests collect both to link slow responses to specific constraints. Key measures include request throughput per second, request concurrency, connection throughput per second including Transport Layer Security (TLS) overhead, connection concurrency using RAM and file handles, request latency from start to end, error rate with HTTP 5xx or closed connections, system use of CPU, RAM, and sockets, and bounded resources such as worker thread pools and backend connection pools.
Capacity planning and overload testing answer different questions:
| Approach | Question it answers | How success is judged |
|---|---|---|
| Capacity planning | What load keeps performance acceptable | Request rate keeping 99th-percentile latency below SLO at optimal resource use |
| Overload testing | What happens past limits | Whether throughput and errors shed load gracefully or crash |
Benchmarking learns how load drives CPU and memory use, repeated at normal and peak loads because efficiency changes over time. Results feed autoscaling for Compute Engine MIGs and GKE clusters, tuning thread pools, machine types, and disks. Capacity planning follows forecast of users and request rate, estimation of MIG size and disks with Pricing Calculator, N+1 redundancy with at least one extra component per tier, benchmark tuning, and quota and reservation management. Resource quotas limit creatable resources while rate quotas limit API requests per period across zonal, regional, and global scopes. When testing with an Application Load Balancer, first benchmark backends alone to find app versus pool versus host bottlenecks, then test with the balancer for distribution, health checking, and autoscaling.
Security Assessments with Penetration Testing
Security assessments with penetration testing systematically check customer workloads for flaws that could become outages. Under shared responsibility, Google protects physical infrastructure, control planes, and global services, while customers monitor applications, configure audits and logging, and report incidents. Global resources such as VPC networks and global load balancers are single points of failure, so tests touching them are high-risk, verified before production, and rolled out progressively to a few resources in one zone first.
Vulnerability scanning covers both supply chain and runtime. Artifact scanning checks stored images and packages before promotion, while runtime scanning checks running containers and VMs for new exposures. Findings flow from scanner to centralized monitoring to remediation under a flaw-remediation service-level agreement (SLA). Controls include configuring artifact scanning, configuring runtime scanning, and creating cleanup policies to remove old unpatched images. Security Command Center centralizes posture and analytics at organization level when enabled. Telemetry includes Cloud Audit Logs for IAM and firewall changes, VPC Flow Logs and Firewall Rules Logging for VM and GKE traffic including denied ingress, and Cloud Identity and Access Transparency logs for identity and Google access. Common checks include two-step verification, minimum TLS 1.2, Cloud Key Management Service (Cloud KMS) key rotation every 90 days, service account key rotation within 90 days, and restricted API keys.
| Test type | Primary question | How it runs in production |
|---|---|---|
| Vulnerability assessment | What known flaws exist | Automated scanning of images, VMs, buckets, keys, and IAM plus log review |
| Penetration test | Can weaknesses be chained for access or disruption | Controlled scoped simulation against owned apps and configs |
| Load and stress test | Will availability hold under peak or extreme traffic | Progressive simulated traffic through load balancers with monitoring |
Exam tip: Artifact scanning checks stored images before deployment, while runtime scanning checks workloads already running; enable both.
Chaos Engineering with Automated Recovery Validation
Chaos engineering with automated recovery validation intentionally injects faults to prove recovery meets recovery time objective (RTO) and recovery point objective (RPO) without manual rescue. RTO measures time until service resumes, while RPO measures acceptable data loss. Google validates zone and region failure by disconnecting a production-equivalent internal region that is architecturally identical to customer regions, confirming local services go offline while other zones and regions stay unaffected on a periodic schedule.
Workload experiments test 1, 5, 10, or 30 minute zone or region outages and ask what customers experience, how detection happens, what happens to the app and data and dependencies, what recovery work and notifications are required, and who performs them. Business-critical operations must depend only on data-plane components that continuously process operations, not management-plane operations such as VM-creation APIs or permission updates that may be unavailable during the outage. Automated recovery uses MIGs recreating failed VMs from templates, Cloud Load Balancing health checks rerouting from unhealthy zones, regional Persistent Disk synchronous replication within a region, and multi-regional Cloud Storage and Spanner for active-active continuity.
| Resource scope | Resilience | Recovery expectation during test |
|---|---|---|
| Zonal | Low | Zone failure affects zone resources; traffic must shift elsewhere |
| Regional | Medium | Survives single-zone failure; region outage affects region |
| Multi-region or global | High | Continues from another region; risk shifts to config changes |
Google Cloud Observability with Cloud Monitoring collects metrics, traces, and logs to verify backup intervals, replication lag, and recovery time against RTO, RPO, and error budgets. Regular load and chaos tests maintain peak performance, reveal bottlenecks, validate graceful recovery, supply capacity data, gate CI/CD changes, and demonstrate compliance.
Key Facts
- An SLI measures service level such as latency or error rate, while an SLO is the target value such as latency below 100 milliseconds or 99.9% success.
- Data flows from monitored resources to Cloud Monitoring for real-time views, then to BigQuery for storage and analysis, then to operational dashboards for visualization.
- A log sink in Cloud Logging routes matching entries to Cloud Storage for archival, BigQuery for SQL analysis, or Pub/Sub for real-time streaming.
- Source code flows into Cloud Build for testing, built images flow into Artifact Registry for versioned storage, and releases flow through Cloud Deploy to target environments in order.
- High availability uses regional synchronous replication with zero or near-zero recovery time objective and recovery point objective, while disaster recovery uses multi-region typically asynchronous replication with planned objectives.
Frequently Asked Questions
What is the difference between a Service Level Indicator (SLI) and a Service Level Objective (SLO) in Google Cloud Observability?
A Service Level Indicator (SLI) is a quantitative measure such as average request latency, error rate, or throughput, while a Service Level Objective (SLO) is the target value for an SLI such as latency lower than 100 milliseconds. Cloud Monitoring tracks SLIs over time to verify SLOs and service level agreements (SLAs).
When should I use Cloud Storage, BigQuery, or Pub/Sub as a destination for a Cloud Logging log sink?
A log sink in Cloud Logging routes matching entries to Cloud Storage for low-cost, long-term archival and compliance, to BigQuery for large-scale SQL analysis and security investigation, or to Pub/Sub for real-time streaming to applications or third-party tools.
What is the difference between high availability (HA) and disaster recovery for Google Cloud workloads?
High availability (HA) uses regional synchronous replication with zero or near-zero recovery time objective (RTO) and recovery point objective (RPO), while disaster recovery uses multi-region typically asynchronous replication with planned objectives.
Subdomains
Observability and Site Reliability Engineering (SRE) metrics are the practice of measuring how a cloud service behaves from the user's view and using those measurements to guide operations. Holistic o…
Incident management and continuous improvement is the practice of limiting harm when a cloud failure happens and using what is learned to make operations stronger. In this practice, incident response …
Execute Load Testing and Performance Benchmarking is the practice of simulating realistic and extreme traffic to prove that an application meets its Service Level Objectives (SLOs) under normal and pe…
Centralized log routing with sinks is the practice of collecting logs from many projects into one central place for search, analysis, and retention. A log is a record of system or application activity…
Designing automated CI/CD pipelines and artifact management means standardizing how code moves from source to production so only secure, versioned artifacts are deployed. Source code flows into Cloud …
Managing incident lifecycles and service health means deciding quickly whether a failure comes from your own code or from the Google Cloud platform, then tracking the response in one place. **Personal…
How learners score on this domain
Last updated