Fundamental
Prepare and test your skills
Fundamental
Prepare and test your skills
Structured Transaction Data and Unstructured Media Storage
Free sample question, answered and explained below. The Generative AI Leader practice bank has 2,191 more like it. Try 10 free: instant score, no account.
An enterprise is planning a data management architecture to support downstream generative AI workflows. The organization has two distinct data sources:
- Customer transaction records: Tabular account numbers, purchase timestamps, and currency amounts with a rigid, predefined schema
- Customer support recordings and manuals: Audio files, support chat transcripts, and PDF product manuals that lack a uniform, row-and-column structure
How should the enterprise categorize these data sources and select their primary storage environments?
Explanations
Both data sources are classified as structured data because all enterprise business data requires a relational database schema before use in AI systems.
Both data sources are classified as structured data because all enterprise business data requires a relational database schema before use in AI systems.
What This Option Suggests
This option incorrectly assumes that all enterprise data must be structured and converted into predefined relational schemas before it can be utilized or processed by generative AI applications.
Why It Doesn't Meet the Requirement
- Mischaracterizes unstructured formats: Audio files, transcripts, and PDF documents cannot be easily shoehorned into a static tabular database without losing context or requiring intensive transformations.
- Misunderstands Gen AI capabilities: Modern foundation models and generative AI systems are specifically built to process unstructured data (such as raw text, audio, and images) directly without forcing it into tabular relational database structures first.
Key Characteristics and Limitations
- A majority of modern enterprise data (estimated at 80-90%) is unstructured.
- Forcing all content into relational databases introduces severe administrative overhead, storage bloat, and rigid schema maintenance challenges.
This Answer Would Be Correct If
- The organization were strictly using legacy rule-based reporting tools that cannot parse or index raw text, media files, or schema-less documents.
Transaction records are unstructured data best stored in object storage, whereas audio recordings and PDF manuals are structured data best stored in relational databases.
Transaction records are unstructured data best stored in object storage, whereas audio recordings and PDF manuals are structured data best stored in relational databases.
What This Option Suggests
This option inverts the core definitions of data types and their corresponding storage systems by treating tabular data as unstructured and multimedia/document files as structured.
Why It Doesn't Meet the Requirement
- Incorrect data classification: Transaction records contain discrete, highly organized data points (e.g., numbers, dates) that naturally fit relational models, making them structured, not unstructured.
- Incompatible storage pairing: Storing raw audio recordings and complex PDF files in a traditional relational database is inefficient and problematic, as relational engines are not designed to natively index or manage large, schema-less binary payloads without extensive overhead.
Key Characteristics and Limitations
- Relational databases require predefined schemas (tables, columns, data types), which arbitrary audio and PDF files do not possess.
- Object storage is optimized for static binary objects and files, whereas tabular transactional systems require rapid record-level updates and ACID guarantees.
This Answer Would Be Correct If
- Transaction records consisted of open-ended, free-form narrative paragraphs and audio was pre-parsed into strictly defined numerical frequencies and tabular timestamps designed for relational table insertion.
Both data sources are classified as unstructured data and must be stored exclusively in block storage volumes for machine learning processing.
Both data sources are classified as unstructured data and must be stored exclusively in block storage volumes for machine learning processing.
What This Option Suggests
This option categorizes both transactional tabular data and media documents as unstructured, asserting that they must reside solely on low-level block storage devices for machine learning access.
Why It Doesn't Meet the Requirement
- Ignores structured properties: Tabular transaction logs possess strict mathematical and temporal structures with explicit schemas, classifying them definitively as structured data.
- Misidentifies optimal storage: Block storage (such as persistent virtual disks attached to individual compute instances) is designed for direct virtual machine file systems, not as a central, scalable repository for enterprise-wide data distribution or multi-modal AI grounding.
Key Characteristics of Block Storage
- Operates at the disk-block level and is typically tied to specific virtual machine instances.
- Lacks the high-level metadata tagging, global accessibility, and lifecycle management features native to object storage and managed databases.
This Answer Would Be Correct If
- The scenario focused specifically on provisioning raw virtual disk drives for low-latency operating system partitions and ephemeral scratch space for a single training VM instance.
Transaction records are structured data best stored in relational databases, whereas audio recordings and PDF manuals are unstructured data best stored in object storage.
Transaction records are structured data best stored in relational databases, whereas audio recordings and PDF manuals are unstructured data best stored in object storage.
What Structured and Unstructured Data Are
Structured data is highly organized information that conforms to a rigid, predefined schema or tabular format consisting of rows and columns. Unstructured data refers to information that does not have a predefined conceptual model, rigid schema, or tabular structure, encompassing text files, images, video, and audio recordings.
Structured vs Unstructured Storage for GenAI
System Architecture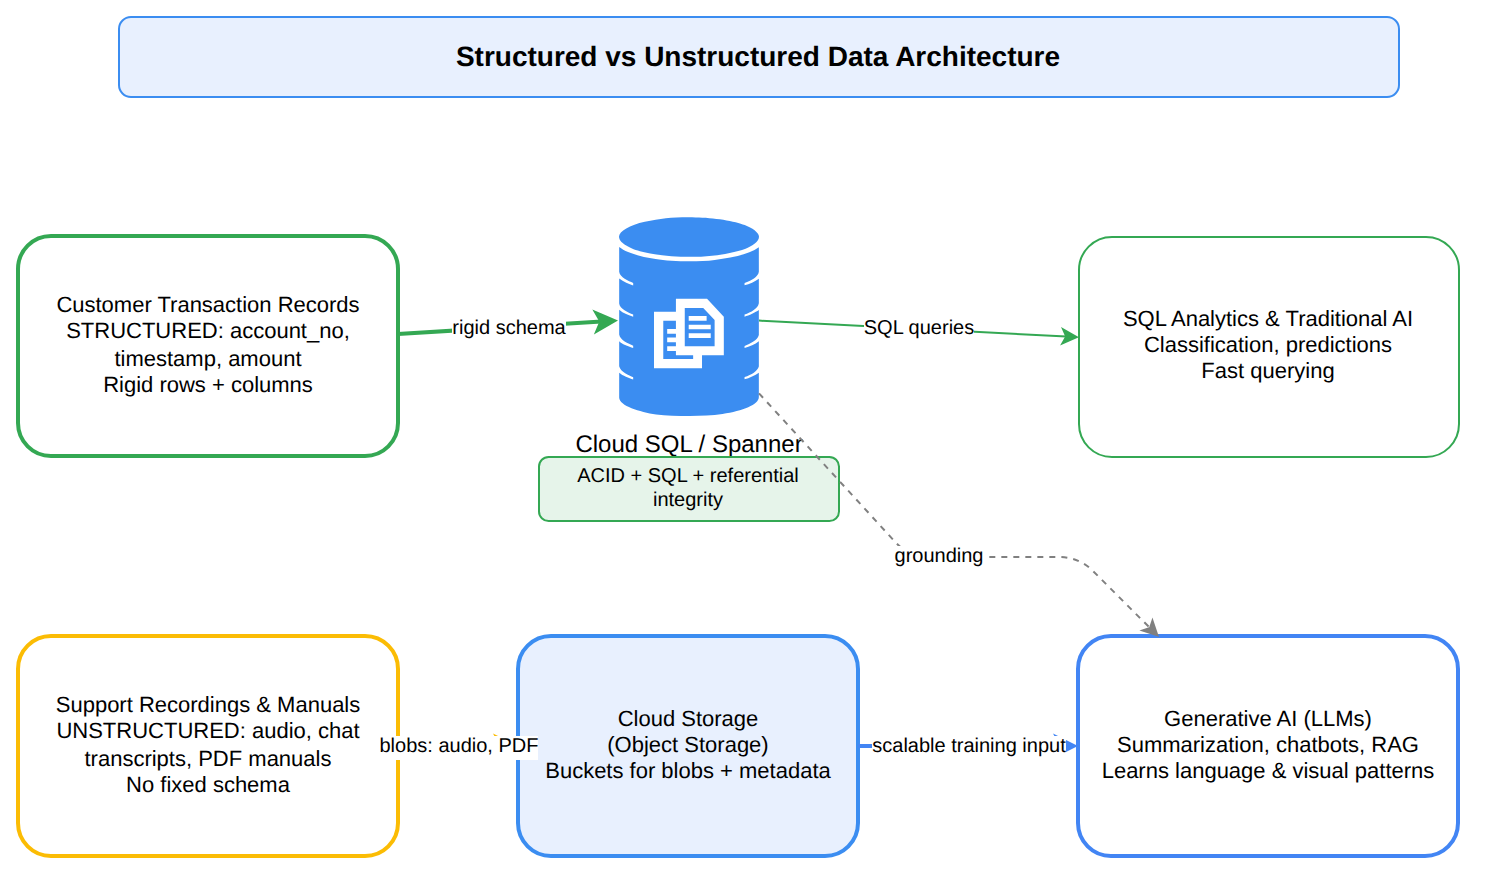
How It Meets the Requirements
- Customer transaction records: Transaction amounts, dates, and account identifiers strictly adhere to predefined data types and relational models, making them classic examples of structured data properly housed in relational databases (such as Cloud SQL or Spanner) or structured data warehouses.
- Support recordings and PDF manuals: Multi-format content like audio files, long-form PDF manuals, and rich documents lack fixed columnar schemas. They represent unstructured data and are ideally stored in scalable object storage (such as Cloud Storage).
Key Advantages and Storage Characteristics
- Relational Databases for Structured Data: Enforce referential integrity, support ACID transactions, and enable rapid querying via standard SQL queries.
- Object Storage for Unstructured Data: Provides virtually limitless scalability, cost-effective storage for large binary and media objects (blobs), and flexible metadata tagging.
- Generative AI Readiness: Large language models and multimodal foundation models excel at ingesting and extracting insights from unstructured data in object stores, while traditional analytical pipelines often query structured data repositories.
Why This Is Optimal
This architecture accurately distinguishes between schema-enforced relational records and raw multimedia files, ensuring optimal query performance, cost efficiency, and straightforward integration with modern AI and analytics platforms.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,191 practice questions across all 4 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
FundamentalGenerative AI Leader
Structured vs Unstructured Data
Identifying the differences between structured and unstructured data, and identifying real-world examples of each type
FundamentalGenerative AI Leader
RAG with Structured Metadata
Identifying the differences between structured and unstructured data, and identifying real-world examples of each type
FundamentalGenerative AI Leader
Grounding with Google Search
Grounding with Google Search
FundamentalGenerative AI Leader
Labeled Data and Supervised Learning
Identifying the differences between labeled and unlabeled data
FundamentalGenerative AI Leader
Vertex AI AutoML
Describing how Google Cloud's AI platform democratizes AI development (e.g., low-code and no-code tools, pre-trained models, APIs)
IntermediateProfessional Cloud Architect
IAM Recommender Role Recommendations
Identity and Access Management (IAM)
Last updated