Fundamental
Prepare and test your skills
Fundamental
Prepare and test your skills
Labeled Data Enables Supervised Email Classification
Free sample question, answered and explained below. The Generative AI Leader practice bank has 2,191 more like it. Try 10 free: instant score, no account.
A retail company wants to train a machine learning model to automatically route incoming customer support emails to the correct department, such as Billing, Technical Support, or Shipping.
The project team compiles a dataset containing thousands of past customer emails, where each email is explicitly paired with the verified department tag that resolved the issue.
Which statement correctly describes this dataset and the learning method used?
Explanations
It is environment state data for reinforcement learning, which trains an agent to route emails via continuous reward signals and penalties during trial-and-error actions.
It is environment state data for reinforcement learning, which trains an agent to route emails via continuous reward signals and penalties during trial-and-error actions.
What Reinforcement Learning Is
Reinforcement learning (RL) is a machine learning paradigm where an autonomous agent learns to make a sequence of decisions by interacting with a dynamic environment. Rather than learning from static labeled datasets, the agent observes the current state, executes an action, and receives feedback in the form of numerical rewards or penalties, iteratively optimizing a policy to maximize cumulative rewards over time.
Why It Doesn't Meet the Requirement
- Incorrect data structure: The scenario uses a static historical collection of emails paired with verified tags, not a real-time interactive environment with dynamic reward feedback.
- Wrong operational paradigm: Categorizing static text records is solved via standard supervised pattern recognition, not through multi-step trial-and-error policy optimization.
- Inefficient approach: Using RL for a straightforward text classification task introduces unnecessary complexity, high computational cost, and instability compared to supervised learning.
Key Characteristics and Limitations
- Action-reward loop: Requires an environment simulator or live interactive system capable of providing reward signals.
- Sequential decision-making: Designed for tasks where current actions influence future states (e.g., game playing, robotic navigation, traffic routing).
- High sample complexity: Typically requires millions of trial-and-error iterations to learn effective policies.
This Answer Would Be Correct If
- The scenario involved an autonomous robotic agent learning warehouse navigation paths based on collision penalties and delivery rewards.
- The goal was dynamic real-time traffic signal management or algorithmic trading where actions alter system states over time.
It is unlabeled data designed for unsupervised learning, which allows the model to group emails into arbitrary clusters without predefined target outcomes.
It is unlabeled data designed for unsupervised learning, which allows the model to group emails into arbitrary clusters without predefined target outcomes.
What Unlabeled Data and Unsupervised Learning Are
Unlabeled data consists of raw inputs (such as text documents, images, or sensor logs) that have no associated target tags, category names, or ground truth annotations. Unsupervised learning algorithms ingest this unlabeled data to discover hidden patterns, underlying structures, anomaly distributions, or natural groupings (clustering) on their own without human guidance on the correct answer.
Why It Doesn't Meet the Requirement
- Predefined business categories: The company has specific, predefined departments (Billing, Technical Support, Shipping) that emails must route to. Unsupervised clustering identifies mathematical similarities but cannot automatically assign meaningful business labels.
- Ignores verified labels: The scenario explicitly states that each historical email has already been paired with a verified department tag, meaning the dataset is labeled rather than unlabeled.
- Outcome mismatch: Unsupervised learning is meant for exploratory discovery, not for training models to predict specific target classes.
Key Characteristics and Limitations
- No ground truth: Models operate without feedback on whether a specific grouping is correct.
- Exploratory utility: Primarily used for customer segmentation, dimensionality reduction, anomaly detection, and data visualization.
- Label absence: Cannot perform standard supervised classification without subsequent labeling or post-processing.
This Answer Would Be Correct If
- The company had a large collection of customer feedback with no assigned tags and wanted to discover emerging topics or unexpected complaint themes.
- The goal was visualizing customer communication networks or clustering user behavior without predefined target categories.
It is validation-only data used to program deterministic heuristic rules, eliminating the need to train machine learning parameters.
It is validation-only data used to program deterministic heuristic rules, eliminating the need to train machine learning parameters.
What Validation Data and Heuristic Rules Are
Validation data is a specific subset of a curated dataset separated from training data to evaluate model performance, tune hyperparameters, and detect overfitting during development. Heuristic rules (rule-based programming) rely on manually written if-then logical statements constructed by human programmers rather than statistical patterns learned by machine learning models.
Why It Doesn't Meet the Requirement
- Mischaracterizes the dataset role: The paired historical records serve as the primary training data (often split into training, validation, and testing sets) to optimize model parameters, not merely for evaluating static rules.
- Bypasses machine learning: The objective is explicitly to train a machine learning model. Relying strictly on manually crafted heuristic rules ignores machine learning altogether and struggles with the nuanced, variable nature of human language.
- Inflexible to natural variation: Hard-coded keyword heuristics frequently fail when customer support emails contain typos, novel phrasing, or ambiguous complaints.
Key Characteristics and Limitations
- Manual overhead: Rule-based systems require ongoing human maintenance as language and business categories evolve.
- Validation role: In machine learning workflows, validation sets are used alongside training sets, not as a replacement for model training.
- Dataset splitting: Comprehensive ML workflows split curated data into training, validation, and testing subsets to ensure reliable generalization.
This Answer Would Be Correct If
- The team decided against using artificial intelligence and instead implemented simple keyword-matching scripts in an email gateway.
- The question asked specifically about the subset of data set aside exclusively to tune hyperparameters and check for model overfitting without updating baseline weights.
It is labeled data containing ground truth tags, which enables a supervised learning model to learn patterns from historical examples and predict discrete categories.
It is labeled data containing ground truth tags, which enables a supervised learning model to learn patterns from historical examples and predict discrete categories.
What Labeled Data and Supervised Learning Are
Labeled data consists of raw input samples (such as text, images, or audio) paired with an explicit target tag, annotation, or ground truth. In machine learning, ground truth represents the verified, correct answer or outcome for each specific example. Supervised learning is the training methodology where an algorithm is provided with these labeled input-output pairs so it can learn the mathematical relationships and patterns connecting features to outcomes.
How It Meets the Requirements
- Target tags and ground truth: Each past email is paired with its verified department (the label), giving the algorithm explicit target outcomes to learn from.
- Supervised classification: Categorizing emails into distinct buckets (Billing, Technical Support, Shipping) is a classic classification task, a core branch of supervised learning.
- Historical pattern learning: The model analyzes features within historical emails—such as keywords, tone, and phrasing—to map them to the corresponding department labels, enabling accurate routing for new, unseen messages.
Supervised Email Classification Flow
Process Flow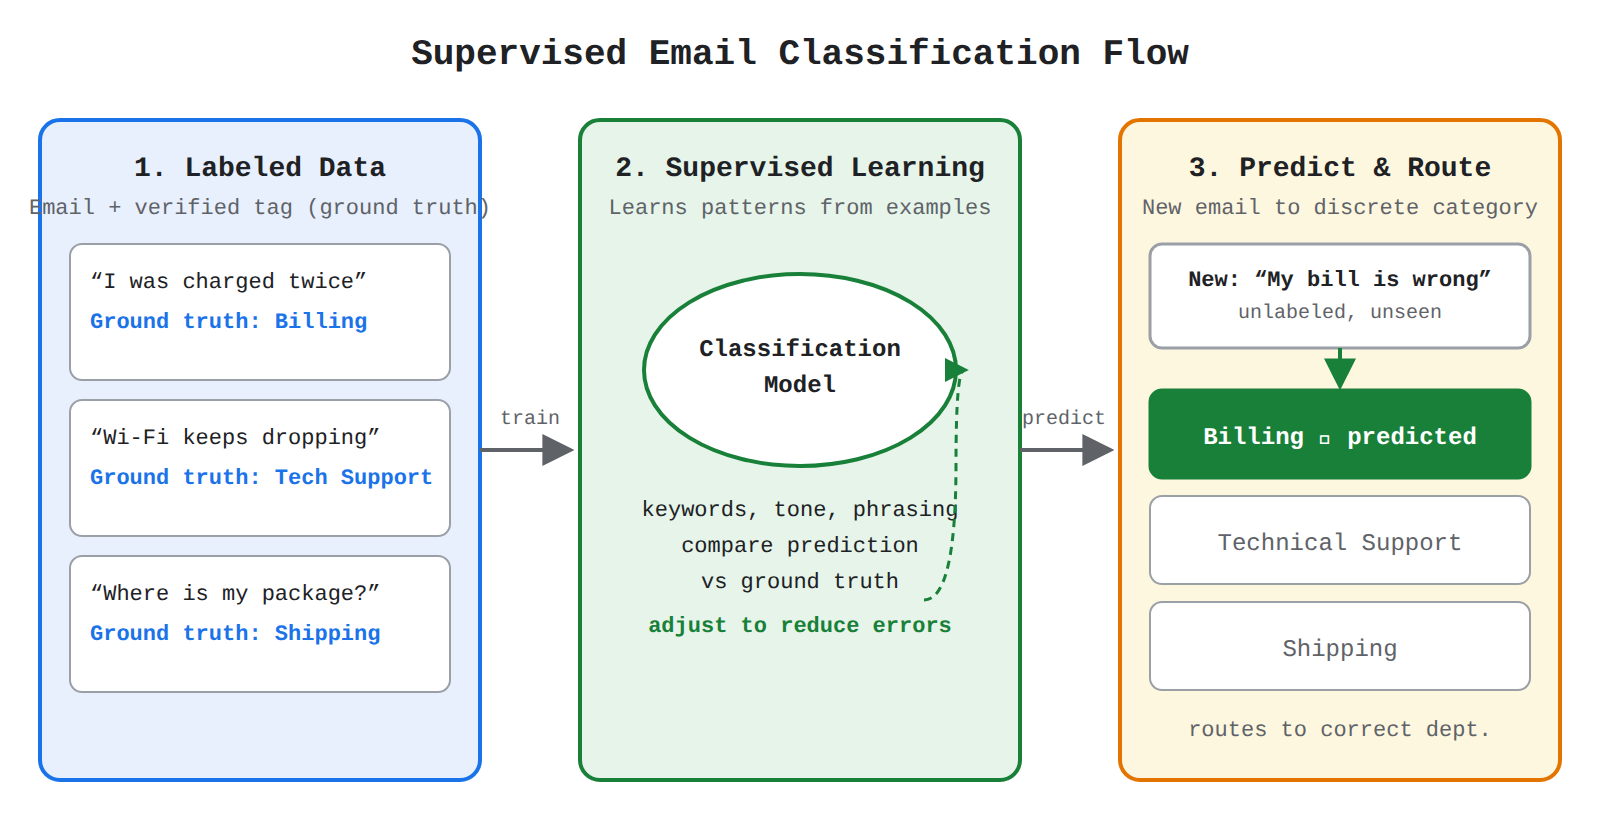
Key Advantages and Capabilities
- Predictable target mapping: Supervised learning with labeled datasets provides clear objective metrics (e.g., accuracy, precision, recall) during model validation and testing.
- High domain precision: By training on human-verified ground truth, models can achieve high accuracy on specialized business tasks like diagnostic screening, text classification, and fraud detection.
- Direct evaluation: Performance can be tested immediately by comparing model predictions against known validation labels.
- Support for classification and regression: The same supervised paradigm powers both discrete categorical classification (e.g., routing tickets) and continuous numerical regression (e.g., forecasting sales amounts).
Why This Is Optimal
Supervised learning on labeled data is the most reliable approach when the desired output classes are well-defined in advance. Because the company already has verified historical examples of emails mapped to specific departments, providing these ground truth pairs allows the model to optimize its parameters directly for accurate category prediction.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,191 practice questions across all 4 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
FundamentalGenerative AI Leader
Unsupervised Pre-training vs Supervised Fine-tuning
Identifying the differences between labeled and unlabeled data
FundamentalGenerative AI Leader
Google Cloud Pre-trained AI APIs
Describing how Google Cloud's AI platform democratizes AI development (e.g., low-code and no-code tools, pre-trained models, APIs)
FundamentalGenerative AI Leader
Multimodal Models With Streaming Responses
Identifying how to choose the appropriate foundation model for a business use case (e.g., modality, context window, security, availability and reliability, cost, performance, fine-tuning, and customization)
FundamentalGenerative AI Leader
Imagen Background Replacement Foreground Preservation
Imagen
FundamentalGenerative AI Leader
Fine-Tuning Data and Model Artifact Security
Identifying how to choose the appropriate foundation model for a business use case (e.g., modality, context window, security, availability and reliability, cost, performance, fine-tuning, and customization)
AdvancedProfessional Data Engineer
Dataplex Lakes Zones Policy Tags
Building a data platform based on requirements by using Google Cloud tools (e.g., Dataplex, Dataplex Catalog, BigQuery, Cloud Storage)
Last updated