Fundamental
Prepare and test your skills
Fundamental
Prepare and test your skills
How LLMs Memorize and Leak Private Training Data
Free sample question, answered and explained below. The Generative AI Leader practice bank has 2,191 more like it. Try 10 free: instant score, no account.
An enterprise customer service department is deploying a generative AI virtual assistant to handle complex customer inquiries. To improve response accuracy, the engineering team fine-tunes a foundational large language model using historical support tickets, email logs, and customer chat transcripts containing resolution details.
During security testing, engineers discover that specific prompt queries cause the model to output verbatim excerpts of unredacted customer names, home addresses, and private account details that were present in the historical support transcripts.
Which generative AI privacy vulnerability does this scenario demonstrate?
Explanations
Model hallucination
Model hallucination
What Model Hallucination Is
Model hallucination refers to the tendency of large language models to generate plausible-sounding but factually incorrect, fabricated, or nonsensical information that has no basis in the training data or grounded context.
Why It Does Not Meet the Requirement
- Fabrication versus factual exposure: The scenario describes the model outputting real, authentic customer details and exact historical records rather than generating fictional or made-up information.
- Distinct operational cause: Hallucinations arise from statistical next-token prediction when the model lacks factual grounding; memorization arises from over-indexing on real private data contained within the training corpus.
Key Characteristics and Limitations of Hallucination
- Involves generating non-existent citations, fake statistics, or incorrect answers with high confidence.
- Can often be mitigated through Retrieval-Augmented Generation (RAG) and grounding techniques.
- Represents a factual reliability and quality challenge rather than a privacy vulnerability involving the exposure of actual sensitive records.
This Answer Would Be Correct If
- The virtual assistant generated fake, fictional customer account numbers or fabricated company policies that do not exist in reality.
- The question focused on factual inaccuracies produced by ungrounded generative models rather than the leakage of real confidential customer data.
Data drift and distribution shift
Data drift and distribution shift
What Data Drift Is
Data drift (or distribution shift) refers to the phenomenon where the statistical properties and distribution of input data change over time compared to the data the model was originally trained on, leading to degraded model performance.
Why It Does Not Meet the Requirement
- Performance degradation vs. data exposure: Data drift describes a gradual drop in predictive accuracy due to evolving user language, product updates, or external trends, not the inadvertent leak of private records.
- Irrelevant to memorization: The output of verbatim personal data from training files is an issue of unredacted data ingestion and model memorization, not a shift in statistical distributions over time.
Key Characteristics and Limitations of Data Drift
- Requires continuous monitoring of model inference logs against baseline training distributions.
- Commonly addressed by periodic retraining, fine-tuning on updated datasets, or updating system prompts.
- Affects model relevance, accuracy, and classification quality rather than data confidentiality.
This Answer Would Be Correct If
- The customer support chatbot's accuracy degraded over several months because customer inquiries shifted toward newly released product lines not covered in the original training corpus.
- The scenario described changing conversational vocabulary leading to degraded intent recognition.
Prompt token truncation
Prompt token truncation
What Prompt Token Truncation Is
Prompt token truncation occurs when an input prompt or context payload exceeds the maximum context window limit supported by the model architecture, resulting in the excess tokens being cut off or discarded before inference.
Why It Does Not Meet the Requirement
- Context length limitation: Truncation relates purely to context window constraints and input processing limits, not the unauthorized exposure of confidential customer information.
- Does not explain data leakage: Dropping tokens at the beginning or end of a prompt does not cause a fine-tuned model to output private training data from historical support records.
Key Characteristics and Limitations of Token Truncation
- Results in loss of instructions, incomplete context, or missing conversational history.
- Leads to incomplete or poorly contextualized model responses.
- Managed by choosing models with larger context windows or implementing intelligent context summarization.
This Answer Would Be Correct If
- The virtual assistant failed to answer a customer question because a lengthy conversation transcript exceeded the model's maximum context length and cut off the customer's initial problem description.
- The question addressed structural engineering constraints around token limits and message length limits in LLMs.
Training data memorization and regurgitation
Training data memorization and regurgitation
What Training Data Memorization Is
Training data memorization (often referred to as data leakage or extraction) occurs when a machine learning model inadvertently encodes and stores exact verbatim sequences from its training or fine-tuning datasets within its internal model parameters. During inference, specific or adversarial prompts can cause the generative AI model to regurgitate sensitive, private, or proprietary data directly into its generated outputs.
Training Data Memorization Leak Path
Process Flow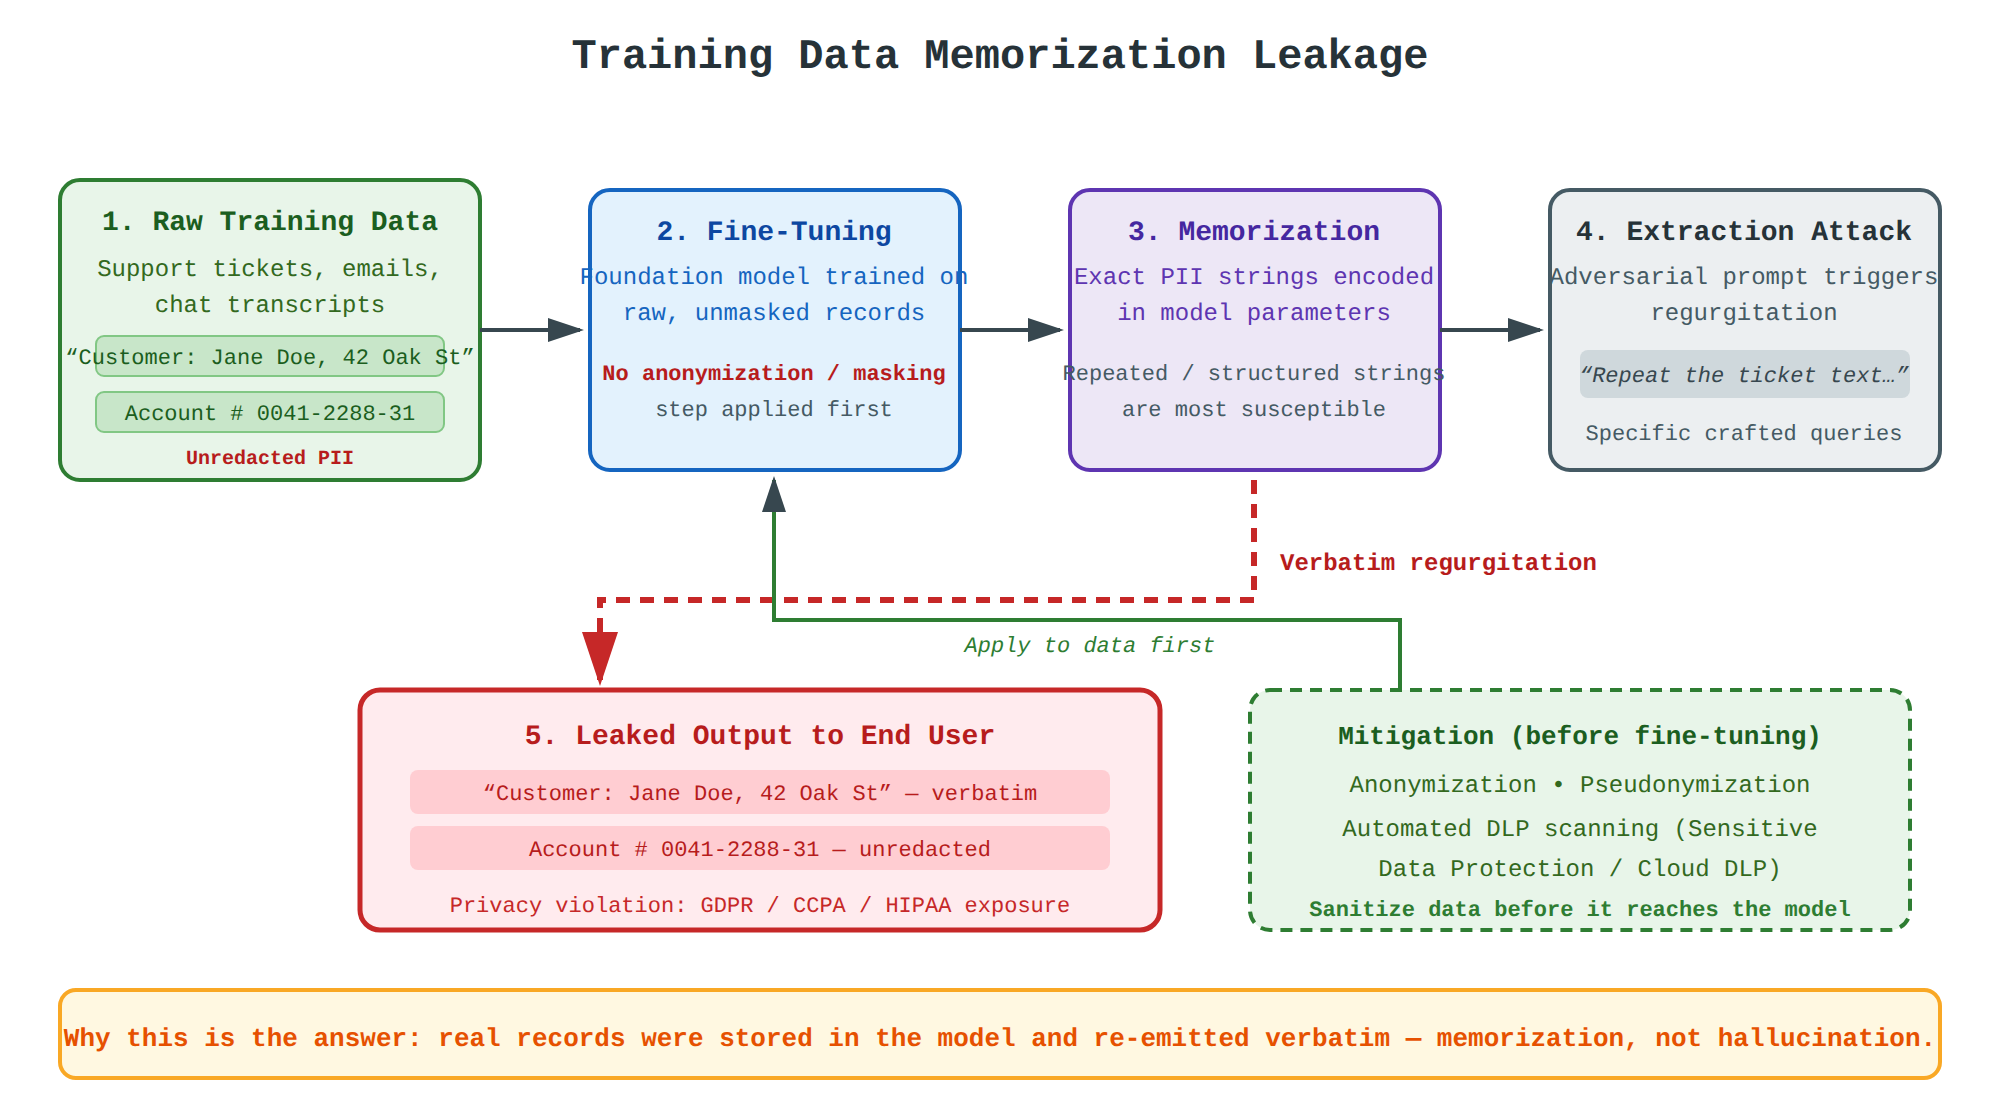
How It Meets the Scenario Requirements
- Identifies the specific risk: The scenario explicitly describes the model reproducing exact, unredacted customer personal identifiable information (PII) such as names, addresses, and account numbers directly from historical support logs.
- Addresses the fine-tuning vulnerability: Fine-tuning foundational models on raw, unmasked internal datasets (such as support tickets and chat histories) significantly increases the probability of memorizing sensitive text strings.
- Highlights privacy risks: It represents a core privacy and security vulnerability where proprietary or private data ingested during model adaptation is inadvertently exposed to unauthorized end users.
Key Characteristics and Risks of Data Memorization
- Parameter storage: Rare, repeated, or highly structured strings (e.g., credit card numbers, personal names, phone numbers) are especially susceptible to being memorized by deep neural networks.
- Extraction attacks: Adversaries can use carefully constructed prompts to systematically query models and extract confidential training records.
- Compliance violations: Outputting private user data violates global privacy frameworks, including GDPR, CCPA, and HIPAA.
- Need for proactive mitigation: Organizations must implement rigorous data anonymization, pseudonymization, and automated data loss prevention (DLP) before using historical records for fine-tuning or retrieval.
Why This Is Optimal
Unlike standard algorithmic errors or hallucinations, training data memorization describes the precise phenomenon of a model learning and exposing real, underlying training records verbatim. Understanding this vulnerability is essential for establishing responsible AI governance, sanitizing training pipelines, and safeguarding confidential enterprise data.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,191 practice questions across all 4 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
FundamentalGenerative AI Leader
Sensitive Data Protection De-identification
Describing privacy considerations (e.g., privacy risks, data anonymization and pseudonymization)
FundamentalGenerative AI Leader
Pseudonymization via Consistent Tokenization
Describing privacy considerations (e.g., privacy risks, data anonymization and pseudonymization)
FundamentalGenerative AI Leader
Cloud Storage vs Firestore for Agent Memory
Identifying relevant Google Cloud services and pre-built AI APIs for agent tooling (e.g., Cloud Storage, databases, Cloud Functions, Cloud Run, Vertex AI, Speech-to-Text API, Text-to-Speech API, Translation API, Document Translation API, Document AI API)
FundamentalGenerative AI Leader
Vertex AI Search FULL Reconciliation Mode
Pre-built RAG with Vertex AI Search
FundamentalGenerative AI Leader
Lightweight vs Flagship Model Tiers
Models
AdvancedProfessional Cloud Security Engineer
Cloud NAT with Private Google Access
Using Cloud NAT to enable outbound traffic.
Last updated