Fundamental
Prepare and test your skills
Fundamental
Prepare and test your skills
FULL Reconciliation Mode for Vertex AI Search
Free sample question, answered and explained below. The Generative AI Leader practice bank has 2,191 more like it. Try 10 free: instant score, no account.
An enterprise is setting up pre-built Retrieval-Augmented Generation (RAG) using Vertex AI Search to ground a generative AI assistant in company knowledge. The organization needs to ingest:
- Unstructured data: PDF operational guides and policy documents stored in Cloud Storage buckets
- Structured data: Product catalogs and inventory tables stored in BigQuery
When refreshing the search index, administrators must ensure that newly added documents are indexed, existing documents are updated, and obsolete records that were deleted from the source systems are automatically removed from the knowledge base.
Which ingestion approach should the team configure in Vertex AI Search to meet these requirements?
Explanations
Import the structured and unstructured datasets into the data store using the FULL reconciliation mode
Import the structured and unstructured datasets into the data store using the FULL reconciliation mode
What FULL Reconciliation Mode Is
In Vertex AI Search, data ingestion enables organizations to build searchable knowledge repositories from diverse enterprise sources, including unstructured content in Cloud Storage and structured tables in BigQuery. When importing documents, the reconciliation mode controls how newly ingested data synchronizes with the existing index in the target data store.
How It Meets the Requirements
- Diverse Data Ingestion: Vertex AI Search natively supports importing unstructured documents from Cloud Storage (such as PDFs, HTML, and text files) as well as structured data directly from BigQuery tables or datasets.
- Automatic Deletion of Stale Records: Setting the
reconciliationModetoFULLinitiates a complete rebase of the data store. Any documents or records present in the source are added or updated, while items that have been deleted from the source are automatically purged from the index. - Reliable Grounding Base: By purging obsolete documents, generative models grounded via Retrieval-Augmented Generation (RAG) will not retrieve out-of-date or deleted company policies, ensuring authoritative and trustworthy AI responses.
FULL Reconciliation Mode Sync Flow
Process Flow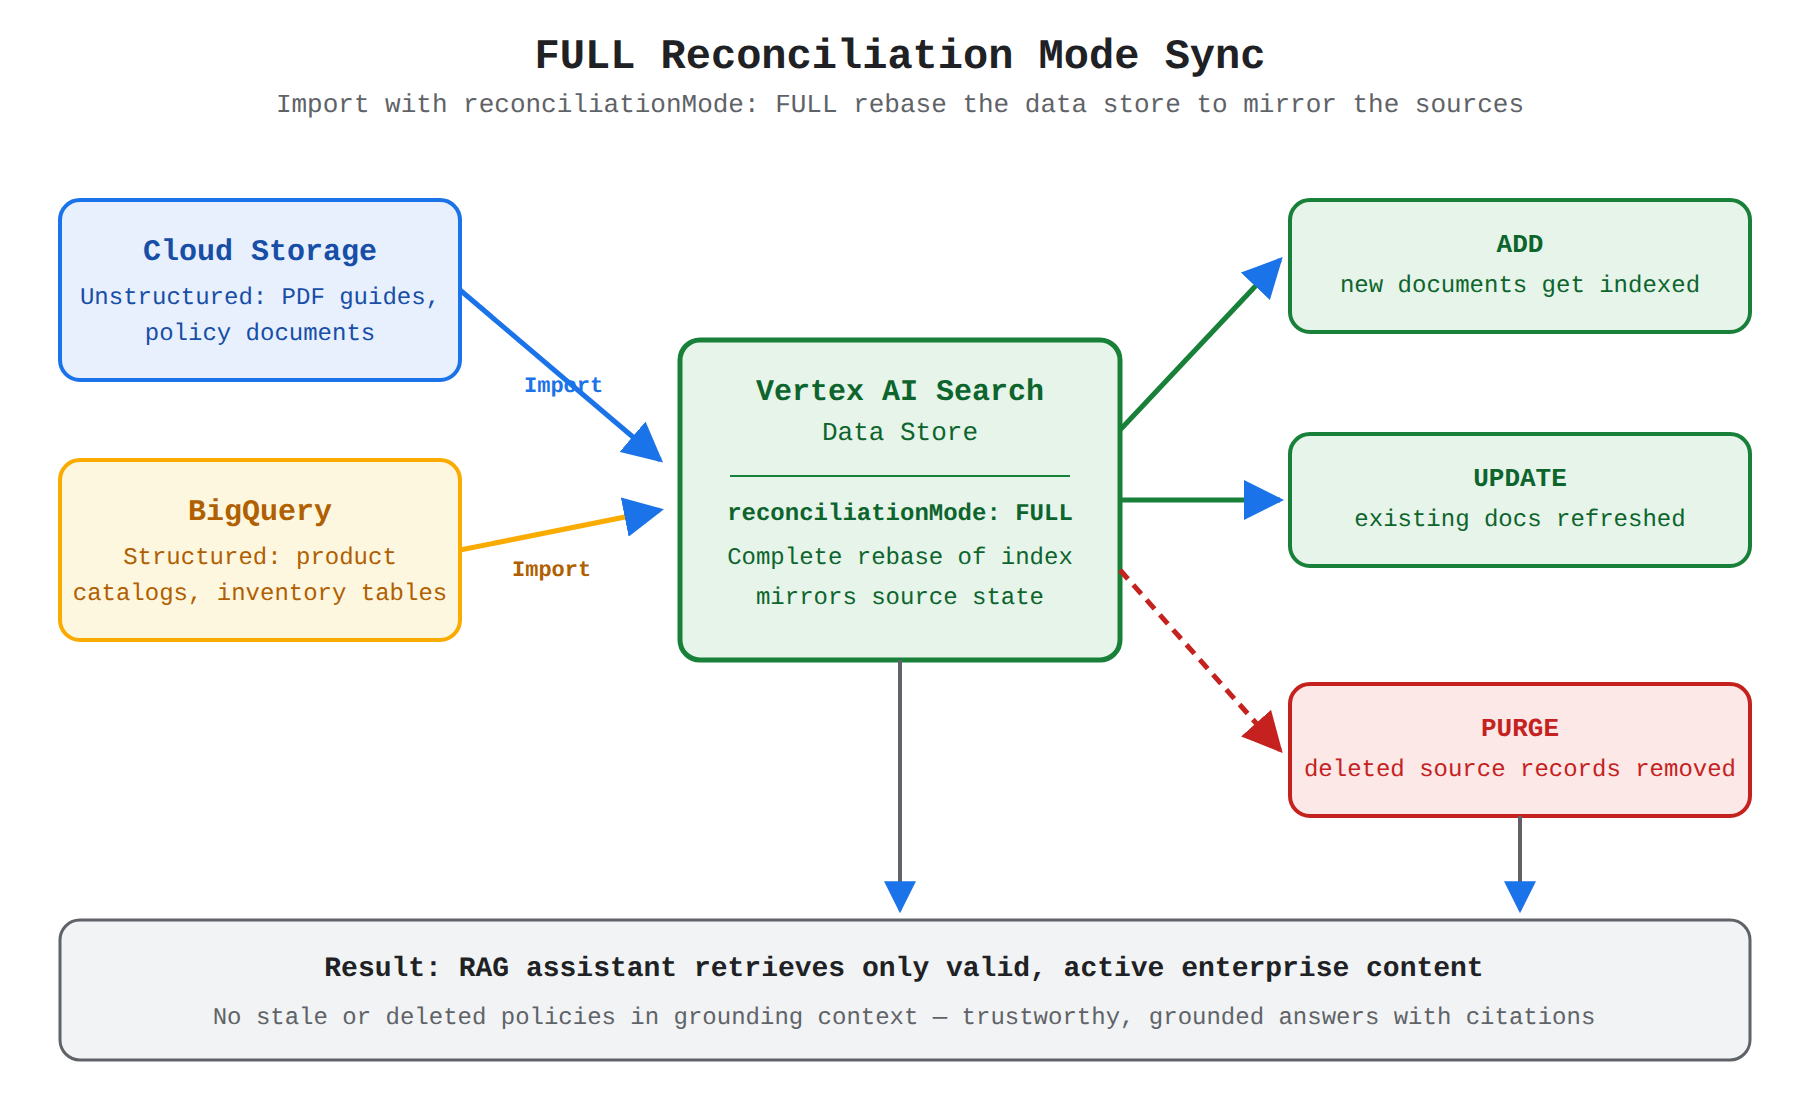
Key Advantages and Capabilities
- Complete Index Synchronization: Performs a full synchronization that mirrors the exact current state of primary storage repositories.
- Native Multi-Source Support: Easily connects to Cloud Storage and BigQuery without requiring custom data transformation pipelines.
- Automated Data Maintenance: Eliminates the administrative overhead of manually tracking and deleting obsolete documents individually.
- Grounding Accuracy: Prevents generative models from hallucinating or citing deprecated product details and policy manuals.
Why This Is Optimal
Using FULL reconciliation ensures bidirectional consistency between the primary storage systems and the grounding knowledge base. It guarantees that the generative AI application retrieves only valid, active enterprise data.
Store all unstructured PDFs inside structured BigQuery string columns before indexing
Store all unstructured PDFs inside structured BigQuery string columns before indexing
What Storing PDFs in BigQuery Involves
This approach attempts to force unstructured binary documents like PDF files into tabular BigQuery text columns (e.g., base64 strings or raw text dumps) rather than leveraging native unstructured storage connectors.
Why It Doesn't Meet the Requirement
- Unnecessary Complexity: Vertex AI Search natively ingests unstructured files directly from Cloud Storage buckets (
gs://), making manual format conversion unnecessary. - Loss of Document Structure: Extracting raw text from complex PDFs into tabular columns strips away document layouts, embedded images, metadata, and structural hierarchy that Vertex AI Search uses during indexing.
- Does Not Solve Reconciliation: Converting storage types does not specify how the search engine reconciles deleted source files during periodic index refreshes.
Key Characteristics and Limitations
- Schema Constraints: BigQuery is optimized for structured and semi-structured tabular analytics, not large binary document repository storage.
- Inefficient Ingestion Pipeline: Requires custom ETL code to parse, convert, and upload PDFs into database tables.
- Maintenance Burden: Adds operational overhead without providing the automated synchronization capabilities of built-in data connectors.
This Answer Would Be Correct If
- The organization was performing SQL-based data warehouse analysis on extracted metadata rather than using Vertex AI Search pre-built RAG capabilities.
Import the datasets using the INCREMENTAL reconciliation mode during recurring refreshes
Import the datasets using the INCREMENTAL reconciliation mode during recurring refreshes
What INCREMENTAL Reconciliation Mode Is
The INCREMENTAL mode is the default reconciliation setting in Vertex AI Search data store imports. It executes an upsert operation, adding newly detected documents and updating existing documents that share the same ID.
Why It Doesn't Meet the Requirement
- No Automatic Deletion: While
INCREMENTALsuccessfully adds new records and overwrites modified ones, it does not delete documents from the search index that have been removed from the source BigQuery tables or Cloud Storage buckets. - Grounding on Stale Data: Over time, deprecated policies and deleted product listings remain in the search index, leading to obsolete information being retrieved during RAG queries.
Key Characteristics and Limitations
- Upsert Only: Only processes additions and in-place replacements matching existing document IDs.
- Orphaned Records: Leaves deleted source files lingering in the knowledge base indefinitely unless explicitly removed through separate delete operations.
- Lower Resource Overhead: Executes faster than full rebasing because it does not evaluate the entire dataset for deletions.
This Answer Would Be Correct If
- The scenario only required adding new documents and updating modified files without needing automatic deletion of removed items.
- Fast, lightweight incremental batch ingestion was prioritized over index purging.
Additional Context
INCREMENTAL is ideal for write-heavy pipelines where records are strictly added or revised, but it requires manual cleanup workflows if records are frequently decommissioned.
Configure an ad-hoc semantic embedding pipeline in BigQuery ML without creating a search data store
Configure an ad-hoc semantic embedding pipeline in BigQuery ML without creating a search data store
What Custom BigQuery ML Embedding Pipelines Are
BigQuery ML allows users to generate vector embeddings using machine learning models directly inside a data warehouse for SQL-driven similarity matching and vector search.
Why It Doesn't Meet the Requirement
- Not Pre-Built RAG: Building a custom vector embedding pipeline in BigQuery ML bypasses Vertex AI Search, requiring teams to manually implement chunking, vector indexing, document parsing, and retrieval orchestration.
- Lacks Native Unstructured Support: It does not natively index unstructured files in Cloud Storage with pre-configured search features, summaries, and citation generation.
- Fails Ingestion Requirements: It requires custom logic to handle document lifecycle management, deletions, and hybrid keyword-semantic retrieval.
Key Characteristics and Limitations
- Developer Overhead: Demands manual implementation of embedding models, distance functions, and prompt grounding interfaces.
- No Turnkey Search Interface: Does not provide out-of-the-box data store management, reconciliation modes, or managed enterprise search connectors.
- Complex Synchronization: Developers must author and orchestrate custom SQL scripts to purge deleted records.
This Answer Would Be Correct If
- The organization required a fully custom, code-first vector database implementation inside BigQuery rather than leveraging pre-built RAG with Vertex AI Search.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,191 practice questions across all 4 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
FundamentalGenerative AI Leader
Data Quality Dimensions
Explaining the characteristics and importance of data quality and data accessibility in AI (e.g., completeness, consistency, relevance, availability, cost, format)
FundamentalGenerative AI Leader
Gemini Enterprise Permissions-Aware Search
Recognizing the functionality, use cases, and business benefits of Google Cloud's external search offerings (e.g., Vertex AI Search, Google Search)
FundamentalGenerative AI Leader
Grounded Conversational Search and Multi-Document Summarization
Identifying business use cases where gen AI can create, summarize, discover, and automate (e.g., text generation, image generation, code generation, video generation, data analysis, and personalized user experience)
FundamentalGenerative AI Leader
Vertex AI Managed ML Infrastructure
Infrastructure
FundamentalGenerative AI Leader
Google Cloud AI Hypercomputer Architecture
Identifying the essential components of Google Cloud's AI-optimized infrastructure and its benefits (e.g., hypercomputer, Google's custom-designed TPUs, GPUs, data centers, cloud computing)
AdvancedProfessional Cloud DevOps Engineer
Private Service Connect NEG Backend
Shared networking (e.g., Shared VPC, VPC Network Peering, Private Service Connect)
Last updated