Fundamental
Prepare and test your skills
Fundamental
Prepare and test your skills
Multimodal Inputs With Streaming Troubleshooting Guidance
Free sample question, answered and explained below. The Generative AI Leader practice bank has 2,191 more like it. Try 10 free: instant score, no account.
An enterprise customer support team is building an interactive assistant to process incoming equipment repair tickets. The system must meet the following operational and technical requirements:
- Ingest and analyze user-submitted repair forms that combine written diagnostic text descriptions with attached equipment photos
- Generate natural language troubleshooting guidance
- Minimize user-perceived latency during live customer interactions
Which foundation model capability and API configuration should the team select?
Explanations
A text-only foundation model paired with asynchronous batch prediction processing
A text-only foundation model paired with asynchronous batch prediction processing
What Text-Only Models with Batch Predictions Are
Text-only foundation models are specialized natural language processors designed solely to accept and generate textual tokens. They lack the architectural layers required to parse, encode, or interpret visual media such as photographs or diagrams.
Batch prediction is an execution mode designed for processing large volumes of non-interactive data asynchronously in bulk jobs, where turnaround time is measured in minutes or hours rather than milliseconds.
Why It Doesn't Meet the Requirement
- Incompatible Modality: A text-only model cannot process the equipment photographs submitted with the repair tickets, directly failing the multi-input requirement.
- High Latency for Live Users: Asynchronous batch prediction is built for background jobs and cannot power real-time, interactive customer support conversations.
- No Streaming Support: Batch jobs return entire datasets after processing completes, which maximizes rather than minimizes perceived latency in user-facing applications.
Key Characteristics and Limitations
- Modality Limitation: Restricted entirely to text tokens and string inputs
- Execution Paradigm: Optimized for offline throughput and scheduled workloads
- Latency Profile: High queue and turnaround times unsuitable for interactive sessions
This Answer Would Be Correct If
This architecture would be suitable for an offline audit scenario where thousands of historical, purely textual customer tickets are analyzed overnight for reporting trends without any live human interaction.
A single-context recommendation model configured with deterministic greedy token decoding (Top-K = 1)
A single-context recommendation model configured with deterministic greedy token decoding (Top-K = 1)
What Single-Context Recommendation Models with Greedy Decoding Are
Single-context recommendation models are purpose-built predictive algorithms (such as retail recommendation engines) designed to suggest items based on a single referenced product interaction on a catalog page.
Greedy token decoding (Top-K = 1) is a sampling setting where the foundation model strictly picks the single highest-probability token at each step during generation, eliminating randomness.
Why It Doesn't Meet the Requirement
- Wrong Model Family: Recommendation algorithms rank structured catalog items; they cannot parse free-form diagnostic text or inspect images to produce narrative troubleshooting steps.
- Context Limitation: A single-context architecture is restricted to evaluating one product identifier at a time rather than multimodal documents.
- Inadequate Latency Solution: While setting
Top-K = 1makes output deterministic, it does not solve user-perceived latency in conversational interfaces the way token streaming does.
Key Characteristics and Limitations
- Functionality: Generates structured ranking predictions rather than generative conversational text
- Sampling Behavior: Top-K of 1 selects solely the top candidate token via greedy decoding
- Modality Support: Operates on tabular and catalog entity data rather than rich multimodal media
This Answer Would Be Correct If
This configuration would be selected for an e-commerce product detail page where the goal is suggesting a single complementary product based on the item currently viewed by a shopper.
A multimodal foundation model supporting text and image inputs, paired with streaming response generation
A multimodal foundation model supporting text and image inputs, paired with streaming response generation
What Multimodal Foundation Models and Streaming Are
Multimodal foundation models are generative AI models architected to ingest, process, and correlate diverse data types—such as text, code, and images—within a unified context. Rather than relying on separate specialized pipelines for vision and language, a native multimodal model accepts mixed-modality prompts and generates coherent, contextual natural language outputs.
Streaming response generation (such as utilizing the streamGenerateContent API method) transmits generated output tokens back to the client progressively in real time as they are produced, rather than waiting for the entire generation process to complete.
Streaming Token Delivery Flow (streamGenerateContent)
Sequence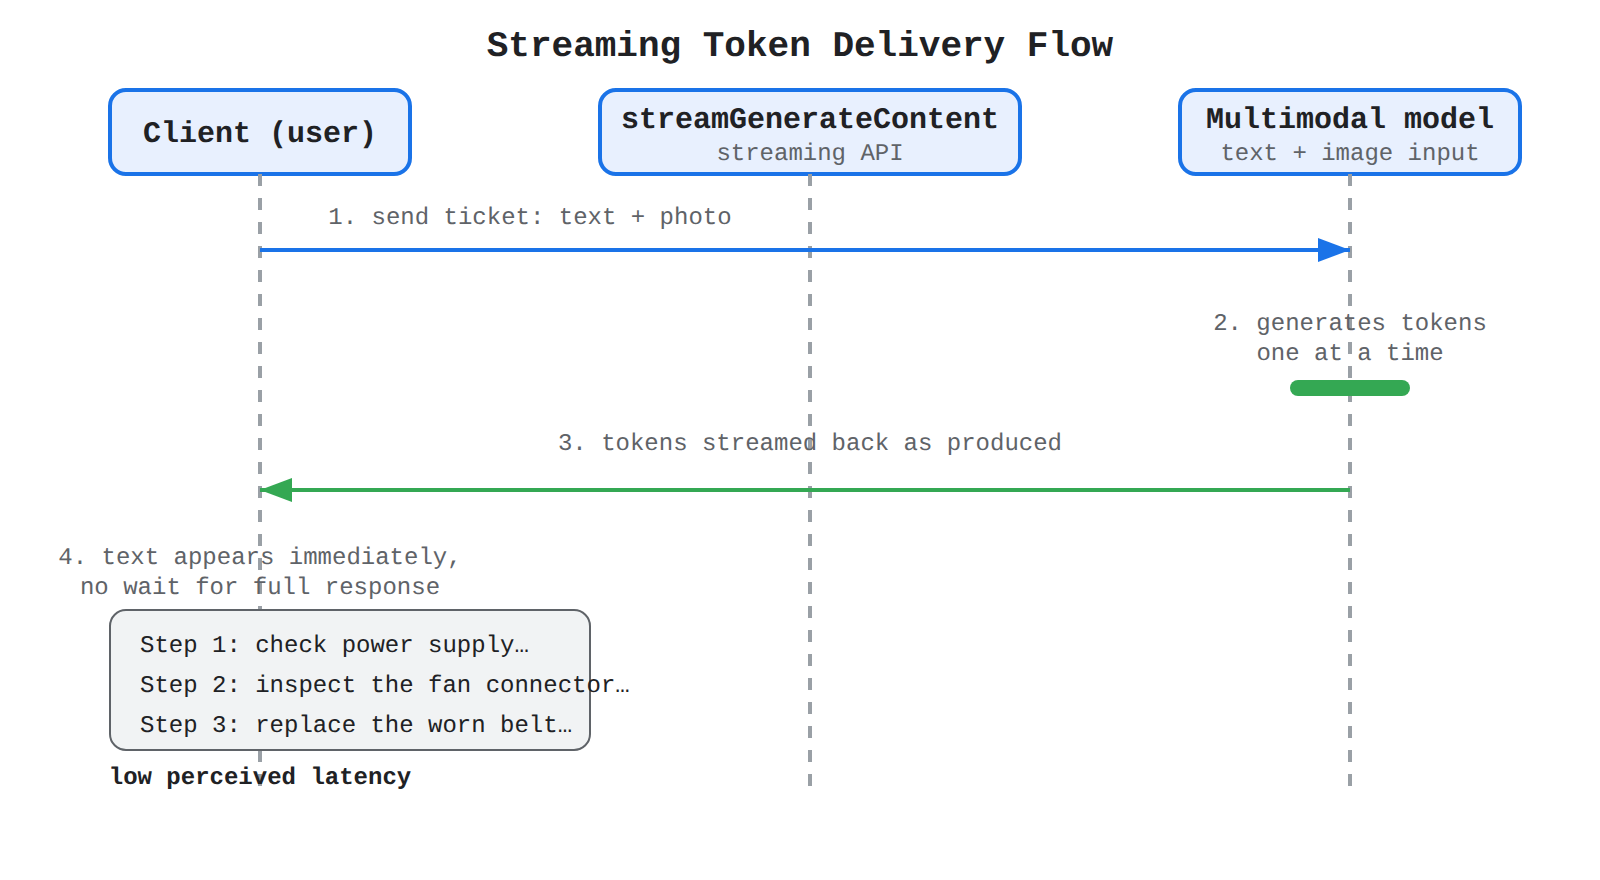
How It Meets the Business Requirements
- Cross-Modality Ingestion: Multimodal models allow the repair ticket's written problem description and the attached equipment photos to be evaluated together in a single request.
- Natural Language Troubleshooting: The model processes the visual and textual diagnostic context to generate step-by-step written instructions.
- Minimizing Perceived Latency: Implementing streaming delivery (
streamGenerateContent) ensures users see text immediately as it generates, eliminating long perceived wait times during live interactions.
Key Advantages and Capabilities
- Unified Context Processing: Eliminates complex preprocessing chains by allowing text and imagery in the same prompt
- Enhanced User Experience: Progressive token streaming delivers rapid interactive feedback to human end-users
- Context Window Utilization: Accommodates substantial input token counts for detailed logs and high-resolution images
- Architectural Simplicity: Reduces infrastructure overhead by leveraging a single managed endpoint for vision and language tasks
Why This Is Optimal
Combining native multimodal input processing with streaming response APIs satisfies both the functional data requirements (images plus text) and the human-centric performance requirements (low perceived latency), making it the optimal design choice for interactive enterprise support.
A code-generation foundation model paired with periodic quarterly automatic model tuning
A code-generation foundation model paired with periodic quarterly automatic model tuning
What Code-Generation Models with Automatic Tuning Are
Code-generation foundation models are specialized systems fine-tuned primarily for software development tasks such as writing syntax, translating programming languages, and debugging source code.
Periodic automatic tuning is a lifecycle management feature that retrains or updates model weights at scheduled intervals (such as every three months) using updated historical datasets to maintain relevance over time.
Why It Doesn't Meet the Requirement
- Mismatched Task Scope: A code-specific foundation model is tailored for software scripts and syntax rather than general equipment troubleshooting and visual inspection.
- Lacks Real-Time Optimization: Periodic tuning affects underlying model weights on a quarterly basis, but does not address live-session latency or user responsiveness.
- Modality Restrictions: Dedicated code models typically do not support visual context analysis for hardware repair photos.
Key Characteristics and Limitations
- Domain Specialization: Focused on programming languages, APIs, and software engineering structures
- Maintenance Overhead: Scheduled retraining cycles designed for long-term drift rather than inference-time delivery
- Inference Experience: Does not inherently provide progressive streaming or image comprehension
This Answer Would Be Correct If
This approach would be appropriate for an automated internal developer tool that generates and maintains software integration scripts and needs regular retraining against updated API repositories.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,191 practice questions across all 4 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
FundamentalGenerative AI Leader
Fine-Tuning Data and Model Artifact Security
Identifying how to choose the appropriate foundation model for a business use case (e.g., modality, context window, security, availability and reliability, cost, performance, fine-tuning, and customization)
FundamentalGenerative AI Leader
Provisioned Throughput vs Pay-As-You-Go Pricing
Identifying how to choose the appropriate foundation model for a business use case (e.g., modality, context window, security, availability and reliability, cost, performance, fine-tuning, and customization)
FundamentalGenerative AI Leader
Open Standards Prevent Vendor Lock-In
Describing the benefits of Google Cloud's open approach
FundamentalGenerative AI Leader
Gemini Advanced Custom Gems
Recognizing the functionality, use cases, and business value of the Gemini app and Gemini Advanced (e.g., Gems)
FundamentalGenerative AI Leader
Transparency and Interpretability with Human-in-the-Loop Oversight
Explaining the importance of responsible AI and transparency
AdvancedProfessional Data Engineer
VPC Service Controls Analytics Hub Ingress Egress
Publishing datasets
Last updated