Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Prebuilt AI APIs and Model Garden Deployment
Differentiating between the Google AI APIs (e.g., Search, Conversation, Vision, Image, Video, and Audio)
Differentiating between the Google AI APIs means matching the input type and job to the right prebuilt API or model. Analytical APIs describe existing images, video, audio, or text, while generative models create new content or reason across modalities. BigQuery (opens in a new tab) can call several of these APIs directly with remote models for bulk transcription and text understanding.
Cloud Vision API for Still Images
Cloud Vision API is a pretrained API that analyzes a single still image in one request and returns structured annotations. An application sends image bytes or a Cloud Storage reference with one or more feature types, and annotations flow back from the API to the application. Because each request is independent, the API has no sense of motion or change over time.
The API behavior is controlled by explicit feature types that select what is returned:
- OBJECT_LOCALIZATION detects multiple objects with bounding boxes.
- TEXT_DETECTION performs optical character recognition (OCR) for sparse text in a larger image.
- DOCUMENT_TEXT_DETECTION performs OCR for dense text, PDF or TIFF documents, and handwriting.
- LABEL_DETECTION adds content labels for what appears in the image.
- FACE_DETECTION detects faces in the image.
- LANDMARK_DETECTION and LOGO_DETECTION identify places and company logos.
- SAFE_SEARCH_DETECTION, WEB_DETECTION, IMAGE_PROPERTIES, and CROP_HINTS flag unsafe content, find web matches, compute dominant colors, and suggest crops.
Exam tip: Use TEXT_DETECTION for sparse text in a photo, but use DOCUMENT_TEXT_DETECTION for dense documents, PDF/TIFF files, or handwriting.
Video Intelligence API for Temporal Analysis
Video Intelligence API is a pretrained API that analyzes video as a sequence of frames over time. Data flows from a video file in Cloud Storage or a local upload to an annotation operation, and time-stamped segments flow back to the application. Because the API tracks information across frames, it can describe motion, duration, and change that a single image call cannot see.
Temporal analysis focuses on tracking and segmentation. The API annotates labels across a clip, detects persons and faces as they move, detects text in frames, flags explicit content, detects shot changes where the camera cuts, and transcribes speech from the audio track. The same operation supports stored files and streaming input, and both return annotations with timestamps and confidence scores.
Generative Image Models Versus Analytical Vision APIs
Generative image models create new visual assets, while Cloud Vision API and Video Intelligence API only describe existing pixels. Imagen is a text-to-image model on Vertex AI that produces or edits images from a text prompt, including automatic mask detection and inpainting where the model creates the masked area and adds requested content inside it. Gemini models are multimodal foundation models trained on text, images, code, and other media that can reason across text, image, video, audio, and code in a single prompt.
The choice depends on input and primary action:
| API or Model | Input | Primary action |
|---|---|---|
| Cloud Vision API | Single image or document page | Detects objects, text, faces, labels, and properties in that frame |
| Video Intelligence API | Video file or stream with audio and frames | Tracks labels, persons, faces, text, shots, and speech over time |
| Imagen and Gemini | Text prompt, optionally plus image, video, or audio | Generates new images, edits regions, or answers across modalities |
Custom training follows the same split. AutoML Vision object detection can be trained to find domain-specific sections of images, and AutoML Vision classification can classify image content. AutoML Vision classification is not generally recommended for document classification because text-based methods after OCR tend to be more accurate.
Speech, Text, and Conversational Orchestration
Conversational interfaces turn audio into text, understand the text, and turn a response back into audio. Speech-to-Text transcribes audio into written text, so a voicemail recording flows to the API and text flows back. Text-to-Speech does the opposite direction, where text flows to the API and synthesized audio flows back for playback. In BigQuery, transcription uses a remote model over the Speech-to-Text endpoint with CLOUD_AI_SPEECH_TO_TEXT_V2 and the ML.TRANSCRIBE function, with inference in Agent Platform and results stored in BigQuery.
Cloud Natural Language API is the pretrained API for understanding written text. Text flows from a table or application to the API, and insights such as classification and sentiment flow back, such as whether product feedback is positive. In BigQuery, a remote model is created with CLOUD_AI_NATURAL_LANGUAGE_V1 and the ML.UNDERSTAND_TEXT function runs against standard tables. Dialogflow orchestrates multi-turn conversations, where Dialogflow ES fits standard linear dialogs and Dialogflow CX fits complex branching with state handling and scaling.
An automated voice agent connects these steps in a fixed order:
Automated Voice Agent Flow
Sequence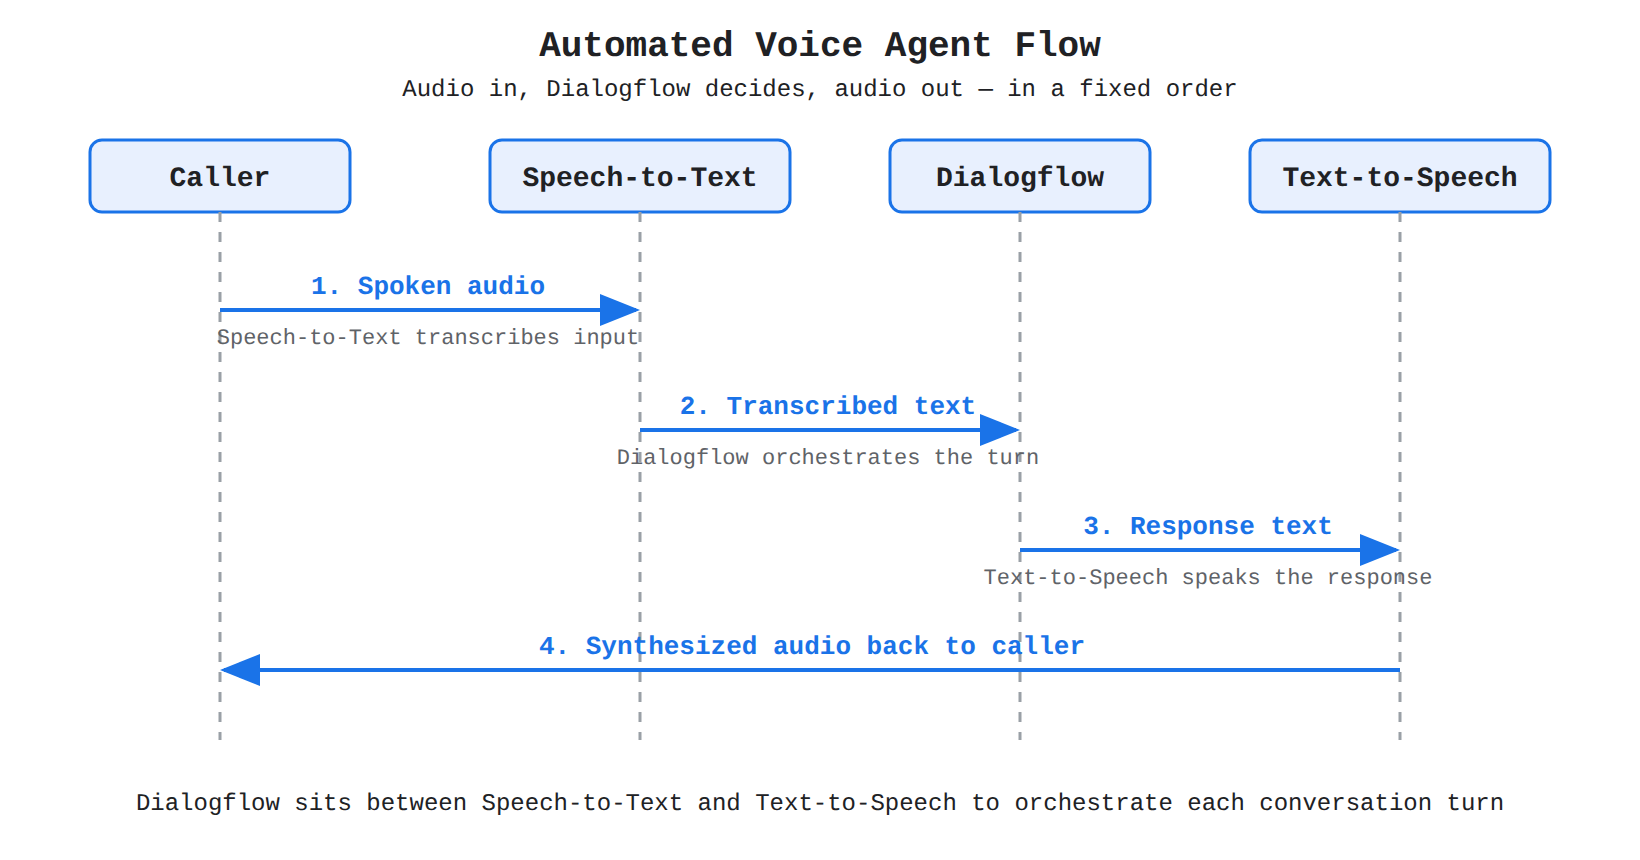
A sequence diagram showing a caller's spoken audio flowing to Speech-to-Text, transcribed text to Dialogflow for orchestration, response text to Text-to-Speech, and synthesized audio back to the caller, with each message animated in order.
- Speech-to-Text transcribes input: spoken audio flows from the caller to Speech-to-Text.
- Dialogflow orchestrates the turn: text flows to the virtual agent, which decides the next action and response.
- Text-to-Speech speaks the response: response text flows to Text-to-Speech and audio flows back to the caller.
Supporting services surround this loop. Google Cloud Contact Center as a Service queues and routes interactions, Agent Assist helps human agents after handoff, Customer Experience Insights finds patterns after calls, and Cloud Translation API translates text across languages.
Vertex AI Search for Discovery and Grounding
Vertex AI Search is a prebuilt search solution for building a discovery engine or Retrieval Augmented Generation (RAG) application. Information retrieval (IR) is the core function that retrieves documents from a corpus based on a user query. Data flows from the user query to Vertex AI Search, and matching documents flow back from the corpus, so teams do not have to build ranking from scratch.
Grounding connects Gemini output to enterprise data in a Vertex AI Search data store. The data store holds enterprise content, Vertex AI Search supplies retrieved documents, and Gemini generates an answer using that context. The RAG Engine can use Vertex AI Search as its retrieval backend, so retrieval flows from the data store to the RAG Engine and then to Gemini. This pattern adds semantic search for meaning-based matches and provides current, source-linked context instead of relying only on pretrained knowledge.
Integrating Gemini Enterprise features means using permissions-aware search, grounded answers, and autonomous agents to automate multi-step work. Gemini Enterprise (opens in a new tab) is an intranet search, AI assistant, and agentic platform that connects Google and third-party data sources. Data flows from connected sources into dedicated data stores, then through a Gemini Enterprise app to the user, and the app only serves content that user is allowed to see.
Security, Identity, and Data Protection
Permissions-aware access in Gemini Enterprise respects each user's existing permissions at scale through single sign-on (SSO) and user-level access. Administrators assign licenses, connect data sources, manage agent service accounts, and configure security policies. Identity and Access Management (IAM) controls who can view data, invoke agents, and change configuration, with Model Armor policies governing agent behavior after deployment.
Authentication supports three peer frameworks:
- Workforce Identity Federation for workforce users with external identity providers, recommended when sending data with a third-party connector.
- Google Identity for Google-managed users.
- Workload Identity Federation for programmatic workloads calling the API.
Workforce pool administration is high risk because the IAM Workforce Identity Pool Admin and Editor roles can change attribute mappings and enable impersonation. Grant those roles only to trusted admins, use Privileged Access Manager for time-bound access, and send audit logs to a security monitoring system. Data is encrypted by default with Customer Managed Encryption Keys (CMEK), with support for External Key Manager or hardware security module keys, and the platform integrates with VPC Service Controls (VPC-SC) to control data movement. User-requested data is deleted within 60 days.
Observability and Admin Surfaces for Governance
Observability shows where data resides, who accessed it, and how agents behaved. Audit logs and usage logs track agent and system activity, while request traces and spans show the execution path of search and agent workflows. When agents are deployed with the Agent Development Kit (ADK), telemetry flows from Agent Platform, Agent Gateway, and Model Armor to Cloud Trace, Cloud Logging, Cloud Monitoring, and Topology using OpenTelemetry. Traces capture paths, logs capture events and errors, and metrics capture latency and token usage.
Governance is split across three admin surfaces:
| Admin surface | What it governs |
|---|---|
| Agent Platform | Central lifecycle, Agent Registry versioning, gateway configuration, IAM and Model Armor enforcement, and threat detection |
| Gemini Enterprise Admin | Licenses and users, instances and connectors, adding agents and tools, and user permissions for agents |
| Google Workspace Admin Console | Enabling the service, domain policies on data access, and audit logging for Workspace interactions |
Knowledge Synthesis with NotebookLM
Gemini Notebook Enterprise (opens in a new tab) is a system for centralized knowledge from curated sources. A notebook is an organized collection of hand-selected documents, websites, and sources on one topic or project. Data flows from uploaded sources into the notebook, and all answers and drafts flow back out from that same bounded set. Notebook data stays under access control and is not used for external model training.
Chat answers are strictly confined to the notebook's information, so responses stay grounded in selected documents. One-click generation turns the same content into FAQs, timelines, study guides, summaries, and interactive audio podcasts. Choose Gemini Notebook Enterprise when answers must stay confined to known sources and every output must trace to curated inputs. Choose Gemini Enterprise when the starting point is unknown across enterprise systems or the task needs broad search, multimodal generation, and agent actions. The joint workflow is discovery first in Gemini Enterprise, then adding discovered sources into a notebook for trusted synthesis.
Architecting and Grounding Conversational Data Agents
A conversational data agent combines a persona, data sources, and business knowledge to answer natural-language questions from databases. Requests flow from the user in natural language to the agent, then from the agent to the database as generated SQL, and finally back to the user as a summary or visualization. This lets users get insights from operational databases such as Spanner and AlloyDB for PostgreSQL without learning query languages.
Agents move through two lifecycle states in order. An agent starts as draft for personal testing by its creator, then moves to published when made available to others in the project or through an API. Gemini Enterprise is the central hub where published agents are found and managed. Grounding with authored context improves accuracy through schema descriptions, system instructions, and structured context that tell the model what tables and fields mean. Before creating an agent, billing must be enabled and the project must enable the Data Analytics API with Gemini, the Gemini for Google Cloud APIs, and the database API.
Grounding with Google Search (GWGS) grounds companion agent suggestions in live web results from the user prompt, customer context, and Google Search data. When GWGS is enabled, requests flow outside customer controls, and GWGS does not support CMEK, Data Residency, VPC-SC, or Access Transparency. Use authored context when answers must stay inside enterprise controls, and use GWGS only when current web facts outweigh those requirements. Tools let agents call external systems to retrieve, update, format, or analyze data, and a tool created in one project can only be used by agents and AI coach in that same project.
Exam tip: Sharing a Looker data agent lets users chat with it, but users still need separate permissions for the Explore and model behind it.
Integrating AI models from Model Garden means selecting a base model, adapting it to domain data, and deploying it behind a managed endpoint. Vertex AI Model Garden (opens in a new tab) is the central library for discovering, testing, customizing, and deploying Google and partner models. Selection matches task, cost, and trust, customization shapes behavior with data and prompts, and deployment connects application traffic to an endpoint under scanning and policy controls.
Model Categories, Discovery, and Task Matching
Model Garden groups models by how ready they are and how they can be adapted:
| Category | Description | Deployment approach |
|---|---|---|
| Foundation models | Pretrained multitask large models | Tune or customize for a task, then deploy to an endpoint |
| Fine-tunable models | Models that support custom training | Fine-tune with a notebook or pipeline, register the new version, then deploy |
| Task-specific solutions | Prebuilt models for a defined task | Deploy as ready-to-use models, many customizable on your own data |
Discovery happens on the Model Garden page, where each listing has a model card with details before testing or deployment. Filters narrow the catalog by tasks such as code, image, embedding, or text generation, by model collections managed by Google, partners, or you, by providers, and by features. Task matching selects the smallest fit: Codey for code generation, Imagen for image generation, text-embedding models for search or clustering vectors, and Gemini as the flagship model for text and multimodal prompts. When no managed model fits because of kernels, legacy systems, or licensing, self-host on Google Kubernetes Engine (GKE), Cloud Run, or Compute Engine.
Customization with Tuning, Data, and Prompts
Fine-tuning continues training of a pretrained foundation model on domain-specific data to improve accuracy for one use case. Most generative models use the Transformer architecture, where an encoder converts input into an intermediate representation and a decoder converts it into output using self-attention. Training from scratch takes significant resources, while fine-tuning a pretrained Transformer is more efficient. High-performance training depends on accelerated compute, so configure Cloud Tensor Processing Units (TPUs) or GPUs.
The customization path depends on fit and operations:
| Approach | What changes | Choose when |
|---|---|---|
| Fine-tune a Model Garden model | Base weights updated with domain data | A pretrained model matches the domain and needs specialized accuracy |
| AutoML on Agent Platform | Architecture, hyperparameters, and provisioning handled automatically | Data matches a supported format and inference latency above 100ms is acceptable for text, video, or tabular models |
| Agent Platform custom training | Your own training routine runs on serverless infrastructure | The problem does not match BigQuery ML or AutoML, or training must match on-premises workflows |
Domain data flows from sources such as BigQuery, Dataflow, or Managed Service for Apache Spark into preprocessing and validation, then into a managed dataset or feature store, and finally into training. Quality covers accuracy of facts and labels, relevance to the task, diversity of prompts, and alignment to safety standards. When data is scarce, BigQuery DataFrames can create synthetic data from existing patterns. Prompts are managed in Agent Studio, while Pipelines automates preparation, tuning, evaluation, and deployment in order, with Vertex ML Metadata linking data, prompts, and versions. After tuning, store the result in Model Registry, which tracks lineage and deploys a chosen version for online or batch inference.
Model distillation trains a smaller student model to mimic a larger teacher model so inference runs with lower cost and latency on limited-resource devices. Reliability after deployment depends on Vertex AI TensorBoard for loss, accuracy, and run comparison, Feature Store for consistent features between training and serving, and Model Monitoring for training-serving skew and drift alerts that trigger retraining.
Deployment Workflow and API Integration
Deployment moves a procured Model Garden asset from Cloud Marketplace to a serving Vertex AI Endpoint through the registry. The workflow depends on a model artifact in Cloud Storage and a serving container, and the endpoint depends on the registered model version. Deployment is long-running and can take more than five minutes.
The ordered steps are:
- Manage on Vertex AI: From the Marketplace product page, select Manage on Vertex AI.
- Upload to Model Registry: Upload with a display name, a Cloud Storage artifact URI such as
gs://bucket/directory, and a serving container image URI. - Create Vertex AI Endpoint: Create an endpoint with display name, project, and location.
- Deploy model to endpoint: Deploy with a deployed-model display name and machine type such as
n1-standard-2.
Only after deployment completes can applications send inference requests and receive predictions. Vertex AI Inference makes predictions on new data, while Vertex AI Agent Engine hosts agents so applications call the agent API. A database example is Cloud SQL for SQL Server, where SQL calls flow to an external endpoint in Vertex AI, Hugging Face, or OpenAI and the AI_GENERATE_EMBEDDINGS function returns vectors for search. Feature data can flow from BigQuery into an online store for low-latency lookup at inference time.
Exam tip: Models flagged as unsafe by scans are blocked from deployment, while models flagged as suspicious can still be deployed but require thorough review before use.
Continue with this study guide: Integrating AI models from Model Garden into the solution
Key Facts
- Cloud Vision API analyzes a single still image with explicit feature types, while Video Intelligence API tracks labels, persons, faces, text, shots, and speech over time in video.
- Speech-to-Text converts audio to text for input, Text-to-Speech converts text to audio for output, and Dialogflow orchestrates the multi-turn conversation between them.
- Vertex AI Search retrieves documents from a corpus and serves as the retrieval backend that grounds Gemini output in enterprise data.
- Gemini Notebook Enterprise confines answers strictly to hand-selected notebook sources, while Gemini Enterprise searches broad enterprise systems and orchestrates agents.
- Model Garden deployment moves from Manage on Vertex AI to Model Registry upload, Vertex AI Endpoint creation, and model deployment before applications can call the endpoint.
Frequently Asked Questions
What is the difference between Cloud Vision API and Video Intelligence API?
Cloud Vision API analyzes a single still image in one request and returns structured annotations with no sense of motion or change over time, while Video Intelligence API analyzes video as a sequence of frames over time with time-stamped annotations. Cloud Vision API is controlled by explicit feature types for objects, text, faces, labels and other properties, while Video Intelligence API tracks labels, persons, faces, text, shot changes and transcribed speech across frames.
When should I use TEXT_DETECTION instead of DOCUMENT_TEXT_DETECTION in Cloud Vision API?
Use TEXT_DETECTION for optical character recognition of sparse text in a larger image or photo, and use DOCUMENT_TEXT_DETECTION for dense text, PDF or TIFF documents, or handwriting. DOCUMENT_TEXT_DETECTION is designed for dense document content while TEXT_DETECTION is designed for sparse text in a photo.
How do Speech-to-Text, Dialogflow, and Text-to-Speech work together in an automated voice agent?
In an automated voice agent, Speech-to-Text first transcribes spoken audio from the caller into text, then Dialogflow orchestrates the turn by deciding the next action and response, and finally Text-to-Speech converts the response text into synthesized audio for playback to the caller. Supporting services surround this loop, including Google Cloud Contact Center as a Service for queuing and routing, Agent Assist for helping human agents after handoff, and Cloud Translation API for translating text across languages.
What is the difference between Gemini Enterprise and Gemini Notebook Enterprise for knowledge work?
Gemini Enterprise connects Google and third-party data sources for broad search across enterprise systems and orchestrates agents with permissions-aware access, while Gemini Notebook Enterprise confines chat answers strictly to hand-selected documents, websites and sources in a notebook. Choose Gemini Enterprise when the starting point is unknown across enterprise systems or the task needs broad search and agent actions, and choose Gemini Notebook Enterprise when answers must stay confined to known sources and trace to curated inputs.
Subdomains
Visual and Multimodal Analysis covers Google Cloud APIs that read existing images and video and models that create new visual content. Analytical APIs describe what is already in the pixels, while gen…
Security and governance of AI workflows in Gemini Enterprise is the framework that controls who can access enterprise data, what agents can do with it, and how activity is monitored. Gemini Enterp…
Model customization and domain adaptation is the practice of tailoring a pre-trained model from Vertex AI Model Garden to an organization's task, vocabulary, and data. A general foundation model that …
How learners score on this domain
Last updated