Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Real-Time Salesforce Case Routing with Application Integration
Free sample question, answered and explained below. The Professional Cloud Architect practice bank has 2,335 more like it. Try 10 free: instant score, no account.
An enterprise customer support organization wants to modernize its multi-platform case routing system. The product owner defines the following business requirement and user story:
- "When a customer creates a high-priority support case in Salesforce, the platform must immediately detect the event, retrieve the full case record, translate non-English customer comments into English, standardize the payload into our canonical JSON format, and route the record to an internal issue-tracking service."
You need to translate this business requirement into functional data flows and service integrations using Google Cloud services.
Which integration architecture should you implement?
Explanations
Create an Application Integration flow with a Salesforce Change Data Capture (CDC) trigger, a Connectors task to fetch the Case entity, a Translate - Text task for localization, and a Data Mapping task to transform variables for the destination endpoint.
Create an Application Integration flow with a Salesforce Change Data Capture (CDC) trigger, a Connectors task to fetch the Case entity, a Translate - Text task for localization, and a Data Mapping task to transform variables for the destination endpoint.
What Google Cloud Application Integration Is
Application Integration is an Integration Platform as a Service (iPaaS) solution in Google Cloud designed to visually orchestrate, automate, and connect enterprise SaaS applications, Google Cloud services, and custom internal APIs without requiring custom middleware code.
How it meets the Functional Requirements
To translate the business user story into specific functional components and data flows:
- Event Detection (Real-Time): The Salesforce trigger configured with Change Data Capture (CDC) on the
Caseobject instantly captures case creation events as they occur in Salesforce. - Entity Retrieval: The integration maps the generated CDC record ID to a Connectors task targeting the Salesforce connection with an Entities: Get operation to pull the complete case payload.
- Language Translation: A Translate - Text task receives the raw customer comment strings in its request parameters and outputs translated text, directly fulfilling the business localization requirement.
- Data Standardization: A Data Mapping task applies transform functions and expressions to map input attributes and translated text into the required canonical target schema before passing the payload along conditional edges to the downstream ticketing service.
Salesforce Case Routing in Application Integration
Process Flow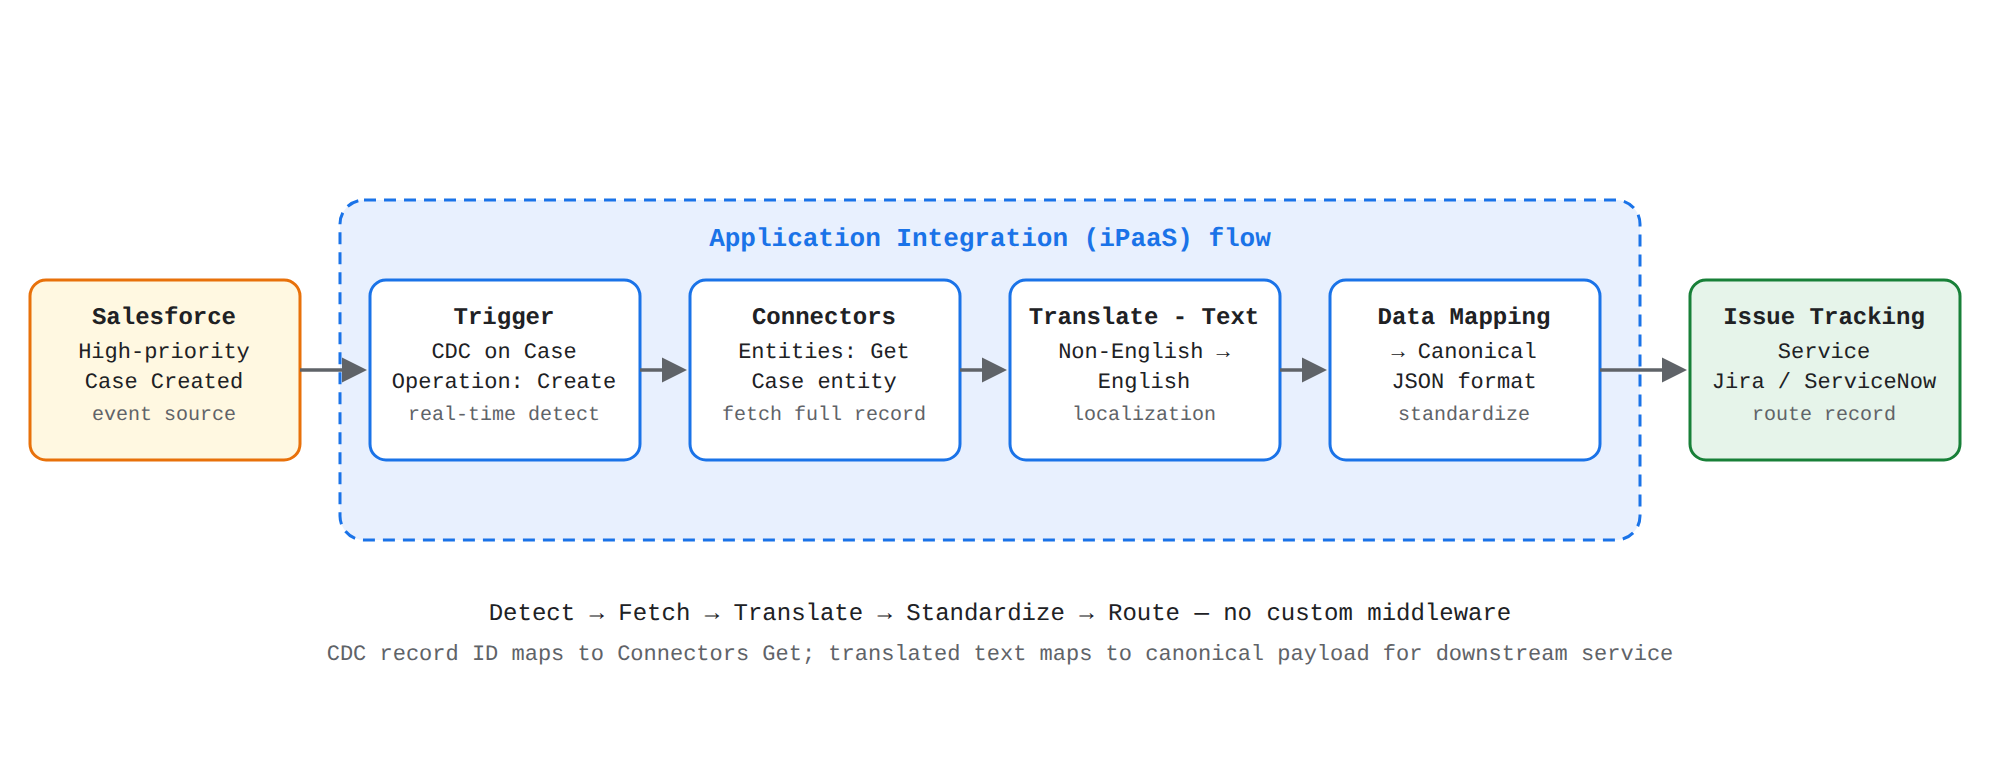
Key Advantages and Capabilities
- No-Code/Low-Code Orchestration: Connects disparate SaaS environments using pre-built triggers, tasks, and visual mapping canvases.
- Built-In Transformations: Employs Data Mapping and Data Transformer tasks to standardize varied schemas and variable data types easily.
- Native Enterprise Connectors: Manages authentication, connection pooling, and credential lifecycle securely across multi-cloud and SaaS platforms.
- Real-Time Responsiveness: Event-driven architecture ensures zero-delay processing compared to scheduled batch polling.
Why This Is Optimal
This architecture directly maps each step of the business user story to purpose-built, managed cloud integration components. It eliminates the operational overhead of running custom server infrastructure while providing built-in error handling, schema mapping, and managed security.
Configure a Cloud Scheduler cron job to poll Salesforce via REST API every hour, write the payloads to Cloud Storage, and execute a Data Transformer Jsonnet task to translate text before schema validation.
Configure a Cloud Scheduler cron job to poll Salesforce via REST API every hour, write the payloads to Cloud Storage, and execute a Data Transformer Jsonnet task to translate text before schema validation.
What Cloud Scheduler and Polling Patterns Are
Cloud Scheduler is a fully managed cron job service that triggers tasks on a recurring schedule. Polling architectures periodically query target systems to check for new or updated records.
Why It Doesn't Meet the Requirement
- Fails Real-Time Requirement: Periodic polling (e.g., hourly) introduces significant latency and fails the requirement to immediately process high-priority cases.
- Misuse of Data Transformer: The Data Transformer task in Application Integration uses Jsonnet to map data models and manipulate data structures, but it cannot perform automated natural language machine translation on text strings.
- Unnecessary Intermediary Storage: Writing operational transactional payloads into Cloud Storage staging buckets adds latency, storage costs, and complexity for a direct application integration use case.
Key Characteristics and Limitations
- Polling increases API consumption against Salesforce quotas even when no new cases exist.
- Jsonnet templates are designed for structural data templating and mapping, not external API service calls.
- Batch scheduling is ill-suited for critical real-time incident routing.
This Answer Would Be Correct If
The requirement was to batch-export non-urgent audit logs from Salesforce into Cloud Storage on a recurring schedule for long-term compliance archiving.
Deploy a Cloud Dataflow streaming pipeline that reads Salesforce webhooks, uses a static singleton Map side-input to query the Cloud Translation API for each record, and executes GroupByKey transforms for external routing.
Deploy a Cloud Dataflow streaming pipeline that reads Salesforce webhooks, uses a static singleton Map side-input to query the Cloud Translation API for each record, and executes GroupByKey transforms for external routing.
What Cloud Dataflow and Side-Inputs Are
Cloud Dataflow is a fully managed data processing service based on Apache Beam that executes batch and streaming big data pipelines. Side-inputs are additional inputs that allow Beam transforms to access lookup data alongside the main PCollection.
Why It Doesn't Meet the Requirement
- Misuse of Side-Inputs: A singleton
Mapside-input is specifically designed for small, slowly changing in-memory lookup tables (such as static store metadata or postal code mappings), not for dynamic external API queries like natural language translation. - Architectural Overkill and Inefficiency: Building a bespoke streaming Beam pipeline with custom webhooks and
GroupByKeyshuffle stages introduces unnecessary coding, maintenance, and compute overhead for straightforward event-driven SaaS routing. - Performance Overhead: Calling an external translation API per record inside worker transforms without proper bundling can easily exhaust API rate limits or degrade pipeline throughput.
Key Characteristics and Limitations
- Dataflow excels at high-volume stream analytics, complex windowing, and ETL processing across millions of events per second.
- Side-inputs must fit into worker memory and are not designed to dynamically invoke external translation services.
- Requires writing and maintaining custom Java or Python Beam pipelines.
This Answer Would Be Correct If
The scenario involved high-throughput real-time stream processing of millions of telemetry logs per second that required enrichment from a static reference dataset.
Implement an offloaded BigQuery data warehouse migration pipeline that syncs Salesforce records once daily, utilizes facade views for schema translation, and triggers Dataflow to load transformed rows into the ticketing platform.
Implement an offloaded BigQuery data warehouse migration pipeline that syncs Salesforce records once daily, utilizes facade views for schema translation, and triggers Dataflow to load transformed rows into the ticketing platform.
What BigQuery Offloading and Facade Views Are
BigQuery data warehouse offloading and facade views are analytical migration patterns. Offloading involves copying data from an existing operational system or legacy warehouse into BigQuery to serve downstream analytics and business intelligence workloads. Facade views mask underlying table schema transformations from analytical queries.
Why It Doesn't Meet the Requirement
- Latency Constraint: The business requirement demands immediate event detection and routing. Running a once-daily batch synchronization creates unacceptable delays for high-priority support cases.
- Incorrect Workload Domain: BigQuery is an enterprise analytical data warehouse built for SQL aggregation and OLAP reporting, not transactional event processing, real-time message routing, or SaaS application orchestration.
- Missing Functional Integrations: Facade views only simplify SQL table queries; they do not perform automated natural language text translation or invoke downstream REST endpoints.
Key Characteristics and Limitations
- Optimized for large-scale analytical queries rather than point-in-time API routing.
- Designed for batch or streaming data warehousing rather than transactional process orchestration.
- Lacks native event-driven triggers for SaaS applications like Salesforce.
This Answer Would Be Correct If
The organization needed an iterative data warehouse migration to offload historical CRM cases into BigQuery for Looker dashboards without disrupting legacy analytical queries.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,335 practice questions across all 6 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
IntermediateProfessional Cloud Architect
SLIs, SLOs, and Error Budgets
Identifying functional and non-functional requirements
IntermediateProfessional Cloud Architect
BigQuery Data Residency, CMEK, and VPC Service Controls
Identifying functional and non-functional requirements
IntermediateProfessional Cloud Architect
Apigee Adapter for Envoy
Supporting the application design
IntermediateProfessional Cloud Architect
Artifact Analysis On-Demand Scanning
Testing and validation of software and infrastructure
IntermediateProfessional Cloud Architect
Cloud Spanner Germany Dual-Region Configuration
High availability and fail-over design
FundamentalAssociate Data Practitioner
Encryption In Transit vs Encryption At Rest
Identify the difference between encryption in transit and encryption at rest
Last updated