Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Latency SLIs and SLOs for 200 ms API Performance
Free sample question, answered and explained below. The Professional Cloud Architect practice bank has 2,335 more like it. Try 10 free: instant score, no account.
An enterprise organization is architecting a globally distributed e-commerce API backend on Google Cloud. To ensure a resilient, low-latency user experience during high-traffic events, the architecture team must define non-functional requirements for performance and availability.
The requirements are as follows:
- Quantify user-perceived performance by tracking the proportion of requests served in under 200 ms.
- Establish an objective target to manage release risk and quantify acceptable downtime or degradation over a rolling 30-day period.
- Determine the maximum sustainable traffic throughput before latency violates the target threshold.
Which approach should the cloud architect implement to establish these requirements and thresholds?
Explanations
Implement a windowed Availability SLI measuring total connection concurrency per backend instance, define an annual SLO compliance period, and size backend resources so that peak utilization matches 100% capacity.
Implement a windowed Availability SLI measuring total connection concurrency per backend instance, define an annual SLO compliance period, and size backend resources so that peak utilization matches 100% capacity.
What this option does
This option tracks the raw number of concurrent client connections over time windows, defines a fixed 365-day compliance measurement window, and sizes infrastructure backend capacity to run at 100% utilization during peak load.
Why it doesn't meet the requirement
- Measures concurrency instead of latency: Connection concurrency measures open sockets and network connections, but does not measure whether client requests are completing within the mandated 200 ms latency target.
- Excessively broad compliance window: An annual compliance window delays operational feedback, preventing teams from rapidly identifying and remediating short-term reliability regressions.
- Dangerous capacity planning: Planning for 100% resource utilization leaves no headroom for unexpected traffic spikes, resulting in queued requests, severe tail latency, and dropped connections during peak traffic.
Key characteristics and limitations
- Connection concurrency does not equal request latency, especially when HTTP/2 or HTTP/3 connection multiplexing is used.
- Optimal resource utilization for latency-sensitive backends is typically well below 100% to avoid queueing delays.
- Long compliance periods dilute the urgency and visibility of recent performance degradations.
This answer would be correct if
The goal was to monitor long-term socket exhaustion on stateful gateway proxy servers rather than validating low-latency API response performance.
Configure an infrastructure-level Availability SLI based on internal ICMP ping response times across Compute Engine VMs, configure alerting policies in Cloud Monitoring for peak disk I/O, and set regional quota limits to trigger autoscaling.
Configure an infrastructure-level Availability SLI based on internal ICMP ping response times across Compute Engine VMs, configure alerting policies in Cloud Monitoring for peak disk I/O, and set regional quota limits to trigger autoscaling.
What this option does
This option measures network reachability at Layer 3 using ICMP ping response times between internal compute nodes, tracks storage subsystem disk I/O via Cloud Monitoring, and uses project quota limits to dictate scaling behavior.
Why it doesn't meet the requirement
- Inaccurate proxy for user latency: ICMP ping only measures low-level network packet transit time between internal hosts; it does not measure application processing time, TLS handshakes, or HTTP response payloads.
- Missing latency threshold: It fails to evaluate the required 200 ms application request threshold or calculate an actionable error budget over the specified 30-day window.
- Improper scaling mechanism: Google Cloud resource quotas are organizational safety limits to prevent runaway spending or resource exhaustion; they are not dynamic triggers for application autoscaling or capacity planning.
Key characteristics and limitations
- Network ICMP probes bypass the entire application and middleware software stack.
- Disk I/O metrics only evaluate storage subsystem utilization without reflecting user-perceived responsiveness.
- Quota monitoring prevents administrative resource exhaustion rather than scaling active application instances.
This answer would be correct if
The scenario required monitoring private network link connectivity and underlying block storage saturation across internal data center interconnects.
Define a request-based Latency Service Level Indicator (SLI) measuring the ratio of requests completed under 200 ms to total requests, establish a Service Level Objective (SLO) percentage goal over a rolling 30-day compliance period to derive an error budget, and perform load testing to determine the request rate threshold where 99th-percentile latency remains within the SLO limit.
Define a request-based Latency Service Level Indicator (SLI) measuring the ratio of requests completed under 200 ms to total requests, establish a Service Level Objective (SLO) percentage goal over a rolling 30-day compliance period to derive an error budget, and perform load testing to determine the request rate threshold where 99th-percentile latency remains within the SLO limit.
What this solution is
This solution establishes a formal Site Reliability Engineering (SRE) framework using Service Level Indicators (SLIs), Service Level Objectives (SLOs), and error budgets implemented via Google Cloud Observability and structured capacity planning.
How it meets the requirements
- Quantifying low-latency performance: Defining a request-based Latency SLI as the ratio of valid requests resolved below the 200 ms Latency Threshold directly tracks the user experience at the application layer.
- Managing release risk and reliability: Setting a percentage goal for the SLO over a rolling 30-day compliance period provides an active error budget, allowing engineering teams to balance feature delivery velocity against system reliability.
- Determining traffic thresholds: Executing load testing to find the request rate where the 99th-percentile latency meets the SLO boundary allows the team to pinpoint exact scaling limits and capacity thresholds before production degradation occurs.
SLI → SLO → Error Budget Flow
Process Flow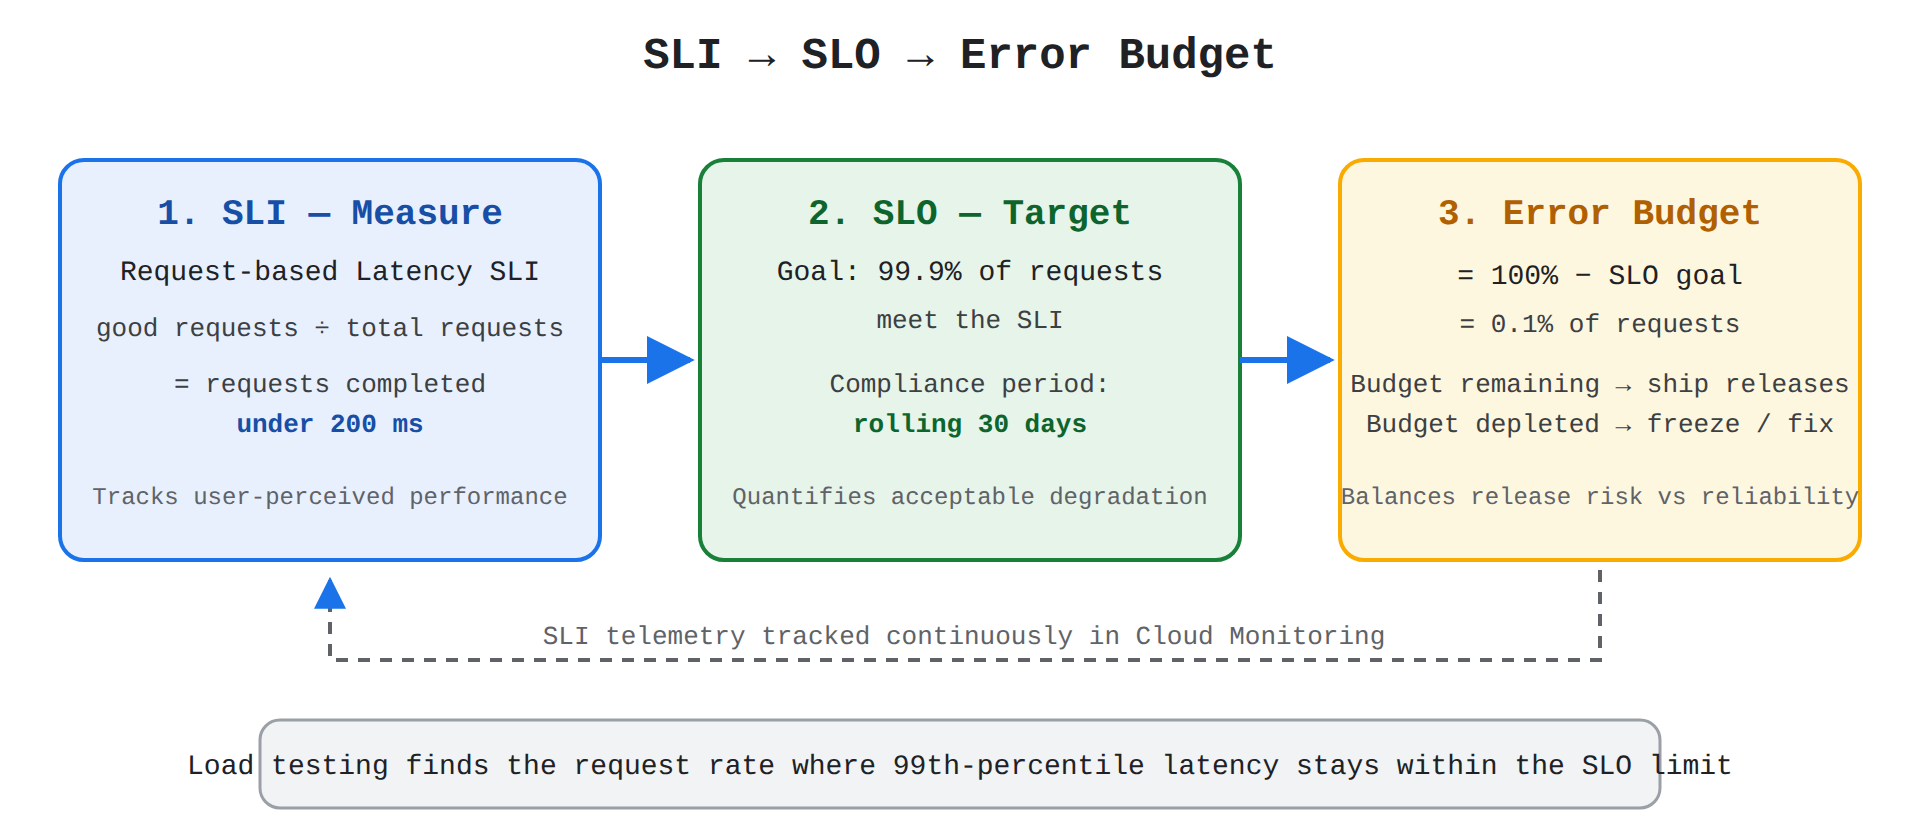
Key advantages and capabilities
- Direct user alignment: Measures actual customer experience rather than raw underlying infrastructure resource metrics.
- Actionable error budgets: Provides a mathematical threshold (
100% - SLO Goal) to govern deployment freezes and architectural remediation. - Predictable capacity planning: Correlates load generation throughput directly against latency distributions.
- Native observability integration: Seamlessly tracks performance goals inside Cloud Monitoring and Cloud Service Mesh.
Why this is optimal
This approach directly targets the non-functional performance requirements by coupling quantifiable quality attributes (latency and availability) with empirical threshold testing, ensuring global system resilience without over-provisioning infrastructure.
Establish a contractual Service Level Agreement (SLA) target for 100% availability, use Cloud Logging metrics tracking average CPU utilization per instance, and conduct stress testing to identify the exact breakpoint where Compute Engine virtual machines crash.
Establish a contractual Service Level Agreement (SLA) target for 100% availability, use Cloud Logging metrics tracking average CPU utilization per instance, and conduct stress testing to identify the exact breakpoint where Compute Engine virtual machines crash.
What this option does
This option attempts to enforce a contractual Service Level Agreement (SLA) of 100% availability while relying on host-level hardware utilization metrics (such as CPU consumption) in Cloud Logging and destructive stress testing to identify system failure limits.
Why it doesn't meet the requirement
- Unrealistic availability targets: Targeting 100% availability leaves a zero error budget, making normal software maintenance, deployments, and transient network anomalies catastrophic failures.
- SLA vs. SLO confusion: An SLA is an external legal and financial contract with customers that defines penalties, whereas an SLO is the internal operational target used by engineering teams to guide reliability.
- Indirect performance metrics: Tracking average instance CPU utilization does not directly correlate with user-facing request latency (a system can experience high latency due to database locks or network congestion while CPU utilization remains low).
- Misaligned testing goal: Overload stress testing to find physical crash limits does not establish the operational capacity threshold required to maintain the 200 ms latency requirement.
Key characteristics and limitations
- SLAs define business commitments and financial penalties rather than internal engineering goals.
- Host metrics do not capture distributed request-response latency profiles.
- Destructive stress testing identifies catastrophic failure points, not performance-degradation inflection points.
This answer would be correct if
The objective was to establish legal compensation terms for external enterprise clients and determine the absolute hardware failure boundaries of unmanaged virtual machine instances.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,335 practice questions across all 6 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
IntermediateProfessional Cloud Architect
BigQuery Data Residency, CMEK, and VPC Service Controls
Identifying functional and non-functional requirements
IntermediateProfessional Cloud Architect
Application Integration
Identifying functional and non-functional requirements
IntermediateProfessional Cloud Architect
Cloud Run CPU Allocation and Startup CPU Boost
Mapping compute needs to platform products (e.g., Google Kubernetes Engine [GKE], Cloud Run, and Cloud Run functions)
IntermediateProfessional Cloud Architect
Shared VPC Per Environment with Folder Hierarchy
Resource hierarchy (organizations, folders, and projects)
IntermediateProfessional Cloud Architect
Same-Zone VPC Benchmarking Client
Profiling and benchmarking
FundamentalAssociate Data Practitioner
gcloud storage cp --recursive
Load data into Google Cloud storage systems using the appropriate tool (e.g., gcloud and BQ CLI, Storage Transfer Service, BigQuery Data Transfer Service, client libraries)
Last updated