Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Tokenization and Masking with SDP Templates
Free sample question, answered and explained below. The Professional Cloud Architect practice bank has 2,335 more like it. Try 10 free: instant score, no account.
An enterprise is preparing customer service datasets stored in Google Cloud to train a machine learning model for sentiment analysis. The datasets include structured customer identifier fields (such as customer email addresses) alongside unstructured freeform text fields (such as customer support notes and reviews).
The machine learning engineering team has specified the following requirements:
- Referential integrity must be preserved so that multiple interactions and reviews from the same individual customer can still be grouped and aggregated.
- Unstructured text columns must be scanned to identify and mask intermittent personally identifiable information (PII), such as phone numbers and government-issued identification numbers.
- Plaintext sensitive PII must not be exposed to the model training and development environment.
Which Sensitive Data Protection (SDP) architecture should you implement?
Explanations
Enable Sensitive Data Protection automated discovery to generate data profiles and export the resulting data risk metrics to Security Command Center and Dataplex.
Enable Sensitive Data Protection automated discovery to generate data profiles and export the resulting data risk metrics to Security Command Center and Dataplex.
What the Option Is
Sensitive data discovery is an automated profiling service within Sensitive Data Protection that continuously scans BigQuery tables, Cloud Storage buckets, and databases across an organization to generate statistical risk profiles, infoType classifications, and security posture metrics.
Why It Doesn't Meet the Requirement
- Discovery and Profiling Only: Automated discovery identifies where sensitive data resides and measures overall data risk, but it does not execute data transformations, masking, or tokenization on the dataset itself.
- Data Remains Raw: The dataset consumed by the AI model training job would remain unmasked and un-tokenized, exposing raw customer PII.
- No Pipeline Integration: Exporting data risk profiles to Security Command Center or Dataplex Universal Catalog aids governance and security posture monitoring, but it does not create a sanitized dataset for machine learning.
Key Characteristics and Limitations
- Visibility and Governance: Generates broad organizational visibility into sensitive data presence.
- Read-Only Inspection: Measures risk levels without modifying or writing transformed copies of source data.
- Audit and Alerting Focus: Best suited for continuous compliance auditing rather than in-line ETL/ELT data sanitization.
This Answer Would Be Correct If
The primary goal was to obtain continuous visibility and high-level reporting of sensitive data assets across the enterprise without performing transformations.
Configure a Sensitive Data Protection inspection job with record suppression rules configured to drop any record that contains a customer email address or detected sensitive infoTypes.
Configure a Sensitive Data Protection inspection job with record suppression rules configured to drop any record that contains a customer email address or detected sensitive infoTypes.
What the Option Is
Record suppression is a de-identification technique in Sensitive Data Protection where entire rows or records are omitted from the output dataset when specified conditions evaluate to true.
Why It Doesn't Meet the Requirement
- Loss of Training Data: Suppressing every record that contains an email address or intermittent PII will discard virtually the entire customer review dataset, making model training impossible.
- Fails Referential Integrity: Record suppression removes the records completely rather than transforming them into a privacy-preserving format, preventing the ML team from analyzing or aggregating customer interactions.
Key Characteristics and Limitations
- All-or-Nothing Approach: Suppresses entire records rather than transforming or sanitizing individual sensitive fields.
- Drastic Reduction in Data Volume: Highly disruptive when applied to datasets where PII appears routinely in standard metadata fields.
- No Entity Continuity: Does not provide surrogate keys or tokens for cross-record analysis.
This Answer Would Be Correct If
The objective was to discard corrupt, invalid, or extremely high-risk records entirely from a dataset where partial masking or anonymization is prohibited by strict compliance policies.
Apply BigQuery policy tags with column-level security and IAM access controls to restrict access to the customer email column and freeform text review columns.
Apply BigQuery policy tags with column-level security and IAM access controls to restrict access to the customer email column and freeform text review columns.
What the Option Is
BigQuery column-level security uses taxonomy-based policy tags and Identity and Access Management (IAM) roles to restrict access to specific table columns based on user identity and group membership.
Why It Doesn't Meet the Requirement
- No Data Transformation: Policy tags do not mask or de-identify data; they merely block unauthorized users from reading specific columns.
- Blocks Model Training: If the ML service accounts or data scientists are granted access to read the freeform text column, they will see raw PII. If they are denied access, the ML pipeline cannot consume the review text needed to train the sentiment analysis model.
- Fails Unstructured PII Remediation: Column-level security operates at the schema level and cannot parse inside unstructured text to selectively mask phone numbers or Social Security numbers while leaving the rest of the review intact.
Key Characteristics and Limitations
- Access Gatekeeper: Controls who can view columns but does not alter underlying data representations.
- Binary Visibility: Users either see the full plaintext column or receive an access denial error (unless SQL dynamic masking routines are explicitly layered on).
- No Freeform Text Parsing: Cannot detect contextual infoTypes within unstructured strings.
This Answer Would Be Correct If
The organization wanted to restrict direct human querying of sensitive structured columns in BigQuery for production users while managing permissions via IAM.
Configure a Sensitive Data Protection de-identification template that performs cryptographic tokenization on the structured email identifier field and applies masking transformations on detected sensitive infoTypes within the freeform text fields.
Configure a Sensitive Data Protection de-identification template that performs cryptographic tokenization on the structured email identifier field and applies masking transformations on detected sensitive infoTypes within the freeform text fields.
What the Solution Is
Sensitive Data Protection (SDP) provides automated de-identification and transformation capabilities designed to sanitize structured and unstructured data before it is ingested by downstream workloads such as AI/ML model training pipelines. Using custom de-identification templates, SDP can apply field-level cryptographic pseudonymization (tokenization) as well as content-level inspection and masking on unstructured text.
How It Meets the Requirements
- Preserving Referential Integrity: Applying cryptographic tokenization (pseudonymization) to the structured
emailfield replaces sensitive identifiers with consistent surrogate tokens. Because identical inputs generate identical surrogate tokens when using the same crypto key, the ML team can group, join, and aggregate records belonging to the same user without seeing the underlying email address. - Masking Intermittent PII in Freeform Text: SDP evaluates freeform strings against built-in or custom infoType detectors (such as
PHONE_NUMBERandUS_SOCIAL_SECURITY_NUMBER) and applies masking transformations (e.g., replacing values with***or surrogate tags) directly to detected sensitive text. - Protecting the AI Training Environment: Sanitizing the raw dataset before exporting it to the ML development environment ensures compliance with data privacy regulations by minimizing exposure of raw PII.
Tokenization Preserves Referential Integrity
Process Flow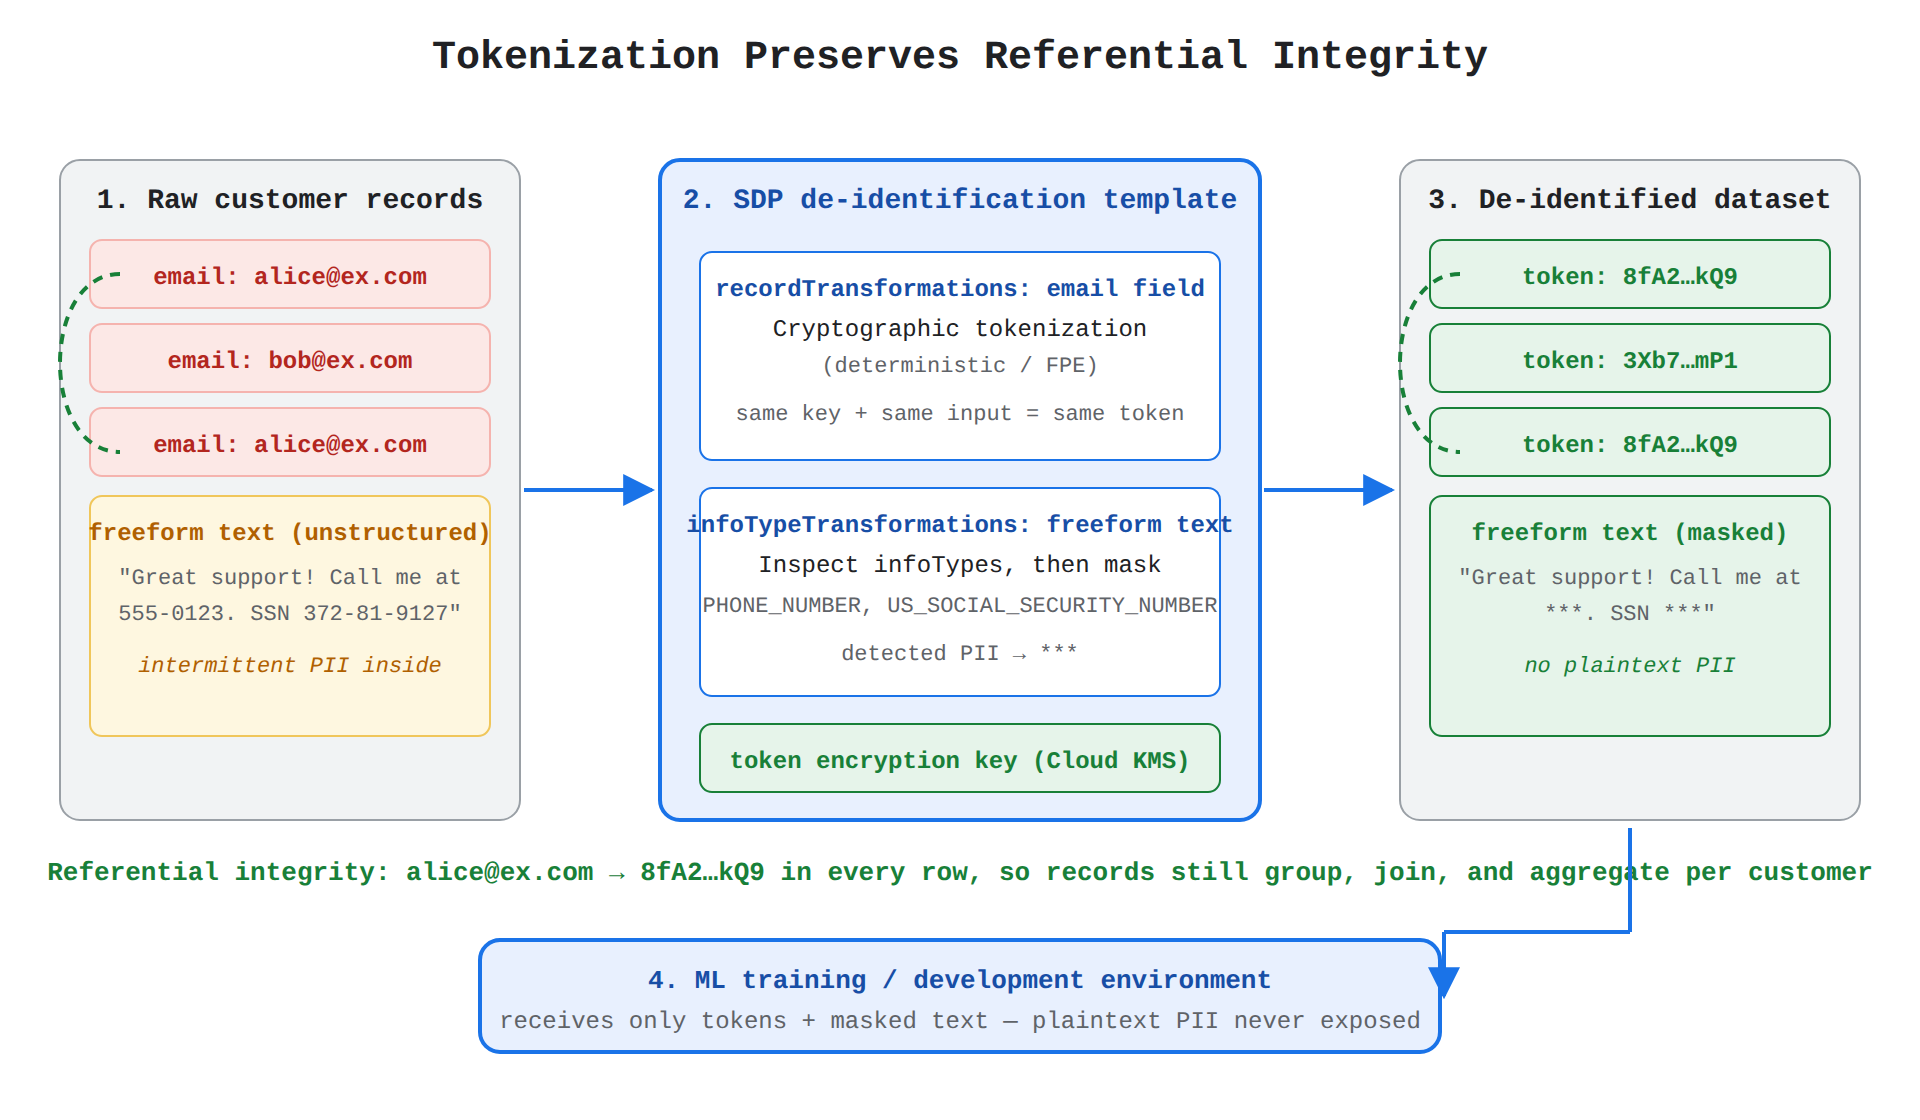
Key Advantages and Capabilities
- Format-Preserving Encryption (FPE) and Tokenization: Maintains data utility and relational joins across multiple tables and training datasets.
- Automated InfoType Detection: Scans complex unstructured freeform text to identify sensitive entities using contextual rules and machine learning.
- Template Reusability: De-identification templates can be managed centrally, version-controlled, and reused across batch pipelines (Dataflow/Data Fusion) and remote BigQuery SQL functions.
- Fine-Grained Obfuscation: Allows different transformation rules for distinct columns and data classifications within the same processing job.
Why This Is Optimal
This solution strikes the optimal balance between data privacy and data utility. Pure redaction or record deletion would destroy the relational links required for customer-level sentiment modeling, whereas tokenization preserves structural analytical value while eliminating cleartext PII risk.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,335 practice questions across all 6 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
IntermediateProfessional Cloud Architect
Model Armor Generative AI Security
Securing AI (e.g., Model Armor, Sensitive Data Protection, and secure model deployment)
IntermediateProfessional Cloud Architect
Vertex AI Security Architecture
Securing AI (e.g., Model Armor, Sensitive Data Protection, and secure model deployment)
IntermediateProfessional Cloud Architect
Cloud Armor vs Cloud NGFW
Security protection (e.g. intrusion protection, access control, and firewalls)
IntermediateProfessional Cloud Architect
Cloud Deploy Skaffold deploy.statusCheck
Deployment and release management
IntermediateProfessional Cloud Architect
Compute Engine Instance Availability Policy
Assisting with the support of deployed solutions
AdvancedProfessional Data Engineer
CSEK vs CMEK vs Cloud EKM
Data encryption
Last updated