Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Securing AI Models and Data on Google Cloud
Mitigation of model-specific vulnerabilities means adding controls around large language models (LLMs) that block attacks on the model itself rather than on servers or networks. These attacks include prompt injection that overrides system instructions, jailbreaking that bypasses safety rules, and generation of prohibited or sensitive content. On Google Cloud, mitigation depends on Model Armor (opens in a new tab) screening prompts and responses, safety thresholds that enforce policy, and agent design that limits what the model can do even when input is malicious.
Model Armor Prompt and Response Screening
Model Armor is a Google Cloud service that proactively screens LLM prompts and responses to enforce safety and security policy. User prompts flow from the application to Model Armor for inspection before they reach the model, and model responses flow back through Model Armor before they reach the user. This placement lets Model Armor block malicious input, verify content safety, protect sensitive data, and apply the same policy consistently whether the model runs on Google Cloud or on an external provider.
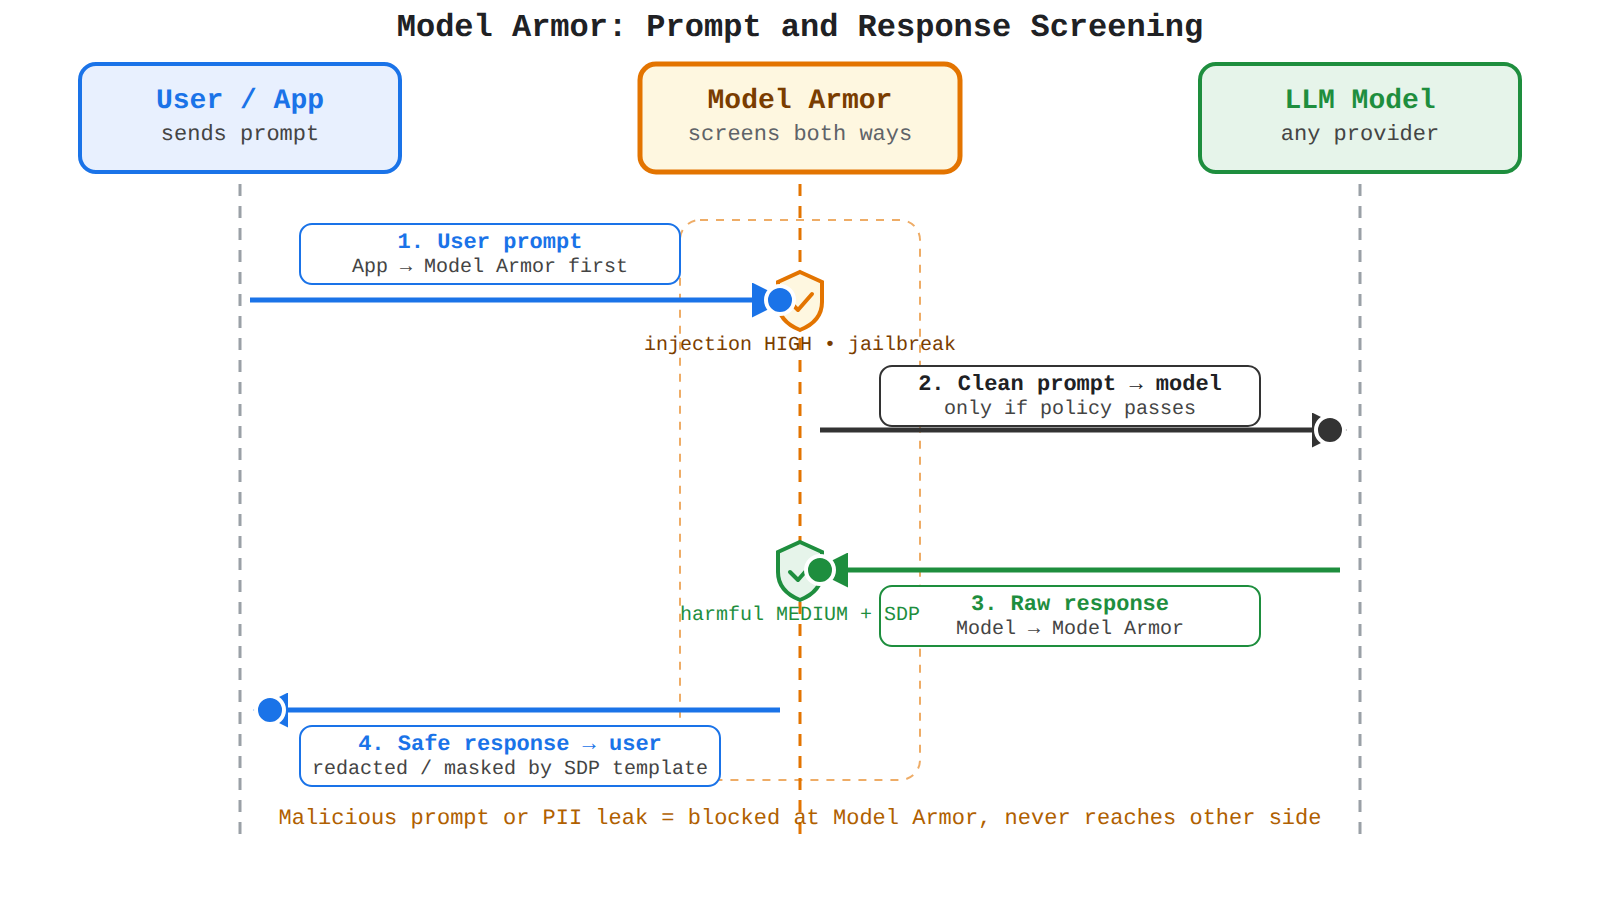
A sequence diagram with User, Model Armor, and LLM lifelines showing prompt screening before the model and response screening before the user, with animated dots flowing in order.
Model Armor protection is enabled by turning on the Model Armor API in the project and attaching protection to the model endpoint or floor setting. A floor setting defines the minimum security filters that apply to all Model Armor calls within a project, so individual workloads cannot drop below the baseline. Model Armor is available only in specific regions, and a call from an unsupported region triggers a cross-regional call to a supported region. If a Model Armor request fails, Model Armor logs the entire payload, which can expose sensitive information in logs.
Configuring Safety Filters and Content Thresholds
Model Armor safety filters are the configured rules that decide which prompts and responses are blocked, masked, or allowed. Filters cover jailbreak and injection attacks, harmful content, and sensitive data, and each filter uses a threshold that balances model utility against organizational policy. A strict threshold blocks more borderline content but can refuse legitimate requests, while a loose threshold preserves utility but allows more risk.
The three filter groups work together in one policy object:
| Filter | What it screens | Policy control |
|---|---|---|
| Injection and jailbreak filter | Prompts that try to override system instructions or bypass safety rules | Threshold such as HIGH blocks suspected injection before it reaches the model |
| Harmful content filter | Obscenity, extremism, violence, sexually explicit, dangerous, harassment, and hate-speech content | Threshold such as MEDIUM controls how aggressively borderline content is blocked |
| Sensitive data filter | Personally identifiable information (PII) and other sensitive data in prompts and responses | Sensitive Data Protection DeidentifyTemplate redacts or masks matches before return to the user |
Model Armor threshold configuration links detection sensitivity to data protection behavior in one policy object. In a typical configuration, safety_thresholds sets injection to HIGH and harmful_content to MEDIUM, while data_protection_config references a template such as projects/PROJECT_NUMBER/locations/LOCATION/deidentifyTemplates/DLP_TEMPLATE_ID. Data flows from the model output through the Sensitive Data Protection template for redaction or masking and then to the user, so protection holds even if the model is compromised. Missing filters are reported as audit findings, including MODEL_ARMOR_HARMFUL_DATA_FILTERS_DISABLED at MEDIUM severity and MODEL_ARMOR_SENSITIVE_DATA_FILTERS_DISABLED at LOW severity.
Exam tip: Do not enable the prompt injection and jailbreak filter for MCP traffic unless that traffic carries natural language data.
Secure Agent Design Against Injection and Tool Misuse
Secure agent design is application logic that assumes inputs are hostile and limits the damage a tricked model can cause. The agent treats end-user text and external data such as web results or third-party documents as untrusted, and it avoids open-ended plan-and-execute architectures where the model freely decides control flow. Instead the action-selector pattern restricts the model to translating a request into one of a small set of pre-defined safe functions whose logic is hard-coded and cannot be changed by the LLM. The dual-LLM pattern pairs an action LLM that performs the task with a guardrail LLM that pre-screens the prompt for malicious intent and post-screens the output for unauthorized actions or data leakage.
Secure orchestration code prevents unauthorized tool chaining by allowing only the tools necessary for the task. The code blocks dynamic tool registration and permission changes, while an allowlist declared in the system prompt and backend code names the exact functions or tables the agent may use. A general execute_sql tool is unsafe in multi-tenant databases because any IAM-permitted row can be read if the user tricks the agent, and instructing the agent to enforce rules is not sufficient protection. The safe alternative builds custom tools with MCP Toolbox for Databases (opens in a new tab), such as lookup_active_order where the user identity in the query filter is set outside the agent's control.
Monitoring Model Inputs and Outputs for Attacks
Monitoring model inputs and outputs means watching live traffic for post-authentication attacks after authentication and authorization have been bypassed. Apigee (opens in a new tab) secures inference endpoints with request validation, traffic control, authentication, and rate limiting, while VPC Service Controls creates a service perimeter around Model Registry or BigQuery data and Identity-Aware Proxy (IAP) protects web tools such as notebooks. These network boundaries sit outside the model, so anomalous requests are contained before they can exfiltrate models or data.
Three traffic signals indicate probing, theft, or hijack attempts against the model:
- Query pattern anomalies: the monitor flags thousands of slightly different sequential queries from a caller when the pattern does not match normal user behavior.
- Request volume spikes: the monitor treats a sudden surge from one IP address or user as a possible denial-of-service or model-theft attempt to reverse-engineer the model.
- Geographic and temporal anomalies: the monitor compares activity against a baseline of normal locations and hours and alerts on events such as a surge of logins from a new country at 3 AM.
Rate limiting and throttling in Apigee control request volume from a single IP address or user when these signals fire. Alerts from Cloud Logging route the anomalous caller, model endpoint, and query history to responders, so investigation starts from the request that crossed the trust boundary into the model.
Data privacy and Sensitive Data Protection means finding, classifying, and transforming sensitive data in AI datasets so models can learn without exposing real identities. Sensitive Data Protection (opens in a new tab) is the Google Cloud service that scans data for personally identifiable information (PII) such as credit card numbers, addresses, and phone numbers, then applies protections that reduce privacy risk while keeping the data useful. Combined with data minimization, governance, and access controls, Sensitive Data Protection helps AI systems meet global data privacy regulations.
Data Minimization for AI Datasets
Data minimization for AI datasets is the practice of not collecting, keeping, or using data that is not strictly necessary for business goals. Training data carries the largest risk of bias, leakage, and compliance failure if it contains unneeded PII, so using less data directly lowers privacy risk. Where possible, teams should use synthetic data or fully anonymized data instead of raw customer data.
Google Cloud supports minimization with Cloud Storage lifecycle controls, which limit how long data is retained and reduce prolonged access or manipulation. Collecting PII without discretion can also produce biased machine learning models, so minimizing inputs protects both privacy and model quality. Logs of data access and manipulation further help audit use and detect unauthorized attempts.
Automated Discovery and Classification
Automated discovery and classification means Sensitive Data Protection scans storage and analytics data to locate PII without manual review. Sensitive Data Protection can inspect BigQuery (opens in a new tab) tables and text, classify findings such as financial information or other PII, and send inspection results from BigQuery to Knowledge Catalog for centralized governance. Knowledge Catalog then provides discovery, data lineage including column-level lineage, data quality checks, data profiles, and a business glossary across data platforms.
Model Armor extends this discovery into runtime protection when combined with Sensitive Data Protection. Sensitive Data Protection with Model Armor discovers, classifies, and protects sensitive data such as intellectual property in LLM interactions. Data flows from prompts and training datasets through Sensitive Data Protection classification to Model Armor enforcement, which helps prevent unauthorized exposure of sensitive data in LLM inputs and outputs.
De-identification and Protective Transformations
De-identification and protective transformations change sensitive values so datasets remain useful for training and inference without exposing real identities. Sensitive Data Protection applies these transformations before data is stored or used in Google Cloud, including tagging and tokenizing classified data. This approach preserves analytical utility while lowering the chance that a model memorizes or reveals PII.
Common transformation methods include:
- Pseudonymization replaces direct identifiers with artificial identifiers that can be mapped back under controlled conditions.
- De-identification removes or masks PII, including redaction of sensitive text found by inspection jobs.
- Generalization such as bucketing replaces precise values with broader ranges or categories to reduce re-identification risk.
Differential privacy adds another layer during analysis and training by adding noise to data in BigQuery. With SQL in BigQuery, teams can run differentially private aggregations that make it difficult to identify individual data points while still letting the model learn overall patterns.
Exam tip: Use Sensitive Data Protection to discover and transform PII in stored datasets, and use Sensitive Data Protection with Model Armor to prevent exposure of sensitive data in LLM prompts and responses.
Governance and Access Controls for Compliance
Governance and access controls for compliance monitor how training data flows from collection through storage, transformation, and model use. Knowledge Catalog (opens in a new tab) acts as the organization-wide governance platform to centrally discover, manage, monitor, and govern data and AI artifacts, including feature metadata, model artifacts, and lineage showing where data comes from and what transformations were applied. BigQuery data clean rooms and sharing controls, plus scheduled monitoring in Agent Platform Feature Store, help teams share and reuse data across privacy boundaries in a governed way.
Access controls place sensitive data inside explicit trust boundaries. Teams should place sensitive data in its own service perimeter with VPC Service Controls, which configures a security perimeter around Google-managed resources to control data movement and reduce exfiltration. The perimeter depends on Identity and Access Management (IAM) for access decisions and on multifactor authentication (MFA) for all users who require access to sensitive data. Together, automated scanning, de-identification, lineage tracking, and perimeter controls create an auditable path from raw data to deployed model that supports compliance.
Secure infrastructure and deployment architecture for AI on Google Cloud is a layered design that keeps training data, model artifacts, and prediction requests inside controlled boundaries with customer-controlled keys and identity checks. VPC Service Controls (opens in a new tab) provides the network perimeter, Identity and Access Management (IAM) and Access Context Manager control who can enter it, Cloud Key Management Service (Cloud KMS) controls how data is encrypted inside it, and Sensitive Data Protection plus logging provide content and activity visibility. Data flows from upload to encrypted storage to inspection and de-identification, and only designated principals that satisfy both identity and context rules can read it.
Network Isolation with VPC Service Controls
VPC Service Controls is a managed networking functionality that creates a security perimeter around Google-managed services such as BigQuery and Cloud Storage to minimize data exfiltration. Resources that hold AI datasets and model artifacts sit inside the perimeter, while the public internet and other Google Cloud projects sit outside the perimeter. The perimeter blocks data movement across its boundary by default, and it explicitly overrides permissive IAM settings so a misconfigured bucket or dataset does not become publicly readable. Access from outside is granted only through an Access Context Manager access level that names the allowed principals, devices, or network conditions.
Exam tip: VPC Service Controls denies access even when IAM allows it — IAM grants permission to an identity, but the perimeter still blocks the request unless the caller also satisfies the access level.
Identity Control with IAM and Access Context Manager
Identity control with IAM and Access Context Manager defines which principals can act on AI resources and under which context they may cross the perimeter. Identity and Access Management (IAM) (opens in a new tab) is the system that defines which principals, such as users, groups, and service accounts, can act on AI deployment resources. Access Context Manager is the service that defines fine-grained, attribute-based conditions, called access levels, for projects and resources inside a VPC Service Controls perimeter. Together they enforce least privilege and separation of duties by limiting access at the project, folder, or dataset level, requiring multifactor authentication (MFA) for users who handle sensitive data, and supporting deny policies that block horizontal movement from system to system.
The deployment depends on both sides: IAM proves who the caller is, and Access Context Manager proves whether the caller context is allowed to cross the perimeter boundary. A caller must therefore satisfy IAM permission checks and the access-level conditions on every request that touches data inside the perimeter. This dual check prevents a valid identity from one network or device from moving sensitive AI data to an untrusted destination.
Encryption Control with Customer-Managed Encryption Keys
Encryption control with customer-managed encryption keys (CMEKs) gives the customer ownership of the keys that protect AI data at rest. Customer-managed encryption keys (CMEKs) (opens in a new tab) are encryption keys that you own and control in Cloud KMS to protect AI data at rest. Services with a CMEK integration use envelope encryption, where the service encrypts data with a data encryption key (DEK) and then wraps that DEK with a key encryption key (KEK) fetched from Cloud KMS. Cloud KMS Autokey simplifies this by creating and assigning suitable KEKs automatically, while Cloud Hardware Security Module (Cloud HSM) and Cloud External Key Manager (Cloud EKM) change where the KEK lives and who operates it.
The three encryption choices differ in who controls the key and how AI data is protected:
| Encryption option | Who controls the key | How AI data is protected |
|---|---|---|
| Default Google encryption | Google-owned and Google-managed keys | Transparent server-side encryption with FIPS 140 validated AES-256 |
| CMEK with Cloud KMS or Autokey | Customer in Cloud KMS, optionally in Cloud HSM | Service wraps DEKs with customer KEKs; data is readable only with the customer key |
| CMEK with Cloud EKM | Customer outside Google Cloud | External key protects data at rest in supported services or through the Cloud KMS API |
Google provides strong isolation for key material: decrypted key material cannot be exported or viewed through APIs, Google personnel cannot access unencrypted customer key material, HSM key material is never accessed in decrypted form by API jobs, and system operators are prevented from extracting customer keys during normal duties. Encryption in transit adds further layers, with Media Access Control Security (MACsec) on the Google backbone at Layer 2, transparent encryption for virtual machine (VM)-to-VM traffic within a Virtual Private Cloud (VPC) network and peered VPC networks, Transport Layer Security (TLS) for API calls, and Cloud VPN tunnels for traffic between a VPC network and on-premises infrastructure.
Classification and Audit Visibility for AI Deployments
Classification and audit visibility for AI deployments comes from Sensitive Data Protection for content inspection and Cloud Audit Logs for activity records. Sensitive Data Protection is a fully managed service that continually discovers and classifies valuable assets, including PII such as credit card numbers, addresses, phone numbers, and health information. After classification, Sensitive Data Protection de-identifies sensitive values by masking or tokenizing them with templates and options that you configure, so training and inference stores hold governed values rather than raw secrets. Cloud Audit Logs, Cloud Monitoring, and request metadata record who accessed model artifacts and prediction services, when the request arrived, and what changed, which preserves visibility over privileged actions and IAM policy changes.
Supporting controls extend that visibility to Google support access. Access Transparency gives a record of actions that Google support performs while access is granted, and Access Approval creates an approval workflow where you authorize or deny that access after a support ticket is filed. Combined with periodic review through Policy Analyzer, which shows which principals can read a BigQuery dataset or use a service account, these logs let auditors verify that only designated users and systems touched sensitive AI data.
End-to-End Secure Deployment Flow
The end-to-end secure deployment flow for AI model artifacts describes how data moves from upload through encryption, inspection, and perimeter-enforced access. The storage services BigQuery and Cloud Storage hold datasets, model files, and prediction outputs, and all access decisions are evaluated at both the IAM layer and the perimeter boundary. The order matters because encryption and de-identification happen before broad use, and the perimeter check happens on every read and copy attempt.
The flow runs in this fixed order:
- Upload with IAM permission: A user with appropriate IAM permissions uploads data to BigQuery or Cloud Storage that is configured for CMEK and Cloud KMS Autokey.
- Encrypt with customer key: The storage service fetches the KEK from Cloud KMS Autokey and encrypts the data, wrapping the DEK with the customer-controlled KEK.
- Inspect and de-identify: Sensitive Data Protection continually inspects the repository, classifies PII and other confidential fields, and masks values using configured templates.
- Enforce perimeter with access level: The storage services operate inside a VPC Service Controls perimeter that blocks outside access, and an Access Context Manager access level template grants entry only to designated IAM principals and systems.
- Deny all other access: VPC Service Controls denies any request that does not satisfy the access level, even if an IAM role would otherwise permit it.
The result is strict isolation for regulated workloads such as finance, healthcare, and public sector, where data must stay encrypted with customer keys, sensitive fields must be detected and masked, and access must remain confined and contextually managed to prevent exfiltration during training or inference.
Key Facts
- Model Armor screens user prompts before they reach the large language model and screens model responses before they reach the user to block prompt injection, jailbreaking, and prohibited content.
- Model Armor safety thresholds such as HIGH for injection and MEDIUM for harmful content balance model utility against security policy, while a Sensitive Data Protection deidentify template redacts PII before return to the user.
- Sensitive Data Protection discovers PII in BigQuery and other stores and protects it with pseudonymization, redaction or masking, generalization such as bucketing, and differentially private aggregations.
- VPC Service Controls creates a security perimeter around BigQuery and Cloud Storage that denies access even when Identity and Access Management allows it, unless the caller satisfies the Access Context Manager access level.
- Customer-managed encryption keys use envelope encryption where data is encrypted with a data encryption key and the data encryption key is wrapped with a customer-controlled key encryption key from Cloud Key Management Service.
Frequently Asked Questions
How does Model Armor screen large language model prompts and responses to block attacks?
Model Armor screens user prompts before they reach the large language model and screens model responses before they reach the user to block prompt injection, jailbreaking, and prohibited content. User prompts flow from the application to Model Armor for inspection before the model, and responses flow back through Model Armor before the user, so the same policy applies whether the model runs on Google Cloud or on an external provider.
How do Model Armor safety thresholds and Sensitive Data Protection de-identification work together?
Model Armor safety thresholds such as HIGH for injection and MEDIUM for harmful content balance model utility against security policy, while a Sensitive Data Protection deidentify template redacts personally identifiable information before return to the user. Data flows from the model output through the Sensitive Data Protection template for redaction or masking and then to the user, so protection holds even if the model is compromised.
Why does VPC Service Controls block access to BigQuery and Cloud Storage AI data even when Identity and Access Management (IAM) allows it?
VPC Service Controls creates a security perimeter around BigQuery and Cloud Storage that denies access even when Identity and Access Management (IAM) allows it, unless the caller satisfies the Access Context Manager access level. Identity and Access Management proves who the caller is, while Access Context Manager proves whether the caller context is allowed to cross the perimeter boundary, so a request must satisfy both checks on every request that touches data inside the perimeter.
Sample Question
A financial enterprise is deploying a customer-facing conversational application powered by foundation large language models (LLMs) on Google Cloud. During security assessments, red-team testers successfully executed sophisticated prompt injection and jailbreaking attacks that bypassed standard system prompts and caused the model to exhibit unintended behaviors.
The enterprise has the following operational requirements:
- Defend the generative AI workload against adversarial prompt injections and jailbreak attempts
- Inspect user prompts and model responses to prevent sensitive data leakage
- Enforce customizable content moderation to block prohibited content harms
Which security capability should the cloud architect implement to meet these requirements?
How learners score on this domain
Last updated