Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
MIG Autoscaler Selects Largest Signal Recommendation
Free sample question, answered and explained below. The Professional Cloud Architect practice bank has 2,335 more like it. Try 10 free: instant score, no account.
An enterprise runs a batch and transaction processing workload on a Compute Engine regional Managed Instance Group (MIG). The workload faces diverse bottlenecks depending on customer behavior:
- Sudden surges in incoming HTTP requests require rapid scaling based on CPU utilization.
- Periodic asynchronous processing requires scaling based on a Cloud Monitoring custom metric tracking message backlog depth.
- A recurring morning traffic surge requires pre-provisioning capacity via scaling schedules.
You need to configure an autoscaling policy that combines these signals to ensure the application maintains high performance without dropping requests.
How does the Compute Engine autoscaler evaluate these multiple signals to determine the target size of the MIG?
Explanations
The autoscaler sums together the recommended instance counts calculated for each individual signal up to the configured maximum number of replicas.
The autoscaler sums together the recommended instance counts calculated for each individual signal up to the configured maximum number of replicas.
What Additive Metric Aggregation Is
Additive metric aggregation assumes that each autoscaling metric operates as an incremental delta, adding its required VM count to the counts requested by all other signals (for example, 10 VMs for CPU + 15 VMs for Queue Depth + 10 VMs for Schedule = 35 VMs).
Why It Doesn't Meet the Requirement
Compute Engine autoscaling does not sum recommended counts together:
- Excessive over-provisioning: In cloud environments, the same VM instance handles both HTTP traffic and queue processing concurrently. Summing the calculated instances would result in massive over-allocation of compute resources and unnecessary cloud expenditure.
- Independent target sizing: Each signal calculates the total group capacity required to satisfy that specific metric's target utilization level independently.
Key Characteristics and Limitations
- The autoscaler treats each signal's recommendation as an absolute group target size, not an incremental add-on.
- It compares the calculated totals and picks the single maximum value (
max(signal_1, signal_2, ...)).
This Answer Would Be Correct If
Different autoscaling signals were mapped to dedicated, non-overlapping pools of instances within separate specialized instance groups rather than a single unified MIG.
The autoscaler calculates the recommended number of VM instances independently for each signal and provisions the largest resulting instance count.
The autoscaler calculates the recommended number of VM instances independently for each signal and provisions the largest resulting instance count.
What Managed Instance Group Multi-Signal Autoscaling Is
Compute Engine autoscaling allows a Managed Instance Group (MIG) to automatically adjust its number of virtual machine instances according to changing workload demands. When an autoscaling policy is configured with multiple signals—such as CPU utilization, Cloud Monitoring custom metrics, load balancing serving capacity, and scaling schedules—the autoscaler independently evaluates the required capacity for every single signal during each collection cycle.
How It Meets the Workload Requirements
In this scenario, the workload has multiple independent bottlenecks:
- CPU spikes: The autoscaler calculates the VM count required to keep average CPU utilization at or below the target threshold.
- Queue backlog: The autoscaler calculates the VM count necessary to process custom Cloud Monitoring queue depth metrics.
- Scheduled morning spikes: The scaling schedule defines a minimum required replica count for specific time windows.
By taking the maximum (largest number of VMs) among all individual recommendations, the autoscaler guarantees that whichever bottleneck or schedule demands the most capacity is fully satisfied, preventing performance degradation or request drops.
MIG Multi-Signal Autoscaling: Max Wins
Process Flow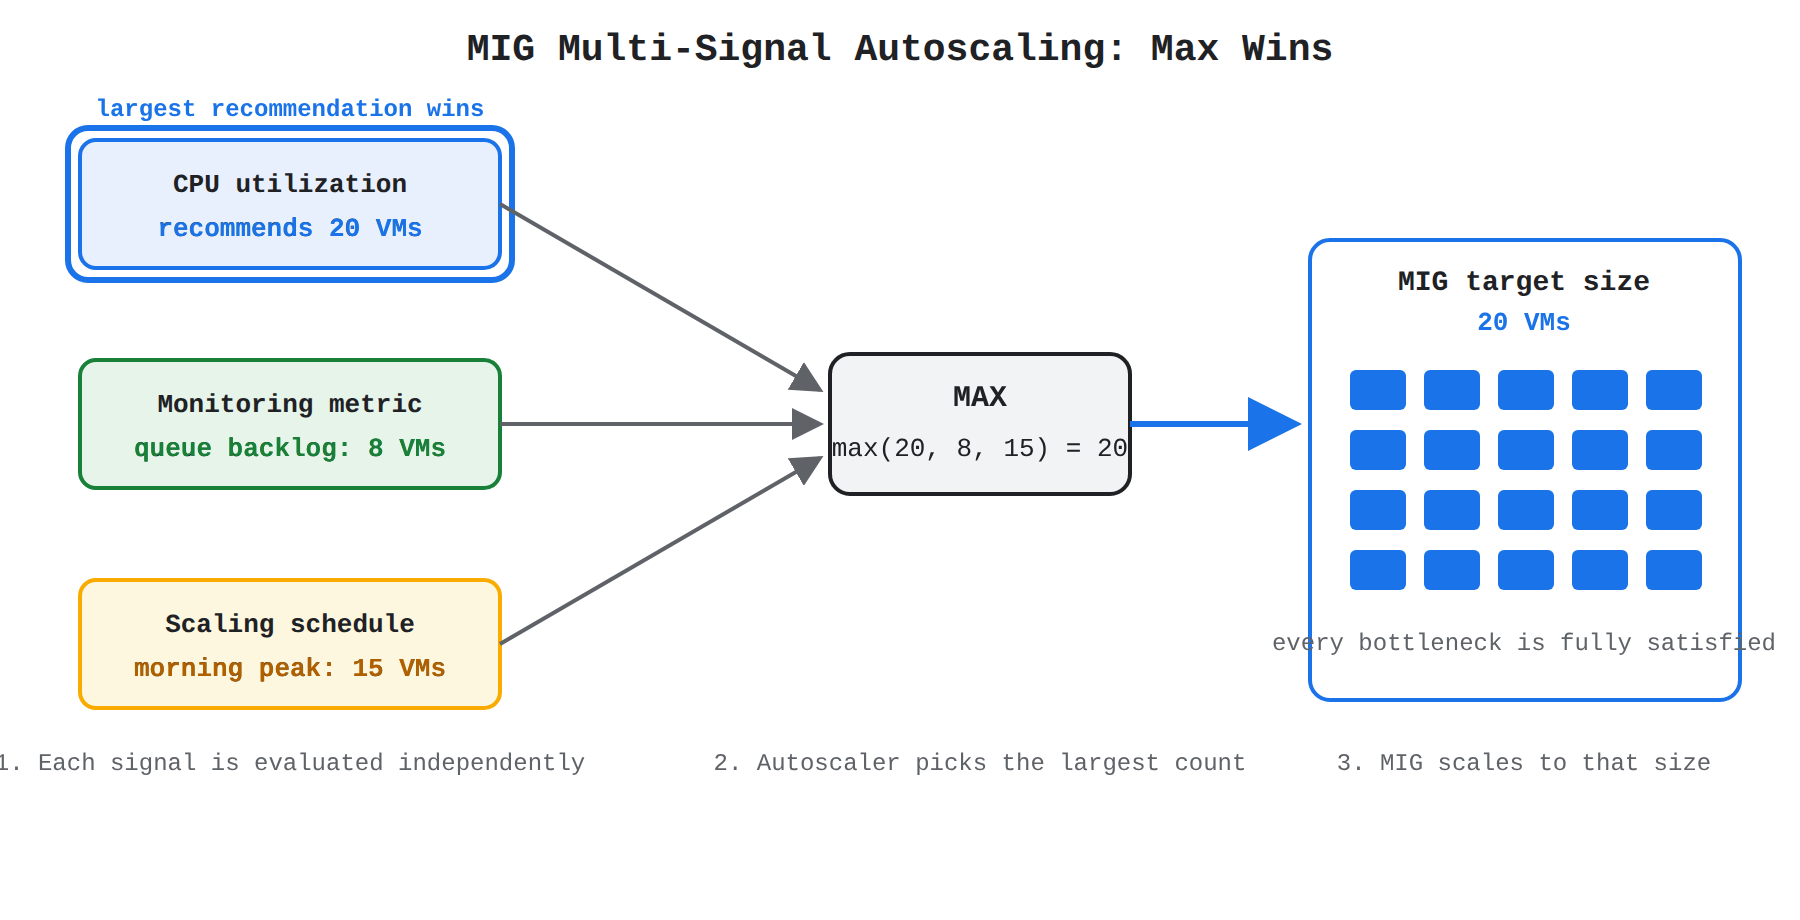
Key Advantages and Capabilities
- Bottleneck resilience: Protects workloads against multi-dimensional bottlenecks where memory, CPU, or message queue depth might independently spike at different times.
- Signal diversity: Supports up to 1 CPU utilization signal, 1 load balancing serving capacity signal, up to 5 Cloud Monitoring custom metrics, and up to 128 scaling schedules per MIG.
- Bounded elasticity: Respects configured
minNumReplicasandmaxNumReplicasbounds across all combined evaluations. - Predictive & proactive scaling: Combines reactive real-time signals with proactive scheduled capacity.
Why This Is Optimal
Picking the largest recommended instance count ensures high availability and eliminates under-provisioning. If one metric demands 20 VMs due to high CPU while a queue metric only requires 8 VMs, scaling to 20 VMs ensures the CPU-bound requests do not fail.
The autoscaler evaluates signals by strict priority hierarchy, where scaling schedules override Cloud Monitoring metrics, which in turn override CPU utilization.
The autoscaler evaluates signals by strict priority hierarchy, where scaling schedules override Cloud Monitoring metrics, which in turn override CPU utilization.
What Hierarchical Signal Precedence Is
Hierarchical signal evaluation implies a strict rule-based priority order where higher-tier triggers completely mask or disable lower-tier metric signals when active.
Why It Doesn't Meet the Requirement
Compute Engine autoscaling does not use a strict hierarchy where schedules or custom metrics suppress CPU utilization:
- No metric suppression: Scaling schedules define a minimum baseline capacity (
minRequiredReplicas) during their active duration. If real-time demand (e.g., CPU utilization) spikes beyond what the schedule provided, the autoscaler dynamically scales out further to meet the higher load. - Parallel evaluation: All configured signals are continuously computed in parallel rather than sequentially evaluated in a fixed precedence chain.
Key Characteristics and Limitations
- Scaling schedules act as scheduled floors, not ceilings that block reactive metrics.
- CPU utilization and Cloud Monitoring metrics are evaluated simultaneously alongside schedules.
This Answer Would Be Correct If
Google Cloud autoscaling operated under an exclusive override model where scheduled events locked the instance group to an immutable static size and ignored live telemetry.
The autoscaler calculates the arithmetic average across all recommended instance counts from the configured signals to smooth out sudden scaling fluctuations.
The autoscaler calculates the arithmetic average across all recommended instance counts from the configured signals to smooth out sudden scaling fluctuations.
What Averaging Scaling Signals Represents
Calculating an arithmetic average across multiple scaling signals is a conceptual method sometimes considered in custom mathematical models to smooth out short-term variance. In this hypothetical approach, if CPU utilization recommends 30 VMs and a custom queue metric recommends 10 VMs, the system would provision the average of 20 VMs.
Why It Doesn't Meet the Requirement
Google Cloud Compute Engine autoscalers do not average instance recommendations across different signal types:
- Risk of severe under-provisioning: If the autoscaler averaged signals, an intensive CPU spike demanding 40 instances combined with a quiet message queue recommending 2 instances would provision only 21 instances, causing CPU starvation and potential service outage.
- Architectural violation: The MIG autoscaler design prioritizes workload sufficiency by selecting the maximum required instance count rather than an average.
Key Characteristics and Limitations
- Averaging is not a supported aggregation method across multiple metrics in Compute Engine autoscaler policies.
- Sudden scaling fluctuations are instead mitigated using scale-in controls (
scaleInControl) and initialization periods (coolDownPeriodSec), not metric averaging.
This Answer Would Be Correct If
A custom external scaling script explicitly implemented a custom smoothing algorithm across metrics before calling the MIG API resize command, but this is neither built-in nor recommended for production SLA-backed services.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,335 practice questions across all 6 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
IntermediateProfessional Cloud Architect
Cloud Spanner Multi-Region Horizontal Scaling
Scalability to meet growth requirements
IntermediateProfessional Cloud Architect
Global External Application Load Balancer Premium Tier
Scalability to meet growth requirements
IntermediateProfessional Cloud Architect
BigQuery Partition Expiration
Data retention and data lifecycle management
IntermediateProfessional Cloud Architect
Model Garden Tiered Model Selection
Google Cloud AI and machine learning solutions (e.g., Gemini LLMs, Agent Builder, Model Garden, Gemini models, and AI Hypercomputer)
IntermediateProfessional Cloud Architect
Predictive Autoscaling
Familiarity with the Google Cloud Well-Architected Framework
FundamentalAssociate Data Practitioner
Cloud Composer
Select a data orchestration solution (e.g., Cloud Composer, scheduled queries, Dataproc Workflow Templates, Workflows) based on business requirements
Last updated