Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Choosing Cloud Run, Functions and GKE by Workload
Free sample question, answered and explained below. The Professional Cloud Architect practice bank has 2,335 more like it. Try 10 free: instant score, no account.
An enterprise is migrating multiple backend workloads to Google Cloud and must map each workload to the optimal compute service based on operational overhead, scaling characteristics, and architectural dependencies:
- Workload 1: A containerized stateless web API that receives fluctuating HTTP(S) request traffic, requires rapid automatic scaling (including scaling to zero when idle), and must minimize cluster management overhead.
- Workload 2: A lightweight, single-purpose event handler that executes short-lived business logic asynchronously whenever new files are uploaded to a Cloud Storage bucket.
- Workload 3: A complex distributed application that requires deployment via Helm, interacts directly with Kubernetes Custom Resource Definitions (CRDs), and enforces fine-grained multi-tenant isolation using Kubernetes Role-Based Access Control (RBAC).
Which compute mapping should you recommend?
Explanations
Workload 1: Compute Engine Managed Instance Groups (MIGs); Workload 2: Cloud Run functions; Workload 3: Cloud Run
Workload 1: Compute Engine Managed Instance Groups (MIGs); Workload 2: Cloud Run functions; Workload 3: Cloud Run
What This Architecture Does
This option deploys the containerized web API onto Compute Engine Managed Instance Groups (MIGs), processes file uploads via Cloud Run functions, and hosts the multi-tenant application on Cloud Run.
Why It Doesn't Meet the Requirements
- Management Overhead for Workload 1: Compute Engine MIGs require administrators to manage base VM images, OS patches, instance templates, health check autohealing configurations, and scaling policies. This fails the requirement for low operational overhead and rapid scale-to-zero container request handling.
- Missing Kubernetes Capabilities for Workload 3: Workload 3 specifically requires Kubernetes Custom Resource Definitions (CRDs), Helm packaging, and Kubernetes RBAC. Cloud Run does not support these Kubernetes-native orchestration features.
Key Characteristics and Limitations
- Compute Engine MIG Autoscaling: Autoscaling VM instances takes minutes due to OS boot times, whereas serverless container platforms scale in seconds.
- Cloud Run Runtime Abstraction: Designed for stateless container execution, Cloud Run intentionally abstracts the underlying control plane, making it incompatible with applications that need to manipulate Kubernetes API objects.
This Answer Would Be Correct If
Workload 1 required direct physical hardware or sole-tenant VM isolation with custom kernel configurations, and Workload 3 had no dependencies on Kubernetes orchestration tooling or RBAC.
Workload 1: Cloud Run; Workload 2: Cloud Run functions; Workload 3: Google Kubernetes Engine (GKE)
Workload 1: Cloud Run; Workload 2: Cloud Run functions; Workload 3: Google Kubernetes Engine (GKE)
What the Recommended Services Are
This architecture correctly maps each application archetype to its optimal Google Cloud runtime: Cloud Run for managed containerized request serving, Cloud Run functions for lightweight event-driven executions, and Google Kubernetes Engine (GKE) for complex container orchestration.
How It Meets Each Requirement
- Workload 1 (Stateless Web API): Cloud Run provides a fully managed, serverless platform that automatically scales container instances up or down to zero based on incoming HTTP(S) request traffic. It abstracts cluster management and infrastructure provisioning, satisfying the requirement for minimal operational overhead.
- Workload 2 (File Processing Trigger): Cloud Run functions (formerly Cloud Functions) offer an event-driven serverless compute model ideal for executing lightweight code in response to asynchronous Cloud Storage events (such as object creation) without running a persistent web service.
- Workload 3 (Complex Multi-Tenant Application): Google Kubernetes Engine (GKE) natively supports Kubernetes APIs, Helm packaging, Custom Resource Definitions (CRDs), and native Kubernetes Role-Based Access Control (RBAC) for fine-grained multi-tenancy.
Key Advantages and Capabilities
- Serverless Request Autoscaling: Cloud Run manages concurrency, load balancing, and rapid scale-to-zero without manual node provisioning.
- Seamless Event-Driven Invocations: Cloud Run functions automatically handle event consumption from Cloud Storage and Eventarc without dedicated polling infrastructure.
- Extensible Container Orchestration: GKE delivers comprehensive support for open-source Kubernetes tooling, custom controllers, and advanced scheduling primitives.
- Optimized Operational Balance: Balances fully managed operational simplicity for standard web and event workloads with deep infrastructure configurability where Kubernetes APIs are strictly required.
Why This Is Optimal
Choosing Cloud Run and Cloud Run functions eliminates cluster maintenance and operational overhead for standard HTTP endpoints and event handlers, while reserving GKE for workloads that have explicit dependencies on Kubernetes ecosystem APIs and RBAC multi-tenancy.
Workload to Compute Decision Tree
Decision Tree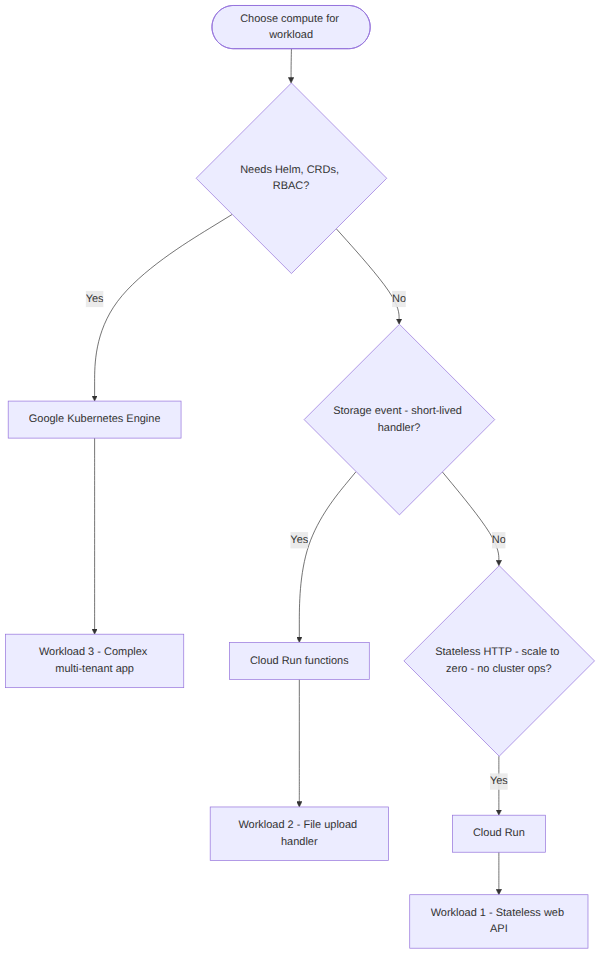
Workload 1: Cloud Run functions; Workload 2: Google Kubernetes Engine (GKE); Workload 3: Cloud Run
Workload 1: Cloud Run functions; Workload 2: Google Kubernetes Engine (GKE); Workload 3: Cloud Run
What This Architecture Does
This option places the high-traffic containerized web API on Cloud Run functions, handles Cloud Storage upload events using Google Kubernetes Engine (GKE), and hosts the complex Kubernetes application on Cloud Run.
Why It Doesn't Meet the Requirements
- Incompatible Platform for Workload 3: Cloud Run does not expose the Kubernetes API, does not support Kubernetes Custom Resource Definitions (CRDs), cannot be deployed using standard Helm release workflows directly against a cluster control plane, and does not support Kubernetes RBAC.
- Disproportionate Complexity for Workload 2: Running a dedicated GKE cluster solely to listen to occasional asynchronous Cloud Storage events adds massive operational overhead, complex event routing, and idle infrastructure costs.
- Suboptimal Model for Workload 1: While Cloud Run functions can serve HTTP requests, full containerized web APIs with existing Dockerfiles and high-concurrency request routing are better matched to the deployment and configuration capabilities of Cloud Run.
Key Characteristics and Limitations
- Cloud Run Limitations: Cloud Run is an abstracted container runtime; it intentionally hides cluster-level Kubernetes APIs and does not support native Kubernetes CRDs or RBAC.
- GKE Resource Waste: Maintaining persistent node pools for simple, bursty event handlers creates unnecessary financial and operational overhead.
This Answer Would Be Correct If
Workload 1 was a simple isolated function snippet, Workload 2 required continuous local high-performance storage and specialized daemon pods, and Workload 3 was a basic request-driven microservice without Kubernetes API dependencies.
Workload 1: Google Kubernetes Engine (GKE); Workload 2: Cloud Run; Workload 3: Compute Engine Managed Instance Groups (MIGs)
Workload 1: Google Kubernetes Engine (GKE); Workload 2: Cloud Run; Workload 3: Compute Engine Managed Instance Groups (MIGs)
What This Architecture Does
This option deploys the stateless HTTP API on a Google Kubernetes Engine (GKE) cluster, executes event-driven file tasks on Cloud Run, and runs the complex Kubernetes-dependent service on Compute Engine Managed Instance Groups (MIGs).
Why It Doesn't Meet the Requirements
- Excessive Overhead for Workload 1: Using GKE for a standard stateless web API introduces unnecessary cluster management overhead (e.g., node provisioning, cluster upgrades, ingress controller maintenance) when Cloud Run can handle containerized HTTP scaling natively with zero infrastructure management.
- Architectural Incompatibility for Workload 3: Compute Engine Managed Instance Groups manage virtual machine instances at the OS level. They do not provide native Kubernetes APIs, Helm chart deployments, Custom Resource Definitions (CRDs), or Kubernetes RBAC multi-tenancy primitives required by Workload 3.
Key Characteristics and Limitations
- Compute Engine MIGs: Ideal for VM-based horizontal scaling and OS-level customizations, but cannot execute Kubernetes-native control plane features or CRDs.
- GKE Overhead: Requires ongoing operational configuration, cluster sizing, and workload lifecycle management.
This Answer Would Be Correct If
Workload 1 required custom kernel extensions or specific network protocols unsupported by serverless platforms, and Workload 3 consisted of legacy monolithic applications distributed across traditional virtual machines.
Additional Context
Attempting to deploy Kubernetes-dependent workloads that rely on CRDs onto Compute Engine MIGs requires building and managing an entire self-hosted Kubernetes cluster from scratch on VMs, adding extreme operational burden.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,335 practice questions across all 6 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
IntermediateProfessional Cloud Architect
Cloud Run CPU Allocation and Startup CPU Boost
Mapping compute needs to platform products (e.g., Google Kubernetes Engine [GKE], Cloud Run, and Cloud Run functions)
IntermediateProfessional Cloud Architect
Cloud Run vs GKE Standard
Mapping compute needs to platform products (e.g., Google Kubernetes Engine [GKE], Cloud Run, and Cloud Run functions)
IntermediateProfessional Cloud Architect
Gemini Cloud Assist Application Design Center Architecture Optimization
Gemini Cloud Assist
IntermediateProfessional Cloud Architect
Cloud Logging, Cloud Trace, and Error Reporting
Troubleshooting/root cause analysis best practices
IntermediateProfessional Cloud Architect
Workload Identity Federation Best Practices
Familiarity with the Google Cloud Well-Architected Framework
AdvancedProfessional Cloud DevOps Engineer
Cloud Build Terraform Ephemeral Environments
Managing ephemeral environments
Last updated