Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Automatic Lineage Tracking in Vertex AI Pipelines
Free sample question, answered and explained below. The Professional Cloud Architect practice bank has 2,335 more like it. Try 10 free: instant score, no account.
A machine learning engineering team at a financial institution needs to build a scalable and auditable machine learning workflow on Google Cloud. The architecture must satisfy several key operational requirements:
- Standardize the end-to-end lifecycle—from data ingestion and preprocessing to model training, evaluation, and endpoint deployment—using modular, reusable components.
- Automatically track execution history, hyperparameters, and full artifact lineage (datasets, metrics, and model binaries) to ensure end-to-end reproducibility and compliance auditability.
- Minimize infrastructure management overhead by orchestrating the workflow using a serverless execution platform.
Which architectural approach should the team implement?
Explanations
Package each pipeline step as an independent Cloud Run microservice, orchestrate step execution with Cloud Composer, and write pipeline parameters and artifact paths directly to BigQuery tables.
Package each pipeline step as an independent Cloud Run microservice, orchestrate step execution with Cloud Composer, and write pipeline parameters and artifact paths directly to BigQuery tables.
What this option is and does
This option builds custom REST microservices on Cloud Run for each ML step and manages their execution order using an Apache Airflow environment managed by Cloud Composer, storing execution logs and artifact metadata manually inside BigQuery tables.
Why it doesn't meet the requirement
- Lack of automatic ML lineage tracking: Cloud Composer and BigQuery do not natively understand ML artifact contracts (e.g., Datasets, Models, Metrics). Engineers would have to manually code and maintain metadata logging routines, introducing substantial operational burden and potential gaps in auditability.
- Infrastructure management overhead: Cloud Composer provisions dedicated GKE clusters and Airflow worker nodes that run continuously, increasing infrastructure management and cost compared to serverless execution.
- Non-standard ML component interface: Building custom HTTP microservices in Cloud Run requires custom scaffolding for passing large ML artifacts and parameters rather than utilizing established ML component SDKs.
Key characteristics and limitations
- Manual metadata tracking: Requires bespoke data modeling and instrumentation for tracking DAG lineage.
- Resource constraints: Cloud Run is optimized for stateless request handling and has specific request timeout and compute limits that are unsuitable for long-running, heavy ML training jobs.
- High maintenance: Requires managing container networking, API contracts, and persistent orchestration infrastructure.
This answer would be correct if
The organization were orchestrating generic, short-duration enterprise ETL tasks across existing internal microservices rather than an end-to-end ML lifecycle needing native ML metadata tracking.
Execute individual training and deployment tasks on Compute Engine virtual machines managed by cron jobs, and register model versions and metadata in Dataproc Metastore.
Execute individual training and deployment tasks on Compute Engine virtual machines managed by cron jobs, and register model versions and metadata in Dataproc Metastore.
What this option is and does
This option provisions standalone Compute Engine virtual machines to run training scripts scheduled via cron utilities and attempts to register model artifacts and pipeline metadata within Dataproc Metastore.
Why it doesn't meet the requirement
- Incorrect tool for ML metadata: Dataproc Metastore is a fully managed Apache Hive metastore service designed for big data ecosystems (like Apache Spark, Hive, and Presto) to track relational table schemas and partitions; it is not designed to track ML model artifact lineage, parameters, or training runs.
- Fragile orchestration: Scheduling disparate VM tasks via cron lacks dependency management, automatic retries, parameter passing, and dynamic graph generation needed for robust ML workflows.
- High operational overhead: Requires provisioning, configuring, and managing static compute instances and custom scripts.
Key characteristics and limitations
- No DAG orchestration: Cron jobs cannot dynamically handle conditional execution or complex dependencies between data ingestion, training, and deployment steps.
- Big data focus: Dataproc Metastore manages Hive table schemas, not ML execution metadata or model lineages.
- Manual error recovery: Lacks native monitoring, visualization, and automated recovery for failed pipeline steps.
This answer would be correct if
The goal was to manage table definitions, partitions, and schemas for an Apache Spark or Hive data processing warehouse on Google Cloud.
Deploy a self-managed Kubeflow cluster on Google Kubernetes Engine (GKE), deploy pipelines via the Kubeflow UI, and maintain an external Cloud SQL database for intermediate container state logging.
Deploy a self-managed Kubeflow cluster on Google Kubernetes Engine (GKE), deploy pipelines via the Kubeflow UI, and maintain an external Cloud SQL database for intermediate container state logging.
What this option is and does
This option entails provisioning and administering an open-source Kubeflow installation hosted directly on a Google Kubernetes Engine (GKE) cluster, backed by a managed Cloud SQL database instance to store application states and execution logs.
Why it doesn't meet the requirement
- Violates serverless requirement: Managing an entire GKE cluster and open-source Kubeflow software stack introduces significant administrative overhead for node pool management, version upgrades, security patching, and cluster scaling.
- Lacks out-of-the-box managed governance: A self-managed Kubeflow deployment does not automatically integrate with managed Google Cloud governance tooling like Vertex ML Metadata without extensive manual configuration and operational maintenance.
Key characteristics and limitations
- Operational complexity: Requires dedicated Kubernetes administrators to maintain the cluster, control plane, storage volumes, and network ingress.
- Cost inefficiency: Idle cluster nodes incur infrastructure costs even when no training pipelines are actively running.
- Manual service integration: Requires manual credential setup and IAM configurations to integrate securely with other Google Cloud managed services.
This answer would be correct if
The business required direct low-level control over Kubernetes manifests, custom on-premise hybrid cloud portability, or full control of underlying cluster networking and kernel drivers.
Define modular pipeline steps using the Kubeflow Pipelines (KFP) SDK and prebuilt Google Cloud Pipeline Components, compile the workflow definition, and execute it using Vertex AI Pipelines to automatically capture lineage in Vertex ML Metadata.
Define modular pipeline steps using the Kubeflow Pipelines (KFP) SDK and prebuilt Google Cloud Pipeline Components, compile the workflow definition, and execute it using Vertex AI Pipelines to automatically capture lineage in Vertex ML Metadata.
What Vertex AI Pipelines and KFP are
Vertex AI Pipelines is a serverless orchestration service in Google Cloud that automates, monitors, and governs end-to-end machine learning workflows. It supports domain-specific language (DSL) frameworks such as the Kubeflow Pipelines (KFP) SDK and TensorFlow Extended (TFX). Developers can construct modular components as standalone containerized steps or lightweight Python functions, which are compiled into a unified pipeline specification.
How it meets the requirements
- Modular, reusable components: The Kubeflow Pipelines SDK and the Google Cloud Pipeline Components library provide standardized, modular factory functions for common ML operations—such as dataset creation, custom or AutoML training, model registry uploads, and endpoint deployments.
- Artifact lineage and auditability: When running on Vertex AI Pipelines, the platform automatically captures all component inputs, outputs, execution states, parameters, and produced artifacts in Vertex ML Metadata without requiring custom tracking scripts.
- Serverless orchestration: Vertex AI Pipelines executes workflow DAGs in a fully managed, serverless environment, eliminating the operational overhead of provisioning, scaling, or patching underlying compute clusters.
Modular ML Pipeline DAG on Vertex AI Pipelines
Process Flow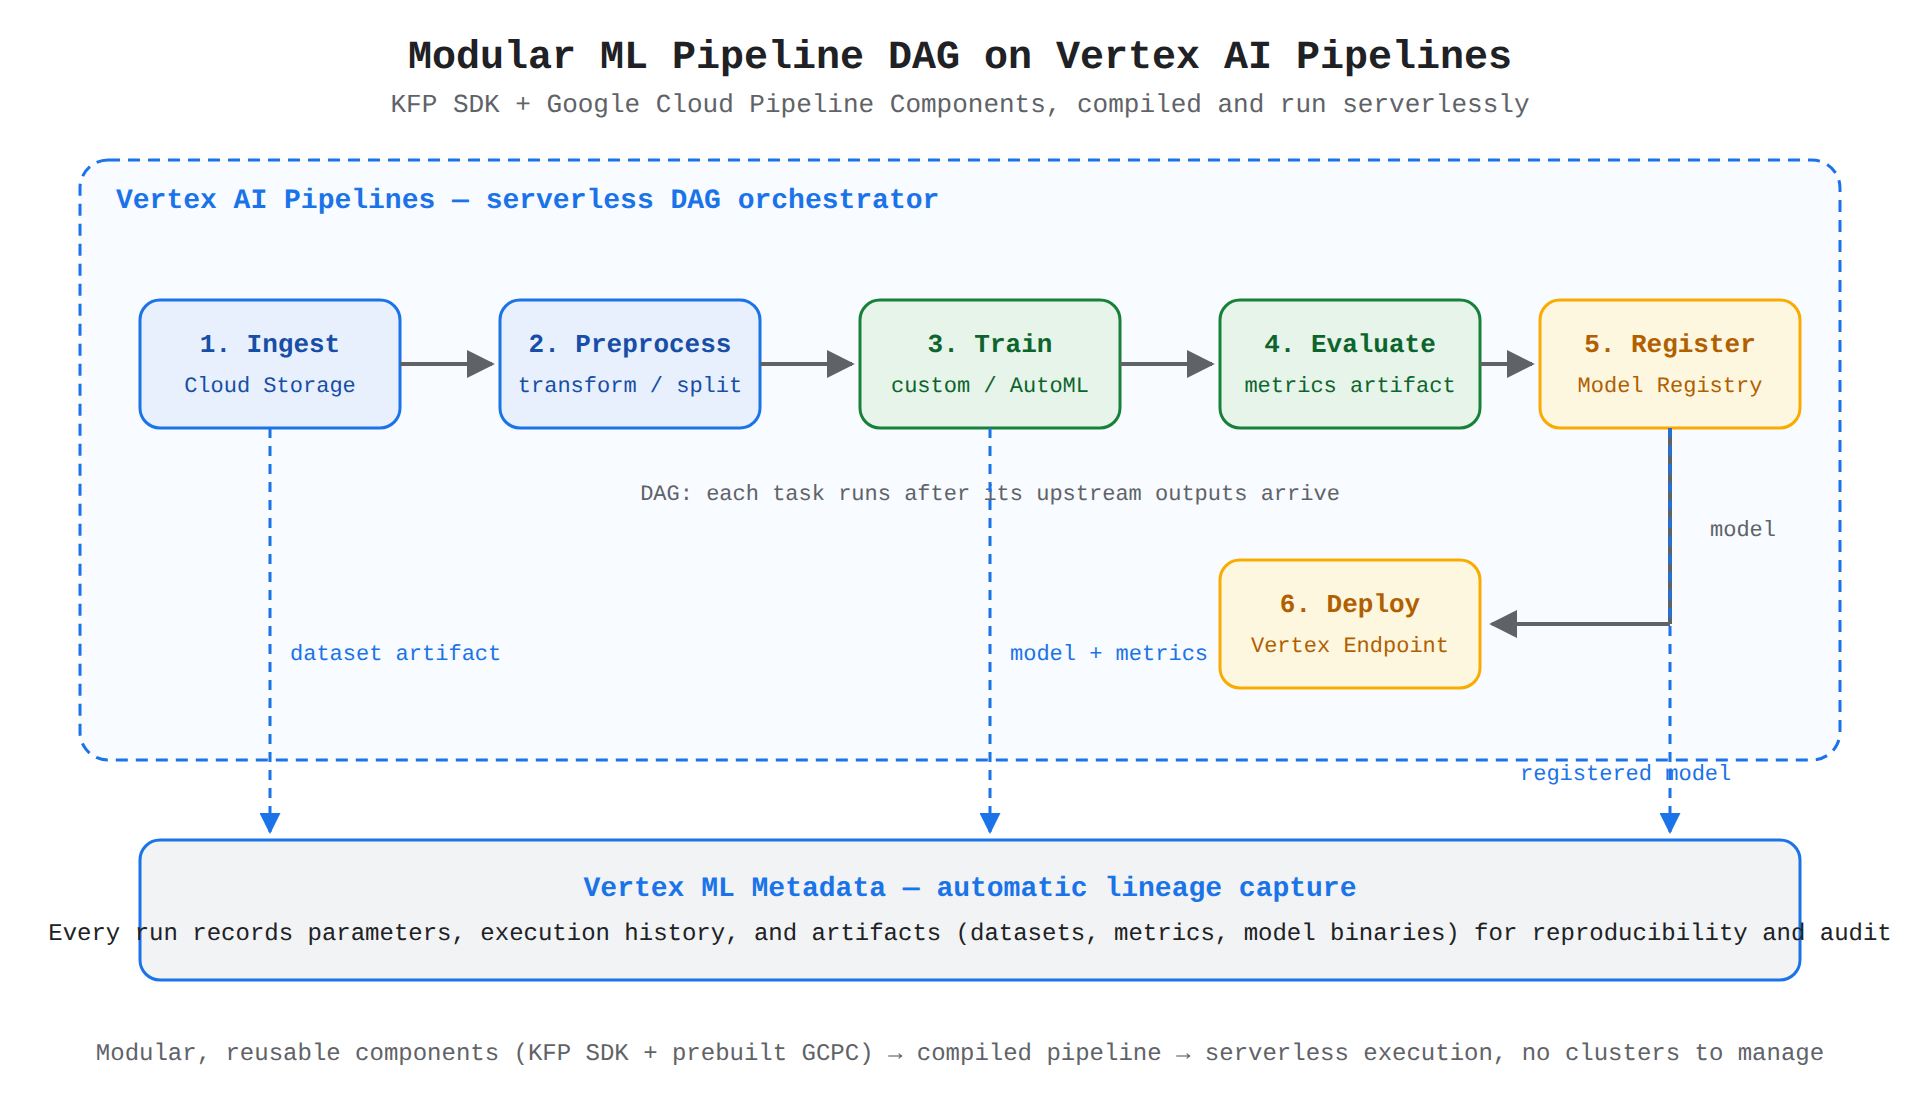
Key advantages and capabilities
- Automatic lineage tracking: Captures complete directed acyclic graph (DAG) execution history and artifact provenance for regulatory auditability.
- Component reusability: Modular components can be shared across multiple team pipelines, accelerating development lifecycles.
- Native Google Cloud integration: Direct integration with services like Cloud Storage, BigQuery, Vertex AI Model Registry, and Vertex AI Endpoints.
- Serverless efficiency: Resources are provisioned dynamically for individual pipeline steps and released immediately upon task completion.
Why this is optimal
This approach directly satisfies all architectural goals by combining the modular authoring model of the KFP SDK with the managed execution and governance features of Vertex AI Pipelines and Vertex ML Metadata.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,335 practice questions across all 6 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
IntermediateProfessional Cloud Architect
Vertex AI Pipelines Service Account and VPC SC
Using Vertex AI pipelines to automate and orchestrate the ML lifecycle
IntermediateProfessional Cloud Architect
Event-Driven Vertex AI Pipeline Triggering
Using Vertex AI pipelines to automate and orchestrate the ML lifecycle
IntermediateProfessional Cloud Architect
API Major Versioning with Path-Based Routing
API management best practices (e.g., Apigee)
IntermediateProfessional Cloud Architect
Sole-Tenant Nodes for BYOL
Determining software license implications and financial impact
IntermediateProfessional Cloud Architect
Workload Validation Protocol
Using migration methodologies, workload testing, network planning, and dependency planning
FundamentalAssociate Data Practitioner
Dataform for BigQuery SQL Transformations
Select a data transformation tool (e.g., Dataproc, Dataflow, Cloud Data Fusion, Cloud Composer, Dataform) based on business requirements
Last updated