Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Using Error Budgets to Balance Velocity and Reliability
Free sample question, answered and explained below. The Professional Cloud Architect practice bank has 2,335 more like it. Try 10 free: instant score, no account.
An enterprise is migrating its core transactional platform to Google Cloud. To meet aggressive release deadlines, the development team has increased deployment frequency, but consecutive unstable releases have caused major service disruptions and completely exhausted the service's monthly error budget.
The operations team wants to halt all cloud migrations and institute mandatory, multi-stakeholder manual change approval gates for every release, while the development team insists on maintaining release velocity.
Which approach aligns with Site Reliability Engineering (SRE) change management principles to resolve this conflict and balance innovation velocity with system stability?
Explanations
Establish a permanent Change Advisory Board (CAB) to manually review and approve every code commit and infrastructure pull request before deployment.
Establish a permanent Change Advisory Board (CAB) to manually review and approve every code commit and infrastructure pull request before deployment.
What a Change Advisory Board (CAB) Review Is
A Change Advisory Board (CAB) is a traditional ITIL governance process where a committee of stakeholders reviews, evaluates, and manually approves proposed changes prior to deployment into production environments.
Why It Doesn't Meet the Requirement
- Slows Velocity Unnecessarily: Introducing a permanent manual approval board drastically reduces software delivery velocity and creates long feedback cycles, directly counteracting cloud-native transformation goals.
- Does Not Fix Underlying Defects: Manual human inspections of code and configuration changes frequently miss syntax issues, runtime regressions, and concurrency problems that automated test suites and canary rollouts catch.
- Undermines SRE Principles: SRE emphasizes automated guardrails, automated canary analysis, and programmatic policy enforcement rather than bureaucratic approval gates.
Key Limitations
- Creates significant deployment bottlenecks and large, batched releases that increase deployment risk.
- Fails to leverage automated CI/CD validation tools, linters, and integration testing frameworks.
- Decreases team agility and slows down the overall migration to Google Cloud.
This Answer Would Be Correct If
The organization were operating under rigid legacy compliance regulations requiring dual-custody human sign-offs on low-frequency, monolithic on-premises systems without CI/CD automation capabilities.
Grant full administrative repository merge permissions and unrestricted production breakglass access to all developers to accelerate unblocked hotfixes.
Grant full administrative repository merge permissions and unrestricted production breakglass access to all developers to accelerate unblocked hotfixes.
What Unrestricted Access and Unmanaged Merging Represents
This approach removes repository branch protections, peer review mechanisms, and least-privilege IAM controls, allowing any individual developer to merge changes and execute emergency changes directly in production.
Why It Doesn't Meet the Requirement
- Increases Production Risk: Bypassing peer reviews, automated CI/CD checks, and access restrictions leads to uncontrolled software supply chain vulnerabilities, configuration drift, and additional outages.
- Violates Zero-Touch Production: Google SRE principles advocate for zero-touch production, where all modifications are deployed through auditable, automated pipelines rather than ad-hoc developer access.
- Misunderstands Breakglass Access: Emergency breakglass accounts must be strictly audited, tightly scoped, and reserved for exceptional disaster recovery scenarios, not used as standard release mechanisms.
Key Characteristics and Vulnerabilities
- Violates security frameworks such as SLSA and least-privilege principles.
- Prevents traceability, auditing, and automated regression testing.
- Fosters chaotic deployments without coordination across cross-functional teams.
This Answer Would Be Correct If
The project were an isolated, non-production sandbox environment with no live users, data, or operational reliability requirements.
Adjust the Service Level Objective (SLO) target to 100% availability and establish individual performance reprimands for developers responsible for failing commits.
Adjust the Service Level Objective (SLO) target to 100% availability and establish individual performance reprimands for developers responsible for failing commits.
What a 100% SLO and Punitive Accountability Represent
A 100% availability SLO assumes that a system should never experience downtime or errors under any circumstances. Combining this with individual reprimands creates a blame-centric culture that punishes engineers for system failures.
Why It Doesn't Meet the Requirement
- Unrealistic Reliability Goal: In cloud environments, 100% availability is fundamentally unachievable due to hardware failures, network partitions, provider updates, and external dependencies. Aiming for 100% halts all feature innovation.
- Destroys Psychological Safety: Assigning personal blame runs completely counter to the SRE concept of blameless post-mortems. When employees fear punishment, they conceal incidents, delay reporting, and avoid making necessary architectural changes.
- Zero Error Budget: A 100% target leaves exactly zero error budget, meaning any single transient failure instantly triggers crisis procedures.
Key Characteristics and Pitfalls
- Causes extreme operational risk aversion, stalling digital transformation.
- Shifts attention away from structural and procedural system improvements toward hiding mistakes.
- Ignores the reality of distributed systems operating on public cloud infrastructure.
This Answer Would Be Correct If
There were safety-critical hard real-time systems where any failure results in loss of life, though even in those cases, blameless culture and systemic failure analysis remain industry standards.
Shift development focus to reliability improvements, technical debt reduction, and automated testing until the error budget recovers, while conducting blameless post-mortems for the outages.
Shift development focus to reliability improvements, technical debt reduction, and automated testing until the error budget recovers, while conducting blameless post-mortems for the outages.
What Error Budget and SRE Change Management Is
In Site Reliability Engineering (SRE), the error budget represents the acceptable level of unreliability that a service can experience within a specific timeframe without violating its Service Level Objective (SLO). It acts as an objective, data-driven governance mechanism that balances product development velocity with infrastructure and service reliability.
How It Resolves the Organizational Conflict
When a service depletes its error budget, the pre-negotiated policy mandates an operational shift: instead of continuing rapid feature launches, the development team redirects engineering effort toward stabilizing the application. Conducting blameless post-mortems ensures that outages are treated as learning opportunities to uncover systemic weaknesses, process gaps, and missing automated guardrails rather than assigning individual fault.
Error Budget Feedback Loop
Process Flow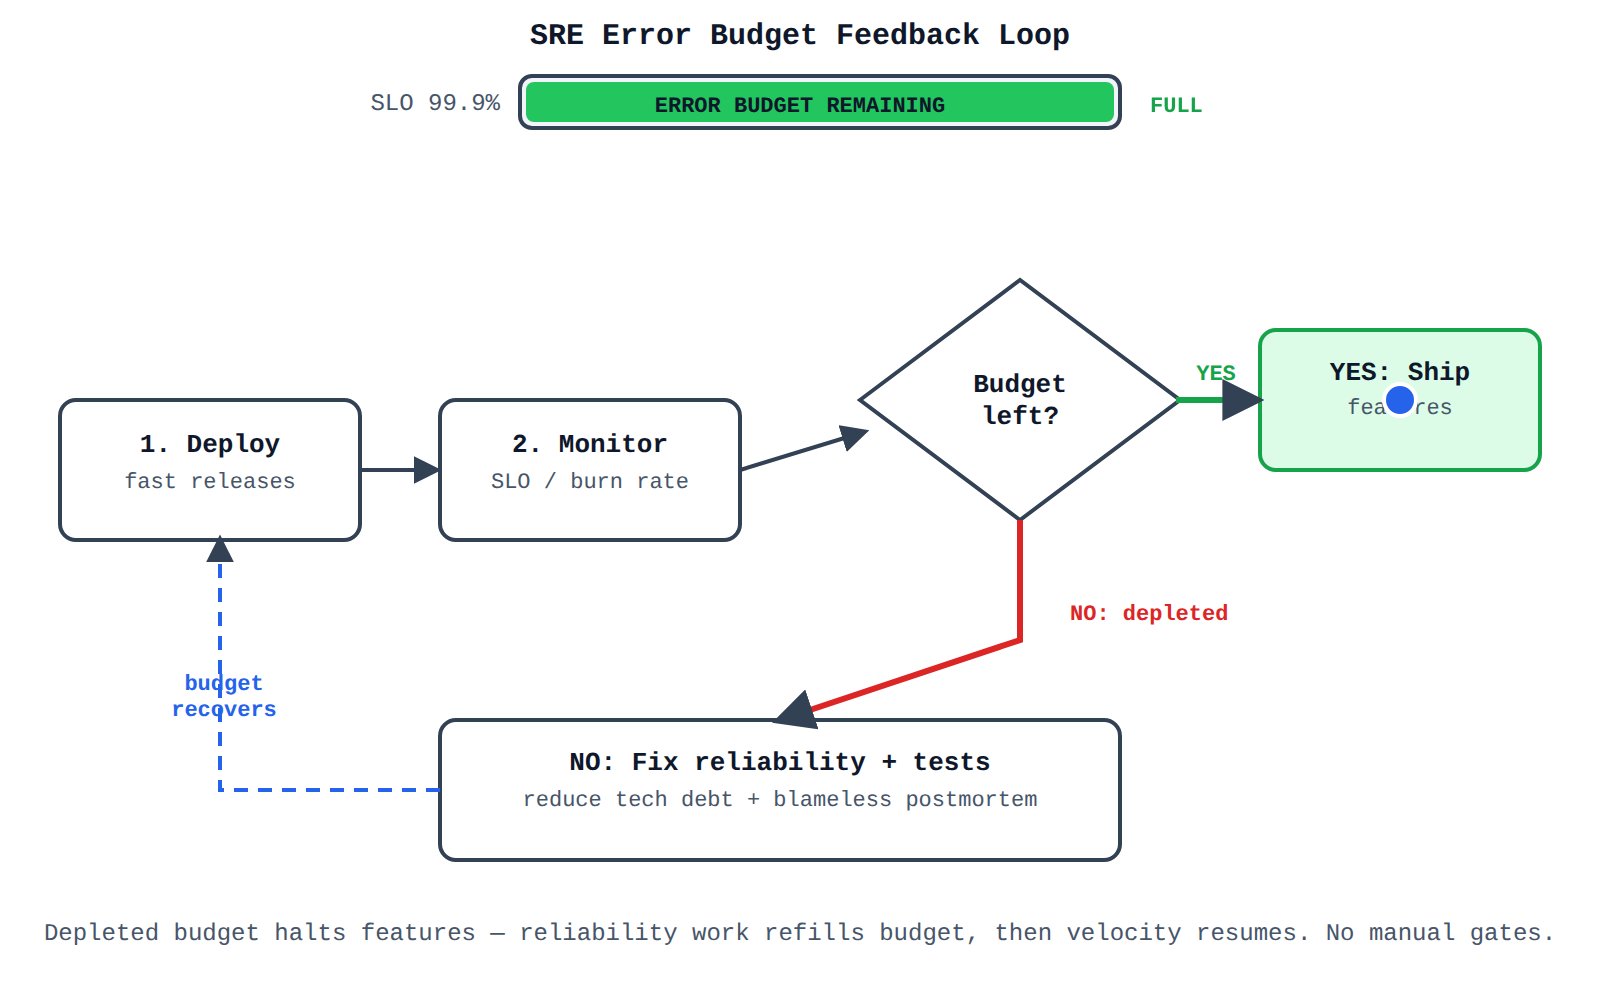
Key Advantages
- Objective Decision-Making: Removes subjective friction and political tension between development and operations teams by relying on shared SLO metrics.
- Continuous Systemic Improvement: Blameless post-mortems generate actionable follow-up items that target root causes such as configuration drift or lack of unit/integration test coverage.
- Self-Healing Culture: Encourages software engineers to design scalable, fault-tolerant cloud architectures and robust CI/CD automated validation pipelines.
- Sustainable Delivery Pace: Protects customer user experience without introducing permanently blocking manual approval bureaucracies.
Why This Is Optimal
This approach directly implements SRE best practices by using the error budget as an automated feedback loop. It guarantees that release velocity is constrained only when reliability falls below agreed thresholds, keeping the organizational transformation focused on automation and measurable quality.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,335 practice questions across all 6 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
IntermediateProfessional Cloud Architect
Least Privilege IAM and GitOps with Break-Glass OU
Change management
IntermediateProfessional Cloud Architect
Cloud Build Emulator Integration Testing
Testing frameworks (load/unit/integration)
IntermediateProfessional Cloud Architect
Custom Machine Types and Spot VMs
Flexibility of cloud resources
IntermediateProfessional Cloud Architect
Spot VMs and Multi-Region Standard Storage
Design decision trade-offs
IntermediateProfessional Cloud Architect
Vertex AI Security Architecture
Securing AI (e.g., Model Armor, Sensitive Data Protection, and secure model deployment)
AdvancedProfessional Cloud DevOps Engineer
GKE HPA VPA Cluster Autoscaler Coexistence
Autoscaling (e.g., managed instance groups, Cloud Run, GKE)
Last updated