Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Proactive GKE Scaling with Scheduled Custom Metrics
Free sample question, answered and explained below. The Professional Cloud Architect practice bank has 2,335 more like it. Try 10 free: instant score, no account.
An online retail company hosts its core ordering service on Google Kubernetes Engine (GKE). The application experiences predictable, massive traffic spikes every morning at the start of business hours, followed by minimal activity overnight.
To ensure responsiveness during the morning rush, the team currently maintains a high static minReplicas value in the Horizontal Pod Autoscaler (HPA) configuration. However, management noticed that this setting prevents the cluster from scaling down during off-peak night hours, resulting in substantial unnecessary infrastructure costs.
You need to design a scaling architecture that handles the predictable morning surges without overpaying for idle capacity overnight.
Which scaling strategy should you implement?
Explanations
Keep the high static HPA minReplicas configuration and set the GKE cluster node pool autoscaler minimum node limit to zero.
Keep the high static HPA minReplicas configuration and set the GKE cluster node pool autoscaler minimum node limit to zero.
What This Option Is
This configuration attempts to rely on the GKE Cluster Autoscaler minimum node setting (min-nodes=0) while leaving the Horizontal Pod Autoscaler (HPA) minReplicas set to a permanently high value.
Why It Doesn't Meet the Requirement
- Cluster Cannot Shrink: The GKE Cluster Autoscaler provisions worker nodes based on the aggregate resource requests of all scheduled Pods. Because
minReplicasenforces a high minimum number of running Pods at all times, the Pods will continually request CPU and memory, preventing the cluster autoscaler from scaling down nodes overnight. - Cost Inefficiency: The cluster remains fully provisioned during overnight off-hours, failing to reduce infrastructure costs.
Key Characteristics and Limitations
- Pod Demand Precedence: Node pools cannot scale below the capacity required to run existing scheduled Pods.
- Static Resource Floor: Setting a high static
minReplicascreates an inflexible lower bound on cluster capacity. - Wasted Capacity: Underutilized Pods sit idle throughout the night while consuming billable Compute Engine resources.
This Answer Would Be Correct If
The workload experienced unpredictable 24/7 traffic at steady rates that required immediate capacity without any tolerance for node spin-up times.
Configure the Vertical Pod Autoscaler (VPA) in Auto mode to increase Pod CPU and memory requests overnight while disabling the Horizontal Pod Autoscaler.
Configure the Vertical Pod Autoscaler (VPA) in Auto mode to increase Pod CPU and memory requests overnight while disabling the Horizontal Pod Autoscaler.
What This Option Is
The Vertical Pod Autoscaler (VPA) adjusts the CPU and memory resource requests and limits of individual containers within Pods rather than changing the total number of Pod replicas.
Why It Doesn't Meet the Requirement
- Misaligned Scaling Direction: VPA performs vertical scaling (resizing containers), which does not solve the challenge of scaling out horizontally to distribute sudden incoming network requests across multiple container instances.
- Disruption During Updates: In
Automode, VPA evicts and restarts Pods to apply updated resource boundaries, which can cause service disruptions during traffic transitions. - Fails Cost Goal: Increasing Pod resource allocations overnight would exacerbate idle resource consumption instead of releasing unused compute capacity.
Key Characteristics and Limitations
- Pod Re-creation Required: Changing container sizes in standard Kubernetes generally requires restarting the Pod.
- HPA Conflict: Running VPA and HPA simultaneously on the same resource metrics (CPU/memory) creates conflicting scaling actions.
- Vertical vs. Horizontal: Optimizes right-sizing for individual workloads rather than elastic elasticity against spiky traffic.
This Answer Would Be Correct If
The goal was to determine optimal baseline resource requests and limits for single-instance, long-running batch applications that run during off-peak hours.
Set the HPA minReplicas to 1 and rely strictly on reactive target CPU utilization thresholds to scale up instances when the morning traffic arrives.
Set the HPA minReplicas to 1 and rely strictly on reactive target CPU utilization thresholds to scale up instances when the morning traffic arrives.
What This Option Is
This approach configures the Horizontal Pod Autoscaler (HPA) with a low minimum replica count (minReplicas: 1) and depends entirely on reactive resource consumption triggers (like reaching 80% target CPU utilization) to scale out the application.
Why It Doesn't Meet the Requirement
- Latency Spikes During Surges: Reactive horizontal autoscaling requires metrics to be collected, threshold evaluations to occur, new Pods to be scheduled, and container runtimes to initialize. Under sudden massive morning spikes, this lag leads to dropped requests, timeouts, and poor user experience.
- Node Provisioning Latency: If new nodes must be added by the Cluster Autoscaler, starting new Compute Engine instances adds further delay before Pods become ready.
Key Characteristics and Limitations
- Reactive Nature: Responds only after resource utilization has already exceeded acceptable thresholds.
- Cold Start Delays: Application startup time and health check verifications delay traffic absorption.
- Insufficient for Predictable Spikes: Poorly suited for known, step-function traffic increases where proactive capacity is necessary.
This Answer Would Be Correct If
Traffic increases were gradual and continuous throughout the day rather than sudden, massive surges at a known start time.
Implement scheduled autoscaling by exporting time-based custom metrics to Cloud Monitoring and configuring the HPA with the Custom Metrics adapter to scale pods proactively before business hours.
Implement scheduled autoscaling by exporting time-based custom metrics to Cloud Monitoring and configuring the HPA with the Custom Metrics adapter to scale pods proactively before business hours.
What Scheduled Autoscaling with Custom Metrics Is
Scheduled autoscaling on Google Kubernetes Engine combines standard Kubernetes autoscaling mechanisms with time-based triggers. Because standard Horizontal Pod Autoscaling (HPA) reacts dynamically to resource metrics like CPU or memory utilization, it can suffer from a slight lag during sudden, sharp traffic surges. By utilizing Cloud Monitoring custom metrics alongside scheduled jobs (such as CronJobs), you can programmatically publish metric values at specific times to scale application replicas up ahead of business hours and down during low-traffic windows.
Scheduled Autoscaling: Scale Up Before the Morning Rush
Timeline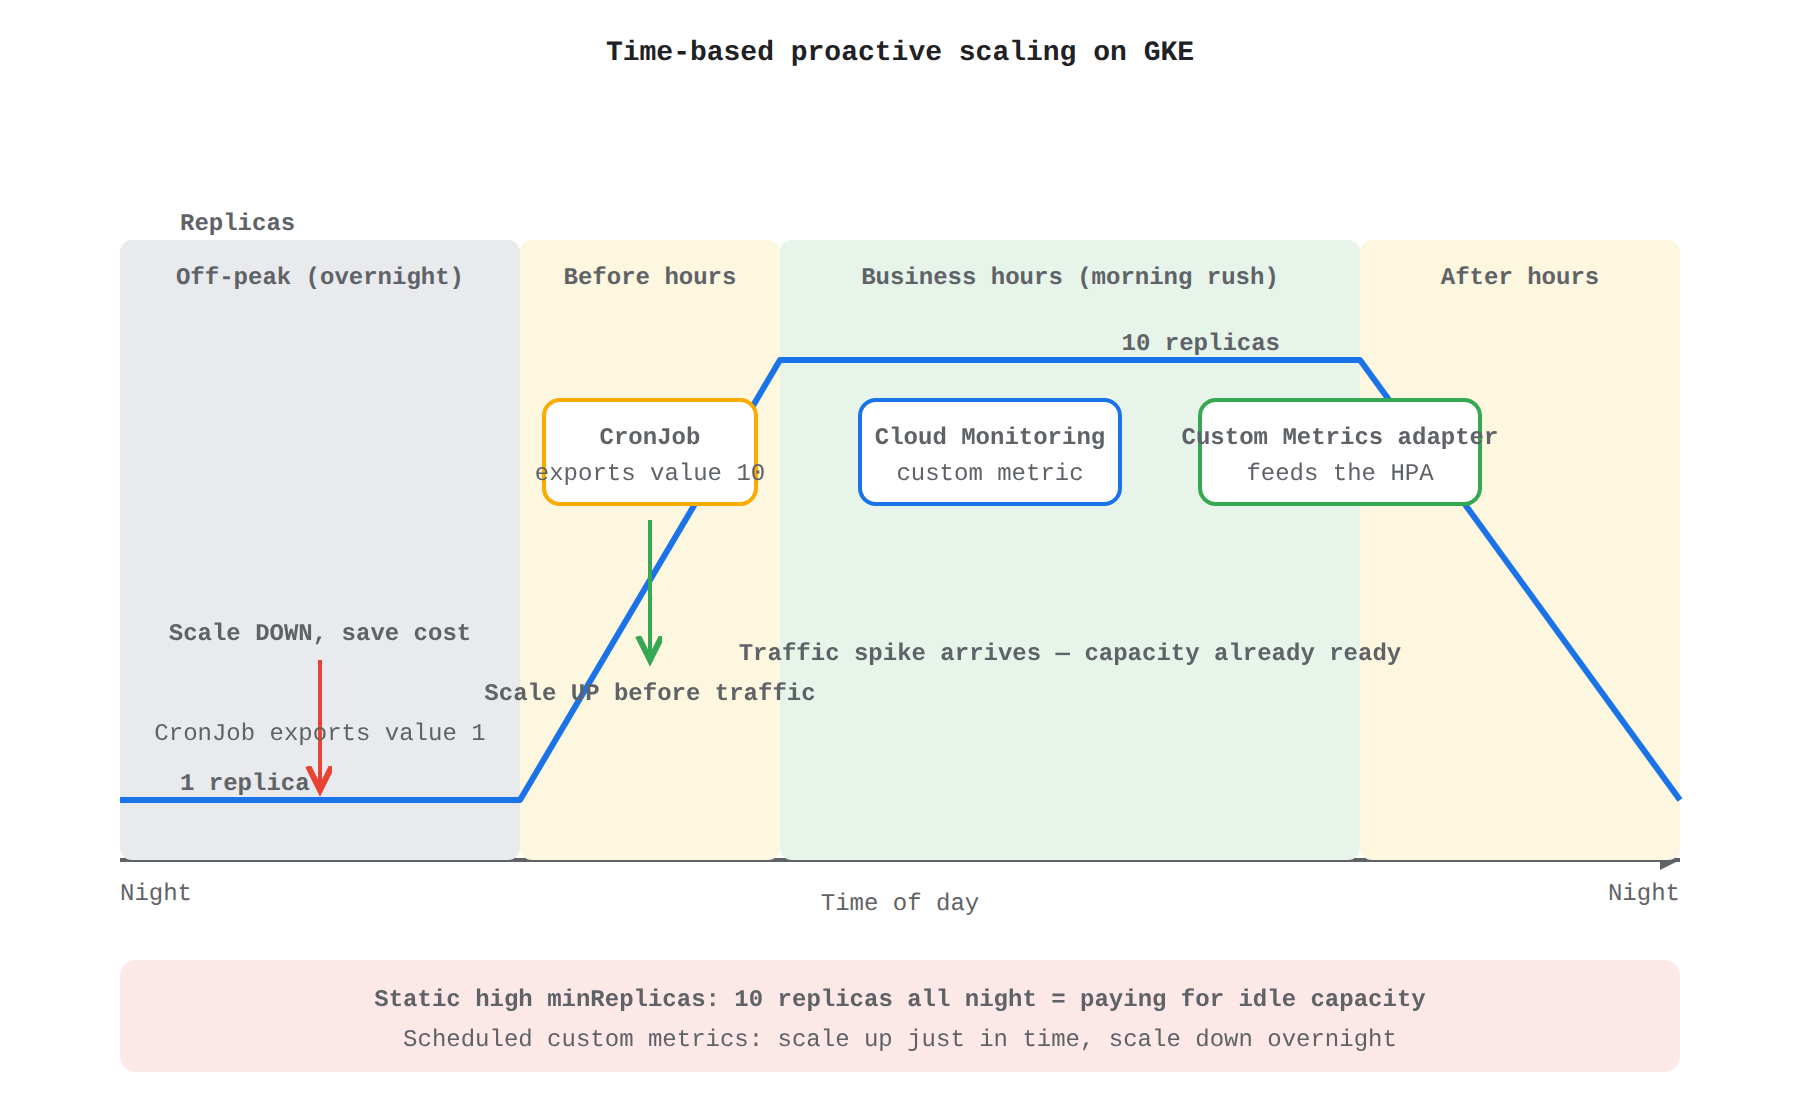
How It Meets the Requirements
- Proactive Scaling for Morning Surges: Scheduled jobs trigger metric increases right before business hours begin, allowing the Custom Metrics - Cloud Monitoring adapter to scale out Pods and nodes proactively before end-user traffic hits.
- Cost Reduction Overnight: When business hours end, scheduled jobs publish lower target values, allowing both the HPA and the underlying GKE Cluster Autoscaler to shrink node pools and release idle resources.
- Automated Operations: The entire workflow is controlled natively within the cluster using Kubernetes manifests without manual daily intervention.
Key Advantages and Capabilities
- Seamless Metric Integration: Connects Kubernetes HPA natively to external Cloud Monitoring time-series data.
- Cost Efficiency: Eliminates the need to maintain an over-provisioned static minimum replica count 24/7.
- Predictable Performance: Prevents application cold-start latencies and request queuing during anticipated traffic spikes.
- Dynamic Infrastructure Alignment: Works hand-in-hand with the GKE Cluster Autoscaler to add and remove VM instances automatically.
Why This Is Optimal
This solution directly balances performance and cost. Rather than keeping expensive infrastructure running all night, scheduled custom metrics anticipate regular traffic spikes while letting standard dynamic scaling handle unexpected daytime fluctuations.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,335 practice questions across all 6 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
IntermediateProfessional Cloud Architect
GKE Enterprise Fleets and Config Sync
Flexibility of cloud resources
IntermediateProfessional Cloud Architect
Custom Machine Types and Spot VMs
Flexibility of cloud resources
IntermediateProfessional Cloud Architect
Active Assist and IAM Recommender
Gemini Cloud Assist
IntermediateProfessional Cloud Architect
Resource-Based CUDs vs Flexible CUDs vs Spot VMs
Cost optimization
IntermediateProfessional Cloud Architect
Cloud Build Provenance with Artifact Analysis
Deployment and release management
AdvancedProfessional Cloud DevOps Engineer
Config Sync Nomos Vet PR Validation
Configuring deployment processes (e.g., approval flows)
Last updated