Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Validating Regional MIG Recovery Against SLOs
Free sample question, answered and explained below. The Professional Cloud Architect practice bank has 2,335 more like it. Try 10 free: instant score, no account.
An e-commerce platform running on Google Cloud uses Regional Managed Instance Groups (MIGs) behind an external Application Load Balancer, with Cloud Monitoring tracking Service Level Indicators (SLIs) against a 99.99% availability Service Level Objective (SLO). The Site Reliability Engineering (SRE) team wants to conduct a chaos engineering experiment in a staging environment that mirrors production to validate that automated recovery mechanisms function properly during infrastructure disruptions without exceeding the allocated error budget.
Which strategy should the team implement to design and validate this failure injection experiment?
Explanations
Establish a steady-state baseline using SLI metrics, inject automated VM terminations and network latency within a single zone under synthetic load, and evaluate whether Regional MIG autohealing and load balancing preserve the SLO within error budget thresholds.
Establish a steady-state baseline using SLI metrics, inject automated VM terminations and network latency within a single zone under synthetic load, and evaluate whether Regional MIG autohealing and load balancing preserve the SLO within error budget thresholds.
What Controlled Chaos Engineering with SRE Principles Is
Chaos engineering is the discipline of experimenting on a system to build confidence in its capability to withstand turbulent conditions in production. Combining chaos engineering with Site Reliability Engineering (SRE) principles involves defining a steady-state baseline using Service Level Indicators (SLIs) and verifying that automated resilience mechanisms operate within the boundaries of the defined Service Level Objectives (SLOs) and error budgets.
How It Meets the Experimentation and Resilience Requirements
- Baseline Verification: Measuring baseline SLIs (e.g., request error rate, latency distribution) establishes the normal steady state before introducing failures.
- Controlled Fault Injection: Intentionally terminating virtual machine instances and injecting simulated network delays within a specific failure domain (a single zone) models realistic cloud infrastructure incidents.
- Validation of Automated Recovery: Evaluates the coordinated action of Cloud Load Balancing health checking and Regional Managed Instance Group (MIG) autohealing to remove unhealthy instances and recreate compute capacity automatically.
- Error Budget Assessment: Quantifies the rate of error budget consumption during the incident to ensure the architecture remains resilient without breaching contractual or operational availability targets.
Regional MIG Autohealing Recovery Flow
Process Flow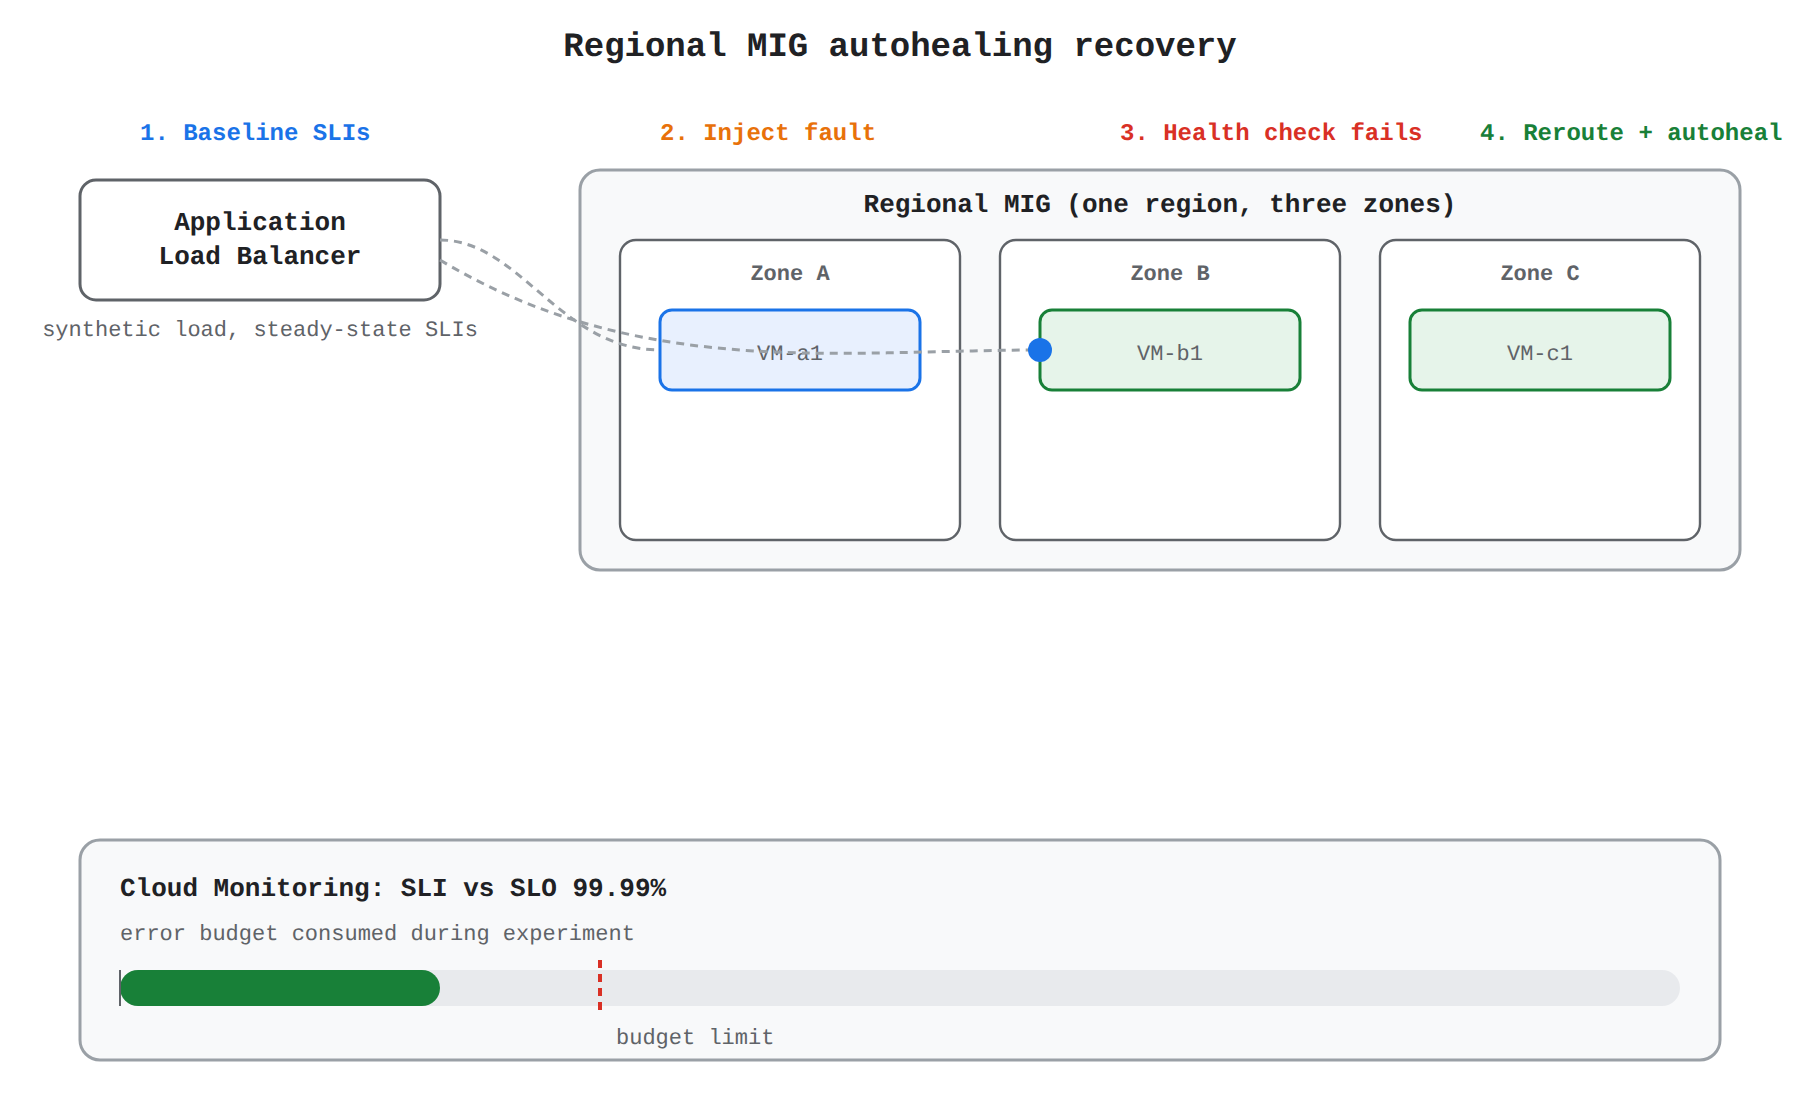
Key Advantages and Capabilities
- Proactive Defect Discovery: Uncovers misconfigured health checks, slow startup scripts, or capacity bottlenecks before they cause customer-impacting outages.
- Blast Radius Containment: Confining the fault injection to a single zone within a regional deployment tests zone independence while maintaining overall platform availability.
- Actionable SRE Insights: Connects recovery behavior directly to quantitative SLO consumption rather than subjective pass/fail criteria.
- Validation of Autoscaling and Autohealing: Confirms that VM recreation policies and traffic rerouting execute without human intervention.
Why This Is Optimal
This method aligns with Google Cloud reliability engineering best practices. It tests the resilience of regional compositions against zonal failure domains, verifies automated platform recovery primitives (MIG autohealing and load balancer failover), and uses empirical SRE metrics to measure overall system health.
Disable health checks on the Application Load Balancer backend service, terminate all virtual machines across all zones simultaneously, and measure the time required for engineers to execute manual disaster recovery runbooks.
Disable health checks on the Application Load Balancer backend service, terminate all virtual machines across all zones simultaneously, and measure the time required for engineers to execute manual disaster recovery runbooks.
What Manual Disaster Recovery Testing with Disabled Health Checks Is
This approach simulates a catastrophic total-system outage by deliberately turning off load balancer health probing and destroying all running VM capacity across every zone, forcing operations teams to perform manual instance recreation and routing.
Why It Doesn't Meet the Requirement
- Bypasses Automated Self-Healing: Disabling load balancer health checks intentionally eliminates the core cloud-native mechanism responsible for detecting faulty instances and rerouting traffic.
- Fails to Evaluate Automated Recovery: Rather than testing automated recovery primitives like Managed Instance Group (MIG) autohealing, this approach tests manual intervention and procedural runbooks.
- Uncontrolled Error Budget Depletion: Terminating all compute instances simultaneously causes complete platform downtime, instantly consuming 100% of the SRE error budget rather than validating that the architecture can absorb faults.
Key Characteristics and Limitations
- Tests human disaster recovery protocols rather than automated architectural resilience.
- Invalidates health-check-driven failover mechanisms in Cloud Load Balancing.
- Represents a destructive disaster recovery drill rather than a controlled, hypothesis-driven chaos experiment.
This Answer Would Be Correct If
This strategy would be appropriate for a manual Disaster Recovery (DR) exercise designed strictly to test operational runbooks and personnel escalation paths in the event of an unrecoverable multi-zone catastrophe where all automated systems have failed.
Increase the target CPU utilization threshold on the Managed Instance Group autoscaler to 100%, disable scale-out actions, and monitor system degradation under unthrottled load.
Increase the target CPU utilization threshold on the Managed Instance Group autoscaler to 100%, disable scale-out actions, and monitor system degradation under unthrottled load.
What Autoscaler Saturation Testing Is
This approach configures the Managed Instance Group autoscaler to an extreme target utilization (100%) and prevents horizontal scaling, allowing incoming traffic to overwhelm compute instances until CPU exhaustion causes request failures.
Why It Doesn't Meet the Requirement
- Focuses on Resource Exhaustion Rather Than Fault Injection: Restricting autoscaling tests system behavior under severe resource starvation, but it does not inject independent infrastructure faults such as VM terminations, host errors, or network latency.
- Disables Core Elasticity Features: Disabling scale-out actions prevents the cloud platform from demonstrating its automated elasticity and capacity management.
- Fails to Validate Multi-Zone Redundancy: It does not evaluate how the platform isolates zonal failures or how the Regional MIG redistributes instance capacity across surviving zones.
Key Characteristics and Limitations
- Measures single-instance saturation limits rather than systemic resilience against unpredictable infrastructure interruptions.
- Produces artificial cascading failures by preventing the infrastructure from reacting dynamically to demand.
- Does not test the integration between health checking, autohealing, and multi-zone failover.
This Answer Would Be Correct If
The objective were stress testing or capacity bottleneck identification to determine the breaking point of an individual VM's web server software under extreme computational load.
Simulate a live migration event on all instances and verify that Compute Engine host maintenance policies restart the virtual machines sequentially without using load balancing.
Simulate a live migration event on all instances and verify that Compute Engine host maintenance policies restart the virtual machines sequentially without using load balancing.
What Live Migration Testing Is
This option involves triggering Google Cloud's native live migration maintenance mechanism to move running VM instances to alternative physical hosts within the same zone without application downtime.
Why It Doesn't Meet the Requirement
- Live Migration Is Non-Disruptive by Design: Live migration is a transparent infrastructure maintenance mechanism designed specifically not to interrupt running VMs or cause failures.
- Fails to Test Failure Injection: Because live migration maintains VM state and uptime transparently, it does not simulate actual system disruptions such as unexpected VM crashes, network degradation, or zonal outages.
- Ignores Load Balancing and Autohealing: Excluding Cloud Load Balancing and autohealing validation leaves the primary mechanisms for handling unplanned outages untested.
Key Characteristics and Limitations
- Live migration moves running VMs across physical hosts without shutting down the guest operating system.
- It is intended for routine host patching and infrastructure maintenance rather than chaos testing.
- Does not consume error budgets or trigger automated healing events because instances remain operational.
This Answer Would Be Correct If
The team wanted to verify that specialized, performance-sensitive workloads do not experience unacceptable CPU jitter during underlying Google Cloud hypervisor maintenance.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,335 practice questions across all 6 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
IntermediateProfessional Cloud Architect
Distributed Cloud Load Testing Duration
Ensuring the reliability of solutions in production (e.g., chaos engineering, penetration testing, and load testing)
IntermediateProfessional Cloud Architect
Security Command Center VPC Service Controls Integration
Ensuring the reliability of solutions in production (e.g., chaos engineering, penetration testing, and load testing)
IntermediateProfessional Cloud Architect
Secret Manager
Data security (key management, encryption, secret management)
IntermediateProfessional Cloud Architect
Event-Driven Vertex AI Pipeline Triggering
Using Vertex AI pipelines to automate and orchestrate the ML lifecycle
IntermediateProfessional Cloud Architect
Workload Validation Protocol
Using migration methodologies, workload testing, network planning, and dependency planning
FundamentalAssociate Data Practitioner
Encryption In Transit vs Encryption At Rest
Identify the difference between encryption in transit and encryption at rest
Last updated