Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Balanced Regional MIG Autoscaling with Autohealing
Free sample question, answered and explained below. The Professional Cloud Architect practice bank has 2,335 more like it. Try 10 free: instant score, no account.
An enterprise is implementing an automated provisioning and elasticity strategy using Terraform to deploy a mission-critical, stateless serving workload across multiple Google Cloud regions. The deployment must satisfy the following architectural requirements:
- Ensure identical and reproducible virtual machine (VM) configurations across all target regions.
- Provide automated resilience against single-zone outages within each region by maintaining balanced instance counts across zones.
- Automatically scale capacity up or down based on compute demand while maintaining zone distribution.
- Automatically detect and repair unresponsive or crashed application instances without manual intervention.
Which configuration should you define in your Terraform templates to achieve this architecture?
Explanations
Define separate zonal google_compute_instance_template resources per zone, create individual zonal google_compute_instance_group_manager resources in each zone, and attach individual google_compute_autoscaler resources.
Define separate zonal google_compute_instance_template resources per zone, create individual zonal google_compute_instance_group_manager resources in each zone, and attach individual google_compute_autoscaler resources.
What Multiple Zonal Instance Groups Are
This approach deploys individual zonal Managed Instance Groups (zonal MIGs) (google_compute_instance_group_manager), placing an independent instance group and zonal autoscaler inside each separate zone rather than using a single regional manager.
Why It Doesn't Meet the Requirement
- Lacks Automated Cross-Zone Balancing: Individual zonal MIGs operate independently and cannot coordinate instance distribution across zones. They cannot maintain an
EVENdistribution across the region as demand fluctuates. - Increased IaC Complexity and Drift: Defining distinct zonal templates and multiple zonal MIG managers multiplies the Terraform codebase and introduces configuration drift across zones and regions.
- Manual Outage Failover: If a zonal outage occurs, a zonal MIG in the failing zone cannot automatically redistribute its capacity or recreate VMs in surviving zones, unlike a regional MIG.
Key Characteristics and Limitations
- Zonal Boundary Isolation: Zonal MIGs cannot span multiple zones or shift instances dynamically to alternative zones.
- Higher Operational Overhead: Requires managing separate capacity limits, autoscaling targets, and maintenance policies per zone.
- Lower Default Group Capacity Limits: Zonal MIGs support up to 1,000 VMs by default, whereas regional MIGs support up to 2,000 VMs.
This Answer Would Be Correct If
You had workloads that strictly required specific hardware accelerators (like specialized TPUs or GPUs) only available in one specific zone, or if you needed isolated zonal maintenance domains without regional coordination.
Additional Context
Google Cloud recommends regional MIGs over collections of zonal MIGs because regional MIGs natively automate cross-zone provisioning, capacity redistribution, and fault domain management.
Define a global google_compute_instance_template, deploy a google_compute_region_instance_group_manager in each region configured with an ANY_SINGLE_ZONE distribution shape, and attach a google_compute_region_autoscaler.
Define a global google_compute_instance_template, deploy a google_compute_region_instance_group_manager in each region configured with an ANY_SINGLE_ZONE distribution shape, and attach a google_compute_region_autoscaler.
What the ANY_SINGLE_ZONE Target Distribution Shape Is
The ANY_SINGLE_ZONE distribution shape instructs a regional MIG to create all of its managed VM instances within a single zone in the chosen region, selecting the zone based on quota, resource availability, or reservation alignment.
Why It Doesn't Meet the Requirement
- Autoscaling Is Unsupported: When a regional MIG's target distribution shape is set to
ANY_SINGLE_ZONE(orANY), autoscaling is explicitly not supported. Google Cloud requires the target distribution shape to be set toEVENorBALANCEDto enable autoscaling. - Fails Zonal Fault Tolerance: By placing all instances inside a single zone, the group is completely exposed to zonal infrastructure outages, violating the core resilience requirement.
Key Characteristics and Limitations
- Single Zone Concentration: Concentrates 100% of the group's capacity in one zone, forfeiting multi-zone distribution.
- Autoscaler Disabled: The Compute Engine Autoscaler cannot add or remove VMs dynamically when
ANY_SINGLE_ZONEis selected. - Workload Target: Primarily intended for low-latency batch jobs or compact placement scenarios where high-throughput inter-node network communication within a single zone is needed.
This Answer Would Be Correct If
You were running high-performance computing (HPC) or tightly coupled MPI batch processing tasks that require low latency via compact placement policies within a single zone and do not use autoscaling.
Additional Context
To provide high availability and elastic autoscaling in regional MIGs, always select either the EVEN shape (for balanced multi-zone distribution) or BALANCED shape.
Define a global google_compute_instance_template, deploy a google_compute_region_instance_group_manager in each region with an EVEN target distribution shape and an application health check autohealing policy, and attach a google_compute_region_autoscaler.
Define a global google_compute_instance_template, deploy a google_compute_region_instance_group_manager in each region with an EVEN target distribution shape and an application health check autohealing policy, and attach a google_compute_region_autoscaler.
What Regional MIGs with Instance Templates and Autoscalers Are
A regional Managed Instance Group (MIG) manages homogeneous Compute Engine virtual machine instances across multiple zones within a single region. The group's VM configuration, including machine type, boot disk image, network settings, and startup metadata, is defined using a global instance template. Elasticity and resilience are managed by coupling the regional MIG manager with a regional autoscaler and an application autohealing policy.
How It Meets the Requirements
- Consistent Regional Deployments: Using a global instance template allows Terraform to reuse a single, standardized, and deterministic VM definition across all target regions, guaranteeing configuration consistency.
- Zonal Resilience & Balanced Capacity: Configuring the regional MIG with a target distribution shape of
EVENguarantees that instance counts across selected zones do not differ by more than one instance, ensuring adequate failover capacity during a zonal outage. - Automated Elasticity: Attaching a
google_compute_region_autoscalerallows the group to scale out or in dynamically based on metrics such as CPU utilization while respecting theEVENmulti-zone distribution shape. - Automatic Instance Recovery: Defining an autohealing policy with an application-based health check allows the MIG to detect crashed or frozen applications and automatically delete and recreate failing instances.
Regional MIG EVEN Distribution Across Zones
System Architecture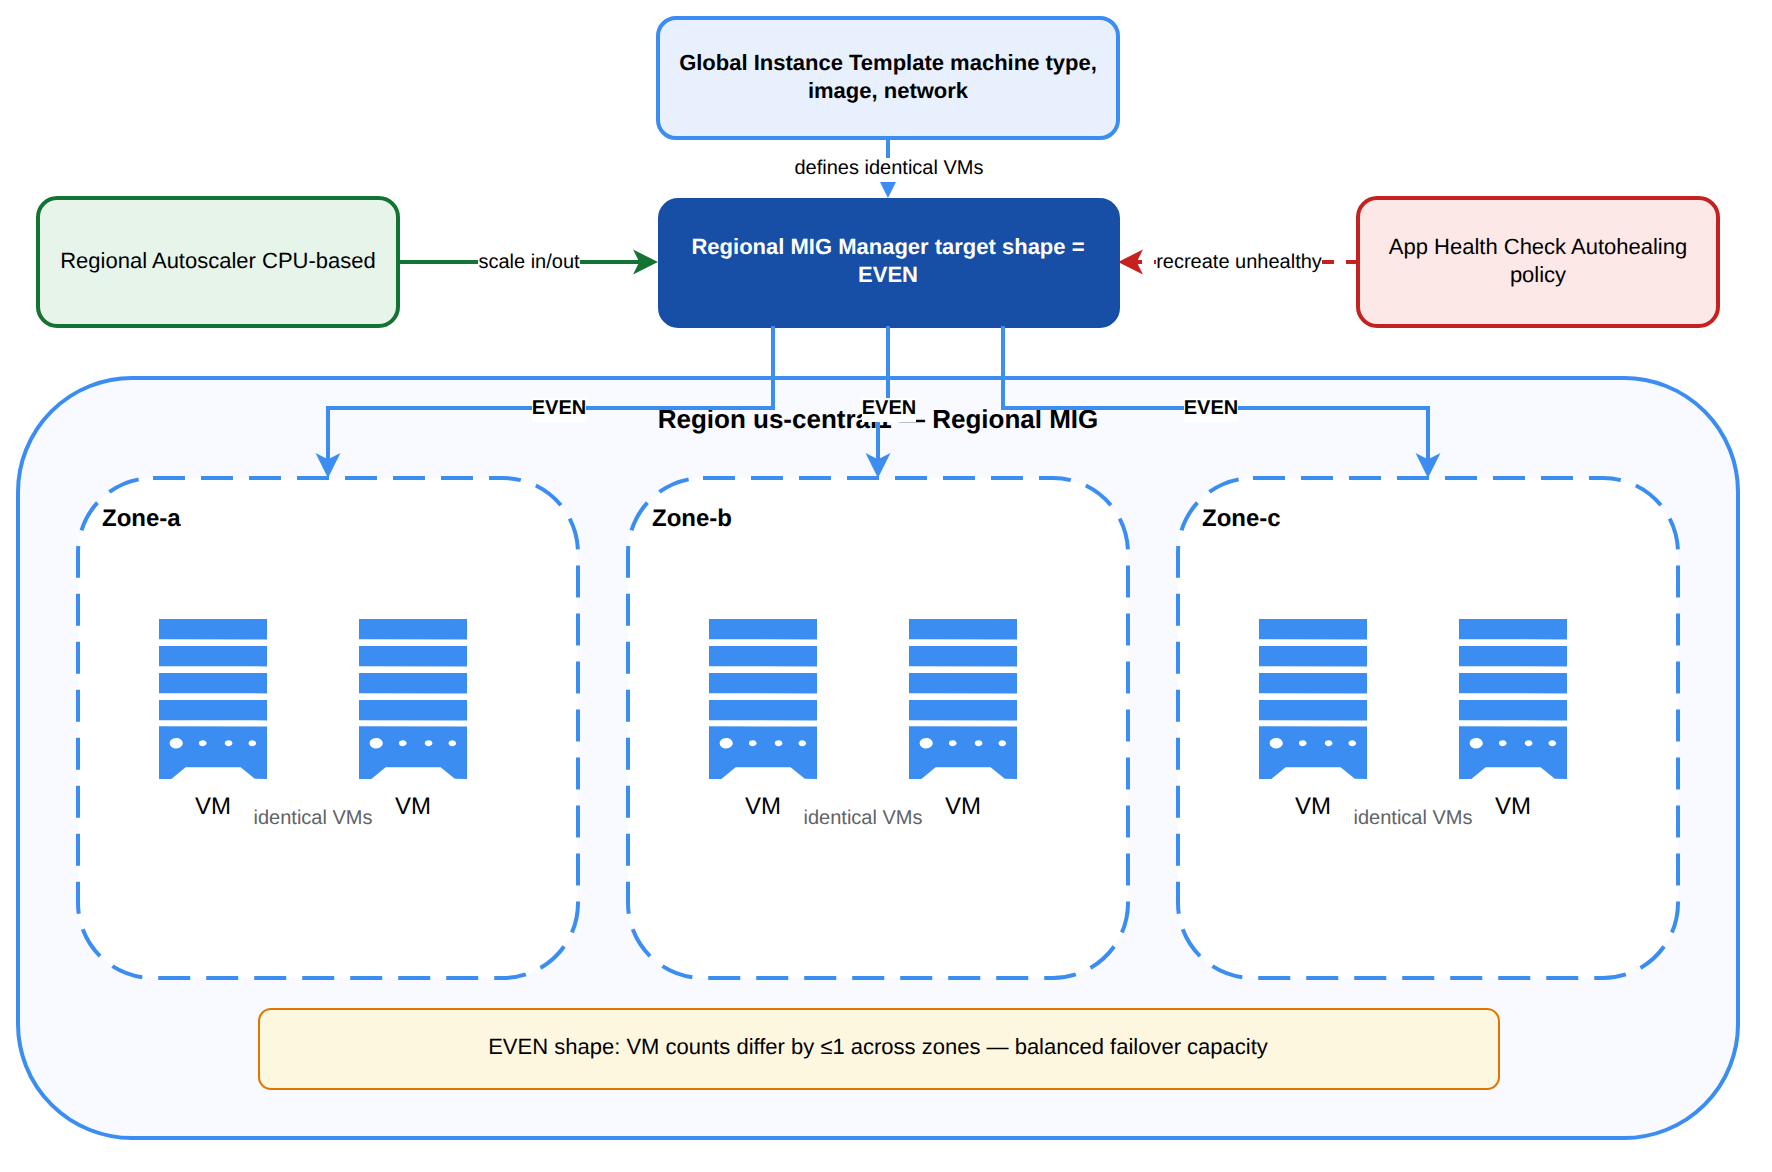
Key Advantages
- Regional High Availability: Protects workloads from localized data center or zonal hardware failures by distributing traffic and compute across multiple physical zones.
- Automated Lifecycle Management: Handles VM creation, health monitoring, autohealing, and automated rolling updates declaratively through Terraform.
- Elastic Efficiency: Dynamically optimizes cloud infrastructure costs by matching instance count precisely to incoming traffic loads.
- Standardized Infrastructure as Code (IaC): Eliminates human configuration drift across multi-regional environments.
Why This Is Optimal
This pattern represents the Google Cloud architectural best practice for stateless, high-availability web tiers. Regional MIGs combined with EVEN distribution shapes, regional autoscaling, and dedicated autohealing health checks deliver multi-zone fault tolerance and zero-touch elasticity natively.
Define a global google_compute_instance_template, deploy a stateful google_compute_region_instance_group_manager in each region configured with stateful disks, and attach a google_compute_region_autoscaler to manage scaling.
Define a global google_compute_instance_template, deploy a stateful google_compute_region_instance_group_manager in each region configured with stateful disks, and attach a google_compute_region_autoscaler to manage scaling.
What Stateful Managed Instance Groups Are
A Stateful Managed Instance Group (Stateful MIG) is designed for workloads that require preserving unique instance state, such as dedicated instance names, attached stateful persistent disks, or specific metadata, across VM recreation, restarts, or autohealing events.
Why It Doesn't Meet the Requirement
- Autoscaling Incompatibility: Stateful MIGs cannot be autoscaled. Compute Engine autoscalers only support stateless managed instance groups. Attempting to attach an autoscaler to a stateful regional MIG will fail or produce an invalid configuration.
- Mismatched Workload Type: The scenario specifically defines a stateless serving workload. Implementing stateful persistent disk configurations adds unnecessary storage overhead and complexity that conflicts with dynamic scaling requirements.
Key Characteristics and Limitations
- No Dynamic Horizontal Autoscaling: Stateful MIGs require manual resizing or scheduled operational scripts rather than metric-based dynamic autoscaling.
- State Preservation Focus: Stateful MIGs preserve disk data and IP configurations during autohealing, which is intended for databases or legacy monoliths, not elastic web tiers.
- Operational Overhead: Requires managing per-instance configurations and stateful disk lifecycle policies.
This Answer Would Be Correct If
You were deploying stateful applications like single-node database instances (such as Cassandra, Kafka, or Elasticsearch nodes) that need automatic recovery of persistent data disks in fixed-capacity clusters.
Additional Context
For stateless web services, boot disks and attached volumes should remain stateless so that instances can be rapidly scaled out, destroyed, or recreated from standard base templates.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,335 practice questions across all 6 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
IntermediateProfessional Cloud Architect
Custom Machine Types
Compute resource provisioning
IntermediateProfessional Cloud Architect
Cloud Run Scale To Zero
Compute resource provisioning
IntermediateProfessional Cloud Architect
VPC Service Controls with Shared VPC
Security and compliance
IntermediateProfessional Cloud Architect
Google Cloud Transfer Appliance
Configuration for data transfer and latency
IntermediateProfessional Cloud Architect
Dataproc vs Dataflow
Data processing and compute provisioning
AdvancedProfessional Cloud DevOps Engineer
Preferred Backends and Automatic Capacity Draining
Spot virtual machines (VMs)
Last updated