Fundamental
Prepare and test your skills
Fundamental
Prepare and test your skills
Dataflow Processing with BigQuery and Cloud Storage
Free sample question, answered and explained below. The Associate Data Practitioner practice bank has 1,156 more like it. Try 10 free: instant score, no account.
A data engineering team is establishing the data collection and preparation architecture for a machine learning project on Google Cloud. The architecture must satisfy three specific requirements:
- Transform and cleanse large batches of raw data at scale using parallel processing pipelines.
- Store the prepared structured feature tables in an analytical warehouse where models can also be trained directly using SQL.
- Archive the original raw input files long-term in a highly durable, cost-effective object store.
Which combination of Google Cloud services should the team select?
Explanations
BigQuery Data Transfer Service for data processing, Dataproc Metastore for data storage and SQL-based ML training, and Managed Lustre for data archival
BigQuery Data Transfer Service for data processing, Dataproc Metastore for data storage and SQL-based ML training, and Managed Lustre for data archival
What the options are:
- BigQuery Data Transfer Service (DTS) is an automated data import service that schedules recurring data ingestion from SaaS platforms and cloud sources into BigQuery.
- Dataproc Metastore is a fully managed Apache Hive metastore service providing centralized metadata management for open-source big data frameworks.
- Managed Lustre is a high-performance parallel file system designed for intensive AI/HPC workloads requiring ultra-high throughput.
Why it doesn't meet the requirements:
- DTS cannot perform complex data processing: DTS automates data loading but does not support custom data cleansing, feature formatting, or complex pipeline transformations.
- Dataproc Metastore does not store data or train models: It only holds metadata catalogs (schemas, partition info) for tools like Hive or Spark; it does not store feature records or execute SQL machine learning queries.
- Managed Lustre is over-engineered for archival: Managed Lustre is an ultra-low-latency, high-IOPS parallel file system designed for active GPU/TPU training clusters, not cost-efficient long-term file retention.
Key limitations:
- DTS lacks arbitrary data transformation capabilities.
- Dataproc Metastore is a metadata repository, not a queryable data warehouse.
- Managed Lustre has capacity limits (e.g., up to 8 PB) and is significantly more expensive than object storage for cold data.
This answer would be correct if:
The team needed scheduled SaaS data ingestion (DTS), centralized Hive metadata management (Dataproc Metastore), and extreme high-throughput storage for distributed HPC simulation clusters (Managed Lustre).
Dataflow for data processing, BigQuery for data storage and SQL-based ML training, and Cloud Storage for data archival
Dataflow for data processing, BigQuery for data storage and SQL-based ML training, and Cloud Storage for data archival
What the selected services are:
This architecture leverages Dataflow, BigQuery, and Cloud Storage, which represent Google Cloud's core services for building robust data collection, preparation, and analytical pipelines for machine learning workflows.
How it meets the requirements:
- Data processing at scale: Dataflow provides a fully managed, serverless execution environment for Apache Beam pipelines. It automates provisioning, scaling, and fault tolerance to cleanse, transform, and normalize massive batch and streaming datasets for downstream machine learning tasks.
- Structured storage and SQL-based ML: BigQuery serves as an enterprise serverless data warehouse designed for structured datasets and fast analytical queries. With BigQuery ML, data practitioners can define, train, evaluate, and deploy machine learning models directly using standard SQL queries without needing to extract data into external compute environments.
- Cost-effective file archival: Cloud Storage provides highly scalable, highly durable, and cost-effective object storage. It is the recommended standard for retaining raw files, datasets, model weights, and training checkpoints long-term.
Key advantages:
- Unified serverless ecosystem: All three services scale automatically based on data volume, eliminating infrastructure management overhead.
- Native integrations: Dataflow can ingest directly from Cloud Storage and sink transformed feature tables into BigQuery seamlessly.
- Built-in ML capabilities: BigQuery ML reduces operational complexity by allowing model training directly where structured data resides.
- Storage lifecycle management: Cloud Storage allows automated tiering to archival classes (such as Nearline, Coldline, and Archive) to minimize retention costs.
Why this is optimal:
This combination establishes the standard Google Cloud reference architecture for ML data preparation. It cleanly separates raw data lake storage (Cloud Storage), distributed data transformation execution (Dataflow), and high-performance structured feature serving with built-in modeling (BigQuery).
Separating Storage, Processing, and Warehouse Roles
System Architecture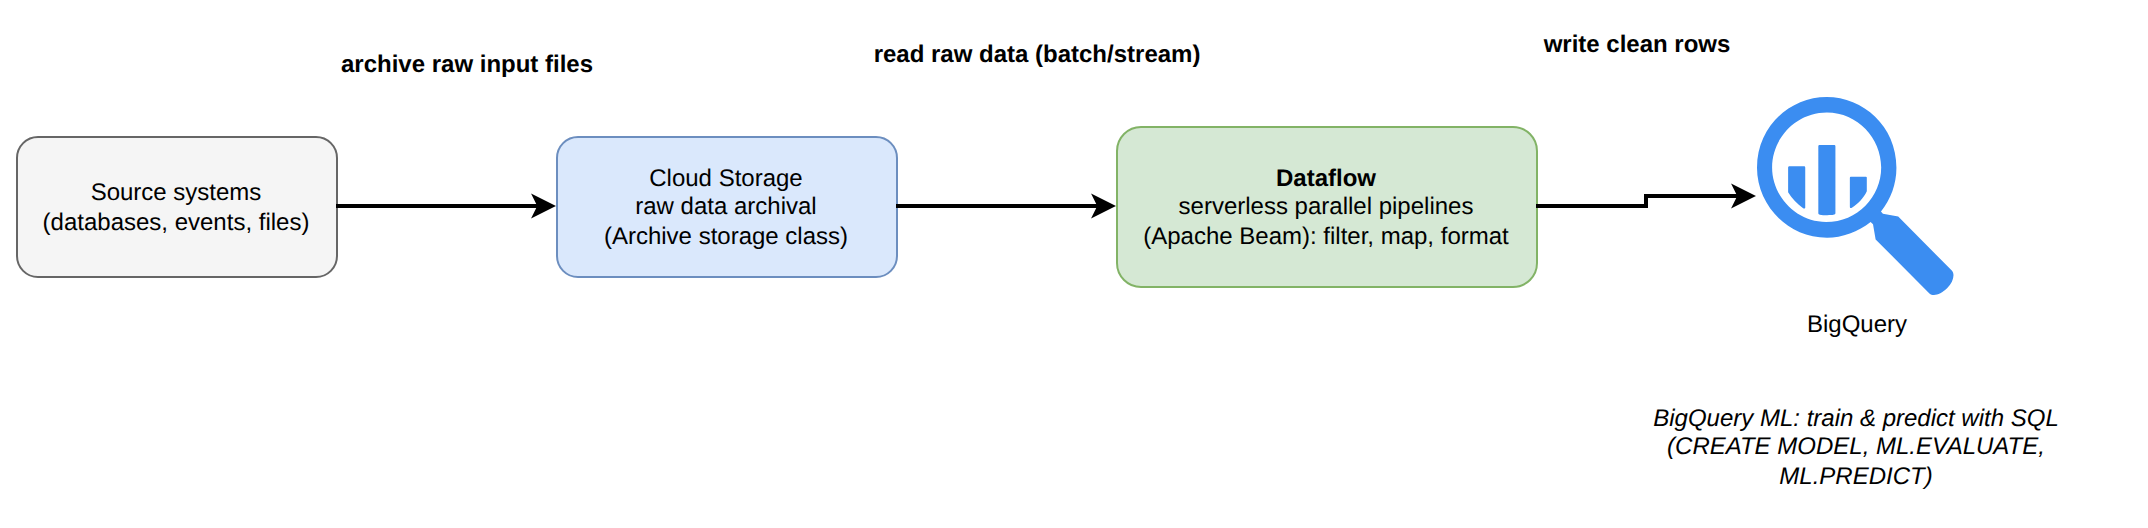
Pub/Sub for data processing, Cloud Spanner for data storage and SQL-based ML training, and Filestore for data archival
Pub/Sub for data processing, Cloud Spanner for data storage and SQL-based ML training, and Filestore for data archival
What the options are:
- Pub/Sub is a globally distributed, asynchronous messaging service designed for real-time stream ingestion and event routing.
- Cloud Spanner is a fully managed, mission-critical relational transactional (OLTP) database providing global consistency.
- Filestore is a managed network-attached storage (NAS) service offering POSIX-compliant file shares for compute instances.
Why it doesn't meet the requirements:
- Pub/Sub is not a data transformation engine: Pub/Sub ingests and decouples message streams; it does not perform batch cleansing, schema transformation, or heavy data processing.
- Cloud Spanner is designed for transactions, not SQL ML: While Spanner supports ANSI SQL for transactional applications, it is not an analytical data warehouse and lacks built-in native model creation statements like BigQuery ML.
- Filestore is not suitable for cost-effective archival: Filestore is an expensive, high-throughput file system intended for low-latency shared compute access, making it cost-prohibitive for raw data archival compared to object storage.
Key limitations:
- Pub/Sub requires downstream compute (such as Dataflow) to execute data transformation.
- Cloud Spanner adds significant operational cost if used solely to store analytical feature tables.
- Filestore lacks automated object lifecycle policies and tiered storage pricing.
This answer would be correct if:
The requirement called for high-throughput event ingestion (Pub/Sub), global transactional consistency for transactional applications (Cloud Spanner), and a shared POSIX file system for high-performance virtual machines (Filestore).
Dataplex for data processing, Cloud SQL for data storage and SQL-based ML training, and Transfer Appliance for data archival
Dataplex for data processing, Cloud SQL for data storage and SQL-based ML training, and Transfer Appliance for data archival
What the options are:
- Dataplex is an intelligent data fabric that manages metadata, data governance, and data discovery across distributed data lakes.
- Cloud SQL is a managed relational database service for MySQL, PostgreSQL, and SQL Server.
- Transfer Appliance is a rugged hardware device used to physically ship large volumes of on-premises data to Google Cloud.
Why it doesn't meet the requirements:
- Dataplex is not a distributed data processing engine: While Dataplex orchestrates data quality tasks, it does not serve as a general-purpose, scalable data transformation pipeline engine like Dataflow.
- Cloud SQL is an OLTP database: Cloud SQL is designed for web application transactions rather than large-scale ML feature storage and lacks native SQL model training capabilities like BigQuery ML.
- Transfer Appliance is a physical migration hardware solution: Transfer Appliance is used for initial, one-time bulk data migration over physical logistics, not for ongoing cloud-based data archival.
Key limitations:
- Dataplex focuses on data governance, cataloging, and security policies rather than raw compute execution.
- Cloud SQL has limited horizontal scaling and storage capacity compared to enterprise cloud data warehouses.
- Transfer Appliance is a physical appliance, not a scalable cloud storage service.
This answer would be correct if:
The project required centralized data governance across existing silos (Dataplex), a standard transactional relational backend (Cloud SQL), and offline physical data migration from an on-premises data center with limited network bandwidth (Transfer Appliance).
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 1,156 practice questions across all 4 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
FundamentalAssociate Data Practitioner
BigQuery ML Model Lifecycle
Plan a standard ML project (e.g., data collection, model training, model evaluation, prediction)
FundamentalAssociate Data Practitioner
BigQuery Dataset Prerequisite
Plan a standard ML project (e.g., data collection, model training, model evaluation, prediction)
FundamentalAssociate Data Practitioner
Cloud Storage Predefined Roles
Differentiate between basic roles, predefined roles, and permissions for data services (e.g., BigQuery, Cloud Storage)
FundamentalAssociate Data Practitioner
Analytics Hub Data Sharing
Determine when to share data using Analytics Hub
FundamentalAssociate Data Practitioner
Cloud SQL Cross-Region Replication Lag
Determine when to use replication
AdvancedProfessional Data Engineer
Eventarc to Cloud Workflows
Job automation and orchestration (e.g., Cloud Composer and Workflows)
Last updated