Fundamental
Prepare and test your skills
Fundamental
Prepare and test your skills
Scheduled SaaS Ingestion and SQL Transformation in BigQuery
Free sample question, answered and explained below. The Associate Data Practitioner practice bank has 1,132 more like it. Try 10 free: instant score, no account.
A data analytics team is designing an Extract, Load, Transform (ELT) architecture for their organization's marketing data. The requirements specify:
- Automatically ingest raw data from supported external SaaS platforms on a scheduled basis without custom code.
- Load the raw data directly into the cloud data warehouse first.
- Perform transformations, data modeling, and aggregations natively within the data warehouse using SQL.
Which combination of Google Cloud services should the team use to meet these requirements?
Explanations
Use Storage Transfer Service to load the data into Bigtable, then run BigQuery federated queries to transform the tables.
Use Storage Transfer Service to load the data into Bigtable, then run BigQuery federated queries to transform the tables.
What Storage Transfer Service and Bigtable are
Storage Transfer Service is a scalable service designed to transfer large volumes of data from external cloud providers, online storage, or on-premises systems into Cloud Storage. Bigtable is a fully managed, low-latency NoSQL wide-column database optimized for high-throughput operational workloads and time-series data.
Why it doesn't meet the requirement
- Incorrect destination for marketing analytics: Bigtable is an operational NoSQL database, not an analytical data warehouse. It does not provide native SQL analytics or standard data modeling capabilities needed for data warehousing.
- Storage Transfer Service target limitation: Storage Transfer Service transfers data to Cloud Storage buckets or POSIX file systems, not directly to Bigtable or BigQuery tables.
- Federated queries are not ELT transformations: Federated queries allow BigQuery to read external sources on demand, but they do not perform scheduled data loading or warehouse-native data transformation.
Key characteristics of Storage Transfer Service and Bigtable
- Storage Transfer Service manages bulk object migration across cloud repositories (e.g., AWS S3 to Cloud Storage).
- Bigtable provides single-digit millisecond latency for key-based lookups and high-scale writes.
- Neither service acts as an enterprise SQL data warehouse or ELT orchestration engine.
This answer would be correct if
The scenario required moving petabytes of unstructured object files from Amazon S3 into Cloud Storage or serving real-time IoT sensor telemetry using a low-latency NoSQL engine.
Use BigQuery Data Transfer Service to load raw data into BigQuery, and use Dataform to execute transformations inside BigQuery.
Use BigQuery Data Transfer Service to load raw data into BigQuery, and use Dataform to execute transformations inside BigQuery.
What BigQuery Data Transfer Service and BigQuery/Dataform are
BigQuery Data Transfer Service (DTS) is a fully managed service that automates the scheduled ingestion of data from external SaaS applications, third-party platforms, and cloud storage into BigQuery. BigQuery is Google Cloud's serverless, highly scalable enterprise data warehouse, and Dataform is a service used to develop, version control, and orchestrate SQL workflows directly inside BigQuery.
How it meets the ELT requirements
- Extract and Load (E & L): BigQuery Data Transfer Service extracts raw marketing and SaaS data (such as Google Ads, Campaign Manager, Salesforce, and Cloud Storage) on a predefined schedule and loads the unmodified raw data directly into BigQuery datasets without requiring custom extraction code.
- Transform (T): Once the raw data resides within BigQuery, SQL-based tools like Dataform or BigQuery scheduled queries perform transformations, deduplication, and aggregation natively inside the warehouse engine, leveraging BigQuery's scalable compute power.
- Codeless Ingestion: Data engineers do not need to write or maintain complex data connectors or pipeline scripts to ingest external data sources.
ELT on Google Cloud: Load Raw, Transform Inside BigQuery
Process Flow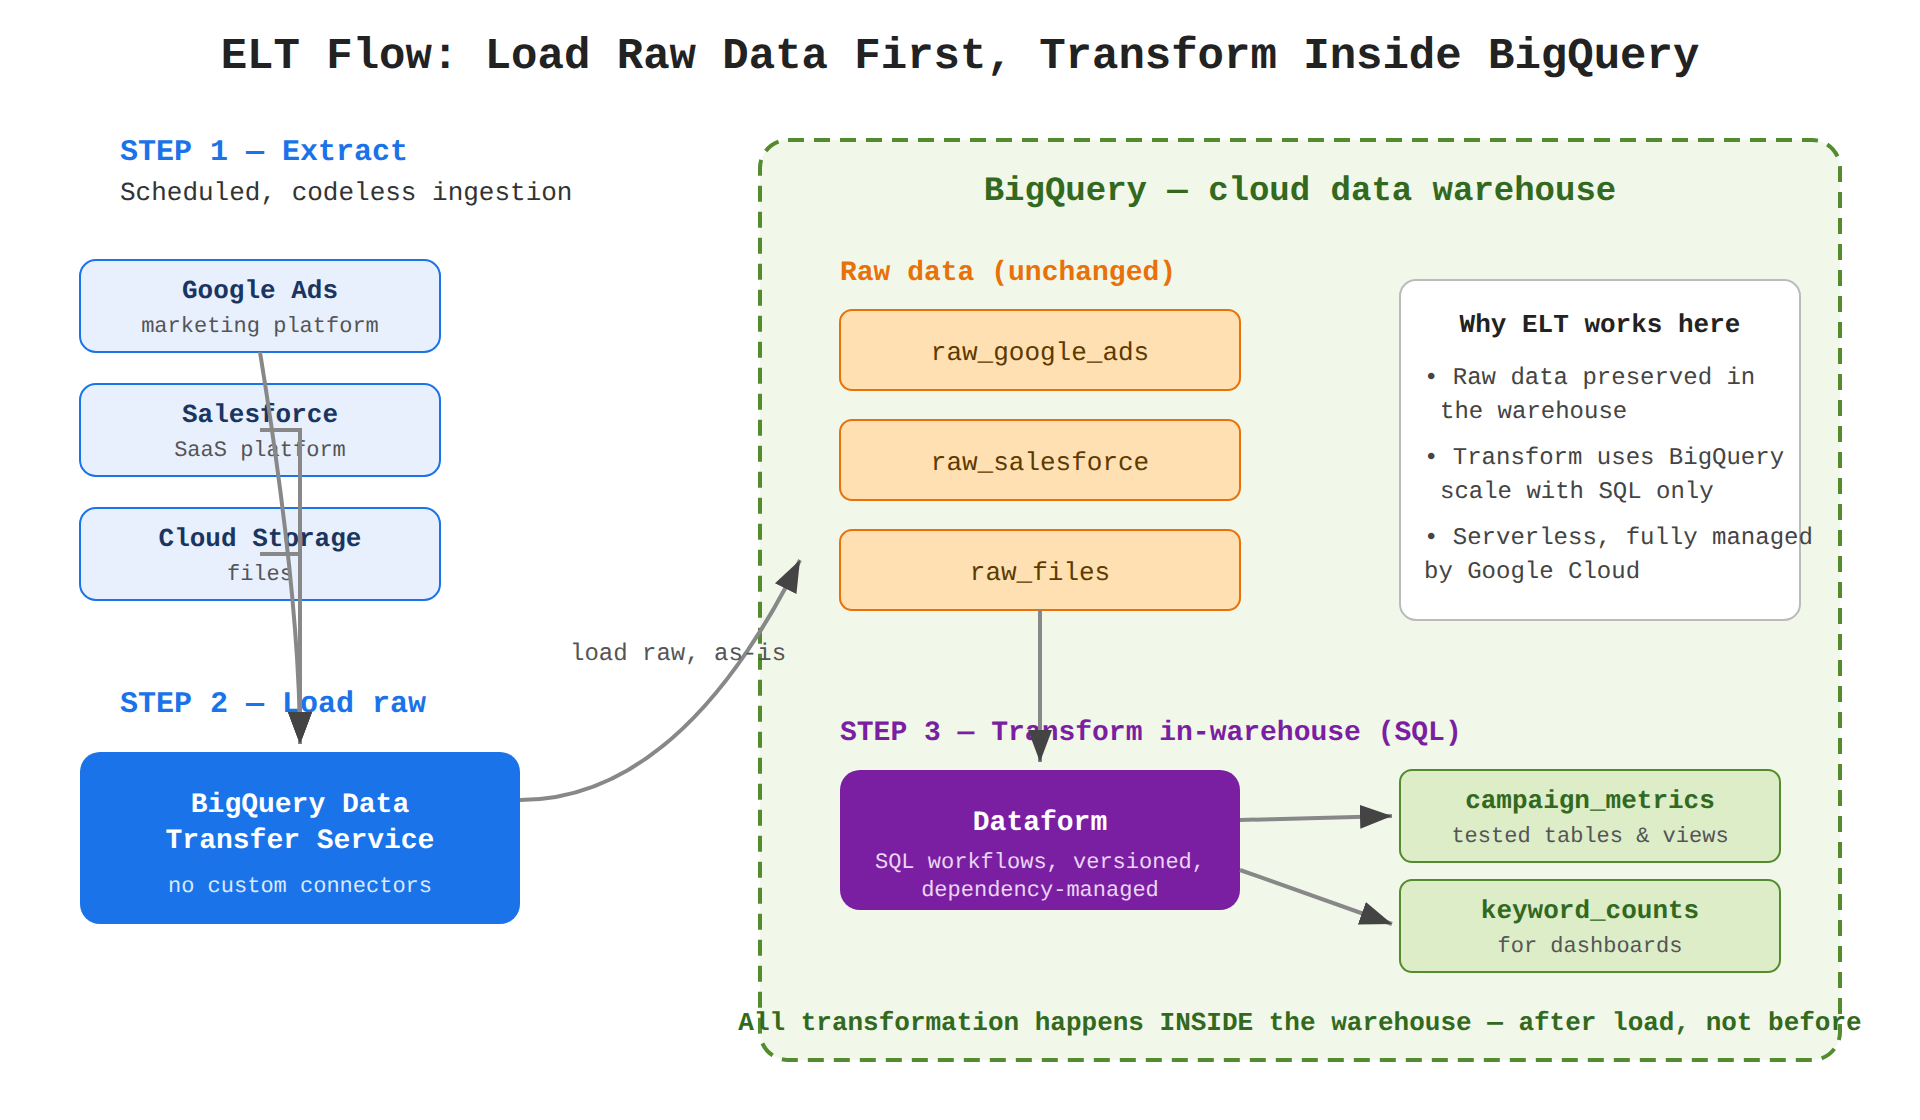
Key advantages of this architecture
- Warehouse-native processing: Shifts compute loads to BigQuery's distributed SQL engine, avoiding external intermediate processing clusters.
- Preservation of raw data: Retains raw ingested data within the warehouse for auditing, re-processing, or exploratory analysis.
- Automated orchestration: Dataform provides built-in dependency management, data quality testing, and SQL workflow scheduling.
- Low operational overhead: Both services are serverless and fully managed by Google Cloud.
Why this is optimal
This architecture perfectly demonstrates the ELT (Extract, Load, Transform) pattern. Instead of transforming data prior to loading it into the warehouse, data is loaded rapidly in its native raw state and transformed post-load using SQL.
Use Dataflow to process and transform the source data in transit, then write the finalized output directly into BigQuery.
Use Dataflow to process and transform the source data in transit, then write the finalized output directly into BigQuery.
What Dataflow is and does
Dataflow is a fully managed, serverless stream and batch processing service built on the Apache Beam programming model. It provides distributed processing capabilities for large-scale real-time and batch pipelines.
Why it doesn't meet the requirement
- Represents ETL processing: Dataflow transforms data before it reaches the target storage or warehouse. The transformation phase occurs in an external compute engine (Dataflow worker virtual machines) rather than inside the data warehouse.
- Requires custom code or pipeline execution: Developing Beam pipelines typically requires programming in Java, Python, or Go, whereas the scenario specifies scheduled ingestion without code and transformation using warehouse-native SQL.
- Mismatched architecture: Dataflow is designed for compute-based data transformations during ingestion rather than native ELT post-load transformations.
Key characteristics of Dataflow
- Supports both streaming and batch data processing with exactly-once semantics.
- Manages worker autoscaling, dynamic work rebalancing, and windowing operations.
- Excels at real-time event ingestion from Pub/Sub and complex data transformations.
This answer would be correct if
The requirements called for streaming real-time event data, performing windowed aggregations or complex event-driven transformations in flight, and then loading the cleaned records into BigQuery.
Use Cloud Data Fusion to extract and transform data before loading the cleaned records into BigQuery.
Use Cloud Data Fusion to extract and transform data before loading the cleaned records into BigQuery.
What Cloud Data Fusion is and does
Cloud Data Fusion is a fully managed, cloud-native enterprise data integration service featuring a visual, code-free interface. It runs on underlying Dataproc clusters (Apache Spark) to execute data transformations and pipeline workflows across diverse on-premises and cloud sources.
Why it doesn't meet the requirement
- Represents ETL, not ELT: Cloud Data Fusion applies compute-based transformations (data cleansing, formatting, filtering) in-flight prior to loading the data into the destination warehouse. This follows the ETL (Extract, Transform, Load) methodology.
- External compute overhead: Instead of executing transformations natively inside BigQuery using SQL, transformations are executed on external Spark/Dataproc worker nodes.
- Unnecessary complexity for native SQL workflows: The scenario specifically requires loading raw data first and executing transformations natively inside the warehouse.
Key characteristics of Cloud Data Fusion
- Provides a visual point-and-click interface with over 150 pre-built connectors.
- Executes distributed data processing on managed Apache Spark/Hadoop clusters.
- Ideal for complex file transformations and multi-cloud data integration before loading.
This answer would be correct if
The organization required an ETL architecture where sensitive data (such as PII) had to be masked or heavily cleansed outside of BigQuery prior to loading, or if the team wanted a visual, drag-and-drop pipeline interface without writing SQL.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 1,132 practice questions across all 4 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
FundamentalAssociate Data Practitioner
ETL with Dataflow Pre-Load Transformations
Differentiate between different data manipulation methodologies (e.g., ETL, ELT, ETLT)
FundamentalAssociate Data Practitioner
ELT
Differentiate between different data manipulation methodologies (e.g., ETL, ELT, ETLT)
FundamentalAssociate Data Practitioner
BigQuery ML ML.FORECAST
Perform inference using BigQuery ML models
FundamentalAssociate Data Practitioner
Vertex AI AutoML for Image and Text
Identify ML use cases for developing models by using BigQuery ML and AutoML
FundamentalAssociate Data Practitioner
BigQuery ML Model Lifecycle
Plan a standard ML project (e.g., data collection, model training, model evaluation, prediction)
IntermediateProfessional Cloud Architect
Windows-Based SLI vs Request-Based SLI
Understanding the principles and recommendations of the operational excellence pillar of the Google Cloud Well-Architected Framework
Last updated