Fundamental
Prepare and test your skills
Fundamental
Prepare and test your skills
Visual No-Code ETL with Cloud Data Fusion
Free sample question, answered and explained below. The Associate Data Practitioner practice bank has 1,156 more like it. Try 10 free: instant score, no account.
A retail analytics team needs to build a new data pipeline to ingest, clean, and transform transactional records from multiple database sources before loading them into their analytics storage.
The team has established the following requirements:
- The pipeline must provide a drag-and-drop, visual user interface to design transformations.
- Business analysts must be able to build and deploy ETL workflows without writing Java or Python code.
- The service must offer pre-built connectors and interactive data wrangling tools.
Which Google Cloud service should the team select?
Explanations
Dataproc
Dataproc
What Dataproc is and does
Dataproc is a fully managed cloud service for running open-source big data processing engines, including Apache Spark, Apache Hadoop, Apache Flink, and Presto/Trino. It allows organizations to lift and shift existing on-premises big data clusters to Google Cloud infrastructure.
Why it doesn't meet the requirement
- Requires writing code and scripts (✗): Dataproc jobs require writing code in languages such as PySpark, Scala, Java, or HiveQL scripts. It does not provide a built-in drag-and-drop graphical interface for pipeline creation.
- Infrastructure and cluster configuration overhead (✗): Users must configure compute engine instances, cluster topology, autoscaling policies, initialization actions, and runtime dependencies.
- Not intended for no-code business analysts (✗): Dataproc is engineered for data engineers, system administrators, and data scientists experienced with the Apache open-source ecosystem, not business analysts seeking a visual workflow builder.
Key characteristics and limitations
- Open-source compatibility: Provides full access to native open-source software distributions and Hadoop ecosystem tools.
- Cluster lifecycle options: Supports long-lived analytical clusters as well as ephemeral job-scoped clusters created specifically to execute individual batch transformations.
- High control over resources: Allows precise customization of machine types, GPUs, attached SSD storage, and custom daemon configurations.
This answer would be correct if
The organization had existing on-premises Apache Spark or Hadoop workloads that they wanted to migrate directly to Google Cloud without refactoring their open-source codebase.
Cloud Data Fusion
Cloud Data Fusion
What Cloud Data Fusion is
Cloud Data Fusion is Google Cloud's fully managed, cloud-native data integration service that provides a graphical user interface for building and managing scalable ETL/ELT data pipelines. Built on the open-source CDAP (Cask Data Application Platform) framework, it allows organizations to ingest data from heterogeneous sources, apply complex transformations visually, and sink transformed datasets into analytics destinations such as BigQuery without writing underlying code.
How it meets the requirements
- Visual pipeline designer (✓): Cloud Data Fusion features Pipeline Studio, a web-based, drag-and-drop graphical canvas where users can visually map source systems, transformation plugins, and data sinks.
- Code-free workflow development (✓): Business analysts and non-developers can design end-to-end extraction, transformation, and loading logic without needing software development skills in Java, Scala, or Python.
- Interactive data wrangling (✓): The built-in Wrangler plugin offers a spreadsheet-like data preparation interface to profile data, clean text fields, convert data types, filter unwanted records, and apply conditional logic interactively.
- Pre-built connectors (✓): Provides over 150 turnkey connectors and plugins for various relational databases, cloud storage services, enterprise applications, and file formats.
Visual ETL Pipeline Design in Cloud Data Fusion
Process Flow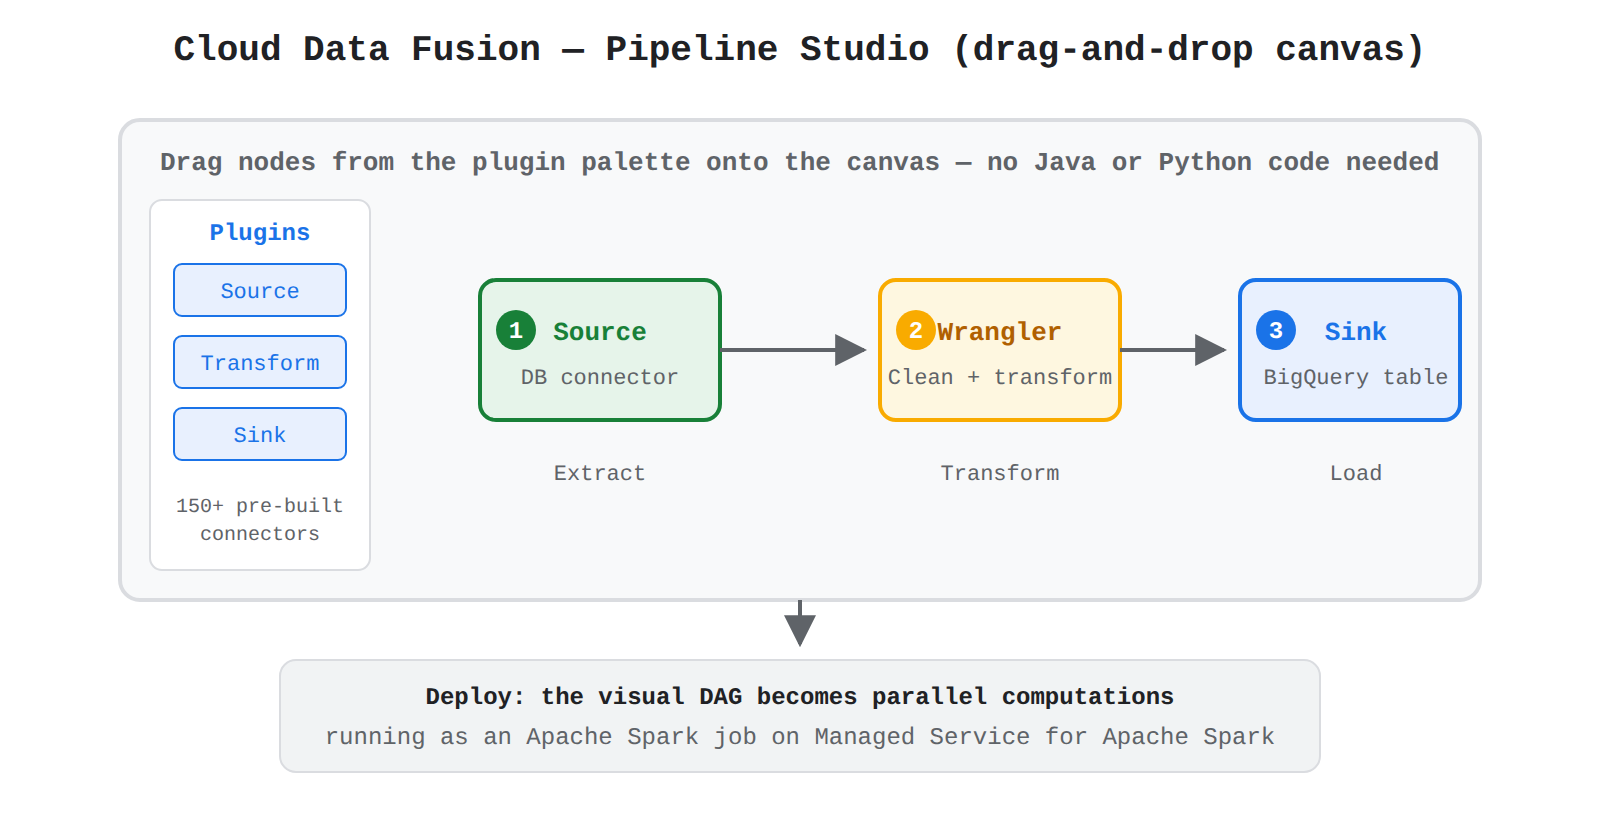
Key advantages and capabilities
- Managed execution runtime: Pipelines designed visually are automatically translated into distributed Apache Spark/MapReduce jobs that run on ephemeral Cloud Dataproc clusters managed seamlessly behind the scenes.
- Data lineage and metadata tracking: Automatically captures end-to-end dataset metadata and transformation lineage, integrating directly with Dataplex and Data Catalog for enterprise governance.
- Built-in scheduling and alerts: Allows users to schedule periodic batch runs, configure retry behaviors, and set up notification alerts without requiring third-party orchestration tools.
- Extensibility: Enables developers to insert custom Python/JavaScript transforms or reusable custom plugins when specialized processing logic is required.
Why this is optimal
Cloud Data Fusion is the optimal choice because it specifically targets users who need a no-code visual ETL interface. In contrast to programmatic frameworks like Dataflow or code-driven cluster solutions like Dataproc, Cloud Data Fusion accelerates time-to-value for business analysts while retaining robust distributed data processing capabilities.
Dataflow
Dataflow
What Dataflow is and does
Dataflow is Google Cloud's fully managed, serverless stream and batch data processing service based on the open-source Apache Beam SDK. It enables real-time message consumption, event-driven windowing, and distributed batch processing at massive scale with exactly-once processing guarantees.
Why it doesn't meet the requirement
- Requires programming expertise (✗): Dataflow requires developers to write pipeline code in Java, Python, or Go using the Apache Beam SDK. It lacks a native drag-and-drop visual interface for creating and modifying custom transformation pipelines.
- Not tailored for code-free analyst workflows (✗): While Google provides pre-built Dataflow templates for common replication patterns, modifying and creating custom transformation logic requires writing software code, unit testing, and managing code deployments.
- Lacks interactive visual data wrangling (✗): Dataflow does not include an interactive graphical wrangling interface (like Wrangler) where business users can visually preview schema modifications on sample data.
Key characteristics and limitations
- Programmatic SDK model: Developers construct pipelines using Beam abstractions such as
PCollection,ParDo, andCombinePerKey. - Unmatched real-time stream processing: Excels at ultra-low latency stream analytics, sliding time windows, sessionization, and handling out-of-order data.
- Serverless autoscaling: Automatically provisions worker compute resources and dynamically rebalances workloads based on throughput demands.
This answer would be correct if
The scenario required a programmatic, real-time streaming pipeline where data engineers needed to write custom Python or Java code to process high-throughput events from Pub/Sub with millisecond latency and complex sliding time-window aggregations.
BigQuery
BigQuery
What BigQuery is and does
BigQuery is a serverless, highly scalable enterprise data warehouse designed for analytical data querying using standard SQL. It provides columnar storage, built-in machine learning (BigQuery ML), geospatial analysis, and business intelligence integrations.
Why it doesn't meet the requirement
- SQL-based ELT rather than visual ETL (✗): BigQuery performs transformations inside the warehouse using standard SQL queries and scheduled queries (an ELT paradigm). It does not provide a visual drag-and-drop pipeline canvas for non-SQL users.
- Not an ingestion ETL tool for external relational sources (✗): While BigQuery can query external data via BigQuery Omni or federated queries, it is not a general-purpose visual integration tool equipped with native drag-and-drop database connectors for extracting and transforming data before loading.
- No visual data preparation interface (✗): BigQuery does not have a native graphical data-wrangler tool for visual cleaning operations without formulating SQL transformation syntax.
Key characteristics and limitations
- In-warehouse processing: Computes transformations over petabyte-scale data using distributed DML and SQL statements.
- Serverless storage and analytics: Decouples compute from storage, allowing high-performance ad-hoc analysis and dashboard reporting.
- Integration with lineage: Integrates natively with Dataplex and Data Catalog to track lineage and metadata for executed SQL queries.
This answer would be correct if
The scenario stated that all raw data had already been ingested into tables within the cloud data warehouse, and analysts wanted to use standard SQL to filter, join, and aggregate tables inside the warehouse using an ELT design pattern.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 1,156 practice questions across all 4 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
FundamentalAssociate Data Practitioner
Dataflow Unified Batch and Streaming
Choose products required to implement basic transformation pipelines
FundamentalAssociate Data Practitioner
Cloud Dataflow GPU Acceleration
Choose products required to implement basic transformation pipelines
FundamentalAssociate Data Practitioner
BigQuery DataFrames Pandas API
Use Jupyter notebooks to analyze and visualize data (e.g., Colab Enterprise)
FundamentalAssociate Data Practitioner
Cloud Storage Regional Location
Choose the appropriate data storage location type (e.g., regional, dual-regional, multi-regional, zonal)
FundamentalAssociate Data Practitioner
Cloud KMS Asymmetric Envelope Encryption
Understand the role of Cloud Key Management Service (Cloud KMS) to manage encryption keys
AdvancedProfessional Cloud Security Engineer
GKE Workload Identity
Identifying scenarios requiring service accounts.
Last updated