Fundamental
Prepare and test your skills
Fundamental
Prepare and test your skills
Unified Batch and Streaming with Dataflow
Free sample question, answered and explained below. The Associate Data Practitioner practice bank has 1,156 more like it. Try 10 free: instant score, no account.
A data analytics team is building a data transformation pipeline for a smart retail platform. The pipeline must ingest high-volume continuous telemetry streams from store sensors as well as process historical transaction logs in scheduled batches using the open-source Apache Beam SDK.
Which Google Cloud service should the team select to execute these unified batch and streaming data processing pipelines?
Explanations
Dataflow
Dataflow
What Dataflow is:
Dataflow is Google Cloud's fully managed, serverless execution service for large-scale data processing. It executes data pipelines written using the open-source Apache Beam SDK, providing unified batch and streaming capabilities.
How it meets the requirements:
- Unified Batch and Streaming (✓): Dataflow uses the Apache Beam execution model, allowing developers to apply the same programming logic and pipeline components to both bounded (batch) and unbounded (streaming) datasets.
- Apache Beam SDK Support (✓): Apache Beam programs written in Java, Python, or Go are natively run and orchestrated on Dataflow without needing infrastructure changes.
- Serverless and Scalable (✓): Dataflow automatically provisions compute worker instances, dynamically optimizes execution graphs, and autoscales based on stream backlog and resource utilization.
- Real-Time Data Transformation (✓): It supports complex stream processing features such as windowing, watermarks, triggers, and stateful processing for high-volume IoT sensor feeds.
Unified Batch + Streaming Model in Dataflow
Set Relationship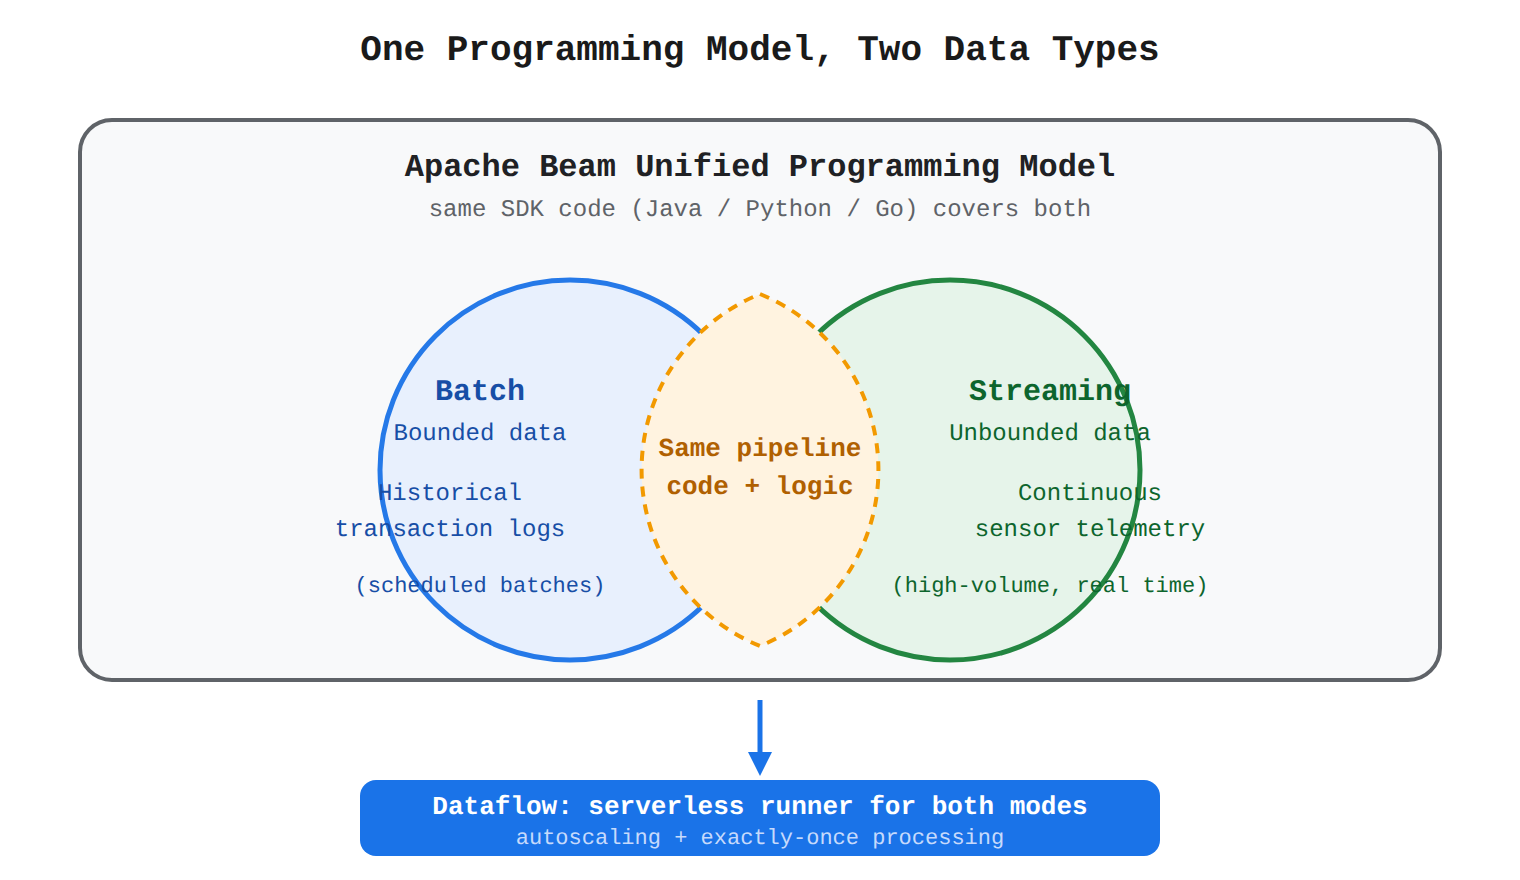
Key advantages and capabilities:
- Autoscaling and dynamic work rebalancing: Automatically scales worker nodes up or down and redistributes lagging partitions across available workers.
- Exactly-once processing: Ensures data consistency and reliability across stream computations.
- Pre-built and Flex templates: Enables teams to package, share, and deploy standardized data pipelines easily.
- Native GCP integration: Integrates seamlessly with Pub/Sub for message ingestion, Cloud Storage for batch inputs, and BigQuery for analytical storage.
Why this is optimal:
Dataflow is purpose-built to run Apache Beam data processing pipelines in a fully managed, serverless environment. It eliminates cluster maintenance overhead while providing low-latency stream transformations and cost-effective batch execution.
BigQuery
BigQuery
What BigQuery is:
BigQuery is Google Cloud's serverless, highly scalable enterprise data warehouse designed for business agility and analytical SQL queries across petabytes of structured and semi-structured data.
Why it doesn't meet the requirement:
- Not an Apache Beam execution runner (✗): BigQuery does not execute arbitrary programmatic data pipelines built with the Apache Beam SDK in languages like Java, Go, or Python.
- SQL-focused transformation: While BigQuery supports powerful SQL-based transformations (ELT workflows) and continuous queries, it is a data warehouse and query engine rather than a general-purpose stream processing runtime.
- Streaming transformation limits: BigQuery is primarily a storage and analysis destination rather than an intermediate stream-processing engine for custom sensor transformations before loading.
Key characteristics and limitations:
- Operates primarily using ANSI SQL and BigQuery ML.
- Provides high-throughput streaming inserts and storage optimizations.
- Excels at large-scale analytical queries, aggregations, and business intelligence reporting.
- Lacks programmatic distributed execution constructs such as
DoFnand pipeline graphs found in Apache Beam.
This answer would be correct if:
The scenario required a serverless data warehouse to store structured analytical data and perform SQL-based transformations, reporting, or business intelligence queries using tools like Looker.
Cloud Composer
Cloud Composer
What Cloud Composer is:
Cloud Composer is a fully managed workflow orchestration service built on Apache Airflow. It is designed to author, schedule, and monitor multi-step data pipelines and dependencies across hybrid and multi-cloud environments.
Why it doesn't meet the requirement:
- Workflow orchestrator, not data processing engine (✗): Cloud Composer manages task scheduling and triggers across systems (Directed Acyclic Graphs, or DAGs); it does not process or transform high-throughput streaming data streams itself.
- No real-time stream processing: Airflow tasks run on scheduled intervals (e.g., hourly, daily) and cannot handle continuous event-by-event streaming workloads.
- Does not execute Apache Beam code: While Composer can trigger a Dataflow job as an orchestration task, it is not the compute runner that processes Apache Beam pipelines.
Key characteristics and limitations:
- Built on Apache Airflow and uses Python-based DAG definitions.
- Coordinates jobs across multiple cloud services (e.g., triggering BigQuery queries, Cloud Storage transfers, and Dataproc jobs).
- Not designed for data-in-flight computations or processing high-velocity IoT streams.
This answer would be correct if:
The requirement focused on scheduling complex, multi-service batch dependencies and orchestrating when different jobs, tasks, and data transfers run.
Dataproc
Dataproc
What Dataproc is:
Dataproc is a managed service for running open-source big data processing ecosystems, specifically Apache Hadoop, Apache Spark, Apache Hive, and Presto clusters.
Why it doesn't meet the requirement:
- Targeted for Hadoop/Spark ecosystems (✗): Dataproc is designed to run Spark and Hadoop jobs rather than serving as the native, managed Google Cloud execution environment for Apache Beam pipelines.
- Cluster management overhead: Dataproc typically requires configuring, sizing, and managing VM clusters (even with autoscaling), unlike the fully serverless execution paradigm of Dataflow.
- Different programming abstraction: Dataproc relies on Spark RDDs/DataFrames and MapReduce workflows rather than the unified Apache Beam pipeline model.
Key characteristics and limitations:
- Best suited for migrating legacy on-premises Hadoop and Spark workloads to the cloud.
- Provides fine-grained control over underlying compute instances, open-source libraries, and cluster configurations.
- Requires cluster lifecycle monitoring and software configuration management.
This answer would be correct if:
The team had existing PySpark or Spark Streaming applications and needed a managed Hadoop/Spark environment to run them with minimal refactoring.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 1,156 practice questions across all 4 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
FundamentalAssociate Data Practitioner
Cloud Dataflow GPU Acceleration
Choose products required to implement basic transformation pipelines
FundamentalAssociate Data Practitioner
Cloud Data Fusion
Choose products required to implement basic transformation pipelines
FundamentalAssociate Data Practitioner
Analytics Hub
Determine when to share data using Analytics Hub
FundamentalAssociate Data Practitioner
LookML Sum Measure
Manipulate simple LookML parameters to modify a data model
FundamentalAssociate Data Practitioner
BigQuery Data Transfer Service
Load data into Google Cloud storage systems using the appropriate tool (e.g., gcloud and BQ CLI, Storage Transfer Service, BigQuery Data Transfer Service, client libraries)
FundamentalGenerative AI Leader
Customer Data Model Training Exclusion
Describing how various data types are used in gen AI and the business implications
Last updated