Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
High Availability and Failover Design on Google Cloud
Automated traffic management and health monitoring is the combination of load balancing, health checking, and self-healing compute that keeps applications reachable without manual action. In Google Cloud, Cloud Load Balancing (opens in a new tab) steers client traffic to healthy backends, health checks decide which backends can receive traffic, and Compute Engine managed instance groups (MIGs) (opens in a new tab) replace failed virtual machines (VMs) and adjust capacity. Together they let traffic flow from clients to surviving zones or regions when hardware, software, or location failures occur.
Global and Regional Load Balancing for Automated Failover
Cloud Load Balancing is the service that distributes traffic across backends so no single VM, zone, or region becomes a single point of failure. A forwarding rule defines one entry point using an external IP address, and the load balancer spreads requests from that entry point across the configured backends. When a backend or location becomes unreachable, the load balancer automatically steers traffic to the remaining healthy capacity.
Regional and global load balancing divide this work by scope. Regional load balancing spreads traffic across VMs in all zones within one region, typically using regional MIGs as backends. Global HTTP(S) load balancing places backends in multiple regions, lets traffic enter Google Cloud at the location nearest the client, and provides cross-regional redundancy while the service remains reachable on the same external IP address.
| Option | Traffic scope | Failover behavior |
|---|---|---|
| Regional load balancer | Spreads traffic across VMs in multiple zones within one region through a regional forwarding rule | Survives zone failure inside the region; cross-region recovery uses Cloud DNS (opens in a new tab) routing to point clients to the load balancer in the failover region |
| Global load balancer | Receives traffic at the edge nearest the client and distributes it across regions | Automatically diverts traffic to another region if a region is unreachable, keeping the same external IP address |
Choose a regional load balancer when the goal is resilience across zones inside one region, and choose a global load balancer when the goal is automatic steering across regions without changing the client-facing address.
Health Checks and Continuous Traffic Steering
Health checks are the monitoring signals that tell Cloud Load Balancing which VMs can safely receive requests. Traffic flows from the client to the forwarding rule, then from the load balancer to backend VMs that pass health checks, and away from VMs that fail them. If some but not all application VMs fail, the application stays available because the load balancer forwards requests only to the responsive VMs.
Health-Check Traffic Steering Flow
Process Flow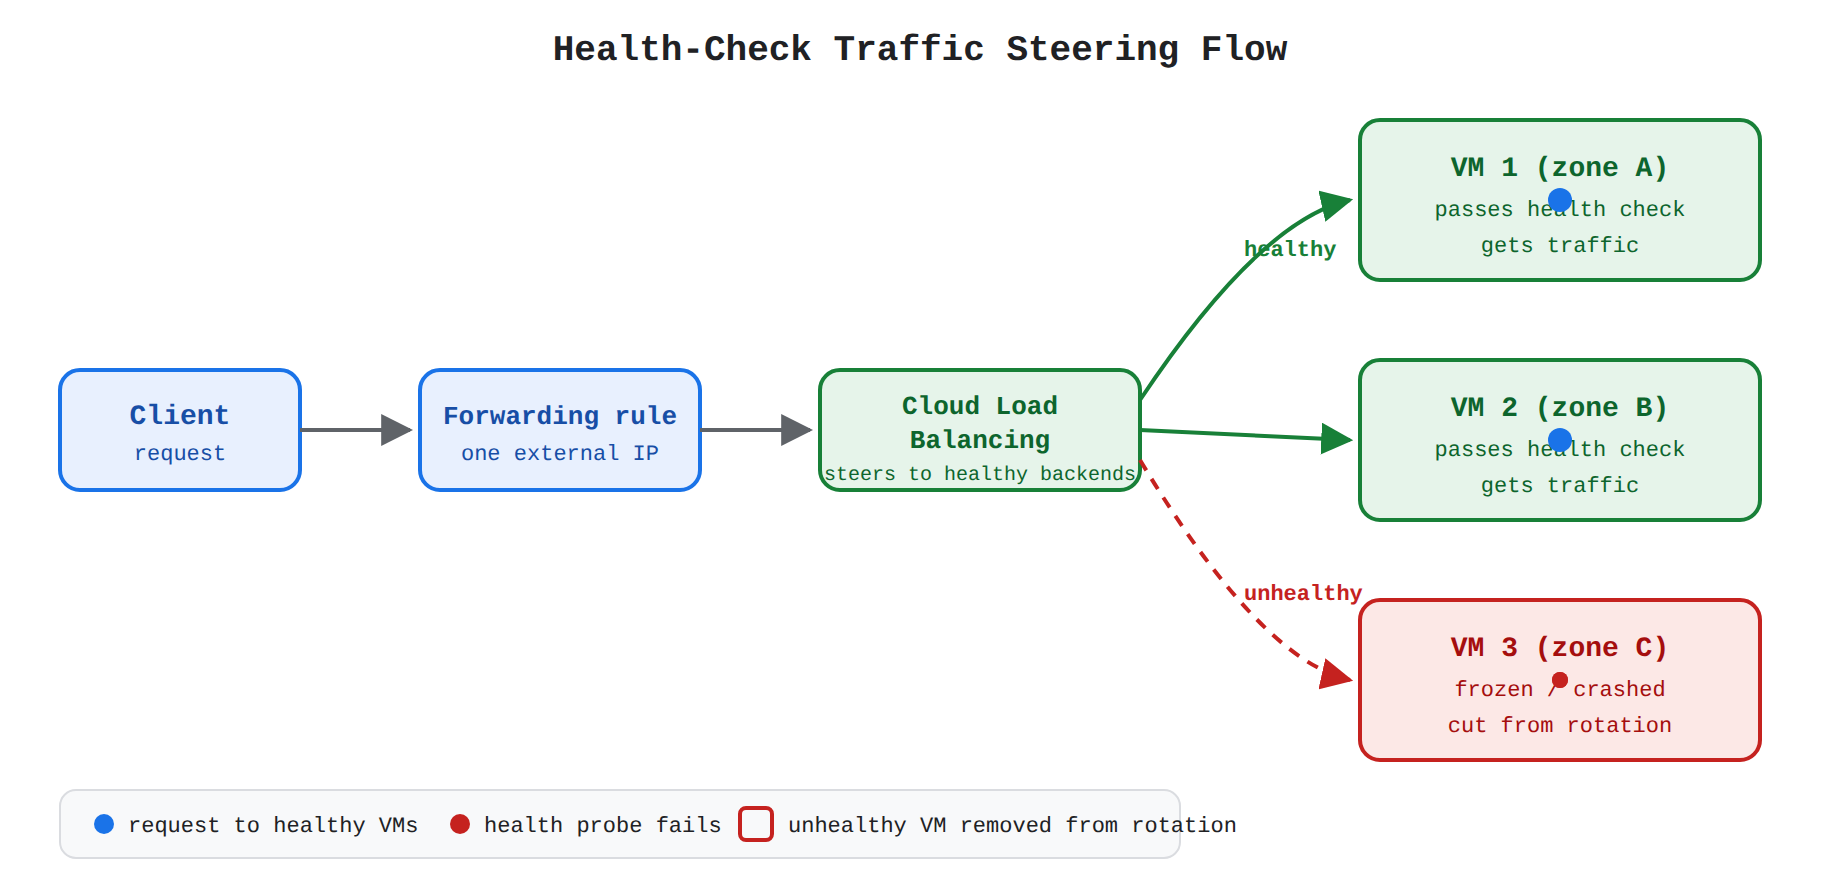
A process flow showing a client request passing through a forwarding rule and Cloud Load Balancing to three backend VMs. Health checks probe each VM; the two healthy VMs receive animated request traffic while the unhealthy VM is cut from rotation.
Health checking covers both VM failure and application failure. A stopped or unreachable VM is removed from rotation, and a VM that is still running but has a frozen, crashed, or out-of-memory application also stops responding to health checks and stops receiving new traffic. This separation matters for recovery: business-critical request handling depends on the load-balancing data plane continuing to steer around unhealthy backends, not on management operations such as creating VMs or updating permissions.
Exam tip: A global load balancer keeps the same external IP address during automatic cross-region failover, while a regional load balancer in a failover region requires a Cloud DNS routing change to send clients to the new region.
Managed Instance Groups with Autohealing and Autoscaling
Compute Engine managed instance groups (MIGs) are homogeneous groups of identically configured VMs that work with Cloud Load Balancing to provide redundant capacity. A regional MIG distributes its VMs across multiple zones within a single region, so the group and its load balancer can continue serving traffic when one zone has issues. The group depends on an instance template for consistent VM configuration, which lets the system recreate any failed member the same way every time.
MIGs provide two self-correcting behaviors that depend on monitoring signals. Autohealing performs health checking and automatically deletes and recreates unhealthy VMs, so failed hardware or software is replaced without an operator rebuilding the VM. Autoscaling increases or decreases the number of VMs based on specific demand signals, so spikes in traffic add capacity and quiet periods remove it. During replacement, the load balancer keeps steering traffic to the remaining healthy VMs, and the new VM rejoins rotation only after it passes health checks.
Regional and zonal redundancy strategies are the practice of placing copies of compute and storage in different failure boundaries so no single zone or region outage stops the application. Google Cloud is designed to support a target availability of 99.9% for a single-zone deployment, 99.99% for a multi-zone deployment, and 99.999% for a multi-region deployment. Google Cloud intends to offer a minimum of three physically and logically distinct zones in every general-purpose region, and zones in the same region are designed to minimize the risk of correlated failure with each other.
Resource Scopes in Google Cloud
Resource scope in Google Cloud defines which outage a resource can survive, based on where its copies run. Compute Engine (opens in a new tab) VMs are zonal resources that run in one zone, so a zone outage can make those VMs unavailable for the duration of the interruption. Cloud Storage (opens in a new tab) regional buckets, regional Persistent Disk volumes, regional MIGs, VPC subnets, regional external Application Load Balancers, regional Spanner instances, and Cloud Run services are regional resources that are redundantly deployed across multiple zones in one region, which gives them higher availability than zonal resources.
Multi-regional and global resources extend redundancy beyond one region. Managed multi-regional resources such as multi-region Cloud Storage buckets, multi-region Spanner instances, Firestore, and BigQuery are distributed within and across regions and are designed to keep functioning after the loss of a single region. Global resources such as VPC networks with routes and firewall rules, Cloud DNS zones, global external Application Load Balancers, Pub/Sub topics, and Identity and Access Management (IAM) policies do not depend on infrastructure in any single region and are resilient to zonal and regional incidents.
Removing Single Points of Failure
A single point of failure (SPOF) is any application component that depends on one infrastructure resource, so failure of that resource makes the whole stack unavailable. A typical content-serving stack has a web tier with a load balancer and web servers, an application tier with application servers, and a data tier for persistence. In an example stack with one load balancer, two web servers, one application server, and one database, the load balancer, application server, and database are each SPOFs because failure of any one of them causes user requests to fail.
SPOFs are removed by distributing resources across locations and deploying redundant resources with adequate capacity in each tier. Traffic flows from the load balancer to healthy backends, so if one web or application instance fails, the load balancer forwards requests to the remaining instances in other zones or regions. If a VM crashes, a regional MIG automatically creates a new VM to maintain the configured minimum count. A global load balancer can be accepted as a logical SPOF because of defense-in-depth controls, but changes to it must be managed carefully because a configuration error can affect all geographies.
Regional Strategies for Zone Resilience
Regional strategies protect against a zone outage by composing multiple zones inside one region, so service continues from another zone when one zone is interrupted. A regional MIG runs identical VMs from an instance template across multiple zones, and regional Persistent Disk provides synchronous replication of data across two zones in the region. Regional load balancers are regional resources that are resilient to zone outages, while individual zonal VMs behind them might be affected.
Data flow in a regional design stays inside the region, which keeps latency low between components and avoids cross-region transfer costs. For zonal resources that cannot replicate themselves, the application owner must build the redundancy by routing traffic with Cloud Load Balancing health checks, scaling identical VMs across zones with MIGs, or using regional Persistent Disk for synchronous cross-zone replication. After a zone outage is resolved, the operator must verify that the application runs as expected in all zones where it is deployed.
Regional strategies do not survive a region outage, so they fit workloads that must withstand zone loss but can tolerate downtime from region loss. Examples include:
- Regional MIGs and regional Google Kubernetes Engine (GKE) clusters with multi-zone configuration for compute
- Regional Persistent Disk and regional Cloud Storage buckets for zonal data replication
- App Engine applications and Cloud Run services that run redundantly across zones
- Regional external Application Load Balancers and VPC subnets for networking
- Cloud SQL high availability (HA) with a primary database synchronously replicated to a standby in another zone and automatic failover on primary-zone failure
Multi-Regional Strategies for Region Resilience
Multi-regional strategies protect against an extended loss of an entire region by keeping independent stacks or replicated data in more than one region. Managed multi-regional storage removes the need to build replication, because Google handles distribution across regions. Dual-region and multi-region Cloud Storage buckets are single buckets that store data and metadata redundantly across regions and operate active-active, so reads and writes can occur in more than one region while the bucket remains strongly consistent.
Replication timing controls data loss, which is measured as recovery point objective (RPO). Metadata in dual-region and multi-region buckets is written synchronously across regions, while object data is replicated asynchronously within an RPO window. Newly written objects start as regionally protected across zones, then become geo-redundant after replication completes, so data written inside the RPO window may be inaccessible or lost if the source region is physically destroyed. Turbo replication is a premium feature for dual-region buckets that targets replication of 100% of newly written objects within 15 minutes.
When managed multi-regional storage is not used, the application owner must replicate or back up data to another region. Supported patterns are snapshotting zonal or regional data to a multi-region resource such as Cloud Storage, Firestore, Datastore, or Spanner, or managing self-owned replication to one or more other regions. For compute, the pattern is to run zonal or regional resources such as Compute Engine or App Engine in the primary region and manually or automatically bring up the application in another region on regional failure, referring to copies of primary data. A multi-region Spanner instance with multi-region configuration is resilient to both zone and region outages without that manual restore step.
Choosing Between Regional and Multi-Regional Deployments
The choice between regional and multi-regional deployments is a tradeoff between availability, cost, latency, operations, and data residency. Distributed architectures provision more resources, generate more cross-location network traffic, and store more replicated copies, so cost and operational complexity are higher. A single-region design keeps inter-resource traffic inside the region for low-latency, high-bandwidth communication needed by workloads such as batch computing, and it avoids cross-region data transfer costs.
| Deployment | Availability target | Choose when |
|---|---|---|
| Single-zone | 99.9%, about 8.75 hours downtime per year | The workload can tolerate downtime or can be redeployed elsewhere with minimal effort |
| Multi-zone or regional | 99.99%, about 52 minutes downtime per year | The workload must survive zone outages but can tolerate some downtime from region outages, needs low latency to nearby users, or must keep data in one region |
| Multi-region | 99.999% | The workload is business-critical and high availability (HA) is essential, such as retail and social media applications |
Data residency often favors a regional deployment. A single-region topology helps meet requirements that user data be stored and accessed only in data centers physically located in a specific area, for example by running the application in a Google Cloud region in Europe. Multi-regional services optimize availability, performance, and resource efficiency together, so each product trades off either latency or consistency model, and cross-region replication adds latency and cost.
Exam tip: Regional resources survive a zone outage but not a region outage, while managed multi-regional resources are designed to survive the loss of a single region.
Data persistence and disaster recovery planning is the practice of keeping stateful data durable, available, and recoverable after zonal, regional, or data-corruption events. Recovery is measured with recovery time objective (RTO), which is how long data can stay unavailable, and recovery point objective (RPO), which is how much data written before the incident can acceptably be lost. Synchronous replication favors low RPO by confirming writes in multiple locations, while asynchronous replication favors distance and cost but leaves a replication lag that affects RPO and RTO.
Replication Strategies and RTO and RPO
Replication strategy determines how data flows from a primary write location to redundant copies and how failover preserves integrity. Firestore (opens in a new tab) in regional mode synchronously replicates data across at least three zones, while Firestore in multi-region mode synchronously replicates across five zones in three regions with two serving regions and one witness region. Firestore handles this replication automatically with no extra configuration, and multi-region databases provide 99.999% availability compared with 99.99% for regional databases.
Asynchronous replication copies data after the initial write is confirmed, so recent writes can be inaccessible or lost if a region fails before replication finishes. Cloud Storage (opens in a new tab) confirms an object write after it is redundantly stored in one initial region across at least two zones, then asynchronously replicates it to a second geographic place for dual-region and multi-region buckets. Default replication is designed to replicate 99.9% of newly written objects within one hour and 100% within 12 hours, while turbo replication on dual-region buckets is designed to replicate 100% of newly written objects within an RPO of 15 minutes. Bigtable also replicates asynchronously across zones within a region, where a production instance has a minimum of two clusters in unique zones and Google automatically synchronizes a separate copy in each cluster zone so traffic can fail over to another cluster in the same instance.
Cloud Storage Redundancy and Recovery
Cloud Storage persistence is controlled by bucket location type, which defines where data at rest lives and how it survives outages. Regional buckets store data redundantly in at least two zones in the selected region and tolerate loss of any one zone without changing storage paths. Dual-region buckets store data in two specific regions chosen by the owner, while multi-region buckets store data in data centers chosen by Cloud Storage within the multi-region boundary and separated by at least 100 miles. Dual-region and multi-region buckets use an active-active design based on a single bucket, so Cloud Storage serves objects from an available region with a designed RTO of zero and no manual failover to a secondary bucket.
When strict RTO and RPO require high confidence that a copy exists in another region, two single-region buckets can be used with either dual-write of each object or write to one bucket followed by a Cloud Storage copy to the second bucket. Cross-bucket replication provides another asynchronous path by copying new and updated objects from a source bucket to a destination bucket in a different location using Storage Transfer Service with Pub/Sub notifications of changes. The source and destination remain independent buckets with their own location, encryption, access, and storage class.
Cross-bucket replication is especially suitable when independent copies are needed for:
- Data sovereignty across geographically distant regions
- Maintaining separate development and production versions with distinct namespaces
- Sharing data with a bucket owned by a vendor or partner
- Aggregating data from different buckets into one bucket for analytics
- Managing cost, security, and compliance under different ownerships, storage classes, and retention periods
Exam tip: Turbo replication applies only to dual-region buckets with a 15-minute RPO, while default replication targets 99.9% of objects within one hour and 100% within 12 hours.
Stateful Database Failover and Recovery
Stateful database recovery combines continuous replication for outages with backups and point-in-time recovery (PITR) for corruption, deletion, or regional loss. Cloud SQL uses automated backups with binary logging to perform point-in-time recovery to a fresh Cloud SQL instance, and it uses a high availability (HA) configuration with cross-region replicas to stay online during zonal or regional failure. Cloud SQL Enterprise Plus edition adds advanced disaster recovery (DR) that simplifies recovery and fallback with zero data loss after a cross-regional failover. Spanner supports full export to Avro files in Cloud Storage with re-import through Dataflow templates, incremental backup selection with commit timestamps, and managed Spanner Backup and Restore with consistent backups retained up to one year.
Spanner restore from a managed backup has a lower RTO than export-based restore because the restore mounts the backup directly without copying data. The speed of Dataflow-based export and re-import depends on the number of configured Spanner nodes, which directly affects RTO, so a warm standby Spanner instance with the minimum nodes for storage and throughput can be kept for small RTO values. Spanner PITR recovers data from up to seven days in the past after an operator error or bad application rollout. BigQuery (opens in a new tab) replicates data to two zones in a single region, so corruption still requires a separate recovery plan, including cross-region dataset replication or managed disaster recovery with slots provisioned in a second location for hard regional loss.
For BigQuery table corruption or accidental change, recovery depends on how quickly the problem is found:
- Query the table to a point in time within seven days using time travel or snapshot decorators
- Export uncorrupted data and create a new table that excludes corrupted rows
- Store data in time-partitioned tables so only a subset must be restored
- Keep periodic copies of the dataset, including copies in another region for regional failure
- Keep original data in Cloud Storage so a new table can be reloaded and applications can point to it
Firestore protects infrastructure outages with automatic synchronous replication and protects data errors with scheduled backups and PITR used together when needed:
| Recovery option | Retention and granularity | Restore behavior |
|---|---|---|
| Scheduled backups | Daily or weekly backups retained up to 14 weeks | Restore to a new Firestore database in the same project at lower cost than PITR data |
| PITR reads | Up to seven days in the past at one-minute granularity with RTO of 0 and RPO of one minute | Surgically read and write back only the needed documents with lower RTO and RPO than backups |
| PITR exports and clone | Export stored indefinitely in Cloud Storage; clone up to seven days with PITR or one hour without PITR | Archive beyond 14 weeks, but recovery from an export is generally more expensive than from a backup |
Encryption Keys and Locality Controls for Recovery
Locality and key controls determine where persistent data is allowed to exist and whether it can be decrypted during failover. The Organization Policy Service applies centralized constraints across the resource hierarchy, including location-restricted resources that allow or deny multi-regions, regions such as us-east1, or zones such as europe-west1-b. Filestore (opens in a new tab) supports these requirements by deploying managed file storage in specific regions and zones, and Cloud Storage and BigQuery datasets can be constrained to single-region or regional locations with backups kept outside the same multi-region scope.
When access rather than geography is the restriction, Cloud External Key Manager (Cloud EKM) encrypts BigQuery and Compute Engine data with keys stored in a third-party system outside Google infrastructure. Customer-supplied encryption keys (CSEK) protect Cloud Storage and Compute Engine data by wrapping Google-generated keys, but Google does not permanently store a CSEK and purges the key from its servers after each operation. The external key manager therefore needs its own high availability (HA) and recovery processes for latency and reliability, and planning centers on RTO because data cannot be safely written or decrypted without the keys.
Key Facts
- Cloud Load Balancing steers traffic only to backends that pass health checks, and a global load balancer keeps the same external IP address when it automatically diverts traffic to another region.
- Compute Engine managed instance groups (MIGs) use autohealing to delete and recreate unhealthy VMs and use autoscaling to adjust VM count based on demand signals.
- Regional resources survive a zone outage but not a region outage, while managed multi-regional resources are designed to survive the loss of a single region.
- Dual-region and multi-region Cloud Storage buckets use an active-active single-bucket design with a designed recovery time objective (RTO) of zero, with turbo replication targeting 100% of new objects within 15 minutes for dual-region buckets.
- Firestore in multi-region mode synchronously replicates across five zones in three regions and provides 99.999% availability, while Firestore point-in-time recovery (PITR) supports reads up to seven days in the past with an RTO of 0 and an RPO of one minute.
Frequently Asked Questions
What is the difference between regional Cloud Load Balancing and global Cloud Load Balancing for automatic failover?
A regional load balancer spreads traffic across virtual machines (VMs) in multiple zones within one region through a regional forwarding rule and survives a zone failure inside the region, while cross-region recovery requires Cloud DNS routing to point clients to the load balancer in the failover region. A global HTTP(S) load balancer receives traffic at the edge nearest the client and distributes it across regions, automatically diverting traffic to another region if a region is unreachable while keeping the same external IP address.
How do Cloud Load Balancing health checks and Compute Engine managed instance groups (MIGs) handle unhealthy virtual machines (VMs)?
Health checks tell Cloud Load Balancing which virtual machines (VMs) can safely receive requests, so traffic flows only to backends that pass health checks and away from stopped VMs or VMs with frozen, crashed, or out-of-memory applications. Compute Engine managed instance groups (MIGs) use autohealing to automatically delete and recreate unhealthy VMs from an instance template and use autoscaling to adjust VM count based on demand signals, with replacement VMs rejoining rotation only after they pass health checks.
When should I choose a regional Google Cloud deployment instead of a multi-regional Google Cloud deployment?
Choose a multi-zone or regional deployment when the workload must survive zone outages but can tolerate some downtime from region outages, needs low latency to nearby users, or must keep data in one region, with a target availability of 99.99% or about 52 minutes downtime per year. Choose a multi-region deployment when the workload is business-critical and high availability (HA) is essential, such as retail and social media applications, with a target availability of 99.999%.
How do Cloud Storage dual-region buckets and Firestore multi-region databases handle replication and recovery?
Cloud Storage dual-region and multi-region buckets use an active-active single-bucket design that stores data and metadata redundantly across regions and serves objects from an available region with a designed recovery time objective (RTO) of zero, where metadata is written synchronously and object data is replicated asynchronously with default replication targeting 99.9% of new objects within one hour and 100% within 12 hours and turbo replication for dual-region buckets targeting 100% within 15 minutes. Firestore in multi-region mode synchronously replicates across five zones in three regions and provides 99.999% availability compared with 99.99% for regional databases, while point-in-time recovery (PITR) supports reads up to seven days in the past with an RTO of 0 and a recovery point objective (RPO) of one minute.
Sample Question
An enterprise is deploying a mission-critical relational database on Google Cloud using Cloud SQL for MySQL. The database design must meet the following disaster recovery and availability requirements:
- Provide automated failover with zero data loss (RPO = 0) and minimal downtime during an unexpected zonal outage in the primary region.
- Provide business continuity and disaster recovery capabilities in a secondary region with low RTO and RPO in the event of an entire regional failure.
- Maintain architectural simplicity by using managed Google Cloud native replication mechanisms.
Which database architecture should you implement?
How learners score on this domain
Last updated