Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Google Cloud Well-Architected Framework Pillars
Operational Excellence and Reliability Strategies are two pillars of the Google Cloud Well-Architected Framework (opens in a new tab) that keep workloads healthy, observable, and able to stay online through failure. Operational excellence means efficiently deploying, operating, monitoring, and managing workloads, while reliability means designing and operating workloads that stay resilient and highly available. Together they require automation of routine work, continuous monitoring of behavior, and disaster recovery planning tied to clear recovery goals.
The framework provides validated recommendations for secure, efficient, resilient, high-performing, cost-effective, and sustainable topologies. The recommendations apply to cloud-first workloads, migrated on-premises workloads, hybrid deployments, and multi-cloud environments. The framework organizes guidance into pillars and cross-pillar perspectives:
- Operational excellence: efficiently deploy, operate, monitor, and manage workloads
- Security, privacy, and compliance: maximize security, design for privacy, and align with regulatory requirements
- Reliability: design and operate resilient and highly available workloads
- Cost optimization: maximize business value of the Google Cloud investment
- Performance optimization: design and tune resources for optimal performance
- Sustainability: build and manage energy-efficient and carbon-aware workloads
A pillar provides principles for one non-functional area such as operations or reliability, while a perspective provides a cross-pillar view for a specific technology or sector such as AI and ML or financial services.
Operational Excellence Through Automation and Monitoring
Operational excellence is the discipline of deploying, operating, monitoring, and managing workloads in a consistent and efficient way. Operationally excellent architectures use automation instead of repeated manual steps, so deployments, configuration changes, and operational responses happen the same way every time. Continuous monitoring provides visibility into workload health, which lets teams detect problems early, respond quickly, and keep operations stable as systems change.
Operational excellence also depends on designing for change and documenting the architecture. Designing for change means delivering small changes regularly and getting fast feedback on each change. Teams can use DevOps Research and Assessment (DORA) software delivery metrics to monitor the speed, ease, and safety of making changes, which builds trust with stakeholders and operators. Documenting the architecture establishes a common language and standards, so cross-functional teams can visualize current deployments, communicate effectively, and collaborate as the system evolves.
Reliability Through Resilient Design
Reliability is the ability to design and operate workloads that remain resilient and highly available through inevitable failures. Reliable design starts from planning for failure, because natural disasters, fiber cuts, and complex infrastructure failures will cause outages even on extremely reliable infrastructure. Google designs data centers with redundancies across power, cooling, and networks, failure mode and effects analysis (FMEA) plans, and modeled availability targets, and actual measured availability normally exceeds design targets by a comfortable margin.
Reliability planning shifts focus from individual components to product-level reliability metrics. At cloud scale, virtualization spreads services across many components, so architects plan around the stated reliability of Google Cloud products rather than the failure modes of cooling, power delivery, or single servers. Recovery Time Objective (RTO) and Recovery Point Objective (RPO) translate business tolerance for downtime and data loss into infrastructure choices. Many Google Cloud products include built-in disaster recovery (DR) (opens in a new tab) mechanisms that help applications perform predictably through outages.
Exam tip: Availability is the ability for a product to be meaningfully accessed and used over time, while reliability is broader and includes availability plus attributes such as durability and correctness.
Core Principles That Support Health and Uptime
Core principles of the Well-Architected Framework support both operational excellence and reliability by making systems easier to change, operate, and recover. Simplified, decoupled, and stateless designs are easier to automate, monitor, and recover because a failure or update in one part has less impact on the rest of the system. Small, frequent changes with fast feedback reduce the risk of each release, while clear documentation keeps teams aligned on how the system is built and operated.
The core principles emphasized by the framework are:
- Design for change: deliver small changes regularly and use fast feedback to improve speed, ease, and safety
- Document your architecture: maintain clear, useful, and current documentation that supports visualization and collaboration
- Simplify your design and use fully managed services: reduce operational burden by relying on managed capabilities where possible
- Decouple your architecture: limit tight dependencies so parts can change and fail independently
- Use a stateless architecture: separate state from compute so components are easier to replace and scale
Planning Disaster Recovery for Infrastructure Outages
Disaster recovery planning for infrastructure outages defines how workloads survive loss of cloud infrastructure and return to normal operation. A complete DR plan must also address causes such as software bugs and data corruption, but infrastructure-focused design ensures that an outage in a zone or region does not become a prolonged outage for users. Architects categorize applications by desired reliability outcomes, then select deployment patterns and products with built-in DR capabilities that meet the required RTO and RPO.
Recovery choices depend on business and regulatory constraints that cross pillar boundaries. The financial services perspective, for example, recommends a DR strategy that meets data residency requirements, and that residency requirement influences the choice of failover region and consequently the achievable recovery objectives. This relationship shows why reliability targets must be realistic: the allowed locations for data storage and processing constrain where workloads can fail over, which in turn shapes recovery time and data loss limits.
Cost and Performance Optimization Trade-offs are decisions that balance high performance against efficient spending in Google Cloud. The Cost optimization pillar seeks to maximize the business value of investment in Google Cloud, while the Performance optimization pillar seeks to design and tune resources for optimal performance. The Google Cloud Well-Architected Framework (opens in a new tab) treats both pillars as one efficient design, where right-sizing, autoscaling, and choice of resource type let an architecture meet demand without paying for idle capacity.
Balancing Cost, Performance, and Sustainability
The balance between cost and performance is achieved when resources match actual demand over time. Over-provisioning resources leads to unnecessary costs because idle capacity is still billed, while under-provisioning causes performance bottlenecks that affect application performance and user experience. Efficient design also supports the Sustainability (opens in a new tab) pillar, because an application that completes work faster holds compute for a shorter duration and the underlying hardware consumes fewer kilowatt-hours of energy. When teams right-size virtual machines (VMs), implement aggressive autoscaling, archive old data, and eliminate idle resources, they reduce cloud costs and reduce energy consumption at the same time.
Right-Sizing Resources
Right-sizing is the practice of continuously monitoring utilization and adjusting allocation to match actual demand. Cloud Monitoring provides real-time visibility into resource utilization metrics, so teams can track usage patterns and identify inefficiencies across workloads. Data flows from Cloud Monitoring to Recommender, which analyzes utilization history and produces intelligent recommendations for optimizing allocation, such as reducing machine size or changing instance type. Custom metrics extend this flow by tracking application-specific signals, and alerts notify administrators when predefined thresholds are met so administrators can adjust allocation before cost or performance problems escalate.
Right-Sizing Loop: Monitor to Resize
Process Flow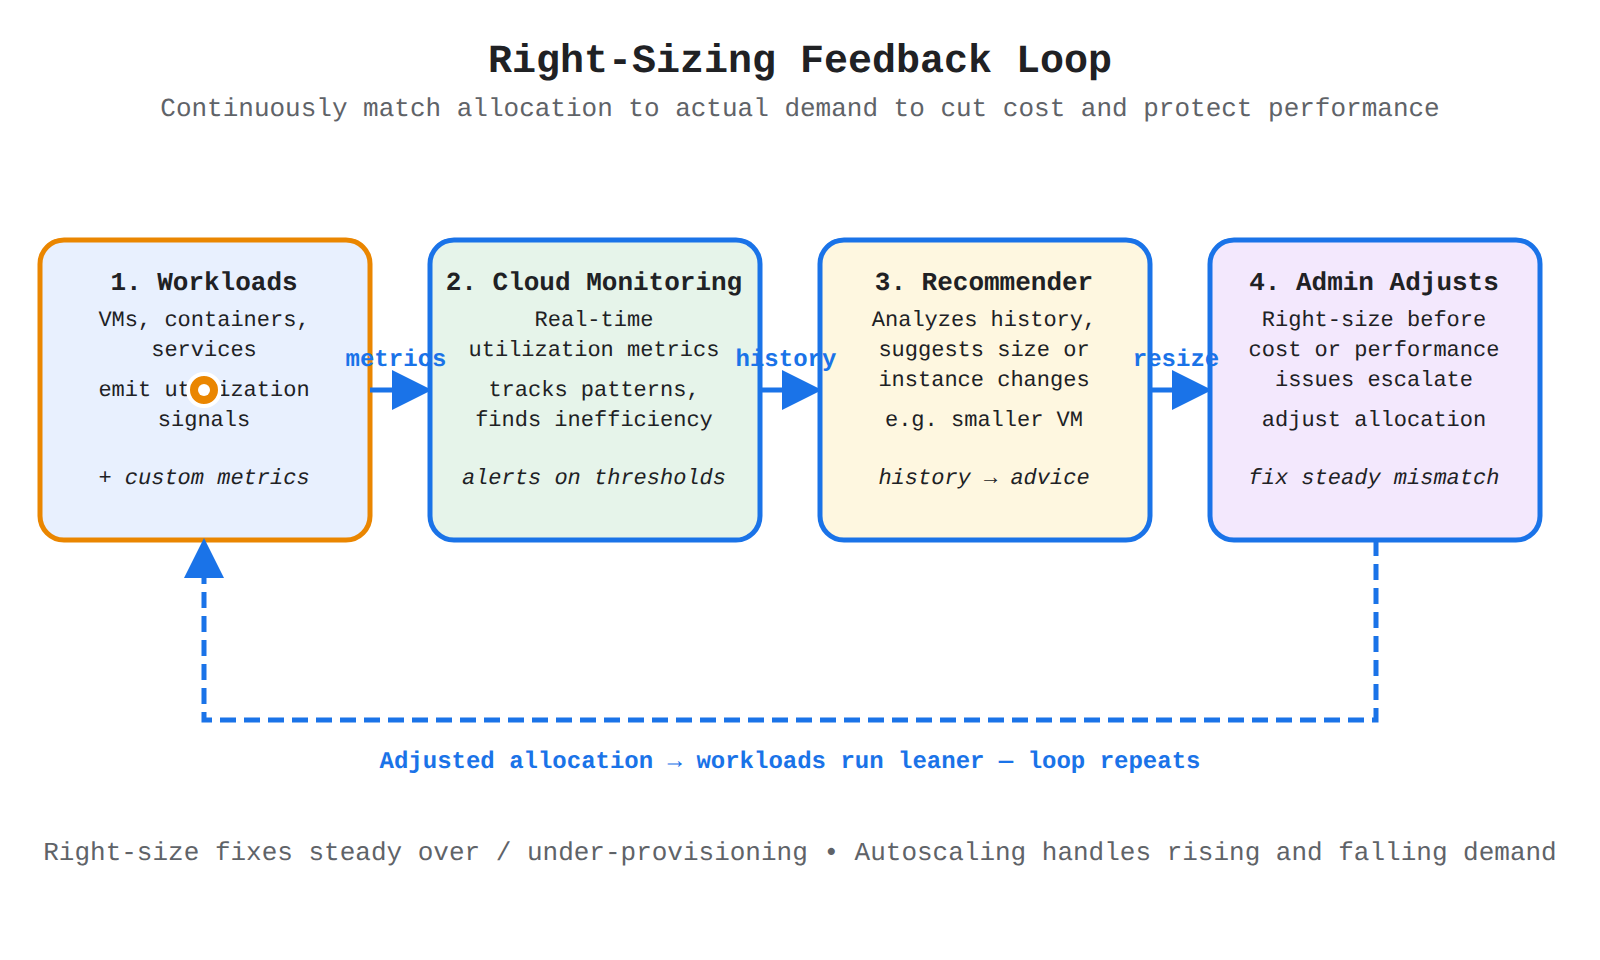
Four boxes in a loop show workloads sending utilization data to Cloud Monitoring, to Recommender, to admin resizing, and back to workloads. A moving dot and sequential highlights show the order of the feedback loop.
Autoscaling to Match Demand
Autoscaling is the ability to dynamically adjust capacity based on workload fluctuations so applications have resources when needed without permanent over-provisioning. An autoscaling policy defines a minimum and maximum capacity and the condition that triggers scaling, and the platform then adds capacity when demand rises and removes capacity when demand falls. This dependency between demand signals, policy thresholds, and provisioned capacity lets infrastructure adapt to rapid growth and diverse workloads while controlling spend. Choose the autoscaling mechanism that matches where the workload runs:
| Option | What it scales | How scaling is triggered |
|---|---|---|
| Compute Engine managed instance groups (MIGs) | Group of VMs managed as a single entity | Policy adds VMs when CPU utilization reaches a threshold and removes VMs when utilization drops |
| Google Kubernetes Engine (GKE) | Cluster nodes and Pod replicas | Cluster Autoscaler, Horizontal Pod Autoscaler, Vertical Pod Autoscaler, and Node Auto-Provisioning respond to Pod demands and usage patterns |
| Cloud Run | Serverless container instances | Built-in autoscaling adjusts instances up as incoming traffic increases and down as traffic decreases |
Google Kubernetes Engine (GKE) autoscaling combines four tools that work together to optimize utilization and simplify cluster management:
- Cluster Autoscaler adds or removes nodes based on Pod resource demands.
- Horizontal Pod Autoscaler changes the number of Pod replicas based on CPU, memory, or custom metrics.
- Vertical Pod Autoscaler fine-tunes Pod resource requests and limits based on usage patterns.
- Node Auto-Provisioning automatically creates optimized node pools for workloads.
Exam tip: Use right-sizing to fix a steady mismatch between allocation and demand, and use autoscaling to handle demand that rises and falls over time.
Selecting Resource Types and Cost Models
Selecting appropriate resource types means simplifying design with fully managed services and matching pricing models to usage stability. Managed and serverless options shift operational work to Google, so Cloud Run runs code without managing infrastructure while GKE automates node and Pod decisions for container workloads. For VMs and steady services, cost models trade commitment and flexibility for lower rates, and pricing models change over time so architectures should be reviewed regularly for better-performing or lower-cost alternatives:
- Committed use discounts (CUDs) are discounts for committing to a certain level of usage over a period of time.
- Sustained use discounts in Compute Engine provide discounts for consistent usage of a service.
- Spot VMs provide access to unused VM capacity at a lower cost compared to regular VMs.
Cloud Billing and Cost Management tools support these choices with budgets and alerts that track spending and warn when budgets are exceeded. Tagging and labeling extend tracking by assigning projects, departments, or other dimensions to resources, so spending patterns can be analyzed by owner and high-usage areas can be found. Together, efficient resource types, the right discount model, and clear cost visibility let architects protect performance for critical peaks while reducing waste during quiet periods.
Security, Privacy, and Compliance Integration is the practice of building protection, privacy, and regulatory requirements into every stage of a cloud architecture. In the Google Cloud Well-Architected Framework (opens in a new tab), this work is guided by the Security, privacy, and compliance pillar (opens in a new tab), which recommends designing workloads that maximize security of data and workloads, design for privacy, and align with regulatory requirements and standards. The pillar applies to cloud-first workloads, migrated on-premises workloads, and hybrid and multi-cloud environments, and it requires collaboration across security architects, developers, DevSecOps teams, and compliance and risk managers.
Shared Responsibility Between Google and Customers
The shared responsibility model (opens in a new tab) defines how security ownership is divided between Google and the customer. Google secures the underlying cloud infrastructure, physical facilities, and foundational services, while the customer secures the data, applications, identities, configurations, and access controls placed in Google Cloud. The exact boundary shifts with the service type, so a customer using infrastructure as a service (IaaS) retains more operating-system and middleware responsibility than a customer using platform as a service (PaaS) or software as a service (SaaS).
Google extends shared responsibility into shared fate, where Google provides tools and programs that actively help customers meet their side of the model. These supports include deployable security blueprints with infrastructure as code, Assured Workloads for compliance obligations, Security Command Center for threat monitoring and response, organization policies for hierarchy-wide governance, and the Risk Protection Program with Cyber Insurance Hub for data-driven risk insight. To put the model into practice, architects translate workload types and regulatory needs into concrete controls:
- List each workload and whether it uses IaaS, PaaS, or SaaS to identify required customer controls.
- List regulatory requirements such as HIPAA or GDPR and map them to resources in the compliance resource center.
- Select Architecture Center blueprints and landing zone guidance to define resource hierarchy, identity onboarding, key management, and network structure.
- Deploy workloads with blueprint automation, then verify posture with Cyber Insurance Hub, Assured Workloads, Policy Intelligence tools, and Security Command Center.
Least Privilege Access Through Identity and Access Management (IAM)
Least privilege access through Identity and Access Management (IAM) (opens in a new tab) means every user, device, and service receives only the permissions needed to perform its task and no more. The Google Cloud Well-Architected Framework enforces this through zero trust, a never trust, always verify approach where no request is trusted because of network location and every access attempt is explicitly authenticated, authorized, and continuously verified. This model reduces blast radius because a compromised identity cannot move laterally to resources outside its narrow grant.
Verification flows from a central identity to the resource through context-aware checks and detailed logging. Customers federate an existing identity provider such as Active Directory to Google Cloud for single sign-on, or use Cloud Identity Premium or Google Workspace when no provider exists, so one identity system governs all access. Requests then pass policy checks based on user role, device posture, and location before Identity-Aware Proxy (IAP) or resource-level IAM allows the connection, and audit logs flow to Security Command Center Enterprise or Google Security Operations for analysis and threat detection.
Strong least-privilege controls depend on disciplined identity operations:
- Grant service accounts only the roles required for their designated tasks and use Workload Identity Federation for applications on Google Kubernetes Engine (GKE) or outside Google Cloud.
- Require single sign-on for users and multi-factor authentication for privileged accounts, including options such as Titan Security Keys, and use OAuth 2.0 or signed JSON Web Tokens for workload authentication.
- Avoid overprovisioning, enforce separation of duties, consider just-in-time privileged access for sensitive operations, and review role grants regularly for policy violations.
- Enable audit logging for administrator and data access and set retention policies that balance security needs with storage cost.
Exam tip: Google secures the cloud platform itself, while the customer always secures identities, data, and configuration — and responsibility grows as you move from SaaS toward IaaS.
Data Protection and Regulatory Compliance
Data protection and regulatory compliance ensure that data stays encrypted, contained, and stored in approved locations while meeting privacy laws and industry standards. Protection covers data in three states: data at rest in storage, data in transit across networks, and data in use during processing. Controls for these states combine encryption, access policy, network perimeters, and discovery, so a failure in one layer does not expose sensitive information.
In Google Cloud, traffic and storage controls work together to enforce that model. VPC Service Controls establishes a secure perimeter around sensitive APIs and services to prevent data exfiltration, while strict egress firewall rules restrict internet-bound traffic and Cloud Key Management Service (Cloud KMS) manages encryption keys for stored data. Sensitive Data Protection discovers and classifies sensitive data, IAM controls who can reach it, and Confidential Computing encrypts data while virtual machines process it. Together, the perimeter contains where API calls can go, the key service controls how stored data can be decrypted, and the identity policy controls who can request either action.
Compliance enforcement turns legal requirements into technical guardrails that prevent noncompliant deployments. Assured Workloads helps configure regulated environments, Organization Policy Service applies constraints across the organization, folder, and project hierarchy, and the compliance resource center maps Google certifications to standards such as HIPAA and GDPR. For data residency, resource location constraints limit workload deployment to pre-approved regions, which matters because multiregional and regional services store data differently. Choose this combination when workloads face regulatory scrutiny or must prove where data is stored and processed and which safeguards enforce it.
Key Facts
- Operational excellence uses automation and continuous monitoring to deploy and operate workloads consistently, while reliability designs for failure using product-level metrics and Recovery Time Objective (RTO) and Recovery Point Objective (RPO) targets.
- Data flows from Cloud Monitoring to Recommender, which analyzes utilization history and recommends allocation changes such as reducing machine size.
- Compute Engine managed instance groups scale groups of VMs on CPU thresholds, Google Kubernetes Engine (GKE) scales nodes and Pods with four autoscalers, and Cloud Run scales serverless container instances with incoming traffic.
- The shared responsibility model assigns infrastructure and physical security to Google and data, applications, identities, and configuration to the customer, with customer responsibility increasing from SaaS to PaaS to IaaS.
- VPC Service Controls creates a perimeter around sensitive APIs to prevent data exfiltration, Cloud Key Management Service (Cloud KMS) manages encryption keys for data at rest, and Confidential Computing encrypts data in use during processing.
Frequently Asked Questions
What is the difference between operational excellence and reliability in the Google Cloud Well-Architected Framework?
Operational excellence means efficiently deploying, operating, monitoring, and managing workloads consistently with automation and continuous monitoring, while reliability means designing and operating resilient and highly available workloads that stay online through failure. Operational excellence uses automation instead of repeated manual steps and continuous monitoring to detect problems early, while reliability starts from planning for failure and uses product-level metrics with Recovery Time Objective (RTO) and Recovery Point Objective (RPO) targets.
What is the difference between a pillar and a perspective in the Google Cloud Well-Architected Framework?
A pillar provides principles for one non-functional area such as operations or reliability, while a perspective provides a cross-pillar view for a specific technology or sector such as AI and ML or financial services. The framework organizes guidance into pillars including operational excellence, security, privacy, and compliance, reliability, cost optimization, performance optimization, and sustainability.
When should I use right-sizing instead of autoscaling for Google Cloud workloads?
Use right-sizing to fix a steady mismatch between allocation and demand, and use autoscaling to handle demand that rises and falls over time. Right-sizing continuously monitors utilization and adjusts allocation to match actual demand, while autoscaling dynamically adjusts capacity based on workload fluctuations using a policy that defines minimum and maximum capacity and the condition that triggers scaling.
How is security responsibility divided between Google and customers in the Google Cloud shared responsibility model?
Google secures the underlying cloud infrastructure, physical facilities, and foundational services, while the customer secures the data, applications, identities, configurations, and access controls placed in Google Cloud. Customer responsibility increases from Software as a Service (SaaS) to Platform as a Service (PaaS) to Infrastructure as a Service (IaaS), with Infrastructure as a Service (IaaS) retaining more operating-system and middleware responsibility.
Sample Question
An enterprise is designing a highly resilient database architecture on Google Cloud for a mission-critical transactional service. The workload has the following architectural and reliability requirements:
- Local High Availability (HA): Requires an RPO of zero (no data loss) and an RTO of less than 60 seconds with automated failover in the event of a primary database instance or zone failure.
- Performance: Transactional write latency must not be severely degraded by long-distance network round-trips during standard operations.
- Disaster Recovery (DR): Protection against total regional failure by maintaining a standby disaster recovery site in a geographically distant secondary region.
- Cluster Management: Automated health detection, distributed consensus, and leader election.
Following the Google Cloud Well-Architected Framework for reliability, which database architecture should you implement?
How learners score on this domain
Last updated