Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Asynchronous Replication Trade-offs in Redis Cluster
Free sample question, answered and explained below. The Professional Cloud Architect practice bank has 2,335 more like it. Try 10 free: instant score, no account.
A global gaming company is architecting a low-latency caching and state store on Google Cloud to handle millions of active sessions. The engineering team requires horizontal write scalability across multiple shards and needs to scale out read throughput across multiple zones while maintaining minimal client response times.
The team decides to deploy Memorystore for Redis Cluster (or Memorystore for Valkey) in Cluster Mode Enabled with read replicas provisioned for each shard, configuring client connections to issue the READONLY command to read directly from replica nodes.
According to distributed systems design trade-offs and the CAP theorem, what architectural trade-off must the team accept with this configuration?
Explanations
Cluster scaling requires freezing all active primary nodes and draining client connection pools, preventing any write operations during shard rebalancing.
Cluster scaling requires freezing all active primary nodes and draining client connection pools, preventing any write operations during shard rebalancing.
What Full Cluster Freezing Is
Full cluster freezing is a legacy operational constraint in non-distributed architectures where resharding or capacity resizing requires putting the entire database into read-only maintenance mode and terminating existing client connection pools.
Why It Doesn't Apply to This Architecture
- Online Resharding: Cluster Mode Enabled supports dynamic slot migration and online shard assignment without bringing down the cluster.
- Topology Discovery: Cluster-aware clients automatically update their slot-to-node maps when receiving
MOVEDredirections or topology updates via discovery endpoints. - Continuous Availability: Primary nodes continue serving reads and writes for unshifted keyslots throughout scaling operations.
Key Characteristics of Cluster-Aware Clients
- Discovery Endpoints: Managed discovery endpoints route topology discovery requests to nodes with up-to-date views without overloading the cluster.
- Exponential Backoff: Clients handle slot redirection and node failover gracefully without requiring manual connection draining.
This Answer Would Be Correct If
The system were operating on a single-node database that lacks clustering and online resharding capabilities, requiring manual downtime for vertical scaling.
Every read request automatically acquires a pessimistic lock on the underlying hash slot across the cluster, causing high transaction contention under heavy traffic.
Every read request automatically acquires a pessimistic lock on the underlying hash slot across the cluster, causing high transaction contention under heavy traffic.
What Pessimistic Locking in Distributed Data Stores Is
Pessimistic locking is a concurrency control mechanism where transactions acquire explicit database locks on records or keys prior to read or write execution, blocking concurrent operations from modifying or viewing uncommitted changes until the lock is released.
Why It Doesn't Apply to This Architecture
- Non-Blocking Reads: Memorystore read operations do not place distributed locks on hash slots or keys across primary and replica instances.
- Direct Node Routing: Cluster clients maintain a local slot map and route
READONLYcommands directly to specific replica nodes without cluster-wide lock coordination.
Key Characteristics of In-Memory Concurrency
- Single-Threaded Command Execution: Shard nodes execute operations sequentially in memory without requiring distributed lock managers for individual read requests.
- Optimistic/Pessimistic Scenarios: Pessimistic locking is typically applied in transactional document or relational databases (such as Firestore server client libraries using built-in transactions), not read replicas in in-memory caches.
This Answer Would Be Correct If
The workload were using a document database running in pessimistic concurrency mode where server-side transactions acquire distributed locks across document entities during read operations.
Write operations will require a synchronous two-phase commit across all shard replicas, leading to increased write latency and blocking during cross-zone network partitions.
Write operations will require a synchronous two-phase commit across all shard replicas, leading to increased write latency and blocking during cross-zone network partitions.
What Two-Phase Commit (2PC) Is
A two-phase commit (2PC) is a distributed consensus protocol used in strongly consistent (CP) relational databases (such as distributed SQL systems) where a coordinator node ensures that all participating nodes synchronously agree to commit a transaction before acknowledging success to the client.
Why It Doesn't Apply to This Architecture
- Asynchronous Protocol: Memorystore clusters do not use two-phase commits across replicas; write replication is asynchronous by default to ensure minimal latency.
- No Synchronous Cross-Zone Blocking: Primary nodes acknowledge writes immediately to the client without waiting for cross-zone replica round trips.
Key Characteristics and Limitations of 2PC
- High Latency Overhead: Introduces multiple round-trip network hops per write operation.
- Availability Vulnerability: Under network partitions, nodes block waiting for coordinator responses, violating low-latency requirements.
This Answer Would Be Correct If
The team chose a distributed strongly consistent database architecture (like Cloud Spanner) where synchronous multi-region or multi-zone consensus is enforced for strict serializability.
Read operations directed to replica nodes may return stale data due to asynchronous replication, and acknowledged writes can be lost during an unplanned failover.
Read operations directed to replica nodes may return stale data due to asynchronous replication, and acknowledged writes can be lost during an unplanned failover.
What Asynchronous In-Memory Replication Is
In distributed in-memory data stores like Memorystore for Redis Cluster and Memorystore for Valkey, Cluster Mode Enabled partitions data across multiple primary shards (from 1 to 250 shards) to achieve horizontal scalability. To maximize write performance and provide sub-millisecond response times, replication from primary nodes to read replicas is performed asynchronously.
How It Reflects the Consistency and Latency Trade-Off
- Read Staleness (Eventual Consistency): When read traffic is scaled out across replicas using the
READONLYcommand, reads do not wait for synchronous replication acknowledgments. If a primary node accepts a write, there is a propagation delay before that write reaches every replica, meaning replica reads may serve stale data. - Data Loss on Unplanned Failover: Because primary nodes acknowledge writes to clients before replicas confirm synchronization, an unexpected crash of a primary node can cause recently acknowledged writes to be lost when a replica is promoted to primary.
- CAP Theorem Alignment: This design prioritizes Availability and Latency (AP) over strict Consistency (CP), ensuring maximum throughput and minimal response latency across distributed zones.
Async Replication: Stale Reads and Lost Writes
Sequence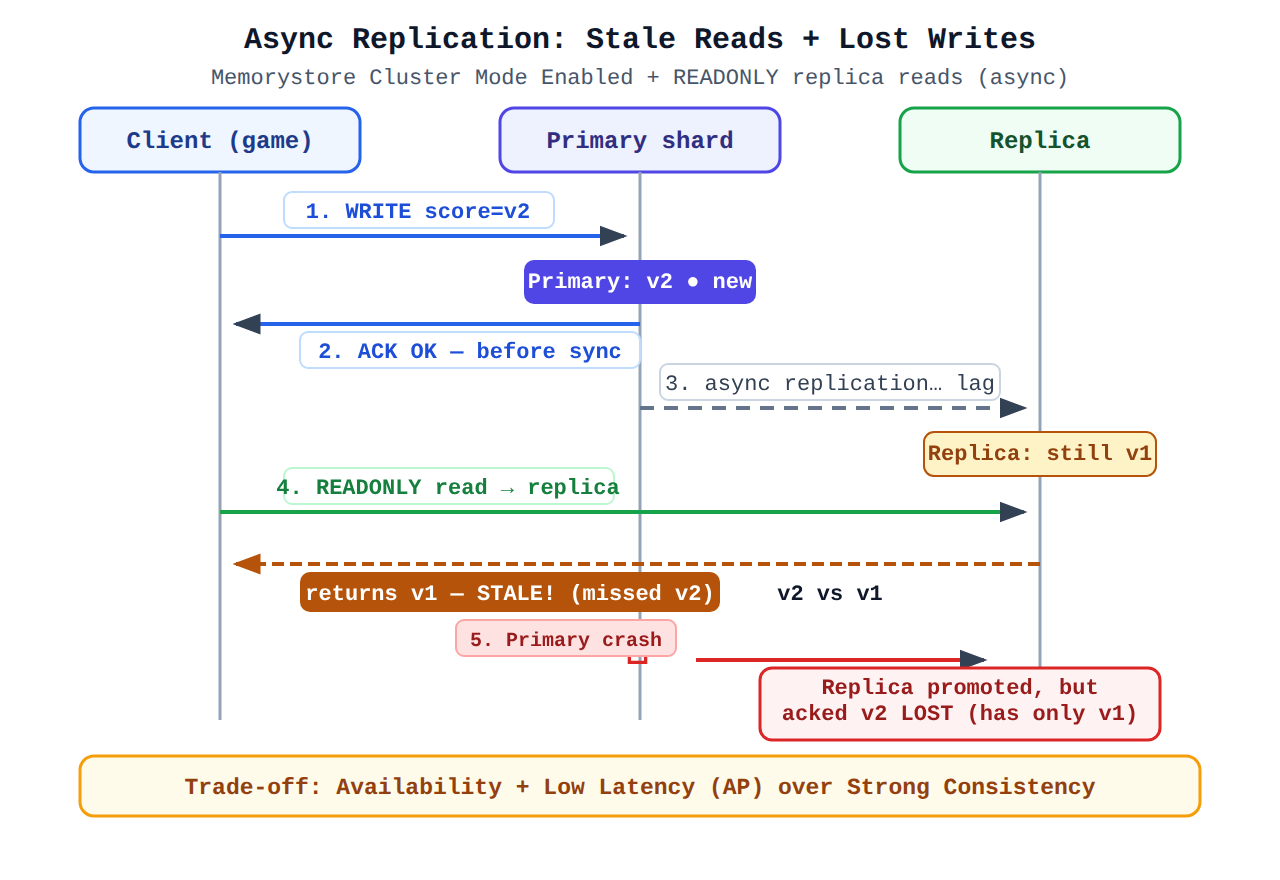
Key Advantages and Characteristics
- Horizontal Scalability: Scales data capacity up to terabytes and write throughput across up to 250 shards.
- Sub-Millisecond Read Latency: Eliminates the round-trip overhead of distributed synchronous locks or quorum acknowledgments during standard read and write paths.
- High Availability: Multi-zone replica placement allows automatic failovers during maintenance or node failure events.
- Traffic Isolation: Separates heavy analytical or query reads from latency-sensitive write paths on primary nodes.
Why This Is Optimal for Caching and Session Stores
For ephemeral session states, leaderboards, and caching layers, sacrificing immediate strict consistency in exchange for massive horizontal read/write scale and minimal network latency provides the best performance balance.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,335 practice questions across all 6 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
IntermediateProfessional Cloud Architect
Spot VMs and Multi-Region Standard Storage
Design decision trade-offs
IntermediateProfessional Cloud Architect
Cloud Run Serverless Containers
Design decision trade-offs
IntermediateProfessional Cloud Architect
Global External Application Load Balancer with Cloud CDN
Performance and latency
IntermediateProfessional Cloud Architect
Apigee API Mediation and Response Caching
API management best practices (e.g., Apigee)
IntermediateProfessional Cloud Architect
GCVE Route Summarization and Filtering
Cloud-native network configuration for compute resources (e.g., Compute Engine, GKE, serverless networking, and Google Cloud VMware Engine)
FundamentalGenerative AI Leader
Google Cloud AI Hypercomputer Architecture
Identifying the essential components of Google Cloud's AI-optimized infrastructure and its benefits (e.g., hypercomputer, Google's custom-designed TPUs, GPUs, data centers, cloud computing)
Last updated