Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Diagnosing Microservices Latency with Trace and Profiler
Free sample question, answered and explained below. The Professional Cloud Architect practice bank has 2,335 more like it. Try 10 free: instant score, no account.
An e-commerce company runs a microservices-based checkout system deployed across Google Kubernetes Engine (GKE) and Cloud Run. During peak shopping events, end users report intermittent latency spikes that violate response time Service Level Objectives (SLOs), accompanied by sudden increases in cluster compute consumption. The operations team needs to pinpoint which specific inter-service calls introduce the delays and identify the exact application functions consuming excessive CPU and memory in production.
Which observability strategy should you implement to diagnose these performance bottlenecks?
Explanations
Enable Active Assist Recommender on the clusters and configure Horizontal Pod Autoscaling (HPA) using standard CPU utilization thresholds.
Enable Active Assist Recommender on the clusters and configure Horizontal Pod Autoscaling (HPA) using standard CPU utilization thresholds.
What Active Assist and HPA do
Active Assist Recommender analyzes infrastructure utilization data to generate recommendations for rightsizing virtual machines and node pools. Horizontal Pod Autoscaler (HPA) dynamically scales the number of Pod replicas up or down in response to observed metrics like average CPU or memory utilization.
Why it doesn't meet the requirement
- Reactive scaling rather than diagnosis: HPA scales infrastructure capacity to absorb traffic loads, but it does not diagnose why a specific service has latency bottlenecks or inefficient code.
- Masks underlying code issues: Scaling out pods in response to high CPU utilization can mask poorly written, CPU-intensive algorithms, resulting in unnecessarily inflated cloud spend.
- No code-level visibility: Neither Active Assist nor HPA provides insight into application code paths, inter-service network call graphs, or memory allocation hotspots.
Key characteristics and limitations
- Automates cluster capacity adjustments based on coarse-grained metric thresholds.
- Focuses on resource sizing and cost/performance optimization at the infrastructure tier.
- Does not collect transaction traces or runtime execution profiling data.
This answer would be correct if
The system architecture was already optimized and the objective was simply to dynamically adjust compute capacity to accommodate predictable seasonal traffic fluctuations.
Create an aggregated sink in Cloud Logging to export application logs to BigQuery, and build Looker Studio reports to analyze function call stacks and memory allocations.
Create an aggregated sink in Cloud Logging to export application logs to BigQuery, and build Looker Studio reports to analyze function call stacks and memory allocations.
What Cloud Logging, BigQuery export, and Looker Studio do
Cloud Logging aggregates system and application log events. By routing logs via an aggregated sink into BigQuery, organizations can perform long-term trend analysis, complex analytical SQL queries, and visualize log patterns in Looker Studio.
Why it doesn't meet the requirement
- Inefficient for distributed timing: While logs record discrete events, correlating distributed microservice calls across asynchronous threads requires distributed trace contexts and span propagation rather than raw log statements.
- Cannot capture execution profiling: Application logs do not inherently track continuous CPU instruction cycles, call stack depth, or heap memory allocations unless excessive, high-overhead debug logging is manually added to the application code.
- Higher latency and cost overhead: Exporting and querying massive volumes of high-granularity logs for performance profiling generates unnecessary storage costs and analysis latency.
Key characteristics and limitations
- Best suited for security auditing, compliance, operational troubleshooting, and post-mortem analysis.
- Requires developers to explicitly emit log statements at every relevant code juncture.
- Visualizations in Looker Studio represent analytical aggregations rather than real-time interactive execution flame graphs.
This answer would be correct if
The primary requirement was performing deep historical audits of application errors, business transaction records, or retrospective compliance reviews across all projects.
Configure Cloud Monitoring custom dashboards with high-frequency metric collection intervals, and enable GKE usage metering to isolate function-level performance bottlenecks.
Configure Cloud Monitoring custom dashboards with high-frequency metric collection intervals, and enable GKE usage metering to isolate function-level performance bottlenecks.
What Cloud Monitoring and GKE usage metering do
Cloud Monitoring provides infrastructure and platform-level time-series metrics, customizable dashboards, and alerting policies. GKE usage metering tracks resource requests and actual usage (such as CPU, GPU, and TPU consumption) aggregated by Kubernetes namespaces and labels to assist in cost allocation.
Why it doesn't meet the requirement
- Cannot trace distributed request flows: Metric aggregation in Cloud Monitoring shows high-level trends (such as average or 99th percentile service latency), but it cannot display the sequential execution path of a single transaction across microservices.
- Lacks code-level function attribution: GKE usage metering and standard metric collection measure aggregate container or pod resource usage, not individual call stacks or code routines.
- Potential performance degradation: Increasing the metric collection sampling frequency significantly can add compute and networking overhead to the environment without providing code-level insights.
Key characteristics and limitations
- Measures aggregate infrastructure utilization rather than transaction spans.
- Collects metrics over fixed time windows, missing transient function-level execution details.
- Intended for macro-level system health, alerting, and cost attribution.
This answer would be correct if
The goal was solely to set up high-level operational dashboards, establish SLO alert thresholds, and divide Kubernetes infrastructure costs among different organizational cost centers.
Instrument the microservices with Cloud Trace to capture distributed request flows across services, and deploy Cloud Profiler agents to identify resource-intensive functions and call stacks in production.
Instrument the microservices with Cloud Trace to capture distributed request flows across services, and deploy Cloud Profiler agents to identify resource-intensive functions and call stacks in production.
What Cloud Trace and Cloud Profiler are
Cloud Trace is a distributed tracing system that collects latency data from applications and displays the flow of requests across multiple network boundaries and microservices in near real time. Cloud Profiler is a continuous, statistical, low-overhead profiling tool that captures CPU utilization and memory allocations directly from production workloads, mapping resource consumption directly to specific source code functions.
How it meets the requirements
- Pinpointing inter-service latency bottlenecks: By instrumenting services with Cloud Trace (often via OpenTelemetry or Google Cloud client libraries), each request is assigned a unique trace context. Distributed spans record the precise execution duration and round-trip time between individual microservices, revealing which downstream service or RPC call causes the latency spike.
- Identifying code-level compute and memory consumption: Cloud Profiler continuously samples production services with negligible performance overhead (typically <1%). It generates interactive flame graphs that attribute CPU cycles, wall time, and heap allocations directly to specific routines, classes, and call stacks, enabling developers to remediate inefficient algorithms.
Distributed Trace Across Microservices
Sequence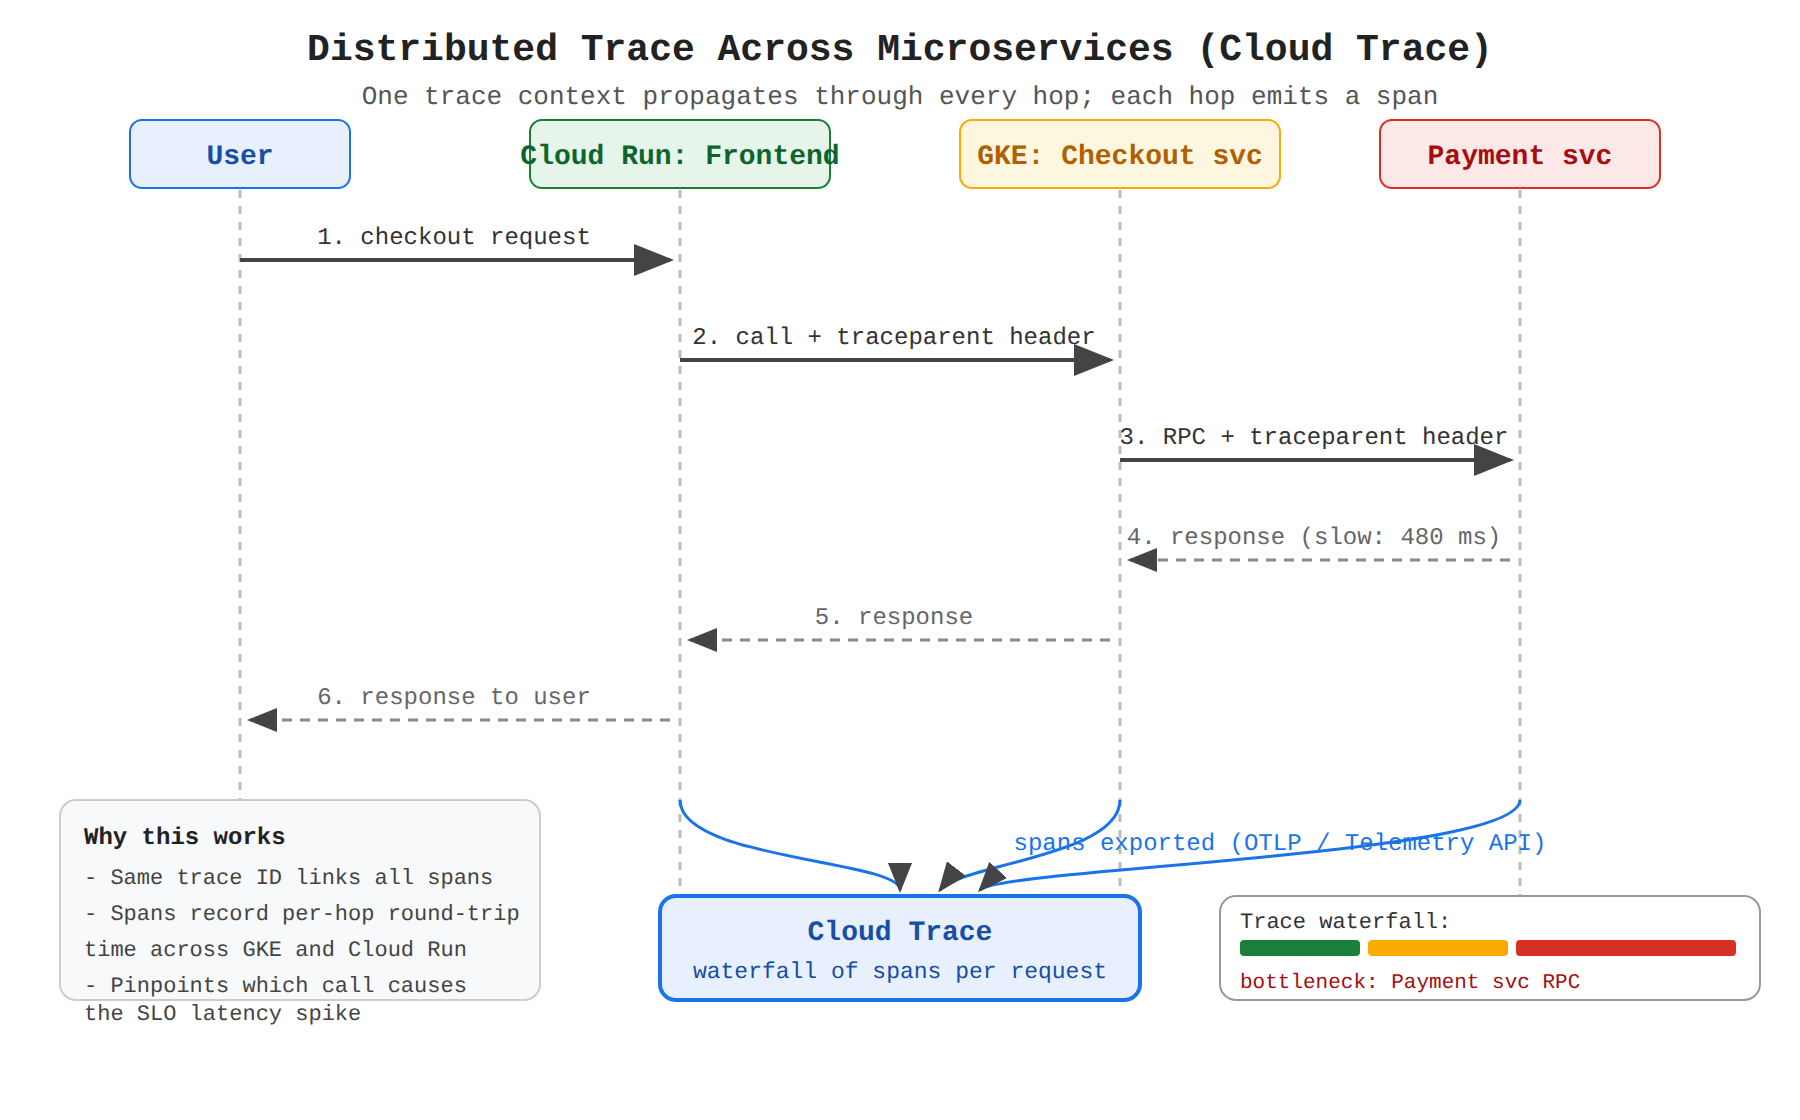
Key advantages and capabilities
- End-to-end distributed visibility: Correlates requests seamlessly as they traverse multiple environments, such as GKE and Cloud Run.
- Low overhead in production: Cloud Profiler operates continuously in live production environments without noticeable user impact or service degradation.
- Granular root-cause analysis: Combines distributed macro-level transaction timing with micro-level function execution analysis.
- Actionable optimization data: Provides actionable flame graphs and trace waterfalls to drive targeted code refactoring and infrastructure right-sizing.
Why this is optimal
Using Cloud Trace alongside Cloud Profiler provides complete vertical observability. Cloud Trace isolates the problematic microservice in the distributed transaction, while Cloud Profiler pinpoints the exact method or loop causing CPU exhaustion and latency inside that service.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 2,335 practice questions across all 6 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
IntermediateProfessional Cloud Architect
Global External Application Load Balancer with Cloud CDN
Performance and latency
IntermediateProfessional Cloud Architect
Highmem VM With Hyperdisk Balanced
Performance and latency
IntermediateProfessional Cloud Architect
Parameter-Efficient Fine-Tuning with LoRA
Integrating AI models from Model Garden into the solution
IntermediateProfessional Cloud Architect
Cold Standby with Managed Instance Group
Backup and recovery
IntermediateProfessional Cloud Architect
GKE Fleet-Based Rollout Sequencing
Supporting the application design
AdvancedProfessional Data Engineer
OnVault Snapshot Pool Offloading
Disaster recovery and fault tolerance
Last updated