Fundamental
Prepare and test your skills
Fundamental
Prepare and test your skills
Validating Staging Data with BigQuery SQL Checks
Free sample question, answered and explained below. The Associate Data Practitioner practice bank has 1,156 more like it. Try 10 free: instant score, no account.
An analytics team ingests daily transaction records into a staging dataset in Google Cloud BigQuery. Before publishing the data to downstream reporting tables, the team needs to assess data quality by verifying that:
- Mandatory fields such as
order_idcontain no null or duplicate values - Numeric fields such as
order_amountare strictly greater than zero - Every
customer_idmatches an existing record in the mastercustomerstable
Which approach should the team implement in BigQuery to evaluate data accuracy and identify these discrepancies?
Explanations
Configure a Pub/Sub dead-letter topic on the BigQuery dataset to automatically filter and reject rows violating relational consistency rules.
Configure a Pub/Sub dead-letter topic on the BigQuery dataset to automatically filter and reject rows violating relational consistency rules.
What Pub/Sub dead-letter topics are:
Cloud Pub/Sub dead-letter topics are messaging mechanisms designed to capture and isolate undeliverable messages after a subscriber fails to acknowledge them a configured number of times during real-time stream ingestion.
Why it doesn't meet the requirement:
- Wrong technology layer (✗): Pub/Sub is an asynchronous messaging broker, not an analytical query engine or database constraint checker. It operates upstream of storage and has no native mechanism to inspect relational data in BigQuery staging tables.
- Cannot evaluate relational integrity (✗): Pub/Sub cannot evaluate cross-table consistency (e.g., verifying against a master
customerstable in BigQuery) or perform SQL-based data profiling. - Cannot be attached to BigQuery datasets (✗): BigQuery datasets do not support attaching Pub/Sub dead-letter topics to filter batch SQL tables.
Key characteristics/limitations:
- Operates on message queues rather than analytical storage tables
- Triggers solely based on delivery attempt thresholds, not data payload validation logic
- Cannot perform complex queries, aggregations, or multi-table joins
This answer would be correct if:
The scenario required capturing unparseable JSON messages from a real-time streaming ingestion pipeline before they entered the data warehouse when message delivery fails repeatedly.
Configure Cloud Storage Object Lifecycle Management rules to validate data types and column boundaries before data is loaded.
Configure Cloud Storage Object Lifecycle Management rules to validate data types and column boundaries before data is loaded.
What Cloud Storage Object Lifecycle Management is:
Cloud Storage Object Lifecycle Management allows administrators to define automated actions on storage objects, such as transitioning objects to colder storage classes (e.g., Nearline or Coldline) or deleting objects after a specific retention age.
Why it doesn't meet the requirement:
- File-level management only (✗): Object Lifecycle Management operates strictly on object-level metadata (such as creation date, versioning, and storage tier) and cannot inspect the internal contents, rows, or columns of data files.
- No relational validation (✗): It cannot check for duplicate identifiers, validate numeric values like transaction totals, or check foreign key consistency against BigQuery tables.
- Wrong service scope (✗): The data in question has already been loaded into a staging dataset in BigQuery; Cloud Storage lifecycle rules have no visibility or control over BigQuery tables.
Key characteristics/limitations:
- Manages storage costs and data retention policies
- Blind to internal file formats (CSV, Parquet, JSON) and relational column data
- Incapable of executing SQL assertions, joins, or profiling
This answer would be correct if:
The organization needed to automatically delete raw export files in a Cloud Storage staging bucket after 30 days to reduce storage costs and meet compliance standards.
Execute SQL validation queries and profiling checks using conditional aggregations and anti-joins to identify constraint violations and orphan records.
Execute SQL validation queries and profiling checks using conditional aggregations and anti-joins to identify constraint violations and orphan records.
What SQL validation queries and profiling in BigQuery are:
SQL-based data validation in Google Cloud BigQuery involves running structured queries against staging tables to profile datasets and verify business rules, constraints, and data integrity before moving data into production. By combining standard SQL constructs like COUNTIF, CASE, window functions, and LEFT JOIN ... WHERE NULL (anti-joins), data practitioners can systematically identify anomalies, nulls, duplicates, and referential mismatches.
BigQuery SQL Validation Check Types
Hierarchy / Taxonomy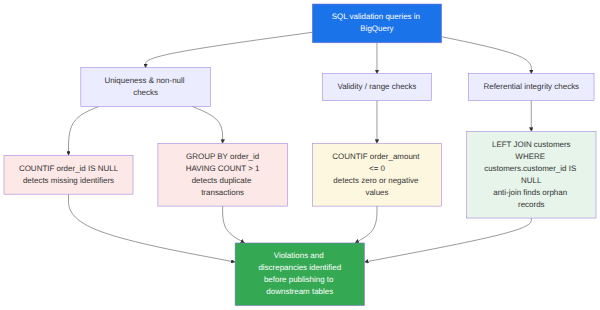
How it meets all requirements:
- Uniqueness and Non-null checks (✓): The team can run
COUNTIF(order_id IS NULL)and aggregate queries likeGROUP BY order_id HAVING COUNT(*) > 1to immediately detect missing identifiers and duplicate transactions. - Range and validity checks (✓): Conditional logic such as
COUNTIF(order_amount <= 0)accurately profiles numerical columns to spot negative or zero values that violate business domain rules. - Referential consistency checks (✓): Using an anti-join (
LEFT JOIN customers ON staging.customer_id = customers.customer_id WHERE customers.customer_id IS NULL) detects orphan records that do not exist in the master customer dimension.
Key advantages:
- Serverless compute scale: BigQuery executes validation queries across millions of rows in seconds using distributed SQL compute without needing separate server infrastructure.
- Automated orchestration: These SQL validation checks can easily be scripted in BigQuery stored procedures, scheduled via Scheduled Queries, or embedded as validation gates in Google Cloud Dataflow or Cloud Composer pipelines.
- Granular audit logging: Detected discrepancies can be written directly to a quarantine or dead-letter table for debugging and remediation.
- Standardized SQL syntax: Uses ANSI standard SQL, allowing analysts and engineers to write and maintain complex validation rules without proprietary scripting languages.
Why this is optimal:
Executing custom SQL profiling and validation rules inside BigQuery provides immediate, comprehensive visibility into data accuracy, domain constraints, and cross-dataset consistency directly at the storage and analysis layer before downstream consumers query the data.
Enable BigQuery BI Engine reservations to enforce foreign key constraints and reject invalid transaction amounts upon table creation.
Enable BigQuery BI Engine reservations to enforce foreign key constraints and reject invalid transaction amounts upon table creation.
What BigQuery BI Engine is:
BigQuery BI Engine is an in-memory analysis service built into Google Cloud BigQuery that accelerates SQL queries and interactive dashboards by caching frequently used table partitions and columns.
Why it doesn't meet the requirement:
- Acceleration, not validation (✗): BI Engine is purely a performance optimization and caching feature designed for sub-second query response times in reporting tools like Looker; it does not perform data quality profiling.
- No constraint enforcement (✗): BI Engine cannot enforce relational integrity rules or intercept and reject rows with negative purchase amounts.
- Misunderstanding of BigQuery constraints (✗): BigQuery supports informative primary and foreign key constraints for query optimization, but does not enforce them as blocking constraints on write operations.
Key characteristics/limitations:
- In-memory compute cache for read queries
- Completely unrelated to data cleaning, ETL checks, or schema validation rules
- Does not generate data discrepancy reports or quarantine bad data
This answer would be correct if:
The scenario asked how to speed up repeated analytical dashboard queries and visual reports generated from an already cleaned and validated reporting table.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 1,156 practice questions across all 4 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
FundamentalAssociate Data Practitioner
Time Series Gap Filling
Assess data quality
FundamentalAssociate Data Practitioner
Dataform rowConditions Assertions
Assess data quality
FundamentalAssociate Data Practitioner
ELT vs ETL
Evaluate use cases for ELT and ETL
FundamentalAssociate Data Practitioner
Encryption In Transit vs Encryption At Rest
Identify the difference between encryption in transit and encryption at rest
FundamentalAssociate Data Practitioner
Encryption in Transit vs Encryption at Rest
Identify the difference between encryption in transit and encryption at rest
AdvancedProfessional Data Engineer
Cloud SQL Cross-Region Replica Failover
Data replication and failover (e.g., Cloud SQL, Redis clusters)
Last updated