Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Data Retention and Lifecycle Management
Analytical and Database Data Expiration Strategies control how long analytic data stays queryable and how long recoverable copies are kept. BigQuery (opens in a new tab) expiration settings automatically delete aging tables or partitions to save storage, while Cloud Bigtable (opens in a new tab) backup retention keeps schema and data copies for recovery and compliance without letting backup storage grow without limit. The goal is to balance historical analysis needs with storage efficiency and resource optimization.
BigQuery Partition Expiration
BigQuery partition expiration is a table setting that controls how long data is kept in each partition of an ingestion-time or time-unit column partitioned table. The setting applies to all partitions in the table, but each partition expires independently from its own partition boundary in UTC. With daily partitioning, the boundary is midnight at 00:00:00 UTC, so a 6-hour expiration means each partition expires at 06:00:00 UTC the next day, and then BigQuery begins deleting data in that partition. A default expiration can be set at the dataset level, a table-level setting overrides that dataset default, and partitions never expire if neither level sets an expiration. Integer-range partitioned tables do not support partition expiration.
Table Expiration and Expiration Updates
BigQuery table expiration is a separate lifetime setting that deletes the entire table and all of its partitions. Table expiration takes precedence over partition expiration, so a table with 5-day table expiration and 7-day partition expiration is deleted with all partitions after 5 days. Partition expiration can be updated at any time after table creation, and the new value applies to all partitions regardless of creation time. Existing partitions older than the new expiration expire immediately, and newly copied or inserted data in a time-unit column partitioned table also expires immediately if its partition is already older than the setting. When a partition expires, BigQuery marks it for deletion, but deletion is not immediate.
Exam tip: Table expiration wins over partition expiration, and integer-range partitioned tables cannot use partition expiration at all.
Automated BigQuery Backups at Scale
Automated BigQuery backup (opens in a new tab) uses scheduled services to create recurrent copies of tables across folders, projects, datasets, and tables. Each table is backed up by one of two methods: a BigQuery snapshot, which is a point-in-time table copy inside BigQuery, or a BigQuery export to Cloud Storage, which writes table data as files in Cloud Storage. Each table gets its backup policy from a table-level policy defined by data owners, or from a fallback policy defined by a data governance officer when no table-level policy exists. This design retries through Pub/Sub when BigQuery concurrency limits cause failures, and it spreads snapshot or export operations across projects or requests a quota increase when daily limits are reached.
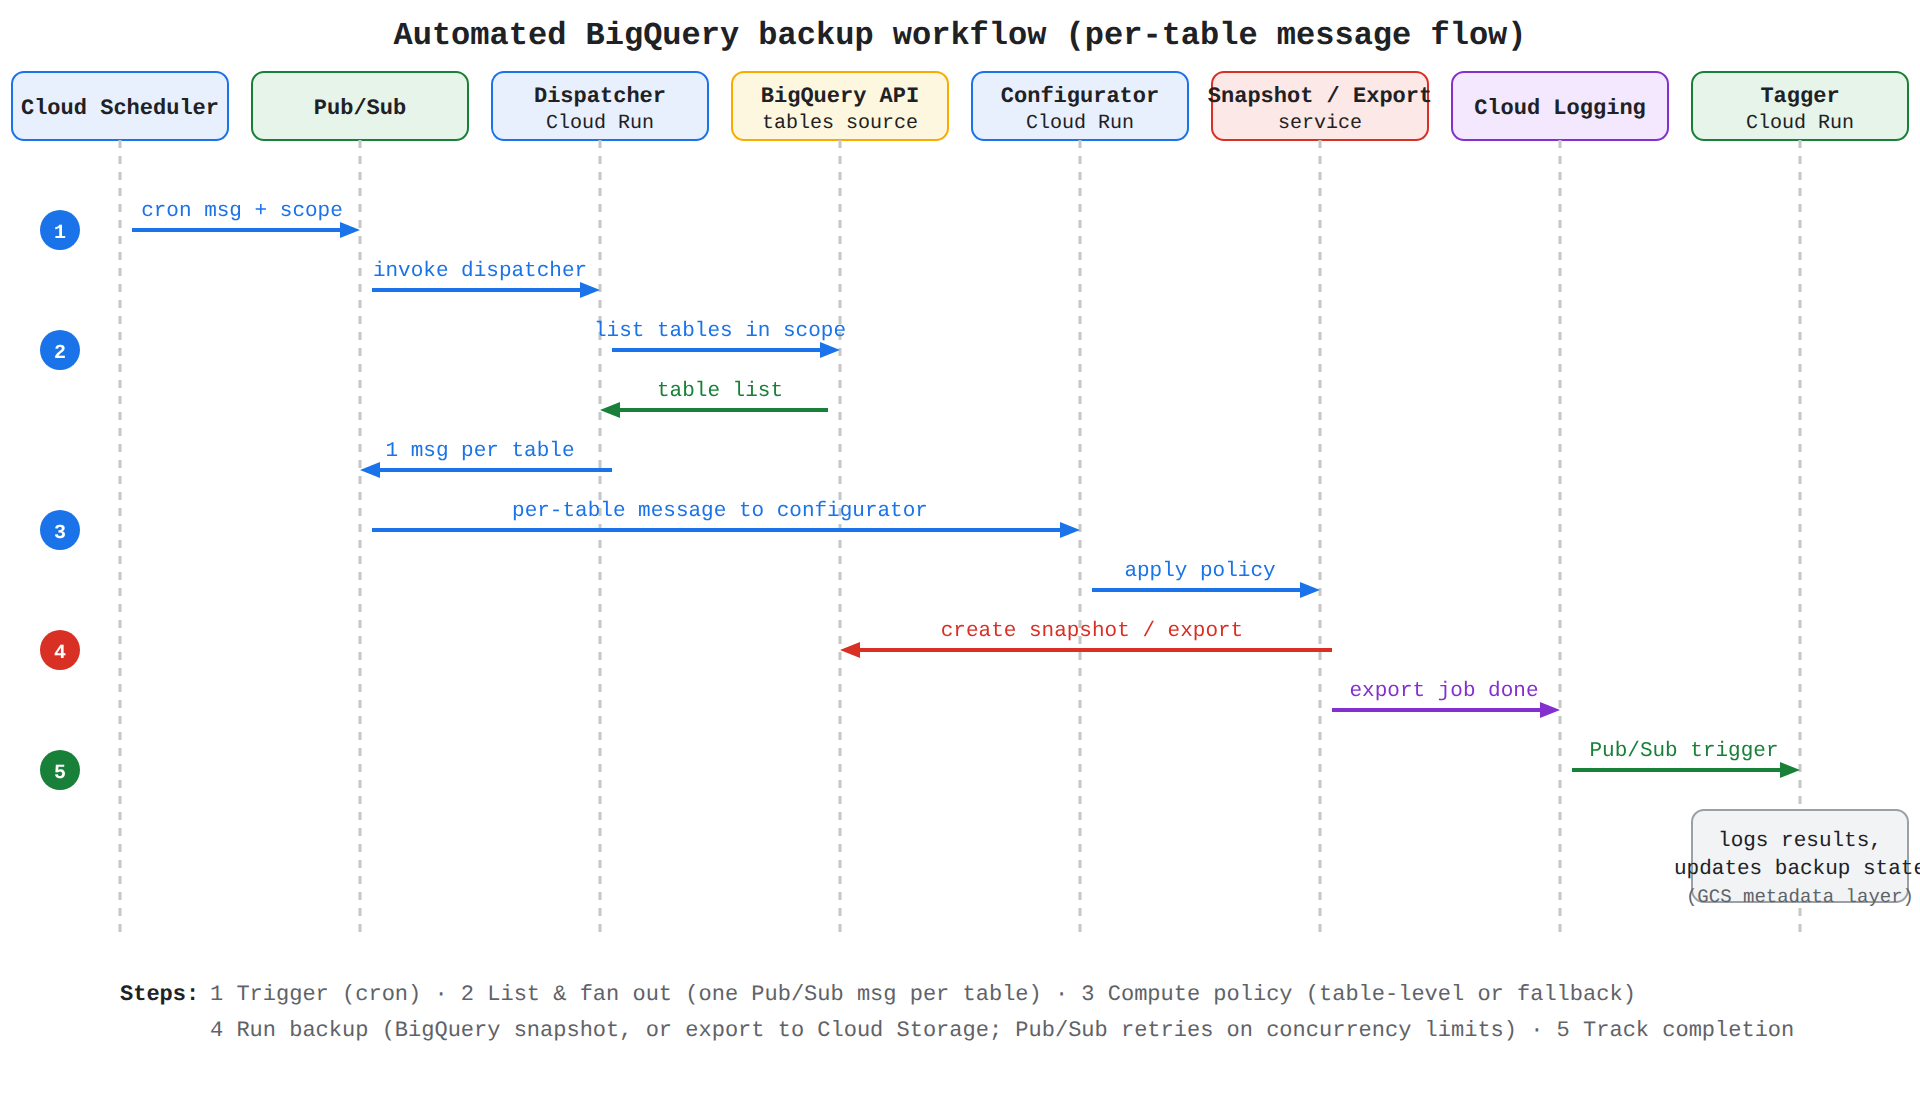
A sequence diagram showing the automated BigQuery backup workflow: Cloud Scheduler triggers Pub/Sub, the dispatcher lists tables in scope, the configurator applies table-level or fallback policies, a snapshot or export service runs the backup via the BigQuery API, and Cloud Logging triggers the tagger to record backup state in Cloud Storage metadata. Arrows appear in order to show the message flow.
The backup workflow moves work from a schedule through per-table execution in order:
- Trigger: Cloud Scheduler sends a Pub/Sub message to the dispatcher service on a cron schedule, and the message carries the included and excluded BigQuery scope.
- List and fan out: The dispatcher service on Cloud Run calls the BigQuery API to list tables in scope, then sends one Pub/Sub message per table to the configurator service.
- Compute policy: The configurator service on Cloud Run selects the table-level policy when present and otherwise selects the fallback policy, then forwards one request per table onward.
- Run backup: A snapshot service calls the BigQuery API to create a snapshot, or an export service calls the BigQuery API to export table data to Cloud Storage.
- Track completion: For exports, a Cloud Logging log sink listens for export-job completion events for asynchronous follow-up, then Pub/Sub triggers the tagger service, which logs results and updates backup state in the Cloud Storage metadata layer.
Bigtable Backup Retention Windows
Cloud Bigtable backups save a copy of a table's schema and data on a cluster so the data can later be restored to a new table. Backups can be created as daily automated backup, as on-demand backup created with the console, gcloud CLI, or client libraries, or as a copy of an existing backup. Backups are incremental and share physical storage of unchanged data with the source table and other backups of the same table, so a backup is never larger than its source table at creation time and its size depends on data divergence since the prior backup. Up to 150 backups can exist per table per cluster, and backup storage does not count toward the node storage limit.
Retention is controlled by a retention period or an absolute expiration date, and both methods produce an expiration time under the same limits. The retention period starts at creation, automated backup defaults to seven days, and an automated backup policy can keep backups up to 90 days in both Enterprise and Enterprise Plus editions. An on-demand backup or an updated retention on an existing backup can be kept up to 90 days in Enterprise or up to 365 days in Enterprise Plus, while a copy of a backup can be kept for a maximum of 30 days from copy creation. A hot backup has an independent transition time that controls when it stops being hot and becomes standard, and that time must be at least 24 hours after creation.
Backup placement and protection affect storage planning and deletion. A manually created backup is stored on a single specified cluster, while automated backup stores a backup on each cluster in the instance, with Enterprise Plus allowing selection of cluster locations. A cluster that contains backups, a cluster listed in an automated backup policy, or an instance that has backups in any cluster cannot be deleted until those backups are deleted, expire, or the policy is changed. The two performance tiers differ by restore readiness:
| Backup type | Optimized for | Restore behavior |
|---|---|---|
| Standard backup | Long-term retention | Restore to an SSD cluster needs extra optimization by Bigtable to reach production-level performance |
| Hot backup | Low-latency, production-ready recovery | Provides the most efficient restoration to production-level performance |
Compliance and retention governance ensures stored data meets regulatory, residency, and encryption requirements while automated controls prevent non-compliant use or retention. Secret Manager (opens in a new tab) provides assessed compliance coverage for regulated secrets, BigQuery Lakehouse (opens in a new tab) caching creates residency and encryption questions when remote data is cached locally, and organization policy constraints limit long-lived credentials. Together these controls define what can be stored, where copies can rest, and how long powerful credentials can exist.
Regulatory Compliance Coverage
Regulatory compliance coverage means a service has been assessed against specific government and industry standards so regulated data can be stored under defined controls. Secret Manager meets standards including Criminal Justice Information Services (CJIS), FedRAMP Moderate and FedRAMP High, Health Insurance Portability and Accountability Act (HIPAA), HITRUST CSF, Department of Defense Impact Levels 2, 4, and 5, International Traffic in Arms Regulations (ITAR), IRS 1075, EU General Data Protection Regulation (GDPR), Israel Privacy Protection Authority, and Kingdom of Saudi Arabia Class C license. Central compliance information is maintained in the Google Cloud Compliance resource center, which maps services to supported programs.
The breadth of coverage matters because different workloads require different attestations:
- CJIS for criminal justice data
- FedRAMP Moderate and FedRAMP High for U.S. federal workloads
- HIPAA and HITRUST CSF for health data
- DoD IL2, IL4, and IL5 for defense workloads
- ITAR and IRS 1075 for export-controlled and tax data
- EU GDPR, Israel Privacy Protection Authority, and Saudi Arabia Class C license for regional privacy requirements
Data Residency and Jurisdiction Governance
Data residency governance controls where copies of data rest when queries span regions or jurisdictions. BigQuery Lakehouse automatically caches retrieved remote data blocks locally within Google Cloud in the target region of the federated catalog or connection. On the first query, data blocks flow from remote object storage over the public internet to Google Cloud and populate the local cache, and subsequent queries targeting the same blocks read directly from local Google Cloud storage. This flow creates a residency boundary because a cached copy at rest exists on the Google Cloud side even when the source remains elsewhere.
For example, when AWS Amazon S3 data in the European Union is paired with BigQuery compute in us-east4, data-at-rest cached copies reside in the U.S. region. The user or administrator who creates the connection or catalog is responsible for ensuring that cross-jurisdiction caching complies with organizational data residency, sovereignty, and compliance requirements.
Encryption Governance for Cached Data
Encryption governance defines which encryption keys protect retained cached copies and what happens when key policy is not satisfied. Lakehouse caching encrypts all cached data blocks at rest using default Google-owned and Google-managed encryption keys. Customer-managed encryption keys (CMEK) are not supported for Lakehouse caching. The encryption policy applies through the organization policy constraint constraints/gcp.restrictNonCmekServices, named Restrict Non-CMEK Services.
When an organization enforces this constraint, Lakehouse automatically disables caching for queries that access restricted tables. The queries still execute successfully, but they do not cache data blocks and do not benefit from cache-related egress savings.
Exam tip: When Restrict Non-CMEK Services is enforced, restricted Lakehouse queries still succeed but run without caching, so no cacheBytesRead savings occur.
Lifecycle Governance with Organization Policy Constraints
Lifecycle governance limits the creation, upload, and lifetime of powerful credentials to reduce long-term risk from unmanaged secrets. Each service account can have up to 10 service account keys (opens in a new tab), and Google stores only the public portion of a user-managed key pair. Keys can be created through the Identity and Access Management (IAM) API, where Google generates the pair and returns the private key, or created externally where only the public key is uploaded. By default, a newly created user-managed key never expires unless an expiry policy is set.
Preventive control flows from the organization policy to the credential action:
constraints/iam.disableServiceAccountKeyCreationprevents principals from creating user-managed service account keys.constraints/iam.disableServiceAccountKeyUploadprevents principals from uploading a public key for a service account.constraints/iam.serviceAccountKeyExpiryHourssets the lifetime in hours for all newly created keys in a project, folder, or organization, with existing keys unaffected.
Expiry times are measured in hours, with short durations such as 8 hours, 24 hours, or 168 hours recommended as best practice. Organizations created on or after May 3, 2024 enforce the key creation and upload restrictions by default under secure-by-default organization resources.
Cloud Storage (opens in a new tab) lifecycle policy implementation uses Object Lifecycle Management (OLM) to automatically move or delete objects when they meet defined conditions. OLM configuration lives on the bucket and the service continuously evaluates objects in that bucket, so data flows from active use to lower-cost storage and then to deletion without manual requests. This automation reduces storage costs, enforces retention periods, and keeps buckets organized while maintaining access to data that is still needed.
How Object Lifecycle Management Automates Retention
Object Lifecycle Management in Cloud Storage is the automated bulk-deletion and transition mechanism for objects that match conditions such as age or storage class. A lifecycle configuration lives on the bucket, the service evaluates each object against the configured conditions, and only after an object satisfies all conditions does Cloud Storage apply the configured action to that object. Choose OLM when deletion or transition should happen automatically on a schedule, such as deleting logs after 30 days for compliance automation, rather than when a person or application issues an immediate delete.
Storage Class Transitions for Cost Control
Storage class transitions move data to a more economical class as access frequency drops over its retention period. The bucket owner chooses an initial storage class based on data-retention and access-frequency requirements, then defines a storage class lifestyle action that changes the class when the lifecycle condition is met. Because Cloud Storage stores or replicates data within the specified region, dual-region, or multi-region location, the lifecycle action lowers cost without moving data outside the compliance boundary chosen for the bucket.
Bulk deletion use cases that pair with lifecycle transitions include:
- Cost optimization: removing large datasets such as old logs or temporary build artifacts that are no longer needed for operations.
- Compliance automation: automatically enforcing a retention period by deleting objects after a specific age.
- Bucket migration or decommissioning: clearing millions or billions of objects when migrating data or closing a project.
- Data pipeline cleanup: removing intermediate processing objects after a pipeline generates a final report or dataset.
Locked Retention Policies for Compliance
Locked bucket retention policies in Cloud Storage enforce how long personal information and other regulated data must be kept and protected. Personal information is retained for no longer than necessary to fulfill stated purposes unless law requires otherwise, and policies and procedures protect that information from erasure or destruction during the specified retention period. The bucket applies a locked retention policy to all objects in the bucket, and the lock prevents anyone, including the bucket owner, from shortening the period or deleting objects early, which is enforced through Bucket Lock and Object Retention Lock.
Object Versioning and Protection Against Loss
Object Versioning is the Cloud Storage feature that retains multiple versions of an object in the same bucket to track system changes before and after updates. When versioning is enabled, an overwrite or delete creates a noncurrent version rather than permanently removing prior data, so a lifecycle or retention rule must account for both live and noncurrent version states. Related protections include soft delete, which guards against accidental deletion, and Cloud Asset Inventory, which tracks configuration changes to buckets for audit and recovery.
Choosing a Deletion and Lifecycle Tool
The deletion method in Cloud Storage depends on object count and whether the work is manual, programmatic, or automatic. Single-object deletion sends an individual DELETE request per object through the console, gcloud storage rm, client libraries, or REST APIs for targeted updates such as correcting errors or removing sensitive data. Bulk tools provide higher throughput with reduced overhead, including console bulk delete, multi-object delete, recursive delete, and OLM for condition-based automation.
| Use case | Method | Recommended tool |
|---|---|---|
| Delete one or a few specific objects | Single-object deletion | Console, gcloud storage rm, client libraries, or REST APIs |
| Delete up to 1,000 objects in one programmatic request | Bulk object deletion | Multi-object delete XML API |
| Delete objects sharing a common prefix | Bulk object deletion | gcloud storage rm --recursive |
| Delete automatically when age or storage class conditions are met | Bulk object deletion | Object Lifecycle Management |
Exam tip: Use Object Lifecycle Management for automatic deletion based on age or storage class, while storage batch operations fits one-time asynchronous deletion of millions or billions of objects with built-in tracking.
Key Facts
- BigQuery table expiration deletes the entire table and takes precedence over partition expiration, while integer-range partitioned tables do not support partition expiration.
- Cloud Bigtable automated backup defaults to seven days retention, with up to 90 days for automated policies and up to 365 days for on-demand backups in Enterprise Plus edition.
- BigQuery Lakehouse caches remote data blocks in the target Google Cloud region, so EU source data queried with US compute creates a US data-at-rest copy.
- Cloud Storage Object Lifecycle Management automatically transitions or deletes bucket objects only after they satisfy all configured conditions such as age or storage class.
Frequently Asked Questions
What is the difference between BigQuery table expiration and BigQuery partition expiration?
BigQuery table expiration deletes the entire table and all of its partitions and takes precedence over partition expiration, so a table with 5-day table expiration and 7-day partition expiration is deleted with all partitions after 5 days. BigQuery partition expiration expires each partition independently from its own partition boundary in UTC for ingestion-time or time-unit column partitioned tables, while integer-range partitioned tables do not support partition expiration.
How long can Cloud Bigtable backups be retained?
Cloud Bigtable automated backup defaults to seven days retention, and an automated backup policy can keep backups up to 90 days in both Enterprise and Enterprise Plus editions. An on-demand backup or an updated retention on an existing backup can be kept up to 90 days in Enterprise or up to 365 days in Enterprise Plus, while a copy of a backup can be kept for a maximum of 30 days from copy creation.
When should I use Cloud Storage Object Lifecycle Management (OLM) instead of manual deletion?
Use Cloud Storage Object Lifecycle Management when deletion or transition should happen automatically on a schedule, such as deleting logs after 30 days for compliance automation, rather than when a person or application issues an immediate delete. The lifecycle configuration lives on the bucket and Cloud Storage applies the configured action only after an object satisfies all configured conditions such as age or storage class.
How does BigQuery Lakehouse caching affect data residency when querying remote data?
BigQuery Lakehouse automatically caches retrieved remote data blocks locally within Google Cloud in the target region of the federated catalog or connection, and subsequent queries targeting the same blocks read directly from local Google Cloud storage. For example, when AWS Amazon S3 data in the European Union is paired with BigQuery compute in us-east4, data-at-rest cached copies reside in the U.S. region, and the user or administrator who creates the connection or catalog is responsible for ensuring that cross-jurisdiction caching complies with organizational data residency, sovereignty, and compliance requirements.
Sample Question
A financial enterprise stores regulated transaction records in Cloud Storage. Compliance mandates require that:
- All uploaded records must adhere to Write-Once-Read-Many (WORM) compliance and cannot be deleted or overwritten by any user or administrator for seven years.
- Individual transaction records subject to pending legal audits must be indefinitely protected from deletion, even if their standard retention duration expires during an investigation.
- Audit protections on specific records must be easily removable once legal proceedings conclude, without altering the underlying bucket configuration.
Which storage configuration strategy should the cloud architect implement to meet these requirements?
How learners score on this domain
Last updated