Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Cloud Backup and Disaster Recovery
Disaster Recovery and Business Continuity Planning is the practice of designing storage so work can resume within a Recovery Time Objective (RTO) and lose no more than a Recovery Point Objective (RPO). RTO is the maximum acceptable time to restore service, while RPO is the maximum acceptable data loss measured in time. In Google Cloud, Cloud Storage (opens in a new tab) and managed databases meet these objectives through cross-region replication, automatic failover, scheduled backups, and point-in-time recovery. Recovery workflows must be validated by restoring, cloning, or failing over in a test before a real outage occurs.
RTO and RPO Design Targets
RTO and RPO targets determine whether an architecture relies on live replication, backups, or both. Live replication across zones or regions keeps a second copy current and supports fast failover with very low RPO. Backups and exports protect against data corruption, accidental deletion, and ransomware, but restore takes longer and defines the RTO. Transfer speed, rate of data change, and restore method all affect whether the targets can be met, so transfer jobs and restore paths must be sized and tested to the required RPO and RTO.
Cross-Region Replication in Cloud Storage
Cross-region replication in Cloud Storage keeps object data available when a zone or region fails. Objects in dual-regions and multi-regions are stored in at least two geographically separate areas regardless of storage class, which provides 99.99% availability even during large-scale disruptions. Dual-regions use a pair of regions you choose, while multi-regions use data centers across the multi-region that can include locations beyond the listed regions. Standard replication between regions is asynchronous, so it does not promise when the second copy completes.
When a strict RPO is required, stronger replication controls are needed:
| Replication option | Scope | Replication behavior |
|---|---|---|
| Dual-regions | Two chosen regions in one dual-region bucket | Automatic storage in both regions with asynchronous sync |
| Turbo replication | Both regions of a dual-region bucket | Replicates 100% of newly written objects within 15 minutes for a 15-minute RPO |
| Cross-bucket replication | Source bucket to destination bucket in a different location | Asynchronously replicates objects to a separate bucket for geographic separation |
For high confidence that data is in an alternate region, another strategy is to use two single-region buckets and either dual-write each object to both buckets or write to one bucket and copy the object to the second bucket with Cloud Storage copy. If locality rules allow only one Google Cloud region, geographic redundancy cannot be built with Google Cloud alone, so a multi-cloud or hybrid copy in the same geographic area or an encryption-based workaround is used.
Protection Against Deletion and Corruption
Protection against deletion and corruption in Cloud Storage retains data after overwrites, deletes, or attacks so it can be rolled back without a full regional failover. Object Versioning preserves an overwritten or deleted live object as a noncurrent version that stays accessible until explicitly removed. Soft delete retains recently deleted objects and buckets for a set period, enabled by default with a seven-day retention period. These controls complement replication by handling logical disasters that replication alone would copy to the second site.
- Object holds: metadata flags on individual objects prevent deletion or overwrite of objects to be retained.
- Soft delete: recovers deleted objects and retains them for a specified period before permanent deletion.
- Object Versioning: preserves deleted objects as versioned, noncurrent objects that remain accessible in the bucket.
- Bucket Lock: retains all objects in a bucket for a minimum duration and locks the bucket retention policy so it cannot be reduced or removed.
- Object Retention Lock: retains individual objects for a minimum duration and locks the object retention policy so it cannot be reduced or removed.
Database Replication and Failover
Database replication and failover in Google Cloud combines synchronous replication with failover to keep reads and writes available during zonal or regional outages. Firestore (opens in a new tab) in Native mode and Datastore mode automatically handles replication with no extra provisioning. A regional database synchronously replicates across at least three zones for 99.99% availability, while a multi-region database synchronously replicates across five zones in three regions with two serving regions and one witness region for 99.999% availability. Traffic can continue serving from surviving zones or regions without rebuilding the database.
Other services apply the same pattern with service-specific failover. Bigtable production instances require at least two clusters in unique zones of a region, Google automatically synchronizes a separate copy in each zone, and incoming traffic can fail over to another cluster in the same instance. Cloud SQL uses a high-availability (HA) configuration for zonal failure and cross-region read replicas for regional failure, with automated backups plus binary logging enabling point-in-time recovery to a fresh instance. Cloud SQL Enterprise Plus edition provides advanced disaster recovery (DR) that simplifies recovery and fallback with zero data loss after a cross-regional failover. For Spanner, a warm standby instance with the minimum nodes for storage and throughput supports small RTO values, while node count directly controls how fast data can be read out or written back during copy-based recovery.
Exam tip: Standard dual-region storage replicates asynchronously with no fixed RPO, while Turbo replication guarantees a 15-minute RPO; use Turbo replication or dual-write to two single-region buckets when a strict RPO must be proven.
Backup, Point-in-Time Recovery, and Validation
Backup, point-in-time recovery (PITR), and validation address data disasters such as accidental deletion, corruption, or bad application writes. Backup and DR Service centralizes this work for Compute Engine workloads by backing up Persistent Disk snapshots to Cloud Storage buckets, with monitoring, auditing, reporting, and insights into ransomware and security threat events. Storage Transfer Service and Transfer Appliance move or periodically synchronize object and file data to, from, or between Cloud Storage, Amazon S3, and on-premises systems for backup and migration. To meet a transfer-based RPO, account for rate of change and transfer performance, where large files depend on bandwidth and many small files can be limited by request rate and may need multiple concurrent jobs.
Firestore and Spanner show how retention, cost, and RTO/RPO trade off:
| Recovery option | Retention and granularity | Restore behavior |
|---|---|---|
| Scheduled backups | Daily or weekly backups retained up to 14 weeks for Firestore; consistent Spanner backups retained up to 1 year | Restore to a new database in the same project at lower cost than PITR; Spanner restore mounts the backup directly without copying data for lower RTO than export |
| Point-in-time recovery (PITR) | Up to 7 days in the past at 1-minute granularity for Firestore and Spanner | Read or surgically write back only needed documents with RTO of 0 and RPO of 1 minute for Firestore; recover from operator or rollout errors in Spanner |
| PITR exports and clones | PITR export captures a timestamp up to 7 days old and stores it in Cloud Storage indefinitely; clone from up to 7 days ago with PITR enabled or up to 1 hour ago without it | Useful for archiving beyond 14 weeks, but recovery from an export is generally more expensive than from a backup |
Validation proves that the RTO and failover path actually work. Firestore backups restore to a new database, PITR exports can be imported from Cloud Storage, and database clone creates a separate copy from a past timestamp for testing without touching production. Spanner commit timestamps support incremental backups by selecting rows changed since the last full backup, and scheduled Dataflow or Managed Airflow directed acyclic graphs (DAGs) can automate BigQuery, Firestore, MySQL, and PostgreSQL exports to Cloud Storage on a daily schedule. Simulated maintenance events for Cloud SQL and trial failovers for Bigtable and Cloud SQL confirm that applications reconnect and that distance, bandwidth, and key-availability dependencies do not break the RTO.
Persistent Disk and Managed Database Protection is the practice of creating restorable copies of block storage and managed databases so workloads can recover from deletion, corruption, or regional outages. For Persistent Disk, protection centers on snapshots of Compute Engine virtual machines (VMs) that are stored in Cloud Storage (opens in a new tab) and managed centrally. For managed relational databases such as Cloud SQL, protection centers on automated backups combined with point-in-time recovery (PITR) to minimize data loss.
Persistent Disk Protection with Backup and DR Service
Persistent Disk protection with Backup and DR Service provides secure storage and centralized backup management at scale for VMs and other workloads running in Google Cloud. Data flows from the Compute Engine VM to its Persistent Disk snapshot, then from the snapshot to a Cloud Storage bucket where the backup is retained. The service depends on the snapshot as the capture point and on the bucket as the durable copy, so recovery depends on both being available in the required location. Centralized monitoring, auditing, and reporting support compliance, while insights into security threat events help defend against ransomware and other risks.
Persistent Disk volumes are durable network storage that VMs access like physical disks, so losing the disk means losing the VM file system and application data. Scheduled snapshot-based backups create consistent restore points without keeping the recovery copy on the same disk that failed. Choose Backup and DR Service when many VMs need consistent, centrally managed protection with compliance reporting rather than one-off manual snapshots.
Relational Database Protection with Point-in-Time Recovery
Relational database protection with point-in-time recovery restores a Cloud SQL database from a backup and recovers it to a fresh Cloud SQL instance. Cloud SQL is the fully managed Google Cloud relational database service for MySQL and PostgreSQL. Protection first requires enabling automated backups and binary logging on the instance, then recovery replays logs on top of the selected backup to reach the desired point in time. The restored database runs on a new instance, so applications must be pointed to the fresh instance after recovery is complete. This order matters because without both the base backup and the continuous log history, recovery cannot move past the last backup point.
Availability during zonal or regional failure is handled separately from backup by replication and configuration choices:
- High availability (HA) configuration keeps the Cloud SQL instance available through zonal failure.
- Cross-region replicas keep a readable copy in another region to maximize uptime during regional failure.
- Advanced disaster recovery for Cloud SQL Enterprise Plus edition simplifies recovery and fallback with zero data loss after a cross-regional failover.
Choose automated backups plus binary logging when the goal is minimum data loss from corruption or accidental writes, and add HA or cross-region replicas when the goal is continued serving during infrastructure outages.
Managed Database Retention and Restore Choices
Managed database retention and restore choices differ by retention window, PITR window, and restore behavior. Spanner Backup and Restore creates consistent backups that can be retained for up to 1 year, and restore directly mounts the backup without copying the data, which gives a lower recovery time objective (RTO) than export to Avro files in Cloud Storage. Firestore in Datastore mode (opens in a new tab) supports scheduled daily or weekly backups with up to 14 weeks retention and restores to a new database in the same project. Both Spanner and Firestore in Datastore mode support PITR for up to 7 days in the past to recover from operator error or bad application writes.
| Service | Backup retention | PITR window | Restore behavior |
|---|---|---|---|
| Cloud SQL | Automated backups plus binary logs | Point-in-time within log history | Restores to a fresh Cloud SQL instance |
| Spanner | Consistent backups up to 1 year | Up to 7 days in the past | Restore mounts backup without copying data |
| Firestore in Datastore mode | Scheduled backups up to 14 weeks | Up to 7 days, 1-minute granularity | Restores to a new database in same project |
Firestore in Datastore mode PITR can read documents from a point in time and surgically write back only the needed data, with a recovery time objective of 0 and a recovery point objective of 1 minute. PITR reads provide lower RTO and lower RPO than full backup restore when only part of the database is damaged. For retention beyond 14 weeks, a PITR data export can save a full database copy in Cloud Storage indefinitely, but recovering from that export is generally more expensive than recovering from a backup.
Exam tip: Cloud SQL PITR always recovers to a fresh instance, while Spanner restore mounts the backup without copying data for faster recovery than export and re-import.
Cloud Storage Resiliency and Compliance is the combination of controls in Cloud Storage (opens in a new tab) that keep object data durable, available, and immutable when regulations or business continuity require it. Resiliency comes from redundant storage across zones and regions plus recovery controls that restore overwritten or deleted objects. Compliance comes from retention policies that prevent deletion for a minimum duration and lifecycle policies that move data to lower-cost archival tiers automatically.
Recovery From Accidental or Malicious Deletion
Recovery from accidental or malicious deletion in Cloud Storage preserves objects after they are overwritten or deleted so they can be restored. Object Versioning automatically archives an overwritten or deleted live object as a noncurrent version that remains accessible in the same bucket until it is explicitly removed or expires. Soft delete retains recently deleted objects and buckets for a specified period before they are permanently deleted, and Cloud Storage enables soft delete for all buckets by default with a seven day retention period. Object holds prevent individual objects from being deleted or overwritten by placing metadata flags on the objects that must be retained.
Object Deletion Recovery Lifecycle
State / Lifecycle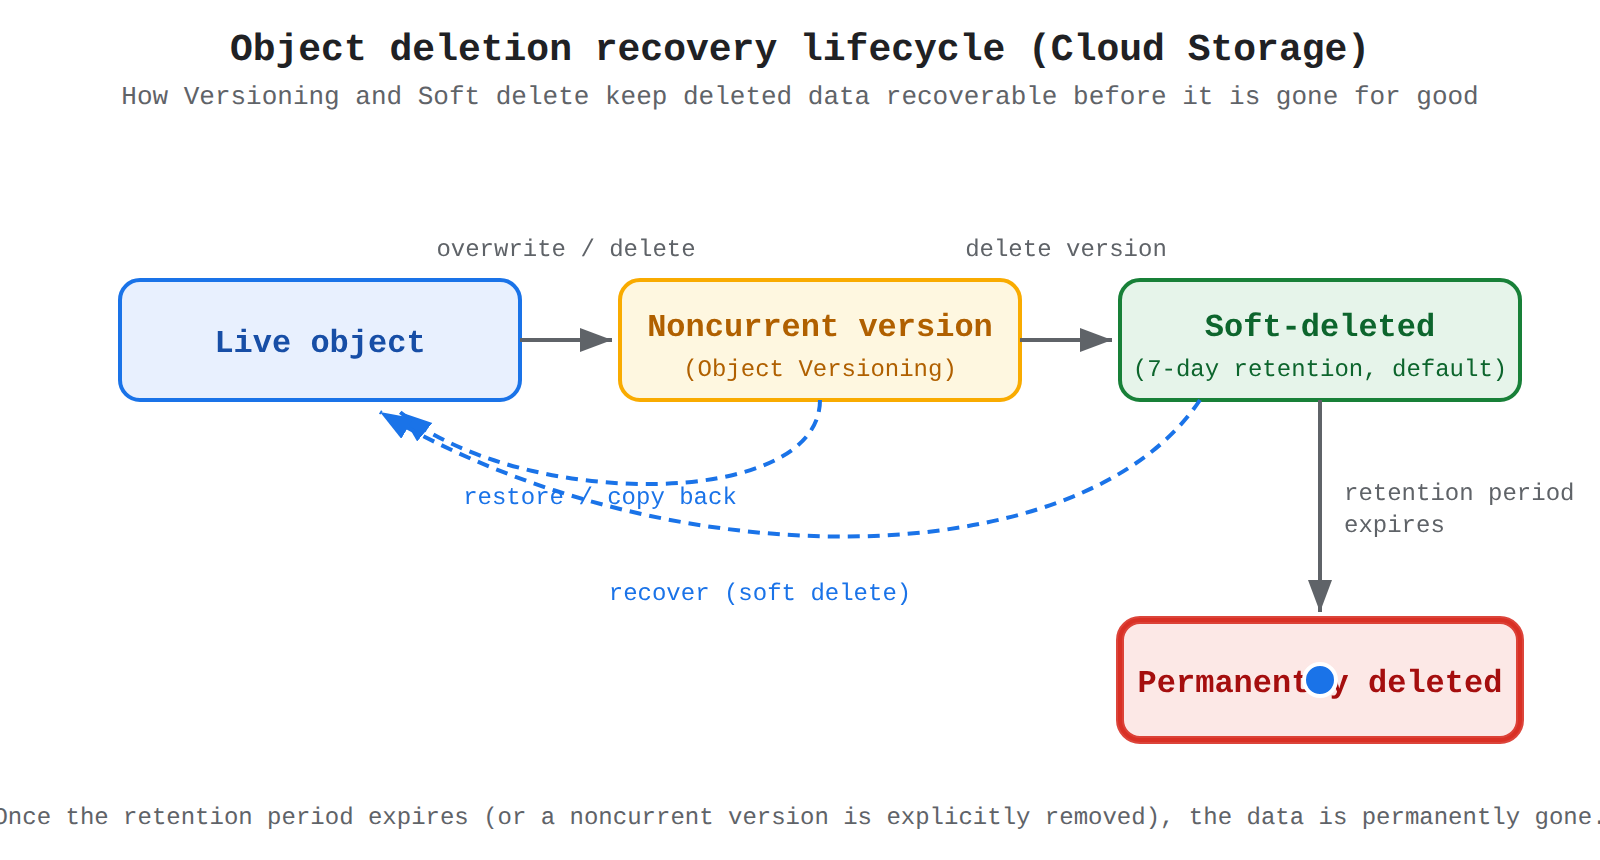
A state lifecycle diagram showing a Cloud Storage object moving from Live, to a Noncurrent version via Object Versioning, to a Soft-deleted state held for a 7-day retention period, and finally to Permanently deleted, with dashed restore paths back to Live. The animation traces a dot through the states in order, highlighting each state as the object reaches it.
The recovery flow moves data through ordered states. First, an application overwrites or deletes a live object in a bucket. Then, Object Versioning converts the prior object to a noncurrent version while soft delete holds a deleted object in a soft-deleted state for its retention period. Only after the retention period expires or an administrator explicitly removes the noncurrent version is the data permanently gone.
Retention Controls for Regulatory Compliance
Retention controls for regulatory compliance in Cloud Storage enforce immutable minimum retention periods that satisfy legal and regulatory requirements. Bucket Lock defines a data retention requirement on a per-bucket basis, so every object in the bucket must be retained for the specified minimum duration. Object Retention Lock defines the requirement on a per-object basis by applying an immutable retain-until date and time to specific objects, which prevents those objects from being deleted or replaced until that duration expires.
| Control | Scope of policy | How immutability works |
|---|---|---|
| Bucket Lock | All objects in a bucket | Bucket retention policy governs how long objects must be retained; the policy can be locked to prevent it from being reduced or removed |
| Object Retention Lock | Individual objects | Object retention policy sets a retain-until time on each object; the policy can be locked to prevent it from being reduced or removed |
| Object holds | Individual objects | Metadata flag blocks deletion or overwrite of flagged objects until the hold is released |
Once a Bucket Lock or Object Retention Lock policy is locked, the retention period cannot be shortened or removed, so even administrators and malicious actors cannot delete protected data early. Choose Bucket Lock when the same compliance rule applies to an entire bucket, and choose Object Retention Lock when different objects need different retain-until times.
Exam tip: Bucket Lock applies one minimum duration to every object in the bucket, while Object Retention Lock applies an individual retain-until time to a specific object; both become unchangeable once locked.
Lifecycle Management for Automated Archival
Lifecycle management for automated archival in Cloud Storage automatically deletes or transitions objects by using custom rule-based policies, which reduces cost without manual movement. Object Lifecycle Management evaluates object age, storage class, or version state, and then the service moves the object from a frequent-access class to an archival class or deletes expired noncurrent versions. Autoclass automatically transitions objects between storage classes based on each object's access pattern when access frequency varies or the retention period is unknown.
Archival targets are chosen by minimum storage duration and access frequency:
- Standard storage: for data that is accessed frequently, including analytics, data lakes, websites, and mobile apps.
- Nearline storage: for low-cost infrequently accessed data that can be stored for at least 30 days, such as backups and long-tail multimedia content.
- Coldline storage: for low-cost infrequently accessed data that can be stored for at least 90 days, such as disaster recovery data.
- Archive storage: for lowest-cost infrequently accessed data that can be stored for at least 365 days, including regulatory archives.
Lifecycle Management depends on Object Versioning when history must be kept, because the lifecycle policy can retain a configured maximum number of versions per object and expire noncurrent versions after a set number of days. This dependency lets a bucket automatically keep recent history for rollback while aging older history into Archive storage or deletion.
Geographic Redundancy and Replication for Availability
Geographic redundancy and replication for availability in Cloud Storage protects data against zone and region failures while maintaining high durability. Cloud Storage is designed for at least 99.999999999% (11 9's) annual durability regardless of storage class and location type by using erasure coding, storing data pieces redundantly across multiple devices, and regularly revalidating checksums to detect and correct corruption. Monthly availability depends on the storage class and the location type of the bucket.
Location types determine where redundant copies live and how writes are confirmed. Regional buckets store data redundantly in at least two availability zones in the selected region and confirm object writes only after data is redundantly stored across at least two different zones, so they tolerate loss of any one zone. Dual-region and multi-region buckets store data redundantly in at least two separate geographic places for 99.99% availability and remain available during a region-wide outage with no change to storage paths. For dual-regions, the administrator selects the specific pair of regions; for multi-regions, Cloud Storage selects data centers within the geographic boundary that are separated by at least 100 miles, which provides cross-region redundancy at lower cost than dual-regions.
Replication between regions is asynchronous by default and can be accelerated for strict recovery objectives. Object writes to dual-region and multi-region buckets are first confirmed after redundant storage in one initial region across at least two zones, then data flows from the initial region to the second region through default replication. Turbo replication is a premium option on dual-region buckets that replicates 100% of newly written objects between the dual-region pair within 15 minutes for a tighter recovery point objective (RPO). Cross-bucket replication asynchronously replicates data from a source bucket to a destination bucket in a different location through Storage Transfer Service, which achieves redundancy between region pairings that are not available as a single dual-region.
Key Facts
- RTO is the maximum acceptable time to restore service, while RPO is the maximum acceptable data loss measured in time.
- Turbo replication on a dual-region Cloud Storage bucket replicates 100% of newly written objects within 15 minutes for a 15-minute RPO, while standard dual-region replication is asynchronous with no fixed RPO.
- Cloud Storage enables soft delete by default with a seven-day retention period, and Object Versioning preserves an overwritten or deleted live object as a noncurrent version.
- Cloud SQL point-in-time recovery requires automated backups plus binary logging and restores to a fresh Cloud SQL instance.
- Spanner consistent backups can be retained up to 1 year and restore by mounting without copying data, while Firestore scheduled backups are retained up to 14 weeks with point-in-time recovery up to 7 days at 1-minute granularity.
Frequently Asked Questions
What is the difference between Recovery Time Objective (RTO) and Recovery Point Objective (RPO) in disaster recovery planning?
Recovery Time Objective (RTO) is the maximum acceptable time to restore service, while Recovery Point Objective (RPO) is the maximum acceptable data loss measured in time. Live replication supports fast failover with very low RPO, while backups and exports protect against corruption and deletion but restore takes longer and defines the RTO.
When should I use Turbo replication instead of standard replication for Cloud Storage dual-region buckets?
Turbo replication on a dual-region Cloud Storage bucket replicates 100% of newly written objects between the pair within 15 minutes for a 15-minute Recovery Point Objective (RPO), while standard dual-region replication is asynchronous with no fixed RPO. Use Turbo replication or dual-write to two single-region buckets when a strict RPO must be proven.
How does point-in-time recovery (PITR) work for Cloud SQL databases?
Point-in-time recovery (PITR) for Cloud SQL requires enabling automated backups and binary logging and then restores to a fresh Cloud SQL instance by replaying logs on top of the selected backup. Applications must be pointed to the fresh instance after recovery is complete.
What is the difference between Bucket Lock and Object Retention Lock in Cloud Storage?
Bucket Lock defines a minimum retention requirement for all objects in a Cloud Storage bucket, while Object Retention Lock applies an individual retain-until time to a specific object. Once either policy is locked, the retention period cannot be shortened or removed.
Sample Question
An enterprise runs a mission-critical database workload on a primary Cloud SQL instance located in us-central1. To achieve a low Recovery Time Objective (RTO) and Recovery Point Objective (RPO) in the event of a regional disaster, the team configured a cross-region disaster recovery (DR) replica in us-east1 and connected their applications using a Cloud SQL DNS write endpoint.
A sudden regional outage occurs in us-central1, rendering the primary database instance completely inaccessible.
Which failover procedure should the cloud architect execute to restore write operations in the secondary region with minimal application downtime?
How learners score on this domain
Last updated