Intermediate
Prepare and test your skills
Intermediate
Prepare and test your skills
Cost Optimization with Storage Lifecycle and Discounts
Storage Class and Data Lifecycle Management is the practice of keeping each object in the cheapest storage that still meets its access, performance, and retention needs. In Cloud Storage (opens in a new tab), the storage class controls the price of keeping data, while automated rules move or delete objects as they age. Together they stop active data from sitting in expensive storage and stop old data from growing without limit.
Choosing the Right Cloud Storage Class
Choosing a Cloud Storage class means matching the class to how often data is read and how long it must be kept. New ingestion data that arrives often should start in Standard class, because frequent production reads need fast, ready access. Older or rarely read data can move down to a lower-cost class where cheaper storage matters more than instant access.
| Class | Best for | Access pattern |
|---|---|---|
| Standard | Actively used datasets, such as current production models | Frequent, performance-sensitive reads |
| Nearline or Coldline | Older training datasets or less-frequently accessed backups | Infrequent reads where lower storage cost matters more |
| Archive | Long-term retention kept for compliance or future use | Rare reads, optimized for efficiency at scale |
The tradeoff flows from access to cost. Keep active objects in Standard, transition infrequently accessed objects to Nearline or Coldline, and keep long-term retention objects in Archive. Choose single-region buckets when data does not need to survive a regional outage, because dual- and multi-region buckets carry different prices and charges for inter-region replication. Use multi-region replication only when reliability needs for the workload, data, and processes require it.
Storage Aging: Standard to Delete
State / Lifecycle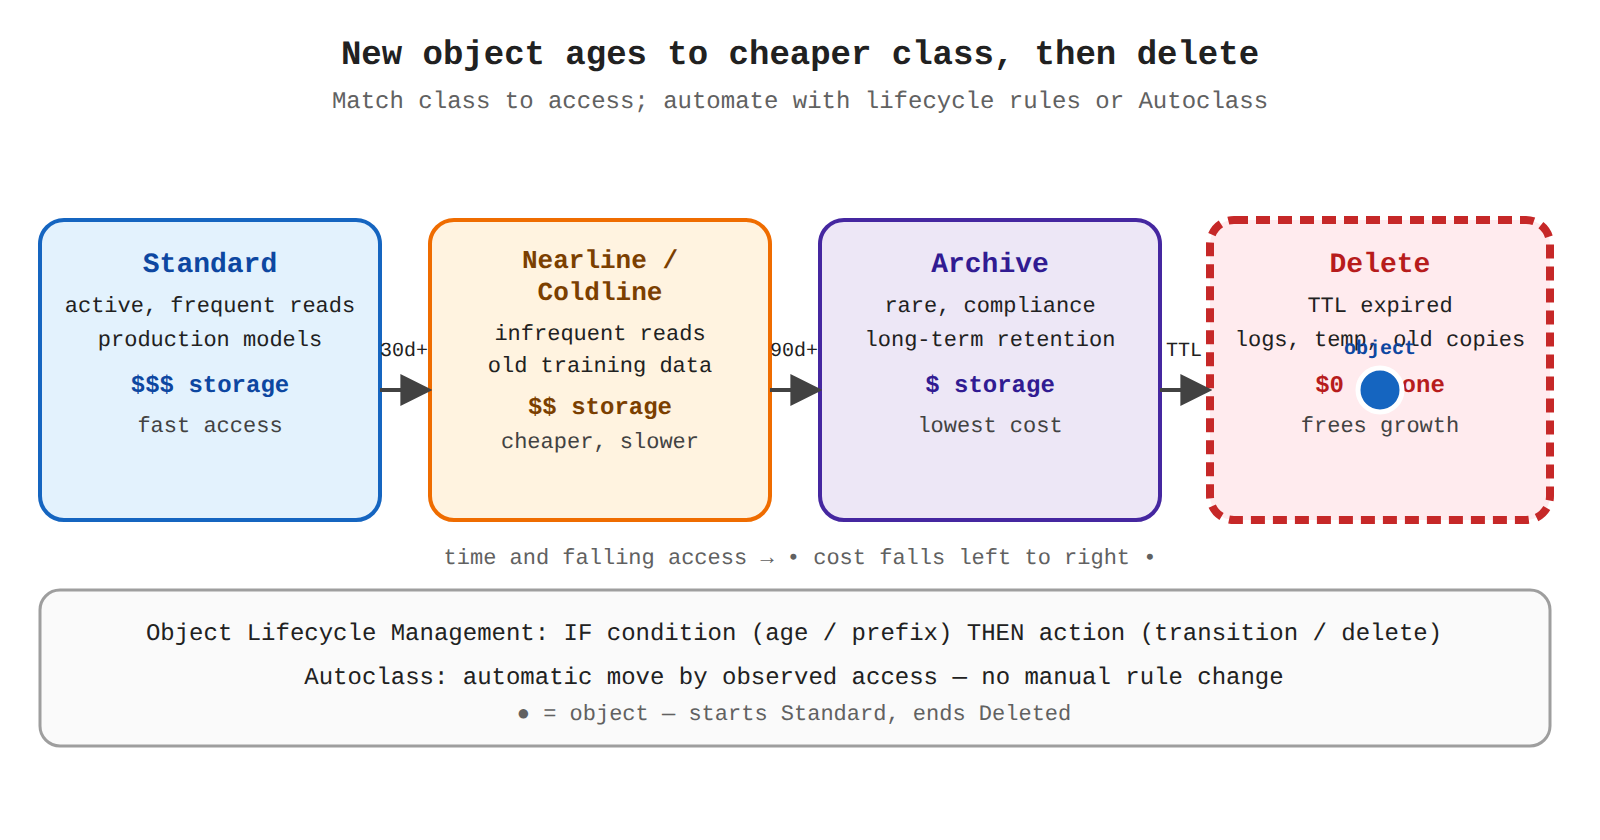
Four states left to right: Standard for active reads, Nearline/Coldline for infrequent reads, Archive for rare retention, then Delete. A dot labeled object moves monotonically from Standard through the middle classes and holds at Delete, showing lifecycle condition-to-action transitions.
Object Lifecycle Management
Object Lifecycle Management (opens in a new tab) is the Cloud Storage feature that automatically transitions objects to a cheaper class or deletes them. Each rule pairs a condition, such as object age, with an action, so data flows from the ingestion bucket in Standard class to a cheaper class and finally to deletion only after the condition is met. This automation matters because stored data can grow to large amounts quickly and manual cleanup cannot keep up.
Cost-saving lifecycle patterns use the same condition-to-action flow:
- Delete unneeded data, such as log files, temporary model artifacts, and outdated intermediate results, after a defined time to live (TTL).
- Generate aggregate data from detailed data and move only the aggregate data into long-term storage.
- Move data that is needed less often to less expensive systems designed for infrequent access.
Define clear, automated TTL policies for non-essential data so rules delete that data after the defined period. For regulated data, set the retention period in the rule to match the legal requirement instead of deleting early.
Autoclass for Automatic Transitions
Autoclass (opens in a new tab) is the Cloud Storage feature that moves each object to the right class based on its observed access pattern. The service depends on access telemetry for each object, so an object that stops being read moves down without an administrator changing a rule. Object Lifecycle Management depends instead on conditions set in advance, such as age or prefix, and then applies the same downgrade or delete action to every matching object.
Exam tip: Use Object Lifecycle Management when you can define conditions for downgrade or deletion, and use Autoclass when you want Cloud Storage to transition each object automatically based on its access pattern.
Governing Retention with Tags and Policies
Governing retention with tags and policies connects each bucket and object to an owner and a retention requirement. Mandate consistent tags and labels on Cloud Storage buckets, BigQuery datasets, and persistent disks that show data owner, purpose, and retention period. The Organization Policy Service (opens in a new tab) enforces constraints that require tags such as retention period, so new buckets cannot be created without the metadata that automation and cost reports depend on.
Tags let the same system serve cost, compliance, and reporting goals at once. Lifecycle automation reads the retention tag to decide when to transition or delete, FinOps reports group spend by owner and purpose, and carbon reports trace storage use to the responsible team. Audit persistent disks and snapshots on the same cycle, because over-provisioned disks and old, unused snapshots keep charging for storage that object rules do not clean up.
Strategic pricing and discount models are methods for lowering the billing rate paid for Google Cloud resources through commitments and workload placement. Committed Use Discounts (CUDs) (opens in a new tab) give lower prices for one-year or three-year commitments, while enterprise discounts give negotiated rates for minimum total spend. Spot VMs (opens in a new tab) give very low prices for flexible workloads, and choices for BigQuery (opens in a new tab) editions and regions further reduce analytics and regional service costs.
Enterprise Discounts
Enterprise discounts are negotiated discounts based on a commitment to a minimum total spend on Google Cloud at a reduced billing rate. The central FinOps team is responsible for optimizing billing rates because it sees resource needs across the whole organization. That team can combine needs from product and engineering teams to maximize commitment-based discounts. Significant savings are possible by using Committed Use Discounts (CUDs) on top of enterprise discounts.
Resource-Based and Spend-Based Committed Use Discounts
Resource-based and spend-based Committed Use Discounts are discounts received for committing to a minimum level of use for one year or three years. Resource-based CUDs commit to a minimum quantity of Compute Engine resources, while spend-based CUDs commit to spend a minimum amount on a particular product. Choose resource-based CUDs when Compute Engine use in a specific region is predictable and steady, and choose spend-based CUDs when product spend is predictable but use may vary by region or shape.
| Commitment type | Commitment basis | Term and scope |
|---|---|---|
| Resource-based CUDs | Minimum quantity of Compute Engine resources | One-year or three-year term, for resources in a specific region |
| Spend-based CUDs | Minimum spend amount on a particular product | One-year or three-year term, at the billing account level, applied regionally or globally by product |
Resource-based CUD sharing lets the discount be shared across all projects under a Cloud Billing account, and Google Cloud enables this sharing for most billing accounts. Because the commitment depends on the billing account relationship, combined usage from many projects can consume the same regional commitment. This sharing makes the central FinOps view important for sizing the commitment to total predictable demand.
Exam tip: Resource-based CUDs are quantity-based for Compute Engine in a specific region, while spend-based CUDs are spend-based for a product at the billing account level.
Spot VMs for Fault-Tolerant Workloads
Spot VMs are Compute Engine virtual machines that use unused capacity at a price more than 80% cheaper than regular VMs. Spot VMs suit fault-tolerant and flexible workloads, such as batch jobs that can tolerate preemption and do not need high availability. Compute Engine may preemptively stop or delete Spot VMs to reclaim capacity, so the workload must handle interruptions. Choose Spot VMs when the workload is flexible and can be retried or distributed, and choose CUDs when the workload is predictable and must run continuously.
BigQuery Editions and Region Selection
BigQuery editions and region selection control the unit rate paid for analytics and regional services. On-demand pricing charges for queries as they run, while edition-based pricing lowers the cost per slot when analytics volume is large and steady enough for a commitment. Choose an appropriate edition when slot use is large and steady so the commitment reduces unit cost. Carefully evaluate Google Cloud regions because regions differ in price and must also meet latency and compliance needs. Use the Google Cloud Region Picker (opens in a new tab) to understand trade-offs between cost, sustainability, and latency before selecting a region.
Resource Governance and Rightsizing Operations is the practice of matching cloud capacity to real demand and tracing every dollar to its owner. Recommender (opens in a new tab) analyzes utilization history to suggest smaller sizes or deletions, Cloud Monitoring (opens in a new tab) supplies the real-time metrics behind those suggestions, and Cloud Billing (opens in a new tab) reports show the financial effect. Together they prevent over-provisioning that wastes money and under-provisioning that hurts performance. Governance ties the loop together with hierarchy and labels so savings persist.
Identify Underutilized Assets with Recommender
Recommender, delivered as Active Assist, is the Google Cloud service that analyzes utilization history and creates rightsizing and cleanup suggestions without charge and without manual setup. Utilization data flows from Cloud Monitoring to Recommender, and Recommender sends recommendations to administrators in the console, API, or FinOps hub. Active Assist covers services including Compute Engine for core applications, Cloud Run for microservices, BigQuery for analytics, and Cloud SQL for relational databases. The recommendations focus on idle resources and underused commitments that are easy to miss at scale.
The following recommendation types support governance decisions:
| Recommendation | What it identifies | Governance action |
|---|---|---|
| Idle VM recommendation | Compute Engine instances with consistently low utilization | Verify impact, then stop or decommission the instance |
| Idle resources recommendation | Unattached disks, unused IPs, and other orphaned resources | Delete the resource to remove ongoing charges |
| Machine type recommendation | Virtual machines (VMs) sized larger or smaller than demand | Change to a more cost-effective machine type |
Decommissioning removes cost completely, while rightsizing keeps performance at a lower price. Both actions depend on Cloud Monitoring data, so the workflow depends on continuous observability before any deletion or resize.
Rightsize Virtual Machine Instances
Rightsizing virtual machine instances is the process of adjusting Compute Engine machine types and counts to match observed CPU, memory, and traffic demand. Over-provisioned VMs waste budget on unused capacity, while under-provisioned VMs throttle applications and hurt user experience. Cloud Monitoring provides real-time visibility into usage patterns that reveals both conditions. Recommender then turns those patterns into a specific target size, such as moving to a smaller machine type.
Rightsizing stays proactive when teams use custom metrics and alerts tied to business workloads. Custom metrics track application signals that standard CPU charts miss, and alerting policies notify administrators when a threshold is crossed. The administrator then reviews the Recommender suggestion and applies the resize, so control flows from metric to alert to human-approved action. This order prevents automatic changes that could disrupt production while still allowing timely adjustment.
Track Spending with Cloud Billing Reports
Cloud Billing reports are built-in views that show cost history, current trends, and forecasted spend by service, project, and time period. Billing data flows from Cloud Billing to built-in reports and dashboards for quick review, and to BigQuery through billing export for deeper analysis with custom SQL. The FinOps hub (opens in a new tab) centralizes that view so finance and audit teams can track posture across business units. The anomaly detection dashboard in Cloud Billing flags unexpected spikes for prompt investigation.
A consistent cost-monitoring cycle keeps governance effective:
- Review billing reports regularly: Check built-in Cloud Billing reports for usage costs, invoices, cost breakdowns, and pricing tables.
- Analyze enriched data in BigQuery: Filter and aggregate exported billing data by labels, projects, or time periods to attribute training, inference, or departmental spend.
- Configure budgets and alerts: Create budgets that compare actual spend to planned spend and send notifications before overruns grow.
Custom dashboards built on BigQuery, Looker, or Data Studio visualize key performance indicators (KPIs) and track progress toward reduction goals. Reports let teams filter by resource type or period to find the drivers of growth.
Exam tip: Active Assist recommendations require no configuration and no extra charge, while detailed chargeback analysis requires billing export to BigQuery with consistent labels.
Allocate Costs with Labels and Resource Hierarchy
Cost allocation with labels and resource hierarchy attaches business context to every resource so spend can be traced to who spent it and why. The hierarchy flows from organization to folders to projects to resources, which mirrors departments, environments, and applications. Labels and tags are key-value pairs on resources, such as team=banking_appdev, region=emea, or product=frontend, that categorize spend in billing reports. Cloud Billing then groups costs by those pairs, so raw usage becomes accountable ownership.
Effective allocation depends on three metadata rules:
- Validity: Choose tags that map to KPIs, cost centers, and regulatory needs so finance can use them for showback, chargeback, and audits.
- Automation: Enforce labeling through infrastructure as code tools like Terraform so every new resource is categorized at creation and manual errors are avoided.
- Simplicity: Measure a small set of uncorrelated factors and avoid complex edge-case rules that confuse operational teams.
Consistent conventions make billing data queryable, and Google Cloud cost allocation distributes shared costs across teams based on usage. When labels, hierarchy, and billing accounts are combined in dashboards, teams can answer not only what was spent but which product and purpose drove the spend and whether re-architecture would preserve value at lower cost.
Key Facts
- Cloud Storage costs are optimized by keeping active objects in Standard, moving infrequently accessed objects to Nearline or Coldline, and keeping long-term retention objects in Archive.
- Object Lifecycle Management applies condition-to-action rules to transition or delete objects, while Autoclass moves each object automatically based on its observed access pattern.
- Resource-based Committed Use Discounts commit to a Compute Engine quantity in a specific region, while spend-based Committed Use Discounts commit to a spend amount on a product at the billing account level.
- Spot VMs use unused Compute Engine capacity at more than 80% discount but can be preempted, so they suit only fault-tolerant, flexible workloads.
- Recommender analyzes Cloud Monitoring utilization data to suggest idle VM cleanup and machine type rightsizing, while Cloud Billing reports and billing export to BigQuery attribute spend by labels, projects, and hierarchy.
Frequently Asked Questions
What is the difference between Object Lifecycle Management and Autoclass in Cloud Storage?
Object Lifecycle Management transitions or deletes objects using condition-to-action rules such as object age or prefix that apply the same action to every matching object, while Autoclass moves each object to the right class automatically based on its observed access pattern. Use Object Lifecycle Management when conditions for downgrade or deletion can be defined in advance and use Autoclass when objects should move down without an administrator changing a rule after access stops.
When should I use Standard, Nearline or Coldline, and Archive storage classes in Cloud Storage?
Keep actively used datasets in Standard for frequent performance-sensitive reads, move older training datasets or less-frequently accessed backups to Nearline or Coldline for infrequent reads where lower storage cost matters more, and keep long-term retention for compliance or future use in Archive for rare reads optimized for efficiency at scale. Choose single-region buckets when data does not need to survive a regional outage and use multi-region replication only when reliability needs for the workload, data, and processes require it because dual- and multi-region buckets carry different prices and charges for inter-region replication.
What is the difference between resource-based Committed Use Discounts (CUDs) and spend-based Committed Use Discounts (CUDs)?
Resource-based Committed Use Discounts (CUDs) commit to a minimum quantity of Compute Engine resources in a specific region for a one-year or three-year term, while spend-based Committed Use Discounts (CUDs) commit to a minimum spend amount on a particular product at the billing account level for a one-year or three-year term. Choose resource-based CUDs when Compute Engine use in a specific region is predictable and steady and choose spend-based CUDs when product spend is predictable but use may vary by region or shape.
When should I use Spot VMs instead of Committed Use Discounts (CUDs) for Compute Engine workloads?
Spot VMs use unused Compute Engine capacity at more than 80% cheaper than regular VMs but can be preemptively stopped or deleted to reclaim capacity, so they suit only fault-tolerant and flexible workloads such as batch jobs that can tolerate preemption. Choose Spot VMs when the workload is flexible and can be retried or distributed and choose Committed Use Discounts (CUDs) when the workload is predictable and must run continuously.
Sample Question
A financial services organization ingests large volumes of transaction audit records into Google Cloud Storage. The data lifecycle requirements and access patterns are defined as follows:
- First 30 days: Records are actively analyzed and queried on a daily basis.
- Day 31 to 365: Records are accessed at most once per quarter during periodic compliance reviews.
- Day 366 to Year 7 (2,555 days): Records are kept strictly for legal compliance, accessed less than once a year, and must be retrievable within milliseconds when requested.
- After 7 years: Records must be permanently purged to comply with data privacy policies.
You need to design an automated, cost-optimized storage lifecycle strategy for the bucket.
Which configuration should you implement?
Enable Autoclass on the bucket, and configure an Object Lifecycle Management rule with a
SetStorageClassaction to transition objects to Archive at age 365 days and aDeleteaction at age 2,555 daysSet the default bucket storage class to Standard, and configure Object Lifecycle Management rules with
SetStorageClassto Coldline at age 30 days,SetStorageClassto Archive at age 365 days, andDeleteat age 2,555 daysSet the default bucket storage class to Archive, and configure an Object Lifecycle Management rule to transition objects to Standard for the first 30 days and delete them after 2,555 days
Set the default bucket storage class to Standard, and deploy a Cloud Run function triggered by Cloud Scheduler to rewrite objects to Coldline and Archive and delete expired records
How learners score on this domain
Last updated