Fundamental
Prepare and test your skills
Fundamental
Prepare and test your skills
Daily Mirror Sync with Storage Transfer Service
Free sample question, answered and explained below. The Associate Data Practitioner practice bank has 1,156 more like it. Try 10 free: instant score, no account.
A data engineering team is setting up a recurring data ingestion pipeline using Google Cloud Storage Transfer Service to sync files from an external object storage bucket to a destination Cloud Storage bucket. The team has the following requirements:
- The transfer must execute automatically every 24 hours.
- Existing files in the destination bucket must only be replaced if the corresponding source file has been modified or updated.
- The destination Cloud Storage bucket must remain an exact replica of the source, meaning files deleted from the source bucket must also be removed from the destination bucket.
Which configuration settings should the team choose when creating the transfer job?
Explanations
Set the schedule frequency to Run every day, configure the overwrite condition to If different, and set the deletion option to Delete files from destination if they're not also at source.
Set the schedule frequency to Run every day, configure the overwrite condition to If different, and set the deletion option to Delete files from destination if they're not also at source.
What Storage Transfer Service Configuration is
Storage Transfer Service provides granular options to control scheduling, object overwrite rules, and object lifecycle actions during data ingestion jobs. When configuring a transfer between cloud object stores, parameters can be customized in the Google Cloud Console, via the gcloud transfer jobs create command, or programmatically through the REST API.
How it meets all requirements
- Automated 24-hour execution (✓): Setting the schedule to Run every day ensures the transfer job triggers on a daily recurring basis starting at a designated time without requiring manual intervention or external cron jobs.
- Overwriting only updated files (✓): Choosing the If different overwrite policy ensures that destination objects are only replaced when the source object has a different ETag or checksum value. Identical files are skipped, optimizing network bandwidth and transfer time.
- Exact replica synchronization (✓): Selecting Delete files from destination if they're not also at source instructs the service to remove extraneous files from the destination bucket that no longer exist in the source repository, maintaining an exact mirror.
Exact Replica Sync on a Daily Schedule
Process Flow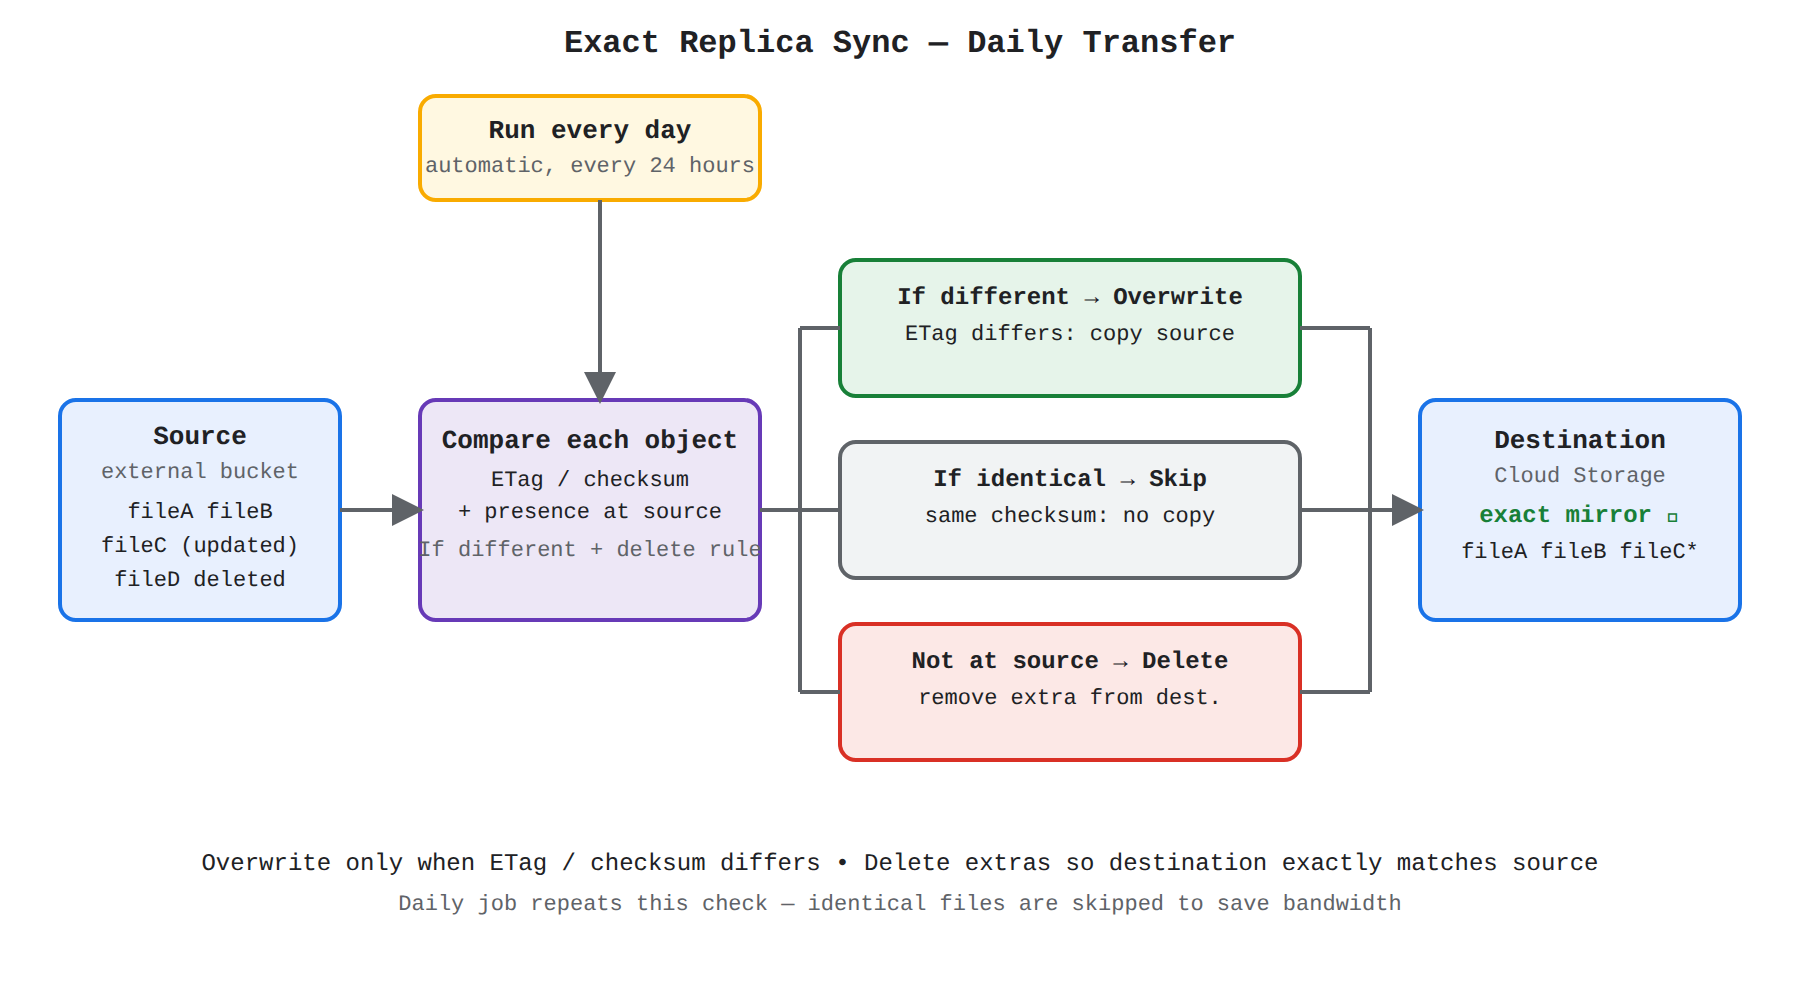
Key advantages and capabilities
- Bandwidth efficiency: By comparing ETags and checksums, only modified and newly added objects are transmitted across networks.
- Automated orchestration: Built-in scheduling in Universal Time Coordinated (UTC) eliminates the need for separate schedulers like Cloud Scheduler.
- Data consistency: Bidirectional state matching ensures target buckets reflect source states accurately for downstream analytical workflows.
- Serverless scaling: Google Cloud manages underlying transfer worker infrastructure automatically to optimize throughput.
Why this is optimal
This configuration cleanly satisfies all functional criteria using native, managed features of Storage Transfer Service. It avoids unnecessary data egress and transfer costs by skipping unchanged files while guaranteeing synchronization consistency by cleaning up orphaned objects.
Set the schedule frequency to Run with custom frequency set to every 30 days, configure the overwrite condition to If different, and set the deletion option to Never.
Set the schedule frequency to Run with custom frequency set to every 30 days, configure the overwrite condition to If different, and set the deletion option to Never.
What this configuration option does
This option schedules the data transfer to run monthly (every 30 days), compares checksums to overwrite modified files, and retains all files indefinitely at both the source and destination.
Why it doesn't meet the requirement
- Incorrect scheduling frequency (✗): Scheduling a transfer for every 30 days violates the explicit requirement to run automatically every 24 hours.
- Orphaned destination files (✗): Setting the deletion option to Never ensures no files are ever deleted. Consequently, if a file is deleted from the source bucket, it will remain in the destination bucket, violating the requirement for an exact replica.
Key characteristics and limitations
- Monthly cadence: Custom intervals can be defined in hours, days, or weeks, but a 30-day frequency leaves data stale for analytical consumers.
- Accumulation of stale data: Without destination deletion rules, target storage steadily diverges from the source over time as files are retired at the origin.
- Non-destructive: Retains all historical files across both repositories.
This answer would be correct if
The team required a monthly cumulative backup where no data should ever be removed from Cloud Storage, even if deleted upstream.
Set the schedule frequency to Run every day, configure the overwrite condition to Never, and set the deletion option to Delete file from source after they're transferred.
Set the schedule frequency to Run every day, configure the overwrite condition to Never, and set the deletion option to Delete file from source after they're transferred.
What this configuration option does
This configuration sets a daily scheduled transfer that skips any files that already exist in the destination bucket and purges transferred files from the source repository.
Why it doesn't meet the requirement
- No updates for modified files (✗): Setting the overwrite condition to Never (or skipping existing files) means that if a source file is modified with new data, Storage Transfer Service will ignore it because a file with the same name already exists in the target bucket.
- Deletes source data instead of syncing (✗): Choosing Delete file from source after they're transferred empties the source system rather than mirroring its contents.
- Fails mirror consistency (✗): It does not clean up destination files when they are deleted at the source, preventing the destination bucket from being an exact replica.
Key characteristics and limitations
- Append-only behavior: Only completely new object names are transferred to the destination.
- Source data loss: Source data is wiped out after transfer completion, making ongoing mirroring impossible.
- Incomplete synchronization: Discrepancies between source and target cannot be reconciled under these settings.
This answer would be correct if
The requirement was an archiving or offloading workflow where new daily log files need to be moved to Cloud Storage and cleared from the source system to free up local capacity without modifying existing archives.
Set the schedule frequency to Run once, configure the overwrite condition to Always, and set the deletion option to Delete file from source after they're transferred.
Set the schedule frequency to Run once, configure the overwrite condition to Always, and set the deletion option to Delete file from source after they're transferred.
What this configuration option does
This option configures a single ad-hoc transfer execution that forces replacement of all matching destination objects regardless of whether they have changed, and purges source data once files land in the target bucket.
Why it doesn't meet the requirement
- No recurring schedule (✗): Setting the schedule to Run once will only execute a single transfer job run upon creation. It fails the requirement to run continuously every 24 hours.
- Inefficient overwrite behavior (✗): Choosing Always forces Storage Transfer Service to re-copy and overwrite destination files even when they are completely identical to the source, generating excessive network transfer charges.
- Destructive source deletion (✗): The setting Delete file from source after they're transferred moves data by clearing the source store, which destroys the source dataset instead of maintaining an exact synchronized mirror between source and destination.
Key characteristics and limitations
- Data migration pattern: This setting is intended for one-time cutover migrations where source systems are being decommissioned.
- Irreversible action: Deleting source files without backups creates risk of permanent data loss.
- High latency and cost: Re-transferring identical objects every run consumes unnecessary compute and bandwidth.
This answer would be correct if
The scenario required a one-time data movement or migration where the source bucket needed to be drained and decommissioned after loading data into Cloud Storage.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 1,156 practice questions across all 4 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
FundamentalAssociate Data Practitioner
BigQuery Data Transfer Service
Load data into Google Cloud storage systems using the appropriate tool (e.g., gcloud and BQ CLI, Storage Transfer Service, BigQuery Data Transfer Service, client libraries)
FundamentalAssociate Data Practitioner
gcloud storage cp --recursive
Load data into Google Cloud storage systems using the appropriate tool (e.g., gcloud and BQ CLI, Storage Transfer Service, BigQuery Data Transfer Service, client libraries)
FundamentalAssociate Data Practitioner
Cloud Logging Application Logs
Review and analyze logs in Cloud Logging and Cloud Monitoring
FundamentalAssociate Data Practitioner
Cloud SQL Regional Availability
Choose the appropriate data storage location type (e.g., regional, dual-regional, multi-regional, zonal)
FundamentalAssociate Data Practitioner
Customer-Managed Encryption Keys
Understand the role of Cloud Key Management Service (Cloud KMS) to manage encryption keys
FundamentalGenerative AI Leader
Google Cloud Pre-trained AI APIs
Describing how Google Cloud's AI platform democratizes AI development (e.g., low-code and no-code tools, pre-trained models, APIs)
Last updated