Fundamental
Prepare and test your skills
Fundamental
Prepare and test your skills
Newline-Delimited JSON for Nested and Repeated Fields
Free sample question, answered and explained below. The Associate Data Practitioner practice bank has 1,156 more like it. Try 10 free: instant score, no account.
A data analytics team is ingesting e-commerce transaction records from Cloud Storage into BigQuery. Each transaction record contains complex hierarchical information, including nested customer contact details and a repeated list of purchased product line items.
Which file format should the team use to load this data while natively preserving its nested and repeated data structure?
Explanations
Standard multi-line formatted JSON array (Pretty-printed JSON)
Standard multi-line formatted JSON array (Pretty-printed JSON)
What Pretty-printed JSON is and does
Standard formatted JSON (often structured as a single outer JSON array containing multiple JSON objects separated by commas and spread across multiple indented lines) is the standard format used for configuration files, document stores, and RESTful web API responses.
Why it doesn't meet the requirement:
- Incompatible with BigQuery batch loading (✗): BigQuery load jobs require JSON data to be newline-delimited (one JSON object per line). Standard multi-line formatted JSON files or arrays spanning across multiple lines cannot be loaded directly as standard BigQuery tables using default bulk load jobs.
- Scalability and parallelization limits (✗): A single multi-line JSON file containing an array of records requires a sequential parser to read the entire file into memory to identify object boundaries, preventing distributed data processing engines from splitting the file into chunks for parallel loading.
Key characteristics and limitations:
- Human-readable indentation: Uses whitespace and newlines for visual readability rather than delimiting discrete data records.
- Resource intensive: Requires high memory overhead to parse large files compared to line-based streaming parsers.
- Requires preprocessing: Must be converted to newline-delimited JSON before ingestion into data warehouses.
This answer would be correct if:
The requirement called for storing a human-readable application configuration file or exchanging single REST API payload payloads where distributed, high-throughput bulk analytical ingestion is not required.
Standard Comma-Separated Values (CSV)
Standard Comma-Separated Values (CSV)
What CSV is and does
Comma-Separated Values (CSV) is a flat, text-based data storage format where each row represents a single record, and fields within each row are separated by a delimiter (typically a comma). CSV is widely used across spreadsheet applications, relational database exports, and traditional batch ETL processes due to its simplicity and human readability.
Why it doesn't meet the requirement:
- Flat structure only (✗): CSV files are strictly two-dimensional (rows and columns) and lack native syntax to represent nested objects (STRUCTs) or repeated arrays (ARRAYs).
- Schema representation limits (✗): To store multiple purchased items in a CSV row, data engineers must either artificially duplicate parent rows (denormalizing the data) or encode arrays as delimited text strings within a single column, requiring expensive custom parsing downstream.
- Type ambiguity: CSV files do not contain embedded data type metadata, requiring explicit schema definitions or schema autodetect heuristics during load jobs.
Key characteristics and limitations:
- No hierarchical modeling: Incapable of cleanly representing multi-level parent-child entities without artificial workarounds.
- Parsing overhead: Highly sensitive to delimiter collisions, special characters, unescaped quotes, and inconsistent line breaks across operating systems.
- Lightweight for flat data: Extremely space-efficient for simple tabular datasets without complex data hierarchies.
This answer would be correct if:
The transaction dataset were strictly tabular with flat scalar fields (such as transaction_id, date, total_amount) where each record represents a single line of data with no nested sub-objects or repeated arrays.
Newline-delimited JSON (JSON Lines)
Newline-delimited JSON (JSON Lines)
What Newline-delimited JSON is
Newline-delimited JSON (often referred to as ndjson or JSON Lines) is a semi-structured, text-based data interchange format where each individual line in a file contains a complete, valid JSON object. In data analytics and ingestion platforms like BigQuery, newline-delimited JSON is the standard JSON format used for batch data loads and streaming ingestion because each record is self-contained and separated by a newline character (\n).
How it meets the requirements:
- Nested records support (✓): JSON objects natively support key-value pairs where the value can be another JSON object. In BigQuery, these map directly to STRUCT (RECORD) data types, allowing complex sub-entities like customer contact profiles to remain grouped within the parent record.
- Repeated fields support (✓): JSON natively supports arrays (e.g.,
"items": [...]), which BigQuery represents as REPEATED (ARRAY) fields. This allows multiple purchased items to be stored directly inside a single transaction record without requiring denormalization or separate child tables. - Direct ingestion from Cloud Storage (✓): BigQuery natively supports loading newline-delimited JSON files directly from Cloud Storage buckets into managed analytical tables.
NDJSON Nesting Maps to BigQuery STRUCT and ARRAY
Annotated Structure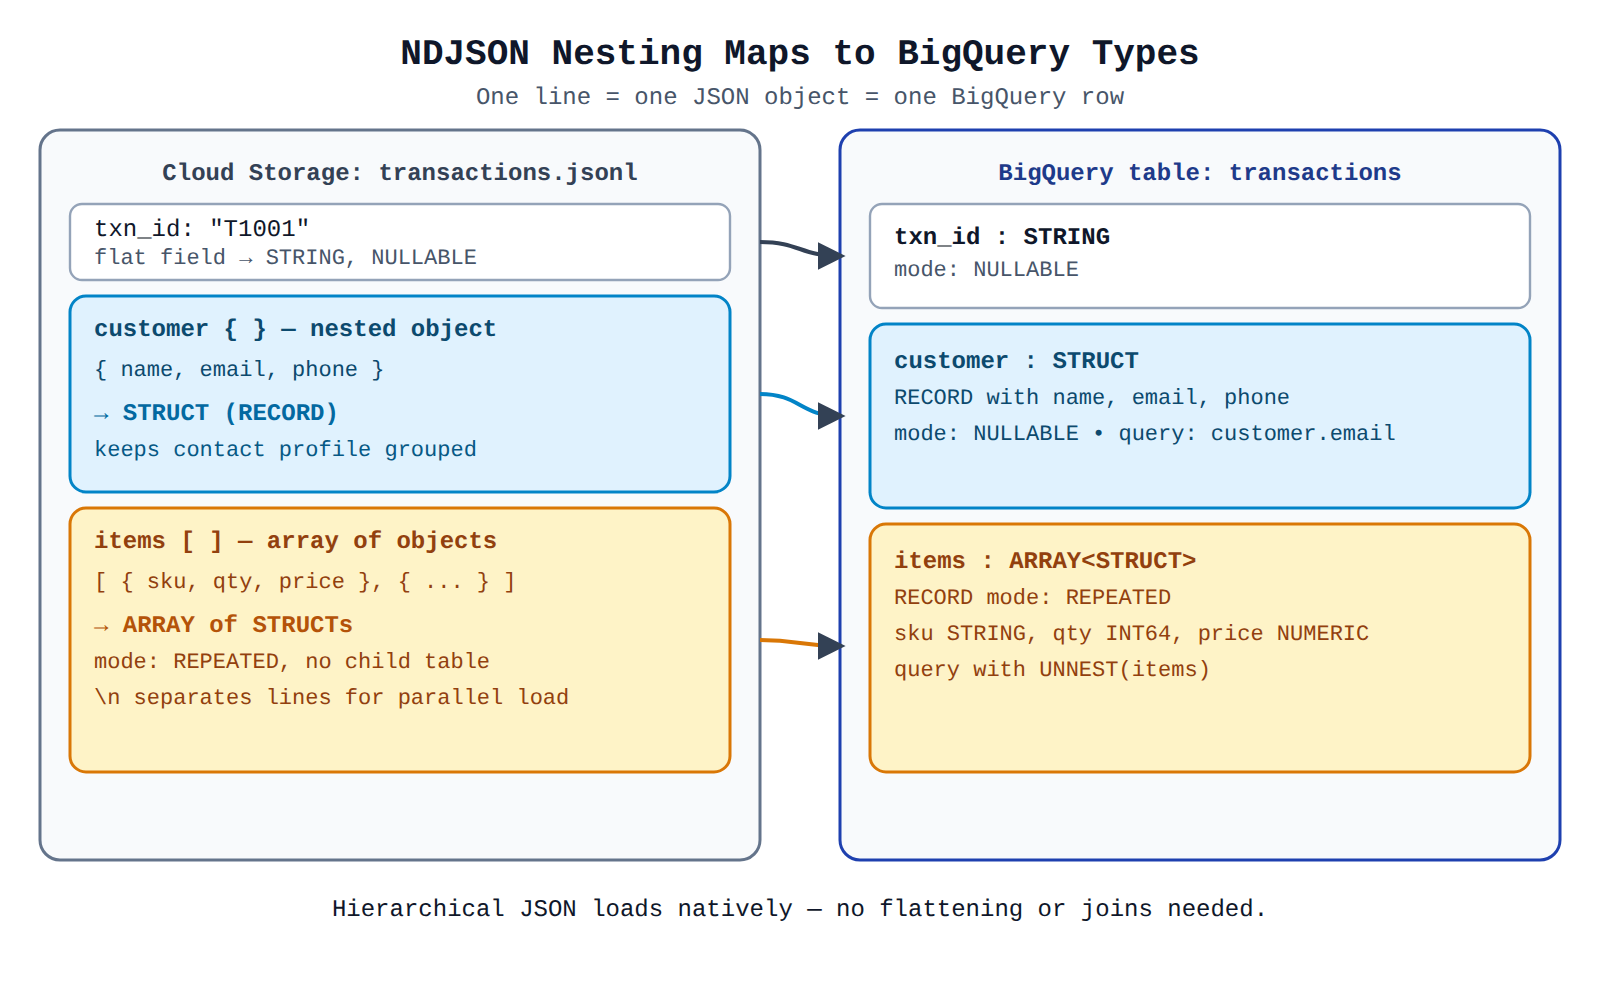
Key advantages:
- Flexible and self-describing: JSON encodes attribute names alongside values, making it easier to represent evolving data structures and variable schemas.
- Hierarchical data representation: Eliminates the immediate need for complex relational multi-table database joins when querying parent-child relationships.
- Standard cloud interchange format: Highly compatible with web APIs, logging services, and distributed stream processing engines across Google Cloud.
- Parallel processing friendly: Because each record occupies exactly one line, distributed ingestion systems can split large files efficiently along line boundaries.
Why this is optimal:
Unlike flat, tabular formats such as CSV that only represent two-dimensional rows and columns, newline-delimited JSON allows complex, multi-tiered business objects to be ingested into BigQuery in their natural structure. This avoids the overhead of flattening arrays or maintaining multiple related tables, making it the ideal choice for hierarchical transaction logs.
Plain unstructured text log files (TXT)
Plain unstructured text log files (TXT)
What Plain Text files are and do
Plain unstructured text files (TXT) store raw, unformatted text strings without any predefined data model, field delimiters, or standardized object notation. They are commonly generated by legacy server daemons, syslog mechanisms, and simple application print logs.
Why it doesn't meet the requirement:
- Lack of structural syntax (✗): Plain text files have no built-in schema, key-value pairs, or array semantics to represent nested customer profiles or repeated line item arrays.
- Requires heavy ETL preprocessing (✗): Ingesting unstructured text files into BigQuery requires writing custom transformation pipelines (e.g., using Dataflow, regular expressions, or custom parsing scripts) to extract and convert fields into structured relational columns.
- No native schema mapping (✗): Managed cloud analytical engines cannot automatically infer data types or nested hierarchy from freeform text lines.
Key characteristics and limitations:
- Unstructured: Content can vary arbitrarily from line to line without syntactic guarantees.
- High parsing failure rates: Changes in logging patterns easily break downstream parsing scripts.
- Analytical query overhead: Cannot be queried efficiently with SQL without substantial preprocessing and data cleansing.
This answer would be correct if:
The objective was to store raw, unstructured system diagnostic outputs or application console logs in Cloud Storage for archival or freeform string pattern matching.
Try 10 interactive questions like this one, free
Answer them yourself and get your score the moment you finish. No account needed.
Full access includes
- 1,156 practice questions across all 4 exam domains
- Every answer explained: why it is right, and why the others are not
- Scout, an AI tutor that answers your follow-up questions
- Readiness tracking by domain, so you know when to book the exam
Related questions
Keep the momentum going with these hand-picked practice scenarios
FundamentalAssociate Data Practitioner
BigQuery Data Transfer Service Supported Formats
Distinguish the format of the data (e.g., CSV, JSON, Apache Parquet, Apache Avro, structured database tables)
FundamentalAssociate Data Practitioner
Avro vs Parquet Data Formats
Distinguish the format of the data (e.g., CSV, JSON, Apache Parquet, Apache Avro, structured database tables)
FundamentalAssociate Data Practitioner
Cloud Storage Classes by Access Frequency and Retention
Determine the appropriate Cloud Storage classes based on the frequency of data access and retention requirements
FundamentalAssociate Data Practitioner
Cloud Storage Archive Storage
Evaluate Google Cloud services for archiving data given business requirements
FundamentalAssociate Data Practitioner
BigQuery BI Engine
Compare Looker and Looker Studio for different analytics use cases
AdvancedProfessional Cloud DevOps Engineer
GKE Multi-Cluster Gateway Service Capacity Overflow
Adding capacity
Last updated